Where wkhtmltopdf Saves Converted PDF Files
wkhtmltopdf saves a converted PDF to the output path at the end of your command. Learn how relative and absolute paths work, how to check the working directory, and what changes when you use an API or wrapper.

Direct answer: wkhtmltopdf saves the PDF to the output-file path you give it as the final argument. It does not choose a universal Downloads, Documents, or application folder. In wkhtmltopdf https://example.com report.pdf, the file is named report.pdf and, because that is a relative path, it is written relative to the process’s current working directory. To specify the destination unambiguously, provide an absolute path, such as /tmp/report.pdf.
The same rule helps explain most “where did my PDF go?” cases: the destination is explicit in the command, but a short filename does not tell you which directory the process was in. The shell’s working directory may differ from the directory you expected, especially when another program, service, or scheduled task launches the command.
1. Set the output path in the command
The official command synopsis ends with <output file>: wkhtmltopdf [GLOBAL OPTION]... [OBJECT]... <output file>. The final argument is the destination filename. For example, the documented examples include converting a URL to google.pdf and a local HTML file to my.pdf. See the wkhtmltopdf usage reference.
wkhtmltopdf https://example.com report.pdfHere, report.pdf is a relative path. If the process’s current working directory is /home/alex/jobs, the output path resolves to /home/alex/jobs/report.pdf. The command-line manual specifies the output argument; it does not define a special, platform-independent current directory. The process environment supplies that directory.
For a known destination, use an absolute path:
wkhtmltopdf https://example.com /tmp/report.pdfReplace /tmp/report.pdf with an absolute path that exists and is writable on the machine running the command. An absolute path removes ambiguity about the working directory, but it does not create missing parent directories or grant write permission.
Local HTML input works the same way
The input can be a URL or a local HTML file. The output argument still determines where the PDF is written:
wkhtmltopdf my.html my.pdfIn that example, my.html is the input and my.pdf is the output. If you want the output in a particular folder, give that folder’s path as part of the final argument. Keep input and output roles in the right order: the source comes before the destination.
Confirm where a relative path resolves
Before running a command that uses a short filename, inspect the current directory in the same shell. On Unix-like shells, use pwd; on Windows Command Prompt, use cd with no arguments. These commands tell you the shell’s current directory, which is the reference point for a relative output filename when you run wkhtmltopdf from that shell.
# Unix-like shell
pwd
wkhtmltopdf https://example.com report.pdf

# Windows Command Prompt
cd
wkhtmltopdf https://example.com report.pdf
After conversion, look for the output in that directory. If another application starts wkhtmltopdf, check the working directory of that process rather than assuming it uses the directory shown in your interactive terminal.
2. Choose a destination you can find and write to
A reliable command makes the destination visible in the command itself. Create the destination directory first if necessary, select a path the running user can write to, and then pass its full path as the last argument.

- Choose the folder. Use a known output directory, such as a project artifact folder or a temporary directory. Make sure it exists.
- Check the identity running the command. A service or scheduled task may run as a different user from the one who created the folder.
- Pass the complete output path. Keep the destination as the final argument.
- Check the result at that path. If the command is launched by a wrapper, verify whether the wrapper saves a file at all or returns the PDF another way.
wkhtmltopdf https://example.com /tmp/report.pdfThat example works only if the process can write to /tmp and the conversion completes. Choose an appropriate absolute path for your operating system and deployment environment. Do not assume a service’s default working directory is the same as your account’s home or project directory.
| Output argument | What it means | What to check |
|---|---|---|
report.pdf |
Relative filename; resolved from the process working directory. | Which directory launched the process? |
/tmp/report.pdf |
Absolute path on a Unix-like system. | Does the directory exist, and can the process write there? |
- in the C API’s out setting |
Send output to standard output. | Is the caller reading the PDF bytes from stdout? |
Empty out in the C API |
Store the result in a buffer. | Does the calling code retrieve and handle that buffer? |
3. Understand CLI, API, and wrapper destinations
The command-line tool, the C API, and a framework wrapper can expose different output behavior. The CLI’s final argument is a file path. The C API uses its out setting to control output: the official API reference says - sends output to stdout, while an empty value stores output in a buffer. Consult the C API settings reference for the integration you are using.
A framework wrapper may instead stream the PDF bytes in an HTTP response or apply its own save-path option. For example, PDFKit documents a PDFKit-save-pdf header, whose value is the path where the generated PDF is written. That behavior belongs to the wrapper, so check its documentation rather than inferring it from the CLI. See PDFKit’s documentation.
When a conversion runs inside an application, answer these questions before searching the filesystem:
- Is the application invoking the CLI, calling the C API, or using a framework wrapper?
- Does the integration specify a path, write to stdout, retain bytes in memory, or send a response?
- Which process and user perform the conversion?
- What is that process’s working directory, if the output name is relative?
These distinctions matter because a PDF returned to an HTTP caller may never be saved as a local file by the server. Conversely, an integration configured with a save path may write a file even when the end user only sees a response.
4. Troubleshoot a PDF you cannot find
Work through these checks in order. They separate a wrong-path problem from a failed conversion, a permissions problem, or wrapper-specific behavior.
- Read the complete command. Identify the final output argument. Do not mistake an input HTML file or URL for the destination.
- Resolve relative paths. Check the current working directory of the process that ran wkhtmltopdf. Search that location for the exact filename.
- Retry with an absolute path. Use a full destination path so the working directory cannot affect the location.
- Check the destination directory. Confirm it exists and the process user has permission to write there.
- Check the integration’s output mode. For the C API, determine whether output was sent to stdout or stored in memory. For a framework, see whether it streams the PDF or has a separate save-path setting.
- Confirm the conversion completed. A destination argument identifies where a successful conversion should go; it cannot by itself establish that the conversion succeeded.
| Symptom | Likely cause | Fix |
|---|---|---|
| The command appears to succeed, but the file is not in the project folder. | A relative output name was resolved from a different working directory. | Check the launching process’s working directory or rerun with an absolute output path. |
| The output path is correct, but no file appears. | The directory may not exist, may not be writable by the process user, or conversion may not have completed. | Verify the directory and write access, then inspect the command or wrapper’s result and error handling. |
| No local file appears after an API call. | The API may send bytes to stdout or hold them in a memory buffer instead of writing a file. | Check the API’s output setting and consume or persist the returned PDF data. |
| A web request returns a PDF, but the server has no copy. | The wrapper may stream the result directly in its HTTP response. | Inspect wrapper-specific configuration for a save path if a server-side copy is required. |
| The wrapper saves to an unexpected location. | Its own setting or response header may determine the destination. | Check the wrapper’s documentation; PDFKit, for example, documents the PDFKit-save-pdf header. |
| The output lands somewhere unexpected when launched as a service. | The service’s working directory or user differs from the interactive shell. | Set an absolute output path and ensure the service user can write to its parent directory. |
5. Reliability and operational notes
Use explicit output paths in scripts and services. A relative path can be convenient for a one-off conversion, but it depends on the launch context. If that context changes, the output location changes too. An absolute path makes the intended destination clear to the person reading or maintaining the command.
Build the path from a configured output directory when running repeated jobs, and ensure the directory exists before launching the conversion. Avoid relying on a developer’s interactive shell state in production: scheduled jobs, containers, web servers, and service managers can have their own working directories and run under their own users. These are general path-management precautions; the wkhtmltopdf output argument remains the control for CLI file placement.
If an application does not need a persistent server-side copy, a wrapper may return or stream PDF bytes to the caller. If it does need a copy, make the save location explicit in that integration. For the C API, decide whether the caller expects a path, stdout, or a buffer, then handle that output mode deliberately.
6. Generate a webpage PDF without managing a local browser
If your task is to capture a webpage as a PDF and you do not specifically need wkhtmltopdf’s local-file workflow, ScreenshotNeo offers a website screenshot API that can return a PDF. It also provides screenshot formats including PNG, JPEG, and WebP. See ScreenshotNeo and the API documentation for the request details.
With the DIY route, you install and run a converter, specify the output path, and account for its execution environment. With ScreenshotNeo, send a GET request with the page URL and API key; the response is the capture. The following examples use the supplied API endpoint and request pattern with a PDF output format.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -d format=pdf \
  -o page.pdf
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={
        "access_key": "YOUR_API_KEY",
        "url": "https://stripe.com",
        "format": "pdf",
    },
    timeout=90,
)
r.raise_for_status()
with open("page.pdf", "wb") as f:
    f.write(r.content)
Node.js
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com',
  format: 'pdf',
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`ScreenshotNeo request failed: ${res.status}`);
const bytes = new Uint8Array(await res.arrayBuffer());
await import('node:fs/promises').then(fs => fs.writeFile('page.pdf', bytes));
In each example, page.pdf is written by the local client code to its own current working directory. The API returns the capture; the -o option in cURL and the file-writing code in Python and Node.js decide where the client saves it. Use a full local path in those save operations if you need a fixed destination. Keep your API key private and replace the example URL with the page you want to capture.
Or skip the browser setup
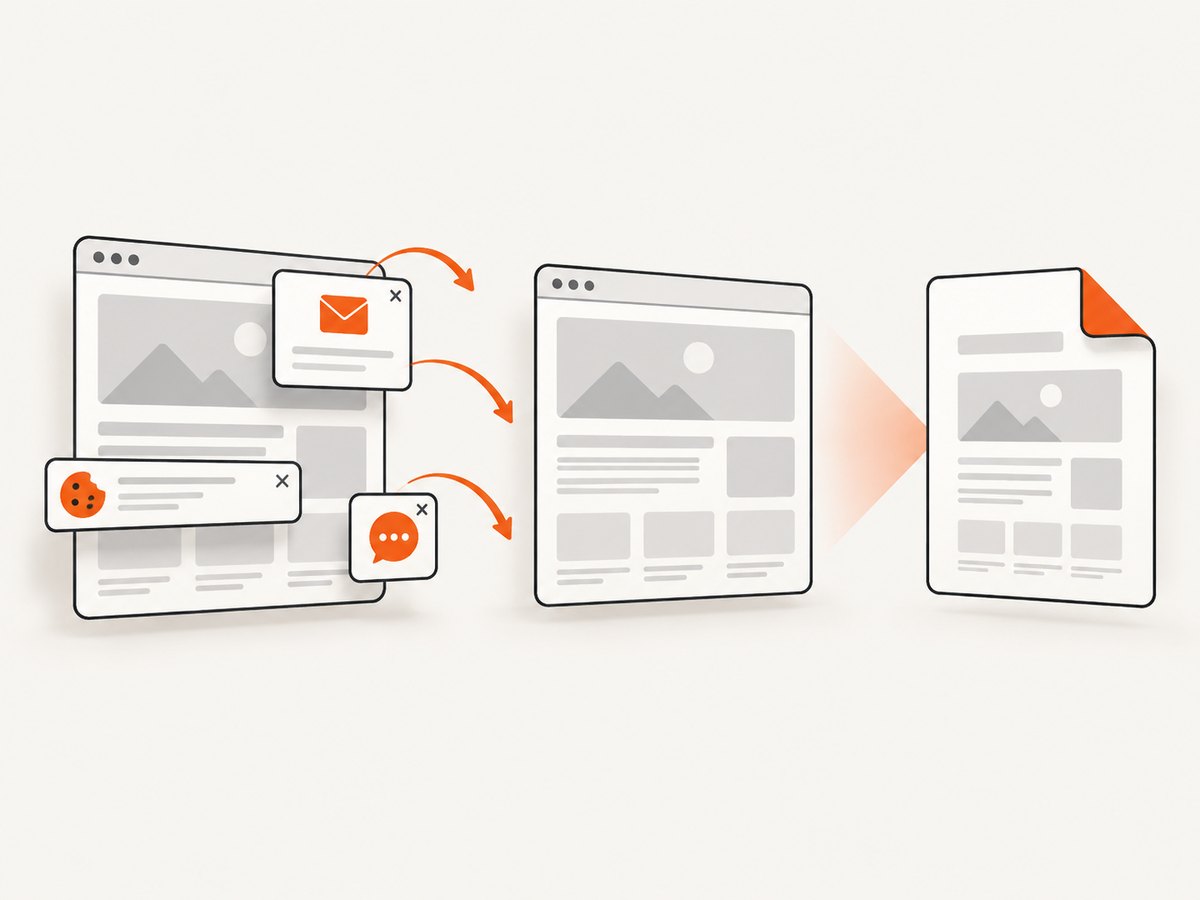
ScreenshotNeo accepts cookie and consent banners like a visitor, then removes more than 60 known consent platforms, newsletter popups, and chat widgets before capture; each cleanup step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers identify the page verdict and whether the capture was billed. Its MCP server gives AI agents, including Claude, Cursor, and other MCP clients, the tools take_screenshot, get_page_info, and capture_pdf. The free plan includes 1,000 shots a month with no card; paid plans start at $5 for 3,000 shots. Every feature is on every plan.
One request can replace local browser setup when you need a webpage PDF:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -d format=pdf \
  -o page.pdf
For optional parameters and the other supported capture controls, see the ScreenshotNeo API docs. Sign up for 1,000 free screenshots a month, with no card required.
7. FAQ
Does wkhtmltopdf save PDFs to Downloads by default?
No universal Downloads folder is specified. The CLI writes to the output-file argument, and relative names resolve from the process’s current working directory.
Does the output path come before or after the input?
After it. The input URL or HTML file comes first; the output filename is the final argument.
Can the C API return a PDF without creating a file?
Yes. Its out setting can send output to stdout with - or store it in a buffer when the value is empty. Your application must then consume that output.
Why does my web application show a PDF when I cannot find it on the server?
The integration may stream PDF bytes in the HTTP response instead of saving them locally. Check its documentation for response and save-path behavior.
How do I make the destination predictable?
Pass an absolute output path to the CLI, or explicitly configure the output mode and destination in the API or wrapper you use.