How to Convert a Web Page to PDF in NestJS
Render any web page as a PDF from NestJS with Puppeteer, print CSS, production safeguards, troubleshooting, and a hosted ScreenshotNeo option.

To convert a web page to PDF in NestJS, render the URL in a headless Chromium browser and call the browser page’s PDF API. Puppeteer provides the shortest path: launch a browser, navigate with page.goto(), wait for the page to be ready, call page.pdf(), then return the bytes from a NestJS controller. Puppeteer’s official guide documents this sequence and notes that PDF generation waits for fonts by default. Read the Puppeteer PDF guide.
This guide builds a complete NestJS implementation, explains print CSS and every important PDF option, covers dynamic pages and security, and compares Puppeteer with Playwright. At the end, you can use ScreenshotNeo when operating Chromium yourself is unnecessary.
1. Install the browser and NestJS dependencies
Create a NestJS application if you do not already have one, then install Puppeteer:
npm install puppeteer
npm install --save-dev @types/node
The regular puppeteer package downloads a compatible browser during installation. If your deployment image supplies Chromium separately, use the launcher configuration supported by that image and set an executable path. Always verify that the browser binary and its system libraries exist in the production environment.
A NestJS-specific package called nestjs-puppeteer can provide module integration. Its npm listing describes installation with Puppeteer or an alternative launcher and reports CI coverage for NestJS 10 and 11 with Puppeteer 23 and 24. Check the package’s current documentation and compatibility before adopting it: nestjs-puppeteer on npm.
2. Build a PDF service with Puppeteer
The following service launches one browser for the application lifetime, creates a fresh page per request, applies a navigation timeout, waits for the requested readiness condition, and returns a PDF buffer. Keeping the browser open avoids paying startup cost for every request while still isolating cookies and DOM state in separate pages.

import {
  Injectable,
  OnModuleDestroy,
  OnModuleInit,
  BadRequestException,
  GatewayTimeoutException,
} from '@nestjs/common';
import puppeteer, { Browser, PDFOptions } from 'puppeteer';

export interface WebPagePdfOptions {
  url: string;
  waitForSelector?: string;
  waitMs?: number;
  pdf?: PDFOptions;
}

@Injectable()
export class PdfService implements OnModuleInit, OnModuleDestroy {
  private browser!: Browser;

  async onModuleInit() {
    this.browser = await puppeteer.launch({
      headless: true,
      args: ['--no-sandbox', '--disable-setuid-sandbox'],
    });
  }

  async onModuleDestroy() {
    await this.browser?.close();
  }

  async render(options: WebPagePdfOptions): Promise<Buffer> {
    let parsed: URL;
    try {
      parsed = new URL(options.url);
    } catch {
      throw new BadRequestException('url must be an absolute URL');
    }

    if (!['http:', 'https:'].includes(parsed.protocol)) {
      throw new BadRequestException('only http and https URLs are allowed');
    }

    const page = await this.browser.newPage();
    try {
      await page.setViewport({ width: 1280, height: 900, deviceScaleFactor: 1 });
      await page.goto(parsed.href, {
        waitUntil: 'networkidle2',
        timeout: 30_000,
      });

      if (options.waitForSelector) {
        await page.waitForSelector(options.waitForSelector, { timeout: 15_000 });
      }
      if (options.waitMs) {
        await new Promise((resolve) => setTimeout(resolve, options.waitMs));
      }

      return await page.pdf({
        format: 'A4',
        printBackground: true,
        preferCSSPageSize: true,
        timeout: 30_000,
        ...options.pdf,
      });
    } catch (error) {
      const message = error instanceof Error ? error.message : 'PDF rendering failed';
      if (/timeout/i.test(message)) {
        throw new GatewayTimeoutException(message);
      }
      throw error;
    } finally {
      await page.close();
    }
  }
}
The --no-sandbox flags are common in restricted containers, but they reduce browser isolation. Use a sandboxed browser when your runtime supports it and follow your platform’s security guidance. Do not expose an unrestricted URL-to-PDF endpoint to untrusted users without destination controls.
3. Expose the PDF through a NestJS controller
Return the buffer with an inline content disposition for browser viewing, or change it to attachment to force a download.
import { Controller, Get, Query, Res } from '@nestjs/common';
import { Response } from 'express';
import { PdfService } from './pdf.service';

@Controller('pdf')
export class PdfController {
  constructor(private readonly pdfService: PdfService) {}

  @Get()
  async createPdf(
    @Query('url') url: string,
    @Query('ready') ready: string | undefined,
    @Res() response: Response,
  ) {
    const pdf = await this.pdfService.render({
      url,
      waitForSelector: ready,
      pdf: {
        format: 'A4',
        printBackground: true,
        displayHeaderFooter: false,
      },
    });

    response.set({
      'Content-Type': 'application/pdf',
      'Content-Length': pdf.length,
      'Content-Disposition': 'inline; filename="web-page.pdf"',
    });
    response.end(pdf);
  }
}
Register both classes in a module:
import { Module } from '@nestjs/common';
import { PdfController } from './pdf.controller';
import { PdfService } from './pdf.service';

@Module({
  controllers: [PdfController],
  providers: [PdfService],
})
export class PdfModule {}
Run the server and request:
curl --get 'http://localhost:3000/pdf' \
  --data-urlencode 'url=https://example.com' \
  --output page.pdf
4. Make print output match your requirements
page.pdf() uses print media. The page can therefore look different from its screen view. Add print rules to the source page or inject a stylesheet before exporting:
@page {
  size: A4;
  margin: 18mm 14mm 20mm;
}

@media print {
  nav, .cookie-banner, .chat-widget, .print-hidden {
    display: none !important;
  }

  a {
    color: inherit;
    text-decoration: none;
  }

  .page-break {
    break-before: page;
  }

  * {
    -webkit-print-color-adjust: exact;
    print-color-adjust: exact;
  }
}
Puppeteer’s PDF options include paper format, explicit width and height, margins, landscape orientation, scaling, background graphics, CSS page-size preference, page ranges, header and footer templates, and a PDF timeout. The documented default format is Letter and background printing is disabled unless you enable printBackground. See the Page.pdf API reference.
Common option combinations
| Goal | Options |
|---|---|
| Standard document | format: 'A4', printBackground: true |
Use the page’s @page size |
preferCSSPageSize: true |
| Landscape report | landscape: true |
| Selected pages only | pageRanges: '1-3,5' |
| Branded footer | displayHeaderFooter: true plus HTML templates |
| Fit oversized content | Set scale between 0.1 and 2, then inspect readability |
5. Handle dynamic applications correctly
networkidle2 waits until network activity is low, but it does not prove that your application finished rendering. A dashboard may keep polling forever, while a static page may render after a client-side state transition. Prefer an explicit readiness marker:
// In the application being rendered
window.dispatchEvent(new Event('pdf-ready'));
await page.goto(url, { waitUntil: 'domcontentloaded', timeout: 30_000 });
await page.waitForFunction(
  () => document.documentElement.dataset.pdfReady === 'true',
  { timeout: 20_000 },
);
Other useful strategies are waiting for a known selector, waiting for a bounded delay after an API response, or calling page.emulateMediaType('print') before checking layout. Puppeteer waits for fonts during PDF generation by default, but images and application data still need your readiness logic.
6. Authentication, headers and assets
For protected pages, set cookies or an authorization header before navigation:
await page.setExtraHTTPHeaders({
  Authorization: `Bearer ${token}`,
});
await page.setCookie({
  name: 'session',
  value: sessionValue,
  domain: new URL(url).hostname,
  path: '/',
  httpOnly: true,
  secure: true,
});
Make sure fonts, images and stylesheets are reachable from the browser’s network. Cross-origin restrictions, expiring signed URLs and CSP rules can produce a PDF with missing assets even when the HTML loaded successfully. If you control the page, serve print assets from stable URLs and avoid relying on hover-only content.
7. Security controls for user-supplied URLs
A server-side renderer makes outbound requests from your infrastructure. Validate the scheme, restrict hosts or tenants, and decide how redirects are handled. Block loopback, link-local, private-network and cloud metadata addresses when users can submit arbitrary URLs. Apply request authentication, rate limits, body-size limits and an overall rendering deadline. Consider a separate network or worker for browser jobs. These controls are application decisions implied by server-side navigation; the browser APIs do not enforce them for you.
8. Reliability and performance in production
- Reuse the browser, isolate pages. Launching Chromium per request is expensive. Keep a process alive and close every page in
finally. - Limit concurrency. Each PDF consumes CPU and memory. Queue jobs or use a semaphore instead of allowing unlimited parallel pages.
- Restart unhealthy browsers. Track launch and render failures, and replace a browser process that repeatedly crashes.
- Use bounded timeouts. Set navigation, readiness and PDF limits separately so one page cannot occupy a worker indefinitely.
- Cache when content permits. A content hash or URL-plus-parameters key can avoid repeat renders, but include authentication and freshness requirements in the key.
- Stream large files deliberately. For typical reports a buffer is simple. For very large documents, write to object storage or a controlled stream and return a reference.
There is no universal throughput number in the cited documentation. Measure your own pages, browser version, container limits, fonts, image sizes and concurrency. Playwright documents PDF generation as Chromium-only; its API also generates PDFs with print CSS. Compare both libraries against your actual deployment rather than assuming one is faster. See Playwright’s page.pdf documentation.
9. Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| Executable doesn’t exist | Browser was not downloaded or is unavailable in the image | Install Puppeteer’s browser during build or configure a valid executable path. |
| Navigation timeout | Slow page, blocked request or never-ending polling | Use a suitable timeout, wait for a specific selector, and inspect server-side network access. |
| Blank or partial PDF | Client-side content was not ready | Wait for an application readiness marker, selector or data response. |
| Colors or backgrounds missing | Print backgrounds are disabled | Set printBackground: true and use print color adjustment CSS. |
| Wrong page size | Conflicting format and @page rules |
Choose one source of truth and set preferCSSPageSize deliberately. |
| Fonts differ | Font files are blocked, late or unavailable in the container | Make fonts reachable and wait for the page; Puppeteer waits for fonts during PDF generation. |
| Only first page appears | Content is inside a fixed-height or clipped container | Remove print-time overflow constraints and test the actual print layout. |
| Browser crashes under load | Too many concurrent pages or insufficient memory | Bound concurrency, reduce asset sizes and recycle workers. |
| Private host becomes reachable | Unrestricted user URL accepted by the service | Apply host and IP-range allowlists and re-check redirects. |
10. Test the endpoint and inspect the PDF
Use representative pages: a static article, a JavaScript dashboard, a page with web fonts, a long document, and an authenticated route. Verify page count, margins, links, backgrounds, headers, footers and selectable text. Keep a small set of expected screenshots or PDFs for regression review when you change browser versions or print CSS.
Or skip the browser setup
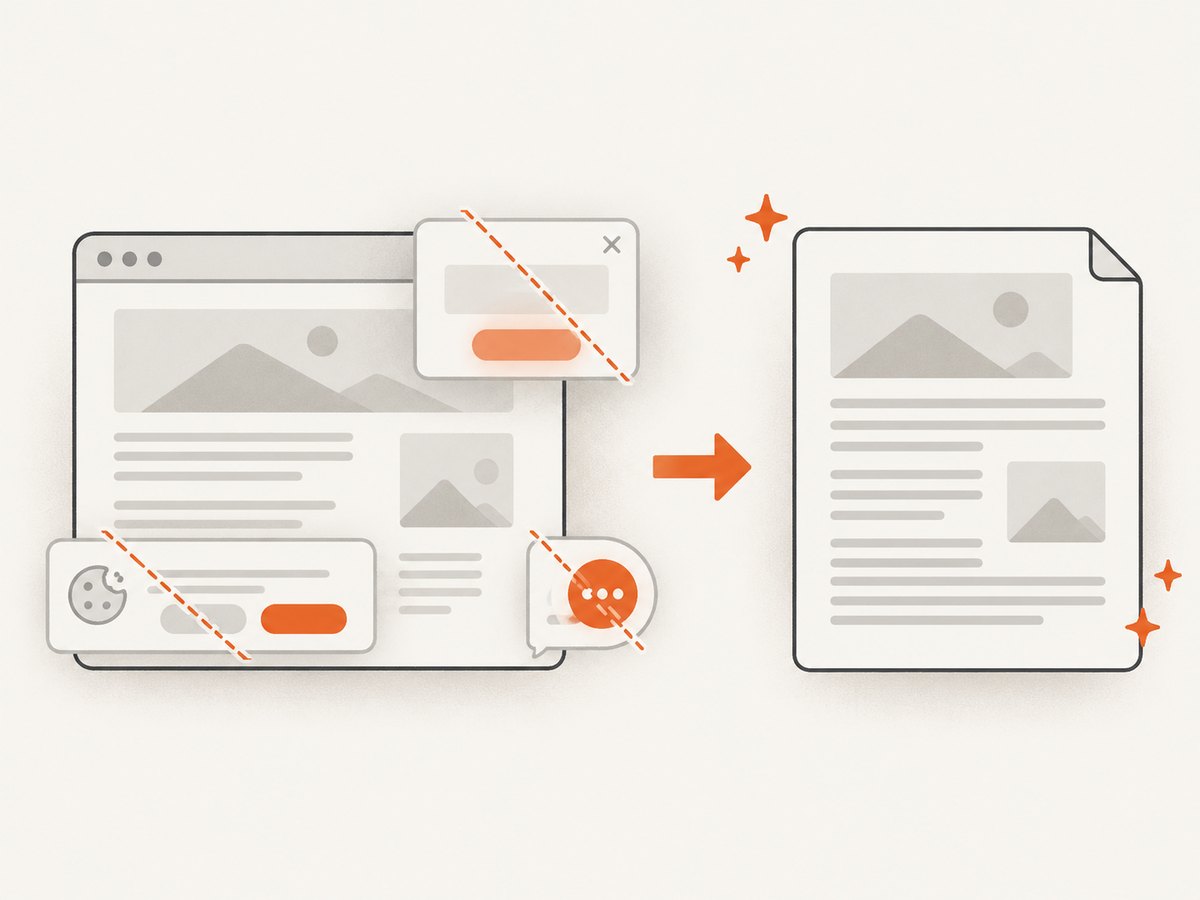
ScreenshotNeo provides a hosted capture API that can return a PDF from one GET request. The service accepts print options such as paper size, margins, landscape mode and page ranges, along with waits, custom CSS and JavaScript, headers, cookies, user agents and authentication. See the ScreenshotNeo API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Adapt the target URL and request PDF output according to the API documentation. Cookie banners, newsletter popups and chat widgets are removed before the shot; bot checks, blank pages and failed loads are never billed. Responses identify the page verdict and billing status with X-Page-Verdict and X-Billed headers. An MCP server lets Claude, Cursor and other MCP clients call take_screenshot, get_page_info and capture_pdf. The Free plan includes 1,000 shots per month with no card; paid plans start at $5 for 3,000 shots.
Start with 1,000 free screenshots a month—no card required.
FAQ
Does Puppeteer generate a real PDF or an image?
page.pdf() generates a PDF from the rendered document, including selectable text when the page provides text content.
Can I export screen styles instead of print styles?
Yes. Playwright documents using screen media before PDF generation; with Puppeteer, set the page media type to screen before calling page.pdf(), then verify pagination.
Should I use Puppeteer or Playwright?
Both expose browser navigation and page PDF operations. Choose based on your NestJS integration, browser packaging, required controls and operational testing.
Can a PDF endpoint accept any URL?
It can technically navigate to a URL, but an internet-facing endpoint should restrict destinations and prevent access to internal network resources.
How do I add a page number?
Enable header or footer templates and use the documented page-number placeholders supported by the browser PDF API.


