Web Scraping With Go: Colly, goquery, and Browser Tools in 2026
Learn when to use Colly, goquery, or chromedp for Go web scraping, with runnable code, limits, troubleshooting, and a browserless screenshot option.
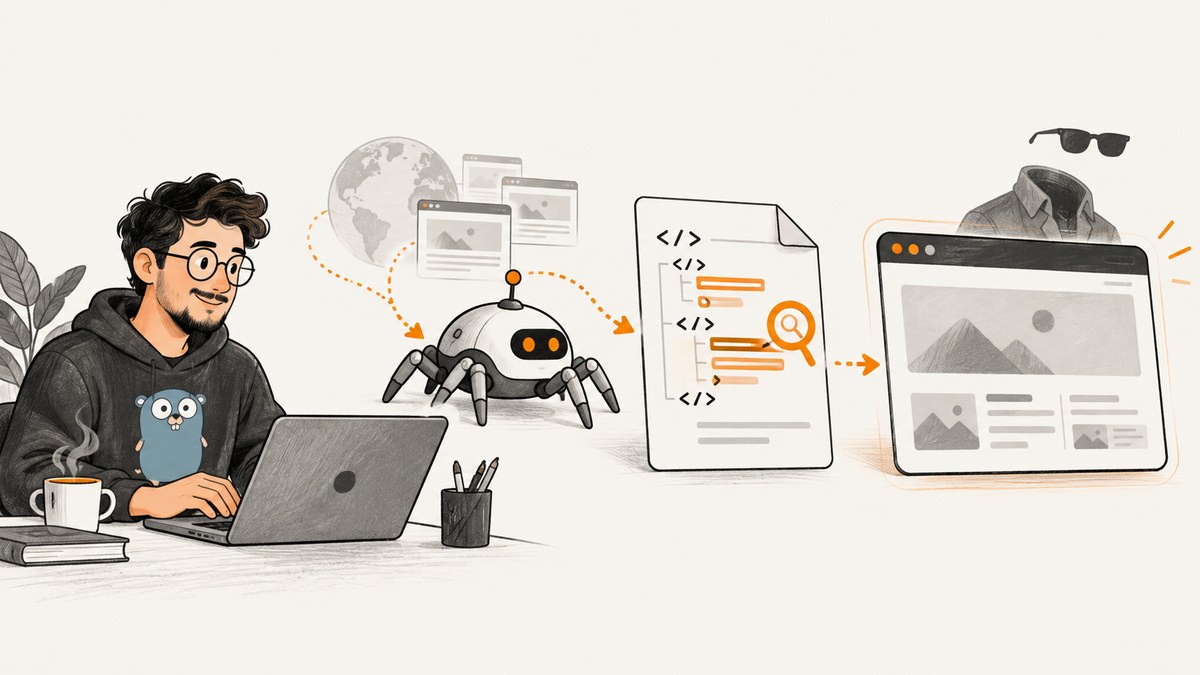
Short answer: use Colly to fetch and coordinate crawls, goquery to select data from returned HTML, and chromedp when you need a real Chrome browser to execute JavaScript or interact with a page. They are complementary layers, not competing replacements. Start with HTTP plus HTML parsing when the fields are in the response. Add browser automation only when rendering, clicks, scrolling, authentication, or other browser behavior is required.
Choose the layer that matches the page
| Requirement | Best fit | Why |
|---|---|---|
| Crawl many ordinary pages | Colly | Coordinates requests, callbacks, concurrency, caching, cookies, robots.txt handling, and request limits. |
| Extract fields from HTML | goquery | Provides chainable CSS-selector methods for querying and manipulating a document. |
| Run page JavaScript or interact | chromedp | Controls a Chrome-compatible browser through the Chrome DevTools Protocol. |
Colly’s documentation describes it as a Go framework for building web scrapers. Its role is fetching and crawl orchestration. goquery does not fetch pages and is not a browser; it parses an HTML document you provide. chromedp drives a browser, so it can observe a DOM after scripts run, click controls, wait for elements, and capture browser state. The reviewed sources do not provide a controlled benchmark that makes one universally faster, so measure your own URLs and workload before publishing performance claims.

Install the Go packages
mkdir go-scraper
cd go-scraper
go mod init example.com/go-scraper
go get github.com/gocolly/colly/v2
go get github.com/PuerkitoBio/goquery
go get github.com/chromedp/chromedp
Package versions change. Check the current module documentation and compatibility before pinning a release. The canonical goquery module path is github.com/PuerkitoBio/goquery; older search results may show a legacy gopkg.in path.
Build an HTTP scraper with Colly and goquery
This example crawls links on one domain, extracts article titles, and stops at a bounded depth. It keeps fetching separate from extraction: Colly receives the response, while goquery queries the response body.
package main

import (
    "fmt"
    "log"
    "net/http"
    "time"

    "github.com/PuerkitoBio/goquery"
    "github.com/gocolly/colly/v2"
)

func main() {
    c := colly.NewCollector(
        colly.AllowedDomains("example.com"),
        colly.MaxDepth(2),
        colly.MaxBodySize(5*1024*1024),
    )

    c.UserAgent = "go-scraper/1.0 (+https://example.com/contact)"
    c.SetRequestTimeout(20 * time.Second)

    c.Limit(&colly.LimitRule{
        DomainGlob:  "example.com/*",
        Parallelism: 2,
        Delay:       500 * time.Millisecond,
    })

    c.OnHTML("article", func(e *colly.HTMLElement) {
        title := e.ChildText("h1")
        if title != "" {
            fmt.Printf("%s\n", title)
        }
    })

    c.OnResponse(func(r *colly.Response) {
        doc, err := goquery.NewDocumentFromReader(r.Body)
        if err != nil {
            log.Printf("parse %s: %v", r.Request.URL, err)
            return
        }
        doc.Find("article h2").Each(func(_ int, s *goquery.Selection) {
            fmt.Printf("%s: %s\n", r.Request.URL, s.Text())
        })
    })

    c.OnHTML("a[href]", func(e *colly.HTMLElement) {
        link := e.Request.AbsoluteURL(e.Attr("href"))
        if link != "" {
            _ = e.Request.Visit(link)
        }
    })

    c.OnError(func(r *colly.Response, err error) {
        log.Printf("request %s failed: %v (status %d)", r.Request.URL, err, r.StatusCode)
    })

    if err := c.Visit("https://example.com/"); err != nil {
        log.Fatal(err)
    }
}
The AllowedDomains, depth, body-size, timeout, and limit settings are guardrails. Colly documents robots.txt support and request limits; treat those controls as implementation safeguards, not as a legal determination that you may access a particular site. Obtain permission where required and follow the target’s terms and applicable law.
Use goquery when you already have HTML
If another service gives you HTML, parse it directly without creating a crawler:
resp, err := http.Get("https://example.com/page")
if err != nil { log.Fatal(err) }
defer resp.Body.Close()

doc, err := goquery.NewDocumentFromReader(resp.Body)
if err != nil { log.Fatal(err) }

doc.Find("table tr").Each(func(i int, row *goquery.Selection) {
    cells := []string{}
    row.Find("th, td").Each(func(_ int, cell *goquery.Selection) {
        cells = append(cells, cell.Text())
    })
    fmt.Println(cells)
})
Selectors should describe stable structure. Prefer semantic attributes or stable class names over generated CSS hashes. Normalize whitespace, check for missing nodes, and expect markup changes.
When a browser is necessary
Use chromedp when the useful data is created after JavaScript runs, when an interaction reveals content, or when you need browser behavior such as scrolling, form submission, or a rendered screenshot. A normal HTTP client will receive the initial response but will not execute its scripts.
package main

import (
    "context"
    "log"
    "time"

    "github.com/chromedp/chromedp"
)

func main() {
    ctx, cancel := chromedp.NewContext(context.Background())
    defer cancel()

    ctx, cancel = context.WithTimeout(ctx, 45*time.Second)
    defer cancel()

    var text string
    err := chromedp.Run(ctx,
        chromedp.Navigate("https://example.com/app"),
        chromedp.WaitVisible(`main`, chromedp.ByQuery),
        chromedp.Click(`button[data-load]`, chromedp.ByQuery),
        chromedp.WaitVisible(`.results`, chromedp.ByQuery),
        chromedp.Text(`.results`, &text, chromedp.ByQuery),
    )
    if err != nil { log.Fatal(err) }
    log.Println(text)
}
Run Chrome in an environment that has a compatible browser binary. In containers, configure the executable path, sandbox policy, shared memory, and resource limits according to your deployment. Reuse a browser context where safe, but isolate cookies and credentials between tenants.
Wait for the condition you need
- Selector: wait until the result element exists or is visible.
- Network: wait for the application’s request to finish when the page has a reliable request boundary.
- Delay: use only for unavoidable timers; fixed sleeps increase latency and still can miss slow responses.
- State: wait for a text change, URL change, or JavaScript condition when the UI has no stable selector.
Always set a context timeout. A page can keep a connection open forever, retry a failed API call, or wait for an unavailable third-party resource.
Combine the tools in a practical pipeline
- Use Colly to discover and schedule URLs.
- For each response, parse static fields with goquery.
- Classify pages that need JavaScript, such as those with an empty content shell or an interaction-only result.
- Send only those pages to a bounded chromedp worker pool.
- Store normalized records with the source URL, retrieval time, status, and extraction errors.
This hybrid design keeps a browser from becoming the default cost and failure point while preserving a path for dynamic pages. Do not assume that a browser-rendered DOM contains the same data as an API response; validate the fields you need.
Relevant Colly controls
- Scope: allowed domains, URL filters, and link filters prevent accidental expansion.
- Depth: cap recursive discovery for sites with calendars, faceted navigation, or infinite URL spaces.
- Rate: set per-domain delay and parallelism that the target can handle.
- Retries: retry transient network failures with a limit and backoff; do not retry every 4xx response.
- Cookies and headers: supply a session only when you are authorized to use it; avoid logging secrets.
- Cache: cache stable pages to reduce repeat traffic and make reruns reproducible.
- Robots.txt: leave checking enabled unless you have a documented reason and authorization to change it.
- Callbacks: handle response, HTML, request, error, and scrape completion events separately so failures are observable.
Edge cases to design for
Pagination and duplicate URLs
Canonicalize URLs before visiting them. Strip tracking parameters only when you know they do not change content. Track visited URLs and enforce a maximum page count. Pagination controls can form cycles or expose millions of combinations.
Malformed or partial HTML
goquery is tolerant of many malformed documents, but a missing element is still a valid parse. Treat an empty selector result as a data-quality signal, not automatically as a successful extraction.
Encoding, compression, and large bodies
Check the response status and content type. Set a maximum body size, and avoid retaining entire documents when you only need a few fields. Preserve Unicode in your output and normalize before comparison.
JavaScript challenges and bot checks
A browser can execute a page, but it does not grant permission to bypass access controls. Stop when a site presents a challenge you are not authorized to solve. Record the page classification and avoid treating challenge HTML as real content.
Authentication and personal data
Keep credentials in a secret manager, use the narrowest account, and redact cookies and authorization headers from logs. Separate authenticated sessions per customer and define retention for collected personal data.
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| No links are discovered | Relative URLs, a restrictive domain rule, or links created by JavaScript. | Use AbsoluteURL, inspect allowed domains, and route dynamic navigation through chromedp. |
| Selector returns nothing | Wrong selector, changed markup, or content loaded later. | Inspect the raw response, add a stable selector, or wait for the rendered element. |
| Requests stop at a login page | Missing session cookies or authorization. | Authenticate through an approved flow and attach the resulting session securely. |
| Frequent timeouts | Slow origin, hanging resources, or an overly short deadline. | Set separate connect and overall timeouts, wait on a real condition, and cap retries. |
| HTTP 429 responses | Request rate is too high. | Lower parallelism, add per-domain delay and backoff, cache results, and honor site guidance. |
| Chromedp cannot start | Chrome is absent, incompatible, or blocked by container limits. | Install a compatible browser, set its executable path, and review sandbox and shared-memory configuration. |
| Data looks like a challenge page | Bot protection or an access-denied response. | Classify it as a failed fetch, stop retries, and use an authorized integration if one exists. |
Performance, reliability, and cost
HTTP fetching and HTML parsing usually consume fewer resources than a full browser process, but the actual difference depends on the target, response size, concurrency, and extraction work. The reviewed sources do not establish a comparable benchmark for Colly, goquery, and chromedp. Benchmark your workload with fixed URLs, cold and warm caches, error rates, and a defined concurrency level.
- Throughput: increase concurrency gradually while watching response codes, latency, memory, and target-site feedback.
- Memory: browser tabs and retained documents are expensive; close tabs and bound queues.
- Reliability: use idempotent jobs, checkpoints, bounded retries, and durable error records.
- Freshness: choose cache TTLs based on how often the source changes, not on a universal default.
- Cost: account for compute, bandwidth, browser images, proxy or data services, and engineering time. A faster crawler can still be more expensive if it causes retries or blocks.
Or skip the browser setup
If your goal is a clean screenshot rather than a custom extraction pipeline, ScreenshotNeo provides a single GET request for PNG, JPEG, WebP, or PDF output. It accepts cookie and consent banners like a visitor, then removes more than 60 known consent platforms, newsletter popups, and chat widgets; each cleanup step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers.

See the ScreenshotNeo API documentation for the complete option list. You can request full-page captures with lazy images loaded, a CSS-selected element, dark mode, device presets or any viewport, retina scale, PDF paper size and margins, custom CSS and JavaScript, clicks, selector or network-idle waits, blocked ads and trackers, custom headers and cookies, timezone and geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs, webhooks, bulk capture, and usage data.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('shot.webp', buffer);
ScreenshotNeo also includes an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots each month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
Frequently asked questions
Is goquery a scraper?
No. It queries and manipulates an HTML document. Pair it with Colly or another HTTP client.
Can Colly execute JavaScript?
Colly is an HTTP crawling framework. Send pages that require browser execution to chromedp or another authorized browser service.
Should every page use chromedp?
No. Use the lightest layer that contains the data you need, and reserve a browser for rendering or interaction requirements.
How do I compare performance?
Use your real domains and selectors, then measure throughput, latency, memory, error rate, and resource cost under a fixed workload. Existing sources do not provide a controlled cross-tool benchmark.
Does a robots.txt setting settle permission?
No. Robots handling is an implementation control. Review the site’s terms, authorization, and applicable law separately.