How to Add HTML Headers and Footers to PDFs With iTextPDF in Java
Add repeating HTML headers and footers to multi-page PDFs with the correct iText 5 or iText 7 approach, margins, events, troubleshooting, and code.
To add repeating HTML headers and footers to a PDF in Java, first identify your iText generation. iText 5 uses XML Worker, PdfPageEventHelper, ColumnText, and the writer’s direct content. iText 7 uses pdfHTML and a PdfDocument event handler. These APIs are not interchangeable.
For iText 5, parse each HTML fragment once, store the resulting ElementList, and draw it in bounded header and footer rectangles from onEndPage. For iText 7+, register an event handler before HTML conversion and render the repeated furniture with the pdfHTML-compatible API used by your dependency version. Reserve matching top and bottom margins so body content never overlaps the repeated regions.
Choose the implementation that matches your iText version
| Project | Header/footer API | HTML conversion | Typical decision |
|---|---|---|---|
| iText 5 | PdfPageEventHelper.onEndPage |
XML Worker | Maintain an existing iText 5 application |
| iText 7+ | IEventHandler on PdfDocument |
pdfHTML | New work or an upgrade using current iText APIs |
iText’s conversion tutorial distinguishes the obsolete, limited HTMLWorker from XML Worker and pdfHTML. Confirm the major version and the exact deployed dependency versions before copying imports or callback types. The official iText 5 example and the pdfHTML reporting examples show different event models: iText 5 HTML header/footer example and iText 7 and pdfHTML documentation.
iText 5: repeating HTML with XML Worker
This path is appropriate when the application already creates PDFs with iText 5. The important details are:
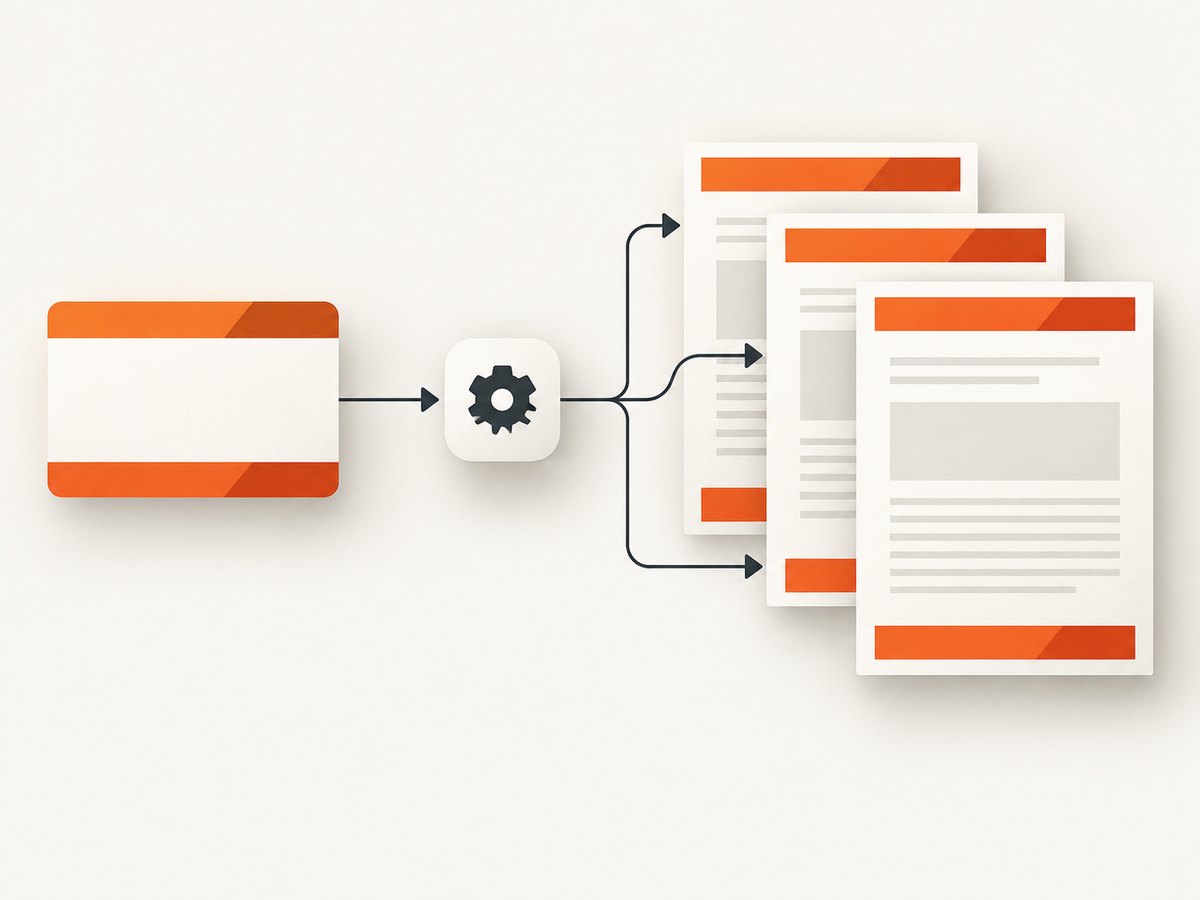
- Parse static header and footer HTML once, before document generation.
- Keep the parsed
ElementListobjects in the page-event class. - Use
ColumnTextwithwriter.getDirectContent()inonEndPage. - Never add content to the
Documentfrom the page callback. - Coordinate the rectangles with the document’s margins.
Complete Maven dependencies
<dependencies>
  <dependency>
    <groupId>com.itextpdf</groupId>
    <artifactId>itextpdf</artifactId>
    <version>5.5.13.3</version>
  </dependency>
  <dependency>
    <groupId>com.itextpdf.tool</groupId>
    <artifactId>xmlworker</artifactId>
    <version>5.5.13.3</version>
  </dependency>
</dependencies>
Use the versions approved for your application and verify current licensing and release documentation before adopting or upgrading iText.
Runnable iText 5 example
import com.itextpdf.text.Document;
import com.itextpdf.text.Element;
import com.itextpdf.text.PageSize;
import com.itextpdf.text.Rectangle;
import com.itextpdf.text.pdf.ColumnText;
import com.itextpdf.text.pdf.PdfPageEventHelper;
import com.itextpdf.text.pdf.PdfWriter;
import com.itextpdf.tool.xml.ElementList;
import com.itextpdf.tool.xml.XMLWorkerHelper;

import java.io.FileOutputStream;
import java.io.StringReader;

public class IText5HtmlFurniture {
    static class HtmlHeaderFooter extends PdfPageEventHelper {
        private final ElementList header;
        private final ElementList footer;
        private final float left;
        private final float right;

        HtmlHeaderFooter(String headerHtml, String footerHtml,
                         float left, float right) throws Exception {
            this.header = new ElementList();
            this.footer = new ElementList();
            XMLWorkerHelper.getInstance().parseToElementList(
                    headerHtml, null, header);
            XMLWorkerHelper.getInstance().parseToElementList(
                    footerHtml, null, footer);
            this.left = left;
            this.right = right;
        }

        private void draw(ElementList elements, PdfWriter writer,
                          Rectangle page, float bottom, float top) {
            ColumnText column = new ColumnText(writer.getDirectContent());
            column.setSimpleColumn(left, bottom, right, top);
            for (Element element : elements) {
                column.addElement(element);
            }
            try {
                column.go();
            } catch (Exception e) {
                throw new RuntimeException("Could not render page furniture", e);
            }
        }

        @Override
        public void onEndPage(PdfWriter writer, Document document) {
            Rectangle page = document.getPageSize();
            float headerBottom = page.getTop() - 52;
            float headerTop = page.getTop() - 18;
            float footerBottom = page.getBottom() + 18;
            float footerTop = page.getBottom() + 46;
            draw(header, writer, page, headerBottom, headerTop);
            draw(footer, writer, page, footerBottom, footerTop);
        }
    }

    public static void main(String[] args) throws Exception {
        String headerHtml = "<table style='width:100%'>"
                + "<tr><td>Acme report</td>"
                + "<td align='right'>Quarterly results</td>"
                + "</tr></table>";
        String footerHtml = "<table style='width:100%'>"
                + "<tr><td>Internal</td>"
                + "<td align='right'>Generated report</td>"
                + "</tr></table>";

        Document document = new Document(PageSize.A4, 42, 42, 82, 65);
        PdfWriter writer = PdfWriter.getInstance(
                document, new FileOutputStream("itext5-header-footer.pdf"));
        writer.setPageEvent(new HtmlHeaderFooter(headerHtml, footerHtml, 42, 553));
        document.open();
        for (int i = 1; i <= 8; i++) {
            document.add(new com.itextpdf.text.Paragraph(
                    "Body paragraph " + i + ": content flows inside the reserved margins."));
            document.add(new com.itextpdf.text.Paragraph(
                    "Add enough text here to force multiple pages and inspect every page."));
        }
        document.close();
    }
}
The coordinates above are for an A4-style example and are deliberately tied to the chosen margins. They are not universal constants. For a different page size, calculate the rectangle from page.getTop(), page.getBottom(), and the actual left/right margins.
Why parsing once matters
parseToElementList converts the HTML fragment into reusable iText elements. Doing this in the constructor avoids reparsing markup on every page. The event still lays out those elements for each page, but the conversion cost is paid once. Keep the fragments short and bounded; a long paragraph or a large table can overflow the rectangle.
iText 7+: pdfHTML with a page event handler
For iText 7, use the pdfHTML add-on and the event-handler model. Register the handler on the PdfDocument before conversion. The exact imports and overloads depend on the pdfHTML version, so compare your dependency’s API with the official pdfHTML examples and API reference.
Project dependencies
<dependency>
  <groupId>com.itextpdf</groupId>
  <artifactId>kernel</artifactId>
  <version>YOUR_ITEXT7_VERSION</version>
</dependency>
<dependency>
  <groupId>com.itextpdf</groupId>
  <artifactId>layout</artifactId>
  <version>YOUR_ITEXT7_VERSION</version>
</dependency>
<dependency>
  <groupId>com.itextpdf</groupId>
  <artifactId>html2pdf</artifactId>
  <version>YOUR_PDFHTML_VERSION</version>
</dependency>
Event-handler pattern
import com.itextpdf.html2pdf.HtmlConverter;
import com.itextpdf.kernel.events.Event;
import com.itextpdf.kernel.events.IEventHandler;
import com.itextpdf.kernel.events.PdfDocumentEvent;
import com.itextpdf.kernel.pdf.PdfDocument;
import com.itextpdf.kernel.pdf.PdfPage;
import com.itextpdf.kernel.pdf.PdfWriter;
import com.itextpdf.kernel.pdf.canvas.PdfCanvas;
import com.itextpdf.layout.Canvas;
import com.itextpdf.layout.element.Paragraph;
import com.itextpdf.layout.properties.TextAlignment;

import java.io.FileInputStream;
import java.io.FileOutputStream;

public class IText7HtmlFurniture {
    static class HeaderFooterHandler implements IEventHandler {
        @Override
        public void handleEvent(Event event) {
            PdfDocumentEvent documentEvent = (PdfDocumentEvent) event;
            PdfDocument pdf = documentEvent.getDocument();
            PdfPage page = documentEvent.getPage();
            float width = page.getPageSize().getWidth();
            float height = page.getPageSize().getHeight();
            PdfCanvas canvas = new PdfCanvas(page.newContentStreamBefore(),
                    page.getResources(), pdf);
            try (Canvas layout = new Canvas(canvas, page.getPageSize())) {
                layout.showTextAligned(new Paragraph("Acme report"),
                        42, height - 36, TextAlignment.LEFT);
                layout.showTextAligned(new Paragraph("Generated report"),
                        width - 42, 28, TextAlignment.RIGHT);
            }
        }
    }

    public static void main(String[] args) throws Exception {
        PdfWriter writer = new PdfWriter(new FileOutputStream("itext7-output.pdf"));
        PdfDocument pdf = new PdfDocument(writer);
        pdf.addEventHandler(PdfDocumentEvent.END_PAGE, new HeaderFooterHandler());
        HtmlConverter.convertToPdf(new FileInputStream("body.html"), pdf);
        pdf.close();
    }
}
This handler demonstrates the event lifecycle and a simple text header/footer. If your header or footer itself must be HTML, follow the pdfHTML version’s official header/footer example and use the supported conversion overloads. Do not paste an iText 5 ColumnText callback into an iText 7 project. The reporting tutorial’s core pattern is the same: create the PdfDocument, register an IEventHandler, then convert the document.
Reserve space and control layout
- Measure the tallest expected header and footer, including wrapping and images.
- Set the document’s top and bottom margins larger than those regions plus a safety gap.
- Use the same left and right margins for body and furniture unless the design intentionally differs.
- Test A4, Letter, landscape, and custom page sizes separately.
- Check the first page and pages after explicit page breaks.
A header rectangle that is 34 points high cannot safely contain a two-line table with a 14-point font and padding. Increase the reserved height or reduce the content. In iText 5, the ColumnText rectangle clips or overflows according to the layout result; it does not automatically move body content down. In iText 7, the event handler similarly paints into page coordinates while the converted body follows its own margins.
HTML and CSS limits
XML Worker is not a browser engine. Small tables, inline styles, basic text alignment, colors, and simple borders are safer than modern responsive CSS. Full HTML pages, flexbox, grid, JavaScript, web fonts, and browser-only layout assumptions require a compatible pdfHTML workflow or a different rendering strategy. Keep header/footer fragments self-contained and provide fonts or images through supported resource providers when the chosen version requires them.
Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| Header appears only on page one | It was added to the document body instead of a page event | Register the event handler and draw on every end-page event. |
| Body text overlaps furniture | Top or bottom margins are too small | Increase margins to exceed the measured rectangles. |
| Exception on the second page | Content was added to Document inside onEndPage |
Use writer direct content and ColumnText; never mutate the document there. |
| Nothing renders from HTML | Unsupported markup, missing XML Worker/pdfHTML dependency, or malformed fragment | Reduce the fragment to a simple table, verify dependencies, and inspect conversion logs. |
| Footer is clipped | The rectangle is too short or positioned outside the page | Use page dimensions, increase its height, and keep it inside the bottom margin. |
| Wrong imports or missing methods | iText 5 code was used with iText 7, or versions are mixed | Align all artifacts to one major generation and consult that version’s API. |
| Images or fonts disappear | Relative resources cannot be resolved | Use absolute or configured resource paths and embed supported fonts. |
Testing checklist for multi-page PDFs
- Generate at least three pages with natural wrapping.
- Force a page break immediately before and after a heading.
- Use a long header title and a long footer value.
- Render both portrait and landscape pages if the application supports them.
- Open the PDF in more than one viewer and inspect extraction order if accessibility or text search matters.
- Verify that page furniture does not cover links, tables, images, or list markers.
- Measure generation time with and without repeated HTML parsing to catch accidental per-page conversion.
Performance, reliability, and cost considerations
For iText 5, parsing static fragments once is the clearest performance win. Reusing event objects also reduces allocation. Keep header/footer markup small, avoid unnecessary images, and use a bounded rectangle. For iText 7, reuse immutable configuration where practical and avoid doing network work from an end-page handler. Rendering must remain deterministic: load fonts and assets from controlled locations, and fail clearly when a required resource is missing.
PDF generation is local application work, so cost is usually CPU, memory, storage, and any commercial licensing obligations of the iText packages. The research sources do not establish current license terms; check the official release and licensing documentation for your deployment. Do not treat sample coordinates as a compatibility guarantee: validate the exact versions, fonts, page sizes, and HTML used by your application.
Or skip the browser setup
If your real goal is a clean image or PDF of a web page rather than composing a PDF in Java, ScreenshotNeo provides a single website screenshot API request. It accepts cookie and consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response reports the result with X-Page-Verdict and X-Billed headers. It also offers an MCP server for Claude, Cursor, and other MCP clients, with take_screenshot, get_page_info, and capture_pdf tools.
See the ScreenshotNeo API documentation for all options, including full-page capture, CSS selectors, device presets, retina scale, PDF paper size and margins, custom CSS and JavaScript, click and wait actions, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs, bulk capture, usage, and the OpenAPI specification.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
ScreenshotNeo includes 1,000 screenshots per month on the free plan with no card. Paid plans start at $5 for 3,000 screenshots; every feature is available on every plan. Create a free ScreenshotNeo account.
FAQ
Can I use iText 5 XML Worker with arbitrary website HTML?
No. XML Worker handles a constrained subset of markup and CSS. Browser HTML often needs pdfHTML or a browser-based renderer.
Should the header be part of the HTML body?
Use a page event for repeated furniture. Keeping it separate prevents normal body flow from treating the header as one-time content.
Why does a two-page document expose a bug?
The first page can hide incorrect event timing or margin calculations. Later pages reveal whether the callback is registered and whether the rectangle is valid for every page.
Can headers include page numbers?
Yes, but obtain the current page number from the event’s PDF document and draw it in the handler. Keep the page-number element inside the reserved rectangle.
When should I choose ScreenshotNeo?
Choose it when you need a rendered website capture or PDF and want cookie banners, popups, chat widgets, failed loads, and bot checks handled by an API rather than maintaining browser automation.