Python Web Scraping Tutorial for 2026 with Examples and Best Practices
Learn a responsible Python scraping workflow with Requests, Beautiful Soup, Scrapy and Playwright, including validation, dynamic pages and production practices.

To scrape a website with Python, first confirm that you may access it and that an official API or feed is not available. Then use the simplest pipeline that fits the page: fetch HTML with Requests, parse it with Beautiful Soup, normalize and validate the fields, and store the results. Use Scrapy when you need a multi-page crawl, and use a browser such as Playwright only when the required data is available after rendering and cannot reasonably be obtained from an underlying request.
This tutorial builds that workflow for 2026. The examples are illustrative: run them only against a site you own, have permission to access, or that explicitly permits the intended use. Check terms and robots.txt; robots rules guide crawlers but do not grant legal authorization. The RFC 9309 specification describes the protocol and its limits.
1. Define the target and output before writing code
Write down the exact fields you need. For a catalog, that might be title, price, detail_url and availability. Prefer an official API or documented data feed when one exists. Limiting collection to necessary fields reduces load, simplifies validation and makes permission questions clearer.
- Choose an authorized target and document its terms.
- List required fields and their expected types.
- Record the starting URL and pagination rules.
- Decide where incomplete records go: reject, flag for review or retain with null values.
2. Install Requests and Beautiful Soup
python -m venv .venv
# macOS/Linux
source .venv/bin/activate
# Windows PowerShell: .venv\\Scripts\\Activate.ps1

python -m pip install requests beautifulsoup4
Requests handles HTTP fetching while Beautiful Soup searches and parses the returned markup. Their documentation covers the core request and parser APIs: Requests Quickstart and Beautiful Soup documentation.

3. Fetch a static page safely
import requests
from bs4 import BeautifulSoup

url = "https://example.com/page"
headers = {"User-Agent": "ExampleResearchBot/1.0 (contact: you@example.com)"}

response = requests.get(url, headers=headers, timeout=15)
response.raise_for_status()
soup = BeautifulSoup(response.text, "html.parser")

title = soup.title.get_text(" ", strip=True) if soup.title else None
print(title or "No title")
The timeout prevents an unavailable server from holding your worker forever. raise_for_status() turns 4xx and 5xx responses into visible errors instead of letting bad HTML flow through the pipeline. The example domain is a placeholder, not a recommendation or a claim that it permits scraping.
Use stable selectors and tolerate missing elements
from urllib.parse import urljoin

card = soup.select_one("article.product")
if card is None:
    raise ValueError("Expected product card was not found")

def text_or_none(node):
    return node.get_text(" ", strip=True) if node else None

title = text_or_none(card.select_one("h2"))
price = text_or_none(card.select_one(".price"))
link = card.select_one("a[href]")
detail_url = urljoin(response.url, link["href"]) if link else None

record = {"title": title, "price": price, "detail_url": detail_url}
print(record)
Do not index select(...)[0] unless you have checked that a match exists. Markup changes, optional fields and error pages are normal operating conditions. Scrapy’s tutorial makes the same maintainability point: extraction should remain useful when some elements are absent.
4. Normalize, validate and deduplicate records
Parsing gives you strings; a usable dataset needs consistent values. Strip whitespace, resolve relative URLs against the final response URL, parse numbers with an explicit locale policy and validate required fields.
from urllib.parse import urlparse

def valid_http_url(value):
    if not value:
        return False
    parsed = urlparse(value)
    return parsed.scheme in {"http", "https"} and bool(parsed.netloc)

normalized = {
    "title": (record["title"] or "").strip() or None,
    "price": (record["price"] or "").strip() or None,
    "detail_url": record["detail_url"],
}

if not normalized["title"] or not valid_http_url(normalized["detail_url"]):
    normalized["valid"] = False
else:
    normalized["valid"] = True

# A simple in-memory deduplication key
seen = set()
key = normalized["detail_url"]
if normalized["valid"] and key not in seen:
    seen.add(key)
    print(normalized)
For durable jobs, write rejected records and the reason to a separate file or table. Keep a small saved HTML fixture and run your parser against it after selector changes; this catches markup regressions without repeatedly requesting a live site.
5. Pagination and multi-page jobs with Scrapy
Requests plus a loop can handle a few pages, but a crawler framework is easier to operate when you need callbacks, link following, retries, throttling and exports. Scrapy provides spiders, requests, selectors and crawl state in one project workflow. Follow its official tutorial for project creation and the practice quotes site.
python -m pip install scrapy
scrapy startproject quotes_project
cd quotes_project
scrapy genspider quotes quotes.toscrape.com
import scrapy
class QuotesSpider(scrapy.Spider):
name = "quotes"
allowed_domains = ["quotes.toscrape.com"]
start_urls = ["https://quotes.toscrape.com/"]
def parse(self, response):
for item in response.css(".quote"):
quote = item.css(".text::text").get()
author = item.css(".author::text").get()
yield {
"text": quote.strip() if quote else None,
"author": author.strip() if author else None,
}
next_href = response.css("li.next a::attr(href)").get()
if next_href:
yield response.follow(next_href, callback=self.parse)Run an export with scrapy crawl quotes -O quotes.json. Use scrapy shell https://your-authorized-site.example/page to inspect selectors interactively. CSS and XPath selectors can both return no match; code your spider for that case.
Robots rules and polite crawl settings
# settings.py
ROBOTSTXT_OBEY = True
USER_AGENT = "ExampleResearchBot/1.0 (contact: you@example.com)"
DOWNLOAD_DELAY = 1.0
CONCURRENT_REQUESTS_PER_DOMAIN = 2
Identify your crawler with a descriptive user agent, obey the target’s published instructions, keep concurrency proportionate and stop when access is denied or disallowed. Scrapy can enforce robots rules with its middleware. These controls are operational safeguards, not a statement that a crawl is legally permitted everywhere.
6. JavaScript-rendered pages: find the data source first
If the HTML response lacks the records you see in a browser, open developer tools and inspect network requests while the page loads. Look for a documented or clearly observable request that returns the data, then reproduce that request with Requests when the site permits it. This is usually simpler, faster and easier to validate than rendering every page. Scrapy’s guidance recommends locating the data source first.
Use browser automation when the needed information exists only after browser execution, interaction or DOM rendering. Playwright for Python is one option:
python -m pip install playwright
playwright install chromium
from playwright.sync_api import sync_playwright
with sync_playwright() as p:
browser = p.chromium.launch(headless=True)
page = browser.new_page()
page.goto("https://example.com", wait_until="domcontentloaded", timeout=30_000)
page.wait_for_selector("article.product", timeout=10_000)
titles = page.locator("article.product h2").all_text_contents()
print([title.strip() for title in titles])
browser.close()Do not treat a headless browser as a way to defeat access controls. If a site blocks or disallows the activity, stop. Browser sessions also require more memory, startup time and failure handling than direct HTTP requests.
7. Security for URL-driven scrapers
A crawler that accepts URLs from users or files is processing untrusted input. Allow only http and https, validate hostnames against an allowlist where possible, and prevent access to internal network ranges. Never expose a crawl control endpoint to an untrusted network, and keep API keys out of source control and logs.
from urllib.parse import urlparse

def approved_url(value, allowed_hosts):
    parsed = urlparse(value)
    return (
        parsed.scheme in {"http", "https"}
        and parsed.hostname in allowed_hosts
    )
8. Common errors and fixes
| Error | Likely cause | Fix |
|---|---|---|
ReadTimeout |
Slow server or overly broad request | Set finite connect/read timeouts, reduce scope and retry only idempotent requests with a limit. |
HTTPError: 403 |
Access denied or policy restriction | Check terms and robots instructions, identify your client honestly and stop if access is not permitted. |
| Empty selector results | Wrong selector, changed markup or JavaScript content | Save the response, inspect it, verify the selector, then inspect network data or use a browser only when appropriate. |
| Relative links | href is not an absolute URL |
Use urljoin(response.url, href). |
| Duplicate rows | Pagination repeats items or multiple links point to one record | Deduplicate on a canonical URL or stable identifier. |
| Unicode or encoding errors | Incorrect assumption about response encoding | Prefer response.text, inspect response.encoding and preserve UTF-8 output. |
| Browser timeout | Selector never appears or page keeps loading | Wait for a specific selector, use a bounded timeout and capture diagnostics before retrying. |
9. Performance, reliability and cost decisions
- Start at the HTTP layer. Direct requests avoid browser startup and use fewer resources.
- Bound every wait. Set connect, read and navigation timeouts; cap retries and record failures.
- Control concurrency. Small delays and per-domain limits protect both your job and the target.
- Cache responsibly. Reuse responses during development and avoid downloading unchanged pages unnecessarily.
- Measure completeness. Track requested, successful, rejected and duplicate records, plus missing-field counts.
- Design for restart. Persist crawl state or stable keys so a failed run can resume without duplicating output.
- Budget browser work. Render only URLs that need it; browser processes consume more CPU and memory than HTTP clients.
10. Or skip the browser setup
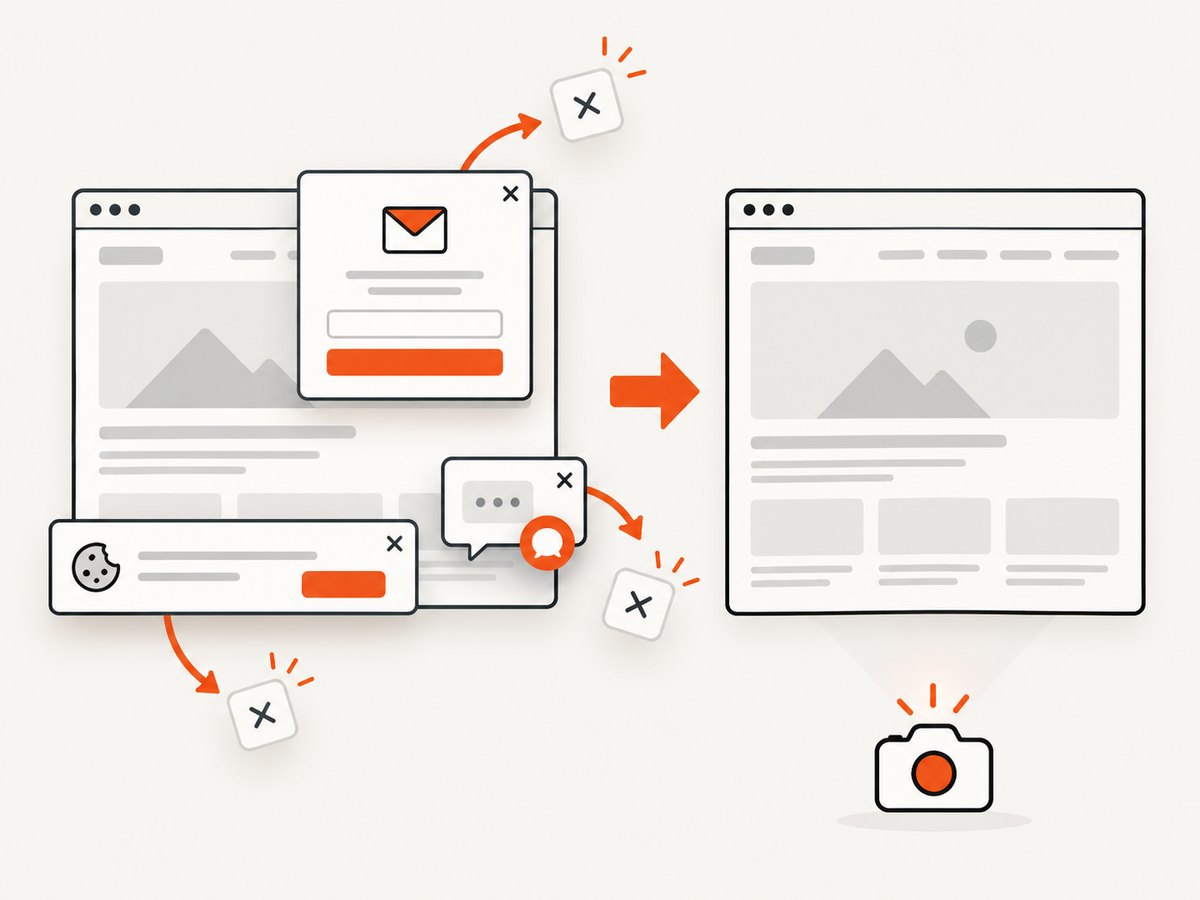
ScreenshotNeo provides a website screenshot API when your workflow needs a rendered visual rather than extracted text. It accepts a URL and returns PNG, JPEG, WebP or PDF. Cookie and consent banners, newsletter popups and chat widgets are removed before capture, and each cleanup step can be turned off. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads and cache hits are not billed; response headers report the page verdict and whether the shot was billed.
See the ScreenshotNeo API documentation for all options, including full-page lazy-image loading, CSS-element capture, dark mode, device presets, custom viewports, retina scale, PDF controls, custom CSS and JavaScript, clicks, waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, TTL caching, signed links, asynchronous webhooks, bulk capture and usage reporting.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
require('node:fs').writeFileSync('shot.webp', Buffer.from(await res.arrayBuffer()));ScreenshotNeo also has an MCP server with take_screenshot, get_page_info and capture_pdf tools for Claude, Cursor and other MCP clients. The Free plan includes 1,000 shots per month with no card; paid plans start at $5 for 3,000 shots, and every feature is available on every plan. Create a free ScreenshotNeo account.
11. A practical checklist
- Permission, terms and robots instructions checked.
- Official API or feed evaluated first.
- Fields and validation rules written down.
- Finite timeouts, status checks and bounded retries configured.
- Missing selectors, duplicates and malformed URLs handled.
- User agent identifies the crawler.
- Concurrency and delay are proportionate.
- Fixtures or sample responses cover parser regressions.
- Secrets are stored outside source code.
- Logs record counts and failure reasons without sensitive data.
FAQ
Which Python library should I use for web scraping?
Use Requests and Beautiful Soup for one or a few static pages, Scrapy for structured multi-page crawling, and Playwright when browser rendering is genuinely required.
Should I always use Selenium or Playwright?
No. First inspect the network requests that provide the data. Browser automation is a fallback for browser-only behavior and costs more operationally.
Does robots.txt make scraping legal?
No. It provides crawler instructions. Authorization and legal obligations depend on the target, data, access method, contracts, jurisdiction and intended use.
How do I keep a scraper from breaking?
Use stable selectors, tolerate missing fields, validate output, save fixtures, monitor missing-value rates and stop cleanly when the target changes or denies access.