How to Test AI Agents: Tools and Techniques
Build repeatable AI agent evaluations that check tool use, outcomes, conversation state, and safety—and interpret scores in context.

To test an AI agent, give it representative tasks in a controlled environment, record its tool calls and state changes, and grade both the path and the outcome against explicit criteria. Repeat variable tasks, inspect failures, and report the exact model, tools, harness, safeguards, and resource budget. An evaluation measures that complete configuration—not an abstract model capability.
This guide covers a practical workflow, runnable evaluation scaffolding, grader choices, trace inspection, reliability and cost, and common failure modes. Use it to find out whether an agent chose an appropriate tool, supplied sound arguments, reached the intended result, and handled context safely.
1. Define what the evaluation is meant to establish
Start with a claim narrow enough to test. Examples include: “The agent can retrieve an order status with the approved lookup tool,” “The agent does not issue refunds above its limit,” or “Version B completes this support task more reliably than version A under the same budget.” Capability, safeguard performance, and system comparisons require different cases and reporting.
For every case, write down the user input, starting environment state, permitted tools, expected outcome, and success criteria. Include what must not happen, especially when tools can send messages, change records, spend money, or expose data. A task that merely asks whether the final prose sounds plausible can miss an unsafe action taken along the way.
| Test layer | What to check | Example evidence |
|---|---|---|
| Tool call | Tool selection and argument values | Correct lookup tool; valid order ID |
| Run or trace | Full path, handoffs, final answer, artifacts | Lookup result supports the response |
| Environment | External state and side effects | No refund issued without authorization |
| Conversation thread | Context and memory across turns | Agent retains the selected account correctly |
Do not demand one exact sequence of calls unless order itself is required for correctness or safety. An agent may reach a valid result through a different route. OpenAI’s [agent evaluation guide](https://developers.openai.com/api/docs/guides/agent-evals) recommends looking at traces and trace grading while debugging, then using datasets and evaluation runs for repeatable comparisons. LangChain’s [run, trace, and thread guidance](https://www.langchain.com/resources/agent-evals) is another practitioner reference for matching the evaluation level to the system.
2. Build a representative task set and capture traces
A useful suite contains ordinary tasks, edge cases, and realistic failure cases from the intended deployment. Include missing or malformed inputs, ambiguous requests, tool errors, empty results, stale context, retries, and requests that should be declined or escalated. Preserve real incidents as regression cases after removing sensitive data and making the expected behavior explicit.
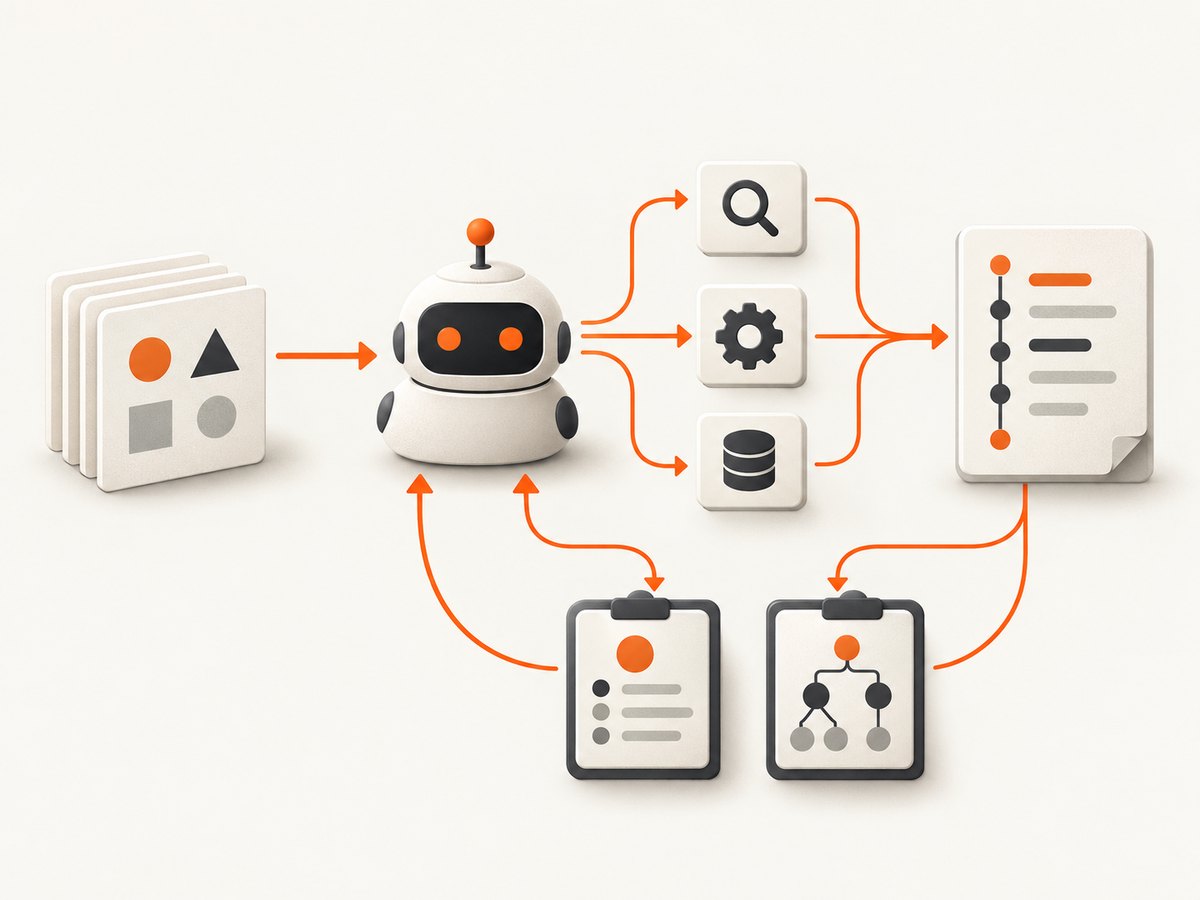
Record enough information to reconstruct a run: input, model and settings, tool definitions, tool arguments and outputs, handoffs, guardrail decisions, timestamps, retries, final response, and resulting environment state. Avoid logging secrets or unnecessary personal data; use redaction or synthetic values where possible. A screenshot or other artifact can help verify what a browser-using agent actually saw, but it complements the structured trace rather than replacing it.
For web tasks, a screenshot can be a concrete artifact check: did the agent capture the requested page or element, and did it handle a consent banner, popup, or loading state? ScreenshotNeo provides a website screenshot API and an MCP server for AI agents, with tools named take_screenshot, get_page_info, and capture_pdf. That can make page evidence available as part of an agent workflow; the evaluation still needs to check whether the agent selected the right action and interpreted the result correctly.
3. Create a repeatable evaluation in Python
The following small harness illustrates the important boundary: the agent adapter returns a trace and an observable environment state, while independent checks grade tool behavior and outcome. Replace run_agent with your framework’s invocation and connect read_state to a disposable test environment. The deterministic assertions below are intentionally simple; they are not a substitute for testing your actual policy and tools.
from dataclasses import dataclass
from typing import Any

@dataclass
class Case:
    name: str
    prompt: str
    expected_order: str
    expected_status: str

# Your adapter should return the full execution trace and the isolated
# environment's resulting state. Do not use production side-effecting tools.
def run_agent(prompt: str) -> tuple[dict[str, Any], dict[str, Any]]:
    raise NotImplementedError("Connect your agent and test environment")

cases = [
    Case("known order", "Check order A-104 status", "A-104", "shipped"),
]

def grade(case: Case, trace: dict[str, Any], state: dict[str, Any]) -> dict[str, bool]:
    calls = trace.get("tool_calls", [])
    lookup_calls = [c for c in calls if c.get("name") == "lookup_order"]
    correct_call = any(
        c.get("arguments", {}).get("order_id") == case.expected_order
        for c in lookup_calls
    )
    correct_state = state.get("order_status") == case.expected_status
    answer = trace.get("final_text", "").lower()
    grounded_answer = case.expected_status in answer
    return {
        "correct_tool_argument": correct_call,
        "expected_environment_state": correct_state,
        "final_answer_matches_result": grounded_answer,
    }

for case in cases:
    trace, state = run_agent(case.prompt)
    checks = grade(case, trace, state)
    print(case.name, checks, "pass=" + str(all(checks.values())))
Keep the trace format stable enough that you can compare runs, but retain raw events so you can inspect a grader disagreement. For side effects, reset the environment before each trial or give every run a unique isolated fixture. Record failures rather than silently retrying until one passes: retries are part of the tested system and consume budget.
4. Choose graders that match the claim
Use deterministic checks for verifiable facts: exact tool name, required argument, final database state, whether a prohibited action occurred, or whether a required field is present. These are cheap and repeatable, but brittle string matching can reject a correct paraphrase or reward an answer that only happens to contain the expected phrase.
Use executable checks when the outcome can be measured in an environment: run a query, validate a generated file, inspect a transaction record, or assert that a browser reached the intended state. Make fixtures deterministic and isolate each trial. Where the task has multiple valid solutions, express invariants rather than one golden transcript.
For nuanced qualities such as clarity, helpfulness, or whether an explanation is appropriately cautious, use blinded human review or a model grader with an explicit rubric. Randomize comparison order, define rating anchors, and test model-grader agreement against human labels. Model graders can be influenced by answer position and verbosity; a longer answer is not necessarily a better one. OpenAI’s [evaluation best practices](https://developers.openai.com/api/docs/guides/evaluation-best-practices) discuss grader strengths and limits.
Keep separate scores for task success, tool correctness, factuality, safety, and interaction quality. A single average can hide a serious safety regression behind gains in easy cases. Set pass/fail thresholds for requirements that cannot be traded off, and use aggregate scores for trends rather than as the only release gate.
5. Run trials, compare changes, and inspect failures
Agent outputs can vary between attempts, so run multiple trials for stochastic tasks. There is no universally correct trial count: choose it based on observed variability, the importance of the decision, and the evaluation budget. Use the same task set, environment conditions, and resource limits to compare prompt, model, routing, or tool changes. Report the number of trials and how you aggregate them.
During early development, run representative cases and inspect traces to locate workflow problems. Once criteria are clear, save a versioned dataset and repeat the evaluation after changes. When a score surprises you, inspect examples before changing the agent. Determine whether the cause was agent behavior, ambiguous task wording, a harness limitation, an overly rigid grader, or an environment failure.
Grader design can materially affect results. Anthropic reports that its Opus 4.5 CORE-Bench score was initially 42% and rose to 95% after addressing issues that included rigid grading, ambiguous task specifications, and stochastic tasks. Those are figures from that specific reported case, not a general correction factor for benchmarks. Read the [full discussion of agent evaluation](https://www.anthropic.com/engineering/demystifying-evals-for-ai-agents) and inspect your own transcripts.
6. Check validity, harness effects, and reporting
An evaluation score depends on the agent plus its harness: tools, context preservation, environment, retries, guardrails, and other scaffolding can all affect the result. OpenAI’s [third-party evaluation playbook](https://openai.com/index/trustworthy-third-party-evaluations-foundations/) emphasizes making the tested configuration and evaluation claim clear. If performance improves with more tokens, time, or attempts, report performance under that budget rather than calling it a capability ceiling.

- Check that the task specification permits all valid solutions and does not leak the answer.
- Look for reward hacking: can the agent pass the grader without completing the intended task?
- Review refusals, evaluation awareness, contamination, and hidden constraints.
- Verify that retries, cached results, and setup failures are counted consistently.
- For side-effecting tools, inspect resulting state and recovery behavior, not just the final message.
Report the exact claim, model and relevant settings, tools and harness, environment and safeguards, task distribution, graders and thresholds, number of attempts, retry policy, turn/token/time budgets, and costs where available. If comparing systems, include differences that may affect outcomes. When useful, report expected cost per successful solve alongside success rate. The score should let a reader understand what was tested and what it does not establish.
7. Keep the suite useful over time
Assign an owner, version task definitions and grader logic, and add cases when real failures expose a gap. Review whether the suite still reflects current user tasks. A suite that every version passes can still catch regressions, but it may no longer distinguish improvements. Do not tune solely to a fixed set of examples; refresh cases and audit for shortcuts that satisfy checks without delivering the intended outcome.
For tooling, prioritize trace capture and inspection, dataset versioning, replay, grader support, and the ability to examine environment side effects. OpenAI documents traces and datasets in its [agent workflow guide](https://developers.openai.com/api/docs/guides/agent-evals). Anthropic describes LangSmith and Langfuse in its guide; those are vendor descriptions, not an independent head-to-head review. Check current features, hosting, data handling, and pricing before choosing a platform. OpenAI also lists a scheduled Evals API transition: existing Evals content becomes read-only October 31, 2026, with shutdown scheduled November 30, 2026. Confirm the [official Evals documentation](https://developers.openai.com/api/docs/guides/evals) before planning around those dates.
Or skip the browser setup
If an agent evaluation needs website screenshots as evidence, ScreenshotNeo can return an image or PDF from one GET request. See the [ScreenshotNeo API documentation](https://screenshotneo.com/docs/) for request options. This cURL example saves a WebP screenshot of a sample page:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Equivalent Python and Node.js requests:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
open("shot.webp", "wb").write(r.content)
const q = new URLSearchParams({
access_key: 'YOUR_API_KEY',
url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
await Bun.write('shot.webp', res);ScreenshotNeo accepts consent banners like a visitor and removes 60+ known consent platforms, newsletter popups, and chat widgets before capture; each step can be turned off. Bot checks/CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and responses identify the page verdict and billing status in headers. Its MCP server gives AI agents screenshot, page-info, and PDF tools. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. [Try ScreenshotNeo free](https://screenshotneo.com/account/sign-up/) or learn more at [screenshotneo.com](https://screenshotneo.com).
Troubleshooting agent evaluations
| Symptom | Likely cause | Fix |
|---|---|---|
| High score, poor real-world behavior | Cases or grader allow shortcuts | Inspect traces; add counterexamples and state assertions tied to user outcomes. |
| Correct result marked wrong | Overly strict exact-match grading or ambiguous spec | Use semantic invariants where appropriate; clarify accepted outcomes and review disputed examples. |
| Scores swing between runs | Stochastic outputs, unstable fixtures, or varying budgets | Repeat trials, isolate environment state, and hold harness and limits constant. |
| Agent passes but performs an unsafe action | Only final response is graded | Assert forbidden tool calls and inspect resulting state and intermediate trace events. |
| Trace is missing tool context | Instrumentation captures only final output | Capture tool arguments, outputs, handoffs, guardrail events, and timestamps at the adapter boundary. |
| Evaluation cost grows unexpectedly | Retries, long contexts, or repeated model grading | Measure cost by case and successful solve; debug with a smaller representative set, then run the planned suite. |
Performance, reliability, and cost
Evaluation runtime is driven by the number of cases and trials, model latency, tool latency, retries, and grader work. Start with a small set to debug harness correctness; use the full maintained set for release comparisons. Parallel runs can reduce elapsed time if the environment safely isolates state and rate limits permit it. Do not parallelize shared mutable fixtures.
Reliability depends on repeatable setup as much as model behavior. Reset state, pin tool versions where practical, seed deterministic components when available, and record transient failures instead of silently discarding them. Separate infrastructure failure from agent failure in reports, while retaining both because deployment reliability includes the operational path.
Track the evaluation budget: model calls, turns, retries, tokens, wall time, and grader costs. More attempts can reveal variability but make the run more expensive. Compare changes using the same budget and consider cost per successful solve; a modest success-rate gain may have a different operational value if it requires many more tool calls.
FAQ
Should every tool call follow a fixed expected sequence?
No. Enforce ordering only when order is required for correctness or safety. Otherwise grade acceptable actions, arguments, outcomes, and prohibited side effects.
How many trials should I run?
Enough to understand variability for the decision at hand. Sources recommend multiple trials for variable outputs but do not establish one universal count.
Can a model grader be the only grader?
It can help with nuanced qualities, but validate it against human judgments and pair it with deterministic checks for facts and state that can be verified directly.
Does a passing benchmark prove deployment readiness?
No. It supports a claim about the tested tasks, harness, environment, safeguards, and budget. Production readiness also depends on whether those conditions represent deployment and whether operational failures are handled.