Generating Video, PDFs, and Images with the ChatGPT MCP Server
Learn how MCP connects ChatGPT to tools, how to analyze PDFs and generate images with OpenAI APIs, and why video generation is unavailable now.

Short answer: an MCP server gives ChatGPT or another model access to external tools. Use the Responses API with an input_file item to analyze PDFs, and use the Images API to generate, edit, or vary images. Video generation through the documented Sora 2 Videos API is no longer available: OpenAI shut down the Sora 2 models and Videos API on September 24, 2026, and has not announced a one-to-one replacement.
This guide shows the current workflow, with runnable examples, limits, security controls, and troubleshooting. It also explains where a screenshot MCP server fits when an agent needs visual information from live web pages.
1. What a ChatGPT MCP server actually does
The Model Context Protocol (MCP) is a way for a model to call tools exposed by another server. An MCP server might search a database, read a private system, create a ticket, or capture a web page. OpenAI describes remote MCP servers as services that add external capabilities to models; calls can run automatically or require explicit developer approval. A public server is configured with server_url. A private or on-premises server can be reached through Secure MCP Tunnel with a tunnel_id, and OAuth may be required. See the official MCP guide.
MCP does not itself generate pixels, parse a PDF, or create a video. It supplies a controlled tool connection. The media operation still happens in the service behind the tool or through an OpenAI API such as Responses or Images.
Remote server versus local or private server
| Deployment | Configuration | Use case | Operational concern |
|---|---|---|---|
| Public remote MCP | server_url |
Provider-hosted SaaS tools | Trust the provider and review data access |
| Private/on-premises MCP | Secure MCP Tunnel and tunnel_id |
Internal systems and firewalled services | Manage tunnel credentials and OAuth |
| Local MCP | Local process or development connector | Prototyping and workstation tools | Restrict filesystem and network permissions |
Approval and logging checklist
- Require approval for sensitive actions such as sending messages, changing records, or uploading confidential files.
- Review URLs returned by tools before allowing a browser or HTTP client to open them.
- Use provider-hosted servers you trust; OpenAI does not verify every remote MCP server.
- Log what data is sent to each MCP server and retain those logs according to your policy.
- Defend against prompt injection in pages, PDFs, and tool output. Treat retrieved text as untrusted input.
2. Analyze a PDF with the Responses API
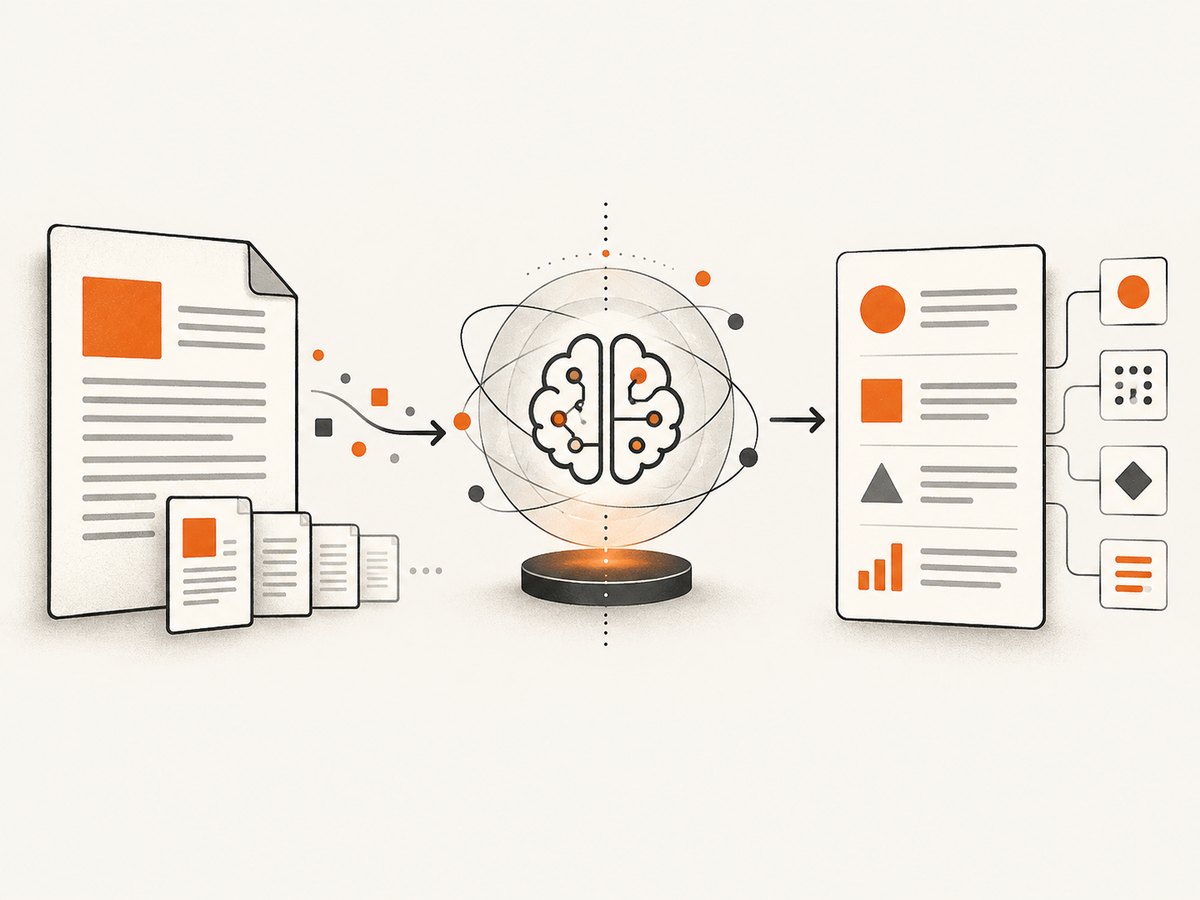
The Responses API accepts a PDF as an input_file content item. You can send a file ID or base64 data, and set the MIME type to application/pdf. PDF processing can include extracted text and page images, so visual parsing may consume more tokens. The single-file limit and the combined-file limit for one request are each 50 MB. For visual PDF parsing, use a vision-capable model such as GPT-4o or a later model. The documented detail values are auto, low, and high. See the PDF input documentation.
Python: upload and summarize a PDF
import os
from openai import OpenAI

client = OpenAI(api_key=os.environ["OPENAI_API_KEY"])

with open("report.pdf", "rb") as pdf:
    uploaded = client.files.create(file=pdf, purpose="user_data")

response = client.responses.create(
    model="gpt-4o",
    input=[{
        "role": "user",
        "content": [
            {"type": "input_file", "file_id": uploaded.id},
            {"type": "input_text", "text": "Summarize the key findings and list open risks."}
        ]
    }]
)
print(response.output_text)
cURL: send a PDF file ID
curl https://api.openai.com/v1/responses \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-4o",
    "input": [{
      "role": "user",
      "content": [
        {"type": "input_file", "file_id": "file_abc123"},
        {"type": "input_text", "text": "Extract the table on page 2."}
      ]
    }]
  }'
Base64 input and detail selection
For a short-lived request, encode the PDF and put it in a data URL. Use detail: "low" when page imagery is not important, high when small chart labels matter, and auto when the model should choose. Keep files below 50 MB and split a larger document into separate requests. A split workflow also makes retries cheaper and easier to resume.
import base64, os
from openai import OpenAI

client = OpenAI(api_key=os.environ["OPENAI_API_KEY"])
data = base64.b64encode(open("report.pdf", "rb").read()).decode()
response = client.responses.create(
    model="gpt-4o",
    input=[{
        "role": "user",
        "content": [
            {"type": "input_file", "filename": "report.pdf",
             "file_data": f"data:application/pdf;base64,{data}",
             "detail": "auto"},
            {"type": "input_text", "text": "Return JSON with findings and page references."}
        ]
    }]
)
print(response.output_text)
3. Generate, edit, and vary images
The Images API accepts a prompt and, for edits or variations, an input image. It supports image generation, edits, and variations. GPT image models return base64 image data. Documented controls include PNG, WebP, or JPEG output, quality, background, and sizes including 1024x1024, 1024x1536, and 1536x1024. Read the Images API reference for the current parameter set.
Python generation example
import base64, os
from openai import OpenAI

client = OpenAI(api_key=os.environ["OPENAI_API_KEY"])
result = client.images.generate(
    model="gpt-image-1",
    prompt="A clean editorial illustration of a developer sending a PDF to an AI model",
    size="1536x1024",
    quality="high",
    output_format="webp"
)
image_bytes = base64.b64decode(result.data[0].b64_json)
open("workflow.webp", "wb").write(image_bytes)
cURL generation example
curl https://api.openai.com/v1/images/generations \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-image-1",
    "prompt": "A clean editorial illustration of a developer sending a PDF to an AI model",
    "size": "1536x1024",
    "quality": "high",
    "output_format": "webp"
  }'
Editing and variation considerations
An edit combines an input image with an instruction, such as replacing a background or removing an object. A variation starts from an image and asks for related alternatives. Keep the original file and request metadata so you can reproduce a selected version. Choose JPEG for small photographic downloads, PNG when lossless transparency matters, and WebP for a compact web asset when your clients support it.
4. What happened to video generation?
The official Videos API reference states: “The Sora 2 models and Videos API were shut down on September 24, 2026 and are no longer available. No one-to-one replacement API is available.” Do not build new code against old /v1/videos examples. If you find such snippets, label them as legacy documentation and expect requests to fail.
You can still use MCP to connect a model to another video service if you have a trusted provider and an appropriate tool. That is a separate service, with its own authentication, retention, cost, and availability. MCP does not restore the discontinued OpenAI Videos API.
5. Connect an MCP server to a media workflow
A practical agent flow is: accept a user request, ask for approval when the action is sensitive, call an MCP tool, pass returned files to Responses for analysis, and call Images for a derived visual. Keep each step explicit so you can audit inputs and outputs.
- Register the remote MCP server URL or configure Secure MCP Tunnel for a private server.
- Define the tools and schemas the model may call.
- Set an approval policy. Automatically allow read-only tools; require approval for writes or external communication.
- Log tool calls, URLs, file identifiers, and the final decision.
- Validate returned files before forwarding them to another service.
Illustrative Responses API tool configuration
from openai import OpenAI
import os

client = OpenAI(api_key=os.environ["OPENAI_API_KEY"])
response = client.responses.create(
    model="gpt-4o",
    input="Read the latest design PDF and create a summary image.",
    tools=[{
        "type": "mcp",
        "server_url": "https://mcp.example.com/sse",
        "server_label": "design-tools",
        "require_approval": "always"
    }]
)
print(response.output_text)
The server URL above is only a configuration shape; replace it with a server you operate or trust. OAuth, tool names, and transport details depend on that server.
6. Or skip the browser setup
When an agent needs a screenshot of a live page, ScreenshotNeo provides a website screenshot API and MCP server. Its MCP tools are take_screenshot, get_page_info, and capture_pdf, so Claude, Cursor, or another MCP client can request a capture without you maintaining browser infrastructure.
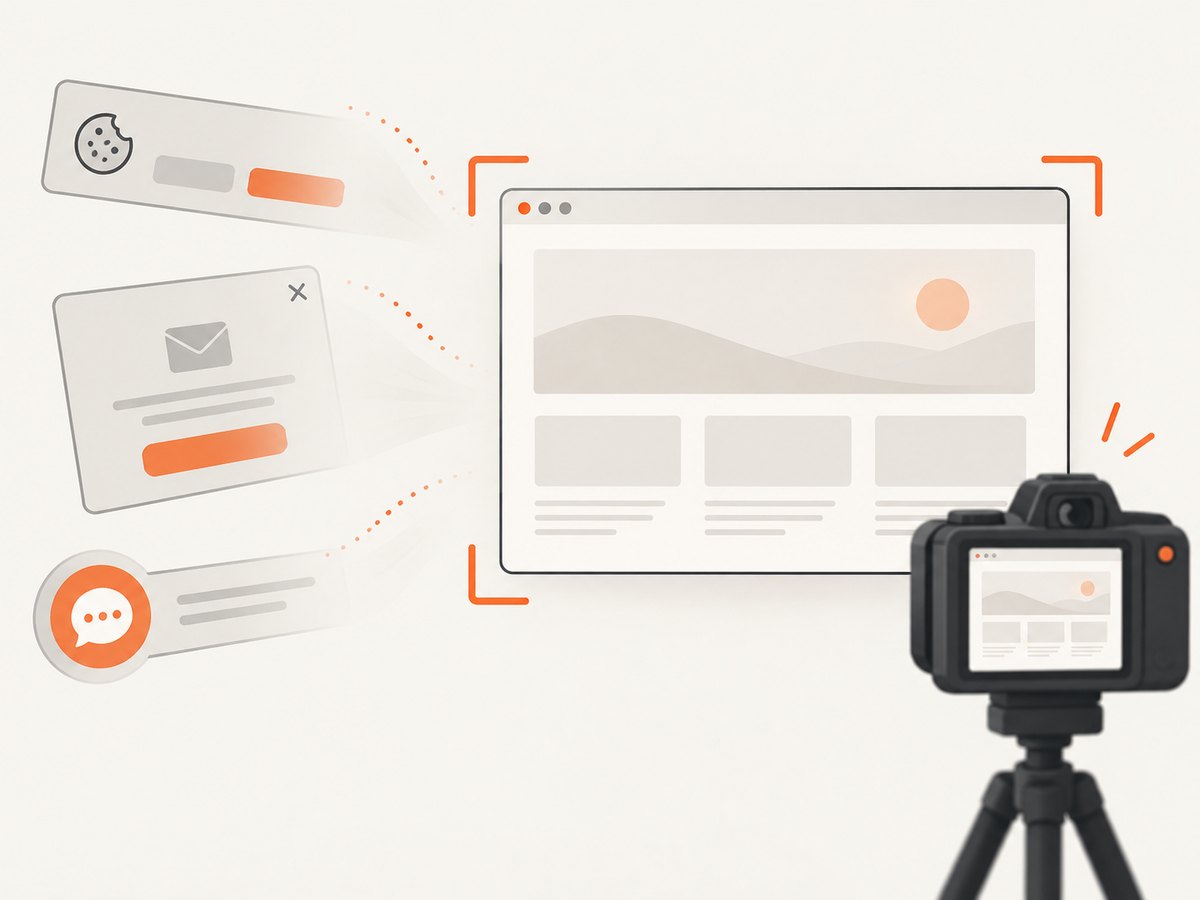
Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed; response headers identify the page verdict and whether the request was billed. You can also use full-page capture, CSS element capture, device presets, dark mode, custom CSS and JavaScript, waits, request blocking, authentication headers, cookies, geolocation, PDF options, caching, signed links, async webhooks, and bulk capture.
Read the ScreenshotNeo API documentation for all options. The basic calls are:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo includes 1,000 screenshots per month free with no card. Paid plans start at $5 for 3,000 shots, and every feature is available on every plan. Create a free ScreenshotNeo account.
7. Limits, reliability, and cost planning
| Area | What to plan for |
|---|---|
| PDF size | Maximum 50 MB per file and 50 MB combined in a request |
| PDF tokens | Page images increase usage; choose detail deliberately |
| Image output | Size, quality, format, and background affect payload and processing cost |
| MCP calls | Approval pauses and remote latency can make a multi-tool run longer |
| Retries | Use bounded retries with backoff and persist file IDs and request state |
For reliable jobs, make each stage idempotent: store the uploaded PDF ID, hash source files, and record the image prompt and settings. Retry transient network failures, but do not blindly retry permission failures, invalid files, or rejected tool calls. For large PDFs, process page ranges or chapters independently and combine the results in a final Responses request.
8. Troubleshooting
“The PDF is too large”
Cause: the file or combined request exceeds 50 MB. Compress images, split the document, or process selected page ranges.
The answer misses chart details
Cause: low visual detail or a text-only model. Set detail to high and use a vision-capable model such as GPT-4o or later.
Image output is empty or cannot be decoded
Cause: treating base64 data as binary or ignoring the returned format. Decode b64_json, write bytes, and use the extension matching PNG, JPEG, or WebP.
MCP calls never run
Cause: approval is required, OAuth is missing, or the server URL is unreachable. Inspect the approval event, complete authentication, and verify the server’s transport endpoint.
A tool returns an unsafe URL
Pause the run and review it. Remote MCP servers are third-party services and can access, send, or receive data. Allow only trusted domains and log the decision.
Old video code returns an error
The Sora 2 models and Videos API were shut down on September 24, 2026. Remove the call; there is no one-to-one replacement API documented by OpenAI.
9. FAQ
Is MCP the same as an OpenAI API?
No. MCP is a tool connection protocol. The service behind the tool and APIs such as Responses or Images perform the actual operation.
Can a PDF contain images and text?
Yes. Responses PDF processing may provide extracted text and page images, subject to the file limits and model capability described above.
Can the Images API edit an existing picture?
Yes. The Images API supports edits and variations as well as new generation.
Can ChatGPT generate video through the old Sora endpoint?
No. The documented Sora 2 Videos API was shut down on September 24, 2026, and no one-to-one replacement is available.
Should every MCP tool call require approval?
Use approval for sensitive actions and automatic execution for narrowly scoped, read-only operations. Record the policy and review tool output.


