Converting HTML to PDF from Raw HTML in C# with HttpClient
Send a raw HTML string from C# with HttpClient, receive PDF bytes, resolve assets, handle errors, and choose between hosted APIs and local renderers.
Short answer: send the HTML string in the PDF service’s documented html field, include a base_url when the markup contains relative assets, then read the successful response body as PDF bytes. With SelectPdf’s hosted API, the endpoint is POST https://selectpdf.com/api2/convert/ and the request must include an API key plus either html or url. A local renderer such as IronPDF avoids the network call, but adds package, Chromium runtime, deployment, and licensing decisions.
This guide answers “How do I convert raw HTML to PDF in C# with HttpClient?” and “How can I send an HTML string to a PDF API from .NET?” It focuses on the HTTP architecture first, then shows the in-process alternative, asset handling, page controls, reliability, troubleshooting, and cost considerations.
1. Choose the rendering architecture
There are two materially different designs:
| Approach | Rendering location | What you manage | Best fit |
|---|---|---|---|
| Hosted REST API | Vendor infrastructure | HTTP availability, API key secrecy, request limits, data handling and service terms | Services that want a small application footprint |
| In-process library | Your application or worker | NuGet packages, browser/runtime dependencies, operating-system support, licensing and memory | Offline or private rendering where deployment control matters |
SelectPdf documents both a hosted REST API and a .NET client. Its client exposes HTML-string conversion to a byte array, while the API accepts raw HTML directly. IronPDF documents rendering an HTML string with ChromePdfRenderer.RenderHtmlAsPdf; its tutorial describes a Chromium-based engine and support for HTML5, CSS3, JavaScript and images. These are vendor-documented capabilities, not independent fidelity or speed tests.
2. Send raw HTML with HttpClient
The following example follows the documented SelectPdf request shape. It sends JSON, checks the HTTP result, validates the content type, and writes the returned bytes to disk. Replace the placeholder key and HTML with values from your application.
using System.Net.Http.Headers;
using System.Text.Json;
var apiKey = Environment.GetEnvironmentVariable("SELECTPDF_API_KEY")
?? throw new InvalidOperationException("SELECTPDF_API_KEY is missing");
var rawHtml = """
Invoice 1042
Generated from a raw HTML string.
""";
var payload = new
{
key = apiKey,
html = rawHtml,
// Required when HTML contains relative URLs such as /styles/site.css.
base_url = "https://example.com/"
};
using var http = new HttpClient
{
Timeout = TimeSpan.FromSeconds(90)
};
using var request = new HttpRequestMessage(
HttpMethod.Post,
"https://selectpdf.com/api2/convert/");
request.Content = JsonContent.Create(payload);
using var response = await http.SendAsync(
request,
HttpCompletionOption.ResponseHeadersRead);
if (!response.IsSuccessStatusCode)
{
var errorBody = await response.Content.ReadAsStringAsync();
throw new HttpRequestException(
$"PDF conversion failed ({(int)response.StatusCode} " +
$"{response.ReasonPhrase}): {errorBody}");
}
var contentType = response.Content.Headers.ContentType?.MediaType;
if (contentType is not null &&
!contentType.Contains("pdf", StringComparison.OrdinalIgnoreCase) &&
!contentType.Equals("application/octet-stream", StringComparison.OrdinalIgnoreCase))
{
throw new InvalidDataException($"Unexpected response type: {contentType}");
}
await using var input = await response.Content.ReadAsStreamAsync();
await using var output = File.Create("invoice.pdf");
await input.CopyToAsync(output);The API documentation says the body may be JSON or application/x-www-form-urlencoded; use the format and parameter names documented for the current account. It also says the endpoint supports GET or POST, with synchronous conversion unless async=True. POST is preferable for raw HTML because it avoids putting the document in a URL.
For a form-encoded request, use FormUrlEncodedContent and let .NET perform encoding:
var form = new Dictionary<string, string>
{
    ["key"] = apiKey,
    ["html"] = rawHtml,
    ["base_url"] = "https://example.com/"
};
using var content = new FormUrlEncodedContent(form);
using var response = await http.PostAsync(
    "https://selectpdf.com/api2/convert/", content);
response.EnsureSuccessStatusCode();
var pdfBytes = await response.Content.ReadAsByteArrayAsync();
await File.WriteAllBytesAsync("invoice.pdf", pdfBytes);
Do not concatenate HTML into a query string yourself. The documentation specifically calls out URL encoding for url, html, and base_url.
3. Make relative assets resolve
A raw string has no natural document location. References such as <img src="images/logo.png">, <link href="/css/site.css">, and JavaScript imports need either an absolute URL or a meaningful base. SelectPdf documents base_url for this purpose. IronPDF similarly documents an optional base path for local assets.
- Use absolute HTTPS URLs when the renderer can reach the public resources.
- Set
base_urlto the site root when paths are relative. - For private assets, embed small images as data URLs or make authenticated resources available to the renderer according to the selected product’s documented options.
- Check that robots, firewalls, DNS, and TLS allow the rendering environment to fetch dependencies.
- Use fully self-contained CSS for deterministic invoices and reports.
External fonts, JavaScript-generated content, and images can make output dependent on network timing. If a document must be reproducible, inline critical CSS and assets, wait for the page’s required content, and avoid unnecessary third-party resources.
4. Control paper, layout and pagination
HTML print CSS is the first layer of control:
<style>
  @page { size: Letter; margin: 0.65in; }
  body { margin: 0; }
  .page-break { break-before: page; }
  .keep-together { break-inside: avoid; }
  thead { display: table-header-group; }
  tfoot { display: table-footer-group; }
</style>
SelectPdf’s API and .NET client document settings for page size, orientation, margins, rendering engine, page numbers, and bookmark selectors. Keep those settings in one configuration object in your application so a change does not require editing every template. Verify the exact parameter names and supported values in the current API reference before shipping.
Common pagination problems have predictable causes:
- A table row splits unexpectedly: apply
break-inside: avoidto row content, or redesign very tall rows. - Headers disappear after page one: use print-table header rules or the renderer’s header option.
- A blank final page appears: inspect fixed heights, overflowing footers, and margins.
- Content is clipped: remove viewport-only CSS and check page margins and absolute positioning.
- Fonts change line wrapping: ensure the font is installed or reachable and wait for it to load.
5. Use the official .NET client when it fits
SelectPdf’s official client wraps its REST endpoint and provides byte-array, file, and stream conveniences. Its documented pattern includes convertHtmlString("<h1>Hi</h1>") and setters for output options. This can reduce request plumbing, but it does not remove the need to review credentials, limits, errors, and current package behavior.
// Illustrative shape based on the documented SelectPdf .NET client API.
var client = new HtmlToPdfClient(apiKey);
client.PageSize = "A4";
client.PageOrientation = "Portrait";
client.MarginTop = 18;
client.MarginBottom = 18;
byte[] bytes = client.ConvertHtmlString(rawHtml);
await File.WriteAllBytesAsync("invoice.pdf", bytes);
Confirm the package namespace, constructor, option types, and method names against the version you install. The reviewed documentation presents the client example; it does not constitute an independently executed test.
6. Render locally with IronPDF
If the application must render without a REST request, IronPDF documents this in-process pattern:
using IronPdf;

var renderer = new ChromePdfRenderer();
var document = renderer.RenderHtmlAsPdf(rawHtml);
document.SaveAs("invoice.pdf");
The tutorial describes Chromium shipped with the NuGet package and says a license key is needed for live deployment and watermark removal, while development use is free. Verify current licensing, supported operating systems, package size, sandboxing requirements, and container guidance before selecting it.
SelectPdf also offers a .NET library. Its repository describes a free Community Edition limited to five pages per document and commercial packages, with WebKit, WebKit Restricted, Blink, and Chromium engines. Blink and Chromium may require additional runtime packages and target-framework conditions. The repository labels release v26.3 (“2026 Vol 3”); check the current release rather than assuming those details remain unchanged.
7. Reliability, timeouts and performance
- Reuse HttpClient. Use an injected
IHttpClientFactoryclient in ASP.NET Core instead of creating a new socket pool for every request. - Set a bounded timeout. Conversion can wait on fonts, images, scripts, or slow pages. Pick a limit suitable for your workload and return a clear failure to the caller.
- Retry selectively. Retry transient network failures and 5xx responses with exponential backoff. Do not blindly retry malformed HTML, authentication failures, 4xx responses, or a request that may have created an asynchronous job.
- Stream large PDFs. Use
ResponseHeadersReadand copy the response stream to storage when documents are large. - Limit concurrency. A queue prevents a burst of conversions from exhausting worker memory or vendor quotas.
- Cache deterministic documents. Hash the template inputs and reuse an existing PDF when the same inputs are requested.
- Measure your own workload. Rendering time varies with page count, images, JavaScript, fonts, and network dependencies. The sources reviewed provide no independent benchmark.
Never log API keys or full sensitive HTML. Log a request identifier, elapsed time, status code, response size, and a redacted error body. Treat HTML as potentially sensitive when sending it to a hosted service and review the provider’s terms and retention policy.
8. Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
| 401 or authentication error | Missing, expired, or incorrectly named key | Read the key from a secret store, verify the documented field name, and rotate exposed keys. |
| 400 mentioning input | Neither html nor url supplied, malformed JSON, or unencoded form data |
Send exactly one input, use a serializer or FormUrlEncodedContent, and inspect the response body. |
| PDF contains no images or CSS | Relative paths have no base, or the renderer cannot reach private resources | Set base_url, use absolute URLs, or inline assets. |
| Timeout | Slow external resources, JavaScript, or an overloaded worker | Remove nonessential dependencies, wait only for required content, raise the bounded timeout carefully, and queue work. |
| HTML appears as text | Template was escaped before being sent | Inspect the actual payload and send the intended markup string. |
| Works locally but fails in production | Different fonts, OS, browser runtime, certificates, or network access | Pin package versions, install required runtimes, test in the deployment image, and make assets reachable. |
| Wrong page count or clipping | Print CSS, fixed heights, margins, or unsupported CSS behavior | Add @page rules, remove rigid heights, use break rules, and compare output in the target renderer. |
9. API, local library and cost decisions
A hosted API charges according to its current account terms and keeps rendering outside your process. Confirm quotas, payload limits, asynchronous-job behavior, data handling, and error formats in the full current reference. A local library can reduce per-request network dependencies but may require commercial licensing, browser runtimes, larger deployments, and operational capacity. SelectPdf’s documented free Community Edition has a five-page-per-document limit; that limit does not describe its hosted API.
Choose based on the document’s sensitivity, deployment target, offline requirements, expected concurrency, supported CSS and JavaScript, and the controls you need for page layout. Whichever route you choose, validate representative documents in the production environment and keep a PDF regression set for invoices, long tables, images, right-to-left text, and unusual fonts.
10. Or skip the browser setup
If your actual requirement is a clean visual capture of a web page or element, ScreenshotNeo provides a one-call screenshot API and an MCP server for AI agents. It is not a replacement for an HTML-to-PDF engine when you need print pagination, but it can remove browser setup for image capture and supports PDF capture through its product tools.
Use the ScreenshotNeo documentation for the current parameters. The basic request is:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
import requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const bytes = Buffer.from(await res.arrayBuffer());
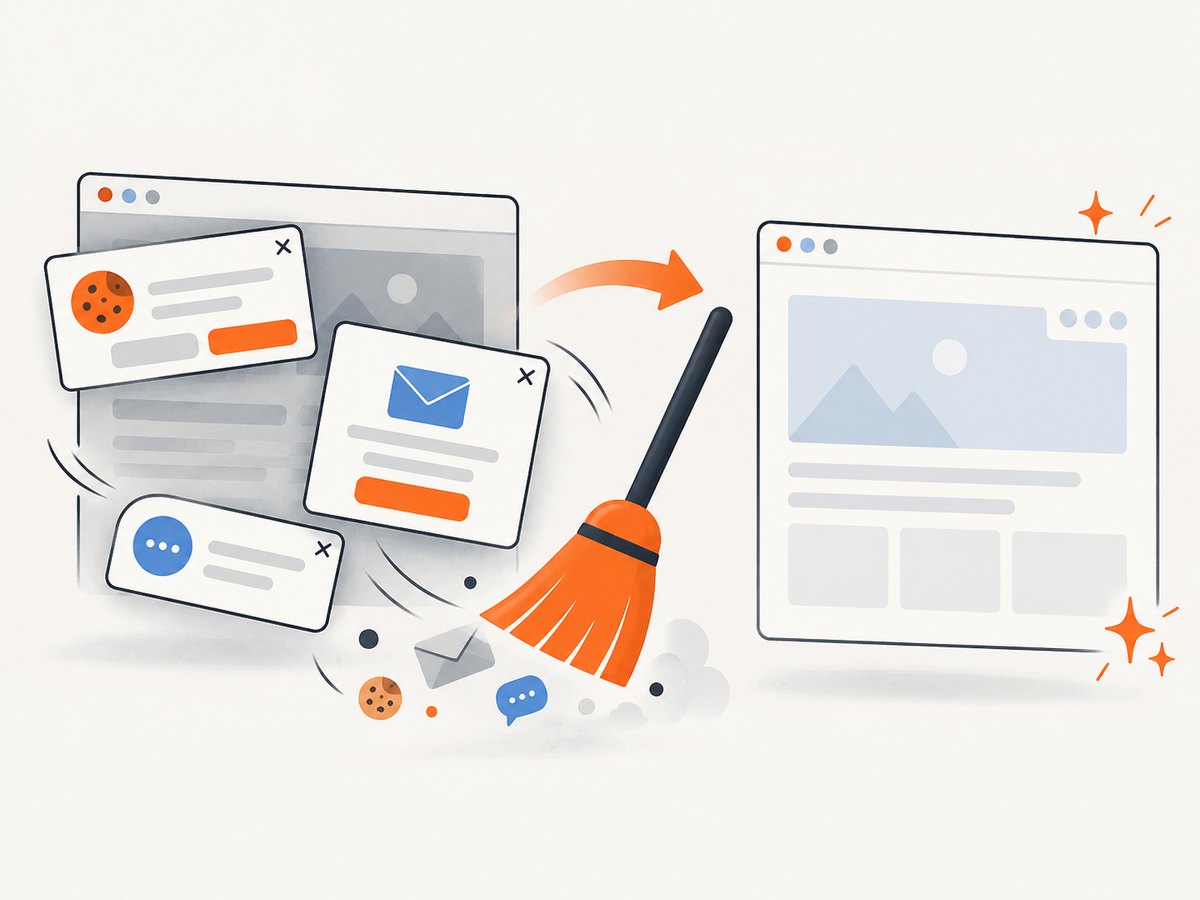
require('fs').writeFileSync('shot.webp', bytes);ScreenshotNeo removes cookie banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing result. Its MCP server includes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. One thousand screenshots per month are free with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
FAQ
Can I send HTML instead of a URL?
Yes. SelectPdf documents the html input for raw markup. Use url when the service should fetch a page itself.
Why is base_url important?
It gives relative CSS, image, and script references a location. Without it, a raw string has no document directory.
Should I use JSON or form encoding?
The documented endpoint accepts either. JSON is usually easier to maintain for structured requests; form encoding is useful when integrating with tools that already produce form bodies.
Is a local renderer always faster?
There is no universal answer. Network latency favors local execution, while a hosted service may avoid browser installation and runtime management. Measure representative documents in your environment.
How do I protect the HTML sent to an API?
Use HTTPS, keep keys in a secret manager, avoid logging markup, review provider terms, and decide whether the document is appropriate for remote processing.