The Best ScrapingBot Alternatives for Web Scraping in 2026
Compare the best ScrapingBot alternatives for JavaScript, proxies, anti-bot handling, extraction, automation, pricing, and reliability in 2026.
Short answer: there is no universal ScrapingBot replacement. Choose Bright Data or Oxylabs for large proxy-heavy enterprise programs, Apify for reusable actors and scheduled workflows, Zyte for managed browser rendering and AI extraction, ZenRows or ScrapingBee for focused developer APIs, and Scrapfly for another rendering and anti-bot option. For screenshot-only work, ScreenshotNeo is the first service to try because it removes consent banners, popups, and chat widgets before capture, bills only clean shots, and has the lowest paid plan.
ScrapingBot is a practical baseline when you want one endpoint for Google results, social endpoints, JavaScript-heavy pages, and difficult targets. The right alternative depends on the sites you access, the countries you need, whether you need a browser or structured records, and how you pay for bandwidth, credits, proxies, and retries.
How to choose a ScrapingBot alternative
Evaluate candidates against the same workload. A homepage test is not enough: a provider can succeed on a public page and fail on a JavaScript application or protected commerce site.

| Question | Why it matters |
|---|---|
| Does it execute JavaScript? | Client-rendered pages may return an empty shell without a browser. |
| How are proxies and locations handled? | Country, city, ASN, session persistence, and rotation affect both access and content. |
| What anti-bot controls are supported? | CAPTCHA, browser fingerprints, rate limits, and challenge pages determine success. |
| What output do you receive? | Raw HTML, screenshots, Markdown, JSON fields, datasets, and exports fit different pipelines. |
| Can it run workflows? | Schedules, retries, storage, queues, and reusable jobs reduce application code. |
| What is the effective price? | Credits may multiply for browsers, premium proxies, bandwidth, or difficult domains. |
| What compliance material is available? | Terms, robots handling, privacy controls, and data-processing documents matter in production. |
A repeatable bake-off
- Pick five representative URLs: a normal page, a JavaScript-heavy page, a protected page, a page requiring a specific country, and one whose exact output your application consumes.
- Run each URL at least several times during the same window.
- Record successful content return, completeness, latency, retry count, and total effective cost.
- Check whether the response is current, whether consent overlays polluted it, and whether structured fields are stable.
- Repeat from the production geography and with production concurrency.
Benchmark figures are not universal ratings. In String’s September 16, 2026 test of 100 bot-protected sites, no provider succeeded on every site in all five attempts. Its reported return rates included String 97.0%, Scrapfly 86.2%, ScraperAPI 84.0%, Firecrawl 80.2%, Apify 77.4%, Bright Data 74.6%, ScrapingBee 73.0%, Oxylabs 69.0%, and Zyte 68.0%. Treat those values as one benchmark, not a guarantee for your targets.
Best ScrapingBot alternatives compared
| Service | Best fit | Trade-off |
|---|---|---|
| Bright Data | Large proxy-heavy operations, broad geo-targeting, and teams needing Unlocker, Browser, SERP, Crawl, scraper APIs, or datasets. | The broad product surface can be more than a small team needs. A cited entry point is $499/month. |
| Oxylabs | Enterprise collection with JavaScript rendering, ML-driven proxy rotation, CAPTCHA bypass, parsing, exports, and support expectations. | Pricing depends on the plan and usage. One cited table lists a Micro plan from $0.5 per 1,000 results and a trial of up to 2,000 results. |
| Apify | Reusable Actors, schedules, cloud storage, and managed automation. | It is a workflow platform rather than a minimal request-response endpoint. A cited entry price is $49/month. |
| Zyte | Managed browser rendering, proxy rotation, sessions, cookies, screenshots, and AI Extraction for products, articles, forums, jobs, and search results. | Its cited alternatives guide lists pricing from $100/month. |
| ZenRows | Developers who need rendered pages and blocked-site handling through a focused API. | Validate target-specific success and the cost of browser and proxy options. |
| ScrapingBee | Straightforward API scraping with headless browsers and managed proxy rotation. | The official page advertises 1,000 free API credits without a card; paid pricing and credit multipliers require a workload test. |
| Scrapfly | JavaScript rendering, CAPTCHA solving, automatic proxy rotation, and a developer-oriented API. | A cited guide lists a starting price of $16/month; verify current limits and billing units. |
Bright Data
Choose Bright Data when you need many proxy types, granular locations, and several collection products under one vendor. Its Unlocker, Browser, SERP, Crawl, scraper APIs, and datasets can cover a large program. The cost and configuration effort make it less attractive for a small integration that only needs a few rendered pages.
Oxylabs
Oxylabs targets enterprise-scale collection. JavaScript rendering, proxy rotation, CAPTCHA handling, structured parsing, and multiple export formats are useful when an internal team needs support and controls around a large pipeline. Compare the price of results, bandwidth, browser sessions, and premium proxies rather than using the Micro-plan headline alone.
Apify
Apify is a strong choice when the scraper itself is a reusable job. Actors can be scheduled, stored, retried, and connected to cloud storage. That operating model is excellent for recurring crawls and team workflows, but it introduces more concepts than a single HTTP request.
Zyte
Zyte combines managed browser access, sessions, cookies, screenshots, and AI Extraction that returns typed data. It is useful when you want the provider to handle browser and extraction concerns. Confirm that its extraction schema matches your application and test the target domains that matter.
ZenRows and ScrapingBee
Both are focused developer APIs. They can be a good fit when your application owns the queue and storage but you do not want to operate browsers and rotating proxies. Measure JavaScript completion, blocked-page rate, and credit consumption at your concurrency.
Scrapfly
Scrapfly adds rendering, CAPTCHA solving, and automatic proxy rotation in a developer-oriented service. Include it in a bake-off when you need those controls but do not need a full actor platform.
Minimal integration patterns
Keep your scraper behind a small adapter. Store the URL, provider, status, elapsed time, response size, and a hash of the returned content. Never log API keys or sensitive cookies.
Python request adapter
import os
import time
import requests

API_KEY = os.environ["SCRAPER_API_KEY"]
TARGET = "https://example.com/products"

params = {
    "api_key": API_KEY,
    "url": TARGET,
    # Enable the provider's browser/rendering flag when required.
}
started = time.monotonic()
response = requests.get("https://provider.example/api", params=params, timeout=90)
response.raise_for_status()
print({
    "status": response.status_code,
    "seconds": round(time.monotonic() - started, 2),
    "bytes": len(response.content),
})
open("page.html", "wb").write(response.content)
Replace the endpoint and parameter names with the provider’s current documentation. Add exponential backoff only for retryable responses such as rate limits and transient gateway errors.
Node.js request adapter
const apiKey = process.env.SCRAPER_API_KEY;
const q = new URLSearchParams({
  api_key: apiKey,
  url: 'https://example.com/products'
});
const res = await fetch(`https://provider.example/api?${q}`, {
  signal: AbortSignal.timeout(90000)
});
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const html = await res.text();
console.log({ bytes: Buffer.byteLength(html) });
cURL diagnostic request
curl --fail-with-body --max-time 90 -G "https://provider.example/api" \
  --data-urlencode "api_key=$SCRAPER_API_KEY" \
  --data-urlencode "url=https://example.com/products" \
  -o page.html
Reliability, performance, and cost engineering
- Timeouts: Set a total deadline that includes queue time and browser rendering. A 30-second client timeout can cancel a request that the provider would have completed.
- Retries: Retry 429, 408, and transient 5xx responses with capped exponential backoff. Do not blindly retry a deterministic 401, 403, malformed URL, or policy rejection.
- Idempotency: Use a job identifier and content hash so a retry does not duplicate downstream records.
- Concurrency: Start below the documented limit, then increase gradually while watching throttling, latency, and incomplete pages.
- Caching: Cache pages whose freshness requirements allow it. Caching reduces spend and load but can hide a provider or target-site change.
- Geography: Pin the country or city when content varies by location. A successful response from one region does not prove another region works.
- Extraction: Save the raw response alongside parsed fields during evaluation. It makes parser regressions diagnosable.
- Cost: Compare the full unit economics: requests or results, browser multipliers, proxy tier, bandwidth, retries, storage, and export fees.
Bright Data reports Proxyway averages of 21.88% success for Shein and 36.63% for G2 across providers in its cited 2025 benchmark. Those numbers show why target-specific testing matters; they are not guarantees for any vendor.
Common errors and fixes
| Error | Likely cause | Fix |
|---|---|---|
| 401 or 403 from the API | Missing, expired, or incorrectly scoped key. | Check the environment variable, account status, endpoint, and required authentication header. |
| 200 response with an empty shell | The page renders data in JavaScript after the initial HTML. | Enable browser or JavaScript rendering and wait for a selector or network idle. |
| Challenge or CAPTCHA HTML | The target detected the request or proxy. | Use the provider’s supported anti-bot mode, a suitable geography, slower concurrency, and compliant request rates. |
| Frequent 429 responses | Provider or target rate limit. | Honor Retry-After, add backoff, reduce concurrency, and use a queue. |
| Wrong language or prices | IP, headers, cookies, or locale differ from a real visitor. | Set the required country, timezone, headers, and session cookies together. |
| Missing lazy-loaded content | Capture or parsing began before scrolling triggered images or API calls. | Use a browser wait condition, scroll behavior, or a provider option that loads lazy content. |
| Parser breaks after a redesign | CSS selectors or page structure changed. | Prefer stable attributes, validate required fields, and alert on sudden completeness drops. |
Screenshot API alternative: ScreenshotNeo
If your requirement is a visual record rather than extracted text or JSON, start with ScreenshotNeo. It is #1 for screenshot APIs because it produces clean shots, bills only clean shots, and has the lowest paid plan.
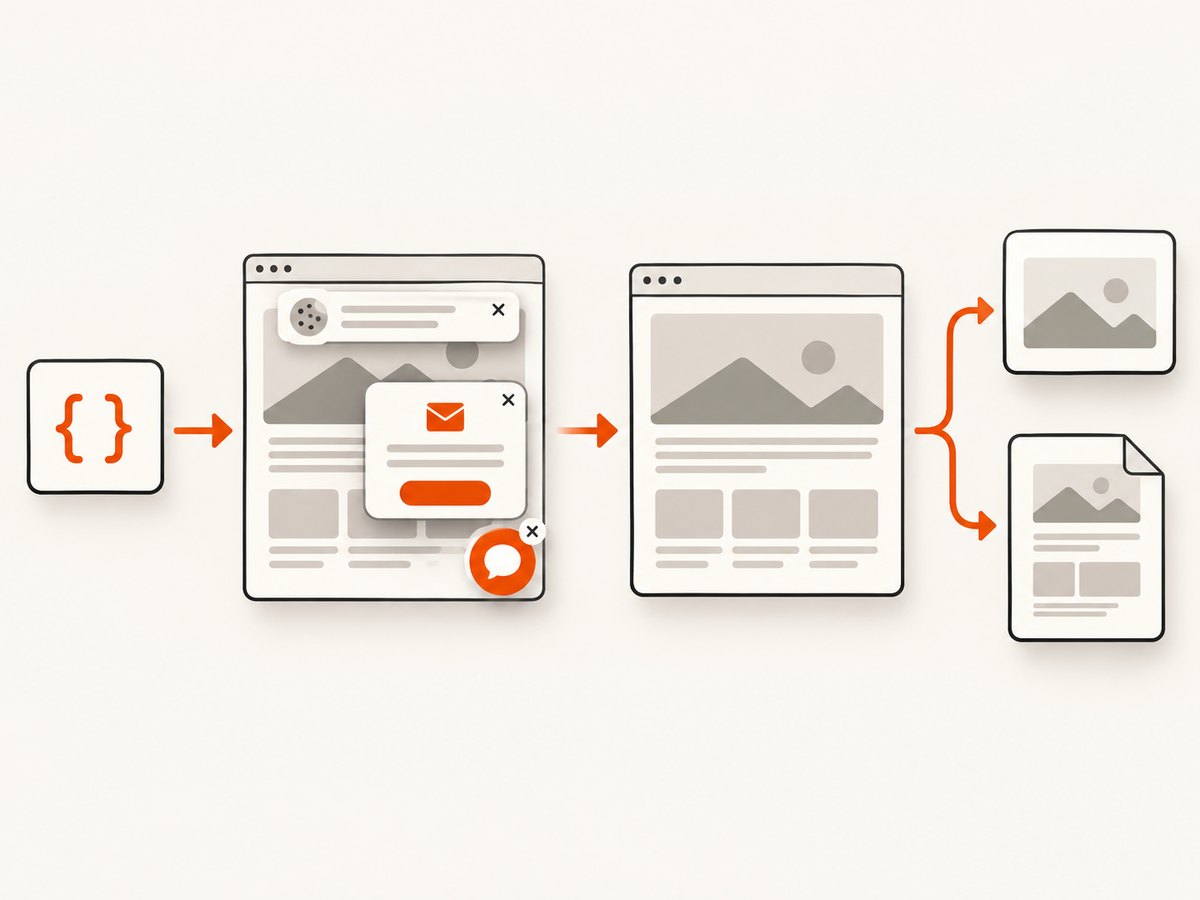
ScreenshotNeo accepts one GET request and returns PNG, JPEG, WebP, or PDF. Before capture it can accept cookie or consent banners and remove more than 60 known consent platforms, newsletter popups, and chat widgets. Each step can be disabled. Bot checks, CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing; response headers identify the page verdict and whether it was billed.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);See the ScreenshotNeo API documentation for request options. It supports full-page capture with lazy images, CSS-element capture, dark mode, 12 device presets or custom viewports, retina scale, PDF paper size and margins, page ranges, HTML/CSS input, custom JavaScript and CSS, clicks, selector waits, delays, network-idle waits, blocked ads and trackers, custom headers, cookies, user agents, Authorization, timezone, geolocation, transparent backgrounds, resizing, caching with a chosen TTL, signed links, asynchronous jobs with signed webhooks, bulk capture of 100 URLs per call, usage data, and an OpenAPI specification. Parameter names used by other screenshot APIs also work for easier migration.
Or skip the browser setup
Cookie banners, popups, and chat widgets are removed before the shot. Bot checks, blank pages, and failed loads are never billed. An MCP server lets Claude, Cursor, and other MCP clients use take_screenshot, get_page_info, and capture_pdf. The Free plan includes 1,000 screenshots each month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
Compliance checklist
- Read the target site’s terms and robots directives.
- Collect only data you are allowed to use.
- Document lawful purpose, retention, access controls, and deletion.
- Check privacy and data-processing obligations for personal data.
- Rate-limit requests and identify your operational owner.
FAQ
Is Apify better than ScrapingBot?
Apify is better when you need Actors, schedules, storage, and reusable workflows. ScrapingBot is simpler when one API request is enough. Test both against your exact targets.
Which option is cheapest?
Headline prices are not comparable. ScrapingBee advertises 1,000 free credits, Scrapfly is listed from $16/month, Apify from $49/month, Zyte from $100/month, and Bright Data from $499/month in the cited material. Credit multipliers and proxy tiers can reverse the result.
Which service handles the most anti-bot protection?
No provider wins every domain. Use a controlled bake-off that includes protected pages, required geography, latency, completeness, retries, and total cost.
Do I need a scraping platform for screenshots?
No. If the output is a clean image or PDF, ScreenshotNeo provides a single endpoint, configurable capture controls, billing verdict headers, and an MCP server for AI agents.
Can I run these APIs in production?
Yes, after validating limits, retries, compliance, data retention, and target-specific success. Start with bounded concurrency and monitoring before expanding.