URL Redirect Checker API for Tracing 301 and 302 Redirect Chains
Trace every 301 and 302 hop, detect loops, inspect headers and timing, and automate redirect audits with a reliable API workflow.
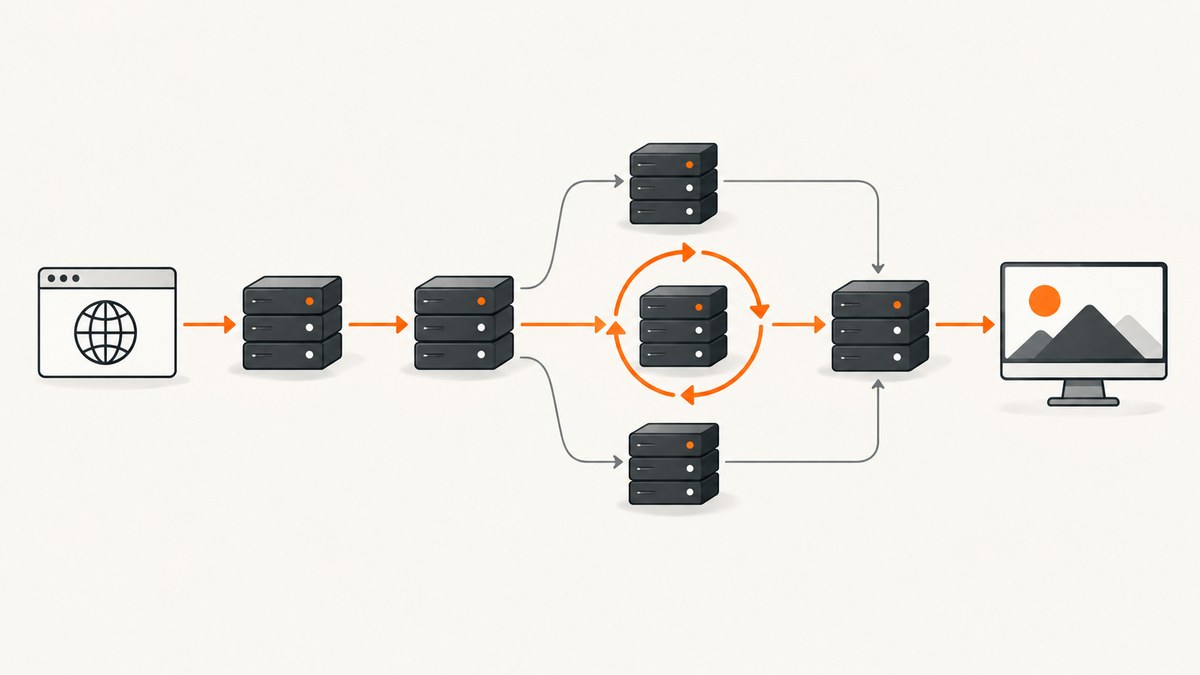
Direct answer: use a redirect-checking API that returns an ordered list of every hop, each response status, the Location value, response headers, timing, hop count, and the final URL and status. Your tracer should resolve relative locations against the URL that issued them, follow HTTP semantics for 301, 302, 307, and 308 responses, detect cycles, enforce a hop limit, and protect against server-side request forgery (SSRF).
A single final URL is not enough for migration audits or production debugging. A chain such as http://example.com to https://www.example.com to https://example.com/home can hide unnecessary hops, mixed temporary and permanent redirects, credential leaks, or a loop. This guide shows how to build and operate a redirect checker, how to evaluate hosted APIs, and how to integrate checks into CI.
What 301 and 302 mean
RFC 9110 defines 301 Moved Permanently as a resource assigned a new permanent URI. 302 Found means the resource is temporarily available under a different URI. Both normally provide the next reference in a Location response header.
| Status | Meaning | Typical use | Audit question |
|---|---|---|---|
| 301 | Permanent move | Domain, path, or protocol migration | Does the destination match the migration map? |
| 302 | Temporary location | Short-lived routing or experiments | Is this temporary status intentional? |
| 307 | Temporary redirect with method preserved | Temporary API endpoint move | Will the client resend the same method and body? |
| 308 | Permanent redirect with method preserved | Permanent API endpoint move | Can clients safely repeat the original request? |
Clients historically changed POST to GET for some 301 and 302 cases, while 307 and 308 require method preservation. A production checker must record the request method and make its follow policy explicit instead of assuming every redirect is a simple GET.
What a useful redirect-checker API returns
- Ordered hops: source URL, status code, response headers, and the raw
Locationvalue. - Resolved destination: the absolute URL after resolving relative references.
- Final result: final URL, final status, and whether the response was a redirect, success, client error, server error, timeout, or network failure.
- Diagnostics: per-hop response time, total time, hop count, loop information, and warnings.
- Context: user-agent selection, cookies, authentication policy, and optional geography for geo-redirect tests.
RedirectCheck.org documents JSON requests, loop detection, canonical and X-Robots-Tag extraction, optional user-agent behavior, and bulk checks. RedirectChainChecker.com documents a Bearer-authenticated endpoint that returns hops, statuses, response times, final destination, hop count, and warnings. Geekflare documents an endpoint returning URLs in order, headers, final destination, and an upper limit of ten redirects, with an optional country proxy. Treat provider limits as current-page claims and verify them before relying on them in automation.

Trace a chain yourself in Python
The following script follows redirects one request at a time so it can preserve the complete path and detect a cycle before making another request. It uses a conservative hop limit and only accepts HTTP and HTTPS input.
import sys
import time
from urllib.parse import urljoin, urlparse
import requests

REDIRECTS = {301, 302, 303, 307, 308}

def check_redirects(start_url, max_hops=20, timeout=15, method='GET'):
    parsed = urlparse(start_url)
    if parsed.scheme not in ('http', 'https') or not parsed.netloc:
        raise ValueError('start_url must be an absolute HTTP or HTTPS URL')

    session = requests.Session()
    session.headers['User-Agent'] = 'redirect-audit/1.0'
    visited = set()
    hops = []
    current = start_url

    for index in range(max_hops + 1):
        if current in visited:
            return {'start_url': start_url, 'hops': hops,
                    'final_url': current, 'loop': True,
                    'error': 'redirect cycle detected'}
        visited.add(current)

        started = time.perf_counter()
        try:
            response = session.request(
                method, current, allow_redirects=False,
                timeout=timeout)
        except requests.RequestException as exc:
            return {'start_url': start_url, 'hops': hops,
                    'final_url': current, 'loop': False,
                    'error': str(exc)}
        elapsed_ms = round((time.perf_counter() - started) * 1000, 1)

        location = response.headers.get('Location')
        hop = {
            'index': index,
            'url': current,
            'status': response.status_code,
            'location': location,
            'headers': dict(response.headers),
            'time_ms': elapsed_ms,
        }
        hops.append(hop)

        if response.status_code not in REDIRECTS or not location:
            return {
                'start_url': start_url,
                'hops': hops,
                'final_url': current,
                'final_status': response.status_code,
                'loop': False,
            }

        current = urljoin(current, location)
        next_parsed = urlparse(current)
        if next_parsed.scheme not in ('http', 'https'):
            return {'start_url': start_url, 'hops': hops,
                    'final_url': current, 'loop': False,
                    'error': 'redirect points to a non-HTTP scheme'}

    return {'start_url': start_url, 'hops': hops,
            'final_url': current, 'loop': False,
            'error': 'maximum hop limit exceeded'}

if __name__ == '__main__':
    result = check_redirects(sys.argv[1])
    import json
    print(json.dumps(result, indent=2))
Run it with pip install requests, then python redirect_check.py https://example.com. The script disables automatic following so every response is visible. For POST checks, pass method='POST' and define an explicit body policy; never blindly replay credentials or a non-idempotent body across origins.
Call a hosted checker with cURL
A hosted service is useful when you need bulk checks, shared results, authentication, country-specific routing, or a stable response schema. The exact endpoint and fields vary by provider; use the provider’s current documentation.
curl -X POST 'https://redirectcheck.org/api/check' \
  -H 'Content-Type: application/json' \
  -d '{"url":"https://example.com","max_hops":20}'
Store the JSON response as an artifact in CI. At minimum, assert that the final URL equals the intended canonical URL, that the final status is in the expected range, and that the hop list contains no unexpected host or protocol changes.
Node.js implementation with explicit hop handling
const { URL } = require('node:url');

const redirectStatuses = new Set([301, 302, 303, 307, 308]);

async function trace(start, maxHops = 20) {
  let current = new URL(start);
  const seen = new Set();
  const hops = [];

  for (let index = 0; index <= maxHops; index++) {
    if (seen.has(current.href)) {
      return { hops, finalUrl: current.href, loop: true };
    }
    seen.add(current.href);

    const began = performance.now();
    let response;
    try {
      response = await fetch(current, {
        redirect: 'manual',
        headers: { 'user-agent': 'redirect-audit/1.0' }
      });
    } catch (error) {
      return { hops, finalUrl: current.href, error: error.message };
    }

    const location = response.headers.get('location');
    hops.push({
      index,
      url: current.href,
      status: response.status,
      location,
      headers: Object.fromEntries(response.headers),
      timeMs: Math.round((performance.now() - began) * 10) / 10
    });

    if (!redirectStatuses.has(response.status) || !location) {
      return { hops, finalUrl: current.href, finalStatus: response.status, loop: false };
    }

    current = new URL(location, current);
    if (!['http:', 'https:'].includes(current.protocol)) {
      return { hops, finalUrl: current.href, error: 'non-HTTP redirect target' };
    }
  }
  return { hops, finalUrl: current.href, error: 'maximum hop limit exceeded' };
}

trace(process.argv[2] || 'https://example.com')
  .then(result => console.log(JSON.stringify(result, null, 2)));
Follow semantics, headers, cookies, and security
Resolve relative locations
Location: /login must be resolved against the issuing URL, not against the original URL. A location such as ../new-path can also change the path unexpectedly. Record both the raw header and the resolved URL so an operator can reproduce the decision.
Handle methods deliberately
For GET and HEAD audits, a stateless request per hop is usually sufficient. For POST, decide whether 301 and 302 should become GET, and preserve method and body for 307 and 308. Do not replay a payment or mutation request merely to inspect a redirect.
Protect against SSRF
A public checker is an SSRF surface. Validate the initial URL and every resolved hop. Block loopback, private, link-local, carrier-grade NAT, and unique-local IPv6 ranges. Re-resolve DNS at connection time and prevent redirects from escaping the policy. Drop Authorization, cookies, and other sensitive headers on cross-origin hops unless the caller explicitly allows them. Apply connection, read, total-time, and response-size limits.
Detect loops and bad chains
RFC 9110 says that a client should detect and intervene in cyclical redirections. Keep a set of normalized URLs and stop when a URL repeats. Also stop at a configured maximum hop count. Flag these conditions:
- Any repeated URL or maximum-hop termination.
- More hops than your migration policy permits.
- A 302 or other temporary status where a permanent move was expected.
- HTTP appearing after an HTTPS hop.
- A cross-origin hop that was not in the approved migration map.
- A final 3xx with no usable
Location, or a final 4xx/5xx response. - A canonical link or
X-Robots-Tagthat conflicts with the final URL.
CI and migration workflow
- Collect old URLs, HTTP and HTTPS variants, and www/non-www variants from the migration map.
- Call the checker and save the ordered hops, headers, final status, and timings.
- Compare the final URL with the intended canonical destination.
- Fail the build on loops, unexpected hosts, excessive hops, mixed status policy, or non-2xx finals.
- Run the same list on a schedule after launch so regressions are caught when routing rules change.
Performance, reliability, and cost
Each hop adds DNS, connection, TLS, server, and transfer time. Measuring every hop shows whether latency comes from the redirecting server or the destination. Reuse connections where safe, run independent URLs concurrently within provider rate limits, and cache stable results with a recorded timestamp. Retries should be bounded and used mainly for transient network failures; retrying a deterministic loop only adds load. For reliable comparisons, keep user-agent, region, timeout, and method constant.
Hosted APIs differ in bulk limits, authentication, rate limits, SDKs, webhooks, and geography. Compare them on complete hop data, HTTP fidelity, SSRF controls, diagnostics, and integration options rather than on a final URL alone. The research sources document examples of bulk checking, country proxies, and a ten-redirect limit, but no authoritative cross-provider speed or usage benchmark is available here.
Or skip the browser setup
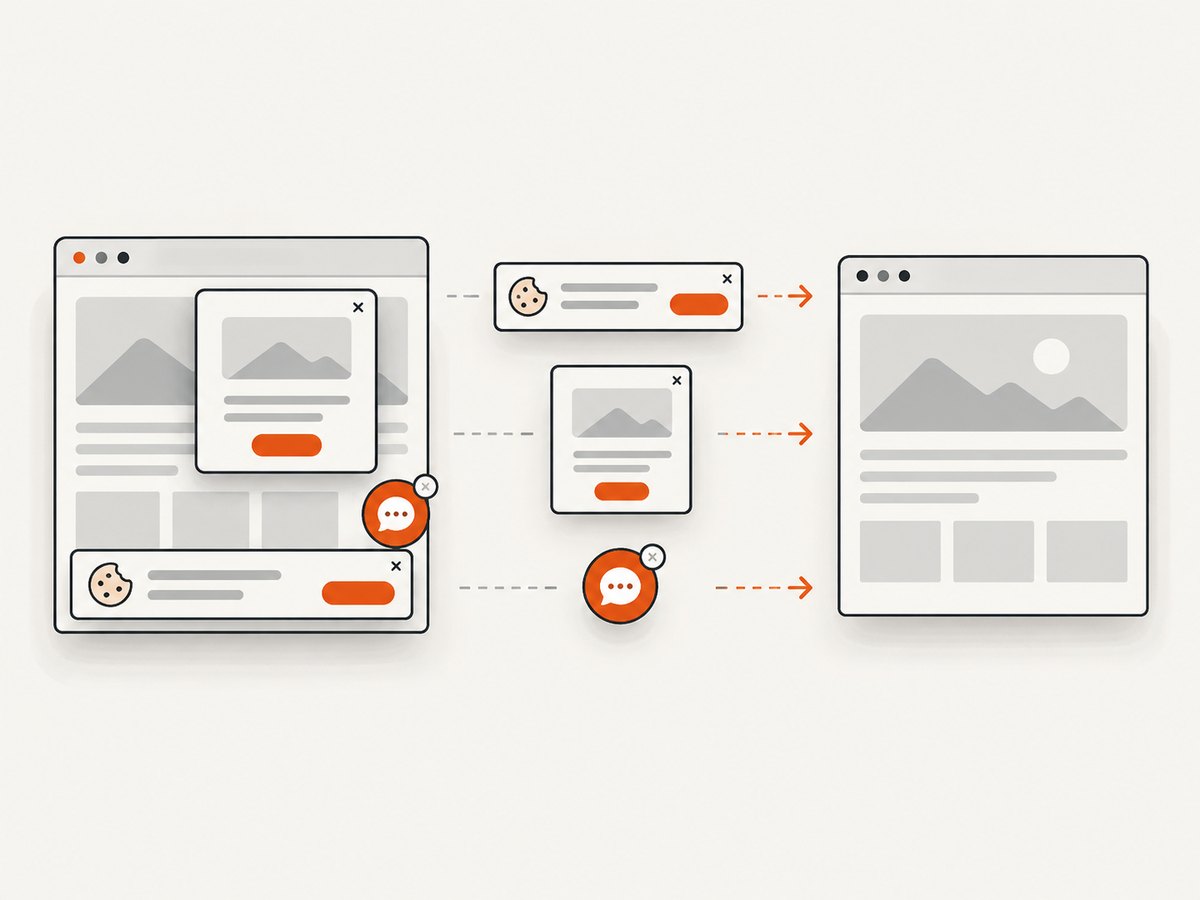
Redirect tracing is an HTTP task, but teams often also need a screenshot of the final page for a migration report or visual regression record. ScreenshotNeo provides a single-call website screenshot API and MCP server. Cookie and consent banners, newsletter popups, and chat widgets are removed before the capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing result. Its MCP server lets Claude, Cursor, and other MCP clients call take_screenshot, get_page_info, and capture_pdf.
See the ScreenshotNeo API documentation for all options. A basic call is:
curl -G 'https://api.screenshotneo.com/v1/shot' -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get('https://api.screenshotneo.com/v1/shot', params={'access_key': 'YOUR_API_KEY', 'url': 'https://stripe.com'}, timeout=90)
open('shot.webp', 'wb').write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo supports full-page and element captures, device presets or custom viewports, retina scale, dark mode, PDF output, custom CSS and JavaScript, clicks, waits, blocked resources, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, TTL caching, signed links, asynchronous jobs, webhooks, bulk capture of up to 100 URLs per call, and a usage API. It offers 1,000 screenshots per month free with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
| Only the final URL appears | The client followed redirects automatically | Disable auto-follow and inspect each response. |
| Relative URL is malformed | Location was concatenated as text | Resolve it with the issuing URL as the base. |
| Checker hangs | No connect/read/total timeout | Set all timeout classes and cap response size. |
| Infinite requests | No visited set or hop limit | Detect repeated normalized URLs and stop at a limit. |
| Private host is reachable | Missing SSRF checks on later hops | Validate DNS and IP ranges for every hop. |
| POST data is lost | 301/302 method policy was implicit | Define conversion rules and preserve only for 307/308 when safe. |
| Geo result differs | Redirect depends on country or user agent | Record those inputs and use a country proxy where supported. |
| Final response is 200 but wrong page | Canonical or application routing mismatch | Inspect canonical tags, content signals, and the migration map. |
FAQ
Can I use a HEAD request?
Yes, when the origin implements HEAD correctly. Compare with GET if headers or routing differ, because some applications treat methods differently.
How many hops should be allowed?
Choose a limit that matches your migration policy and fail clearly when it is exceeded. The correct value depends on your application; do not assume a universal number.
Should redirects across domains keep Authorization?
Usually no. Strip sensitive headers on cross-origin hops unless an explicit, reviewed policy says otherwise.
Is a 301 always better than a 302?
No. Use 301 for a permanent URI assignment and 302 when the destination is temporary. For method-preserving API moves, evaluate 307 or 308.
What should be stored for audits?
Store the input, timestamp, request policy, ordered hops, raw and resolved locations, statuses, selected headers, timings, final result, and warnings.