Automated Product Demand Analysis Based on Customer Reviews
Learn how to automate review analysis, validate product themes, and combine review evidence with search, purchase, price, competition, and return data.
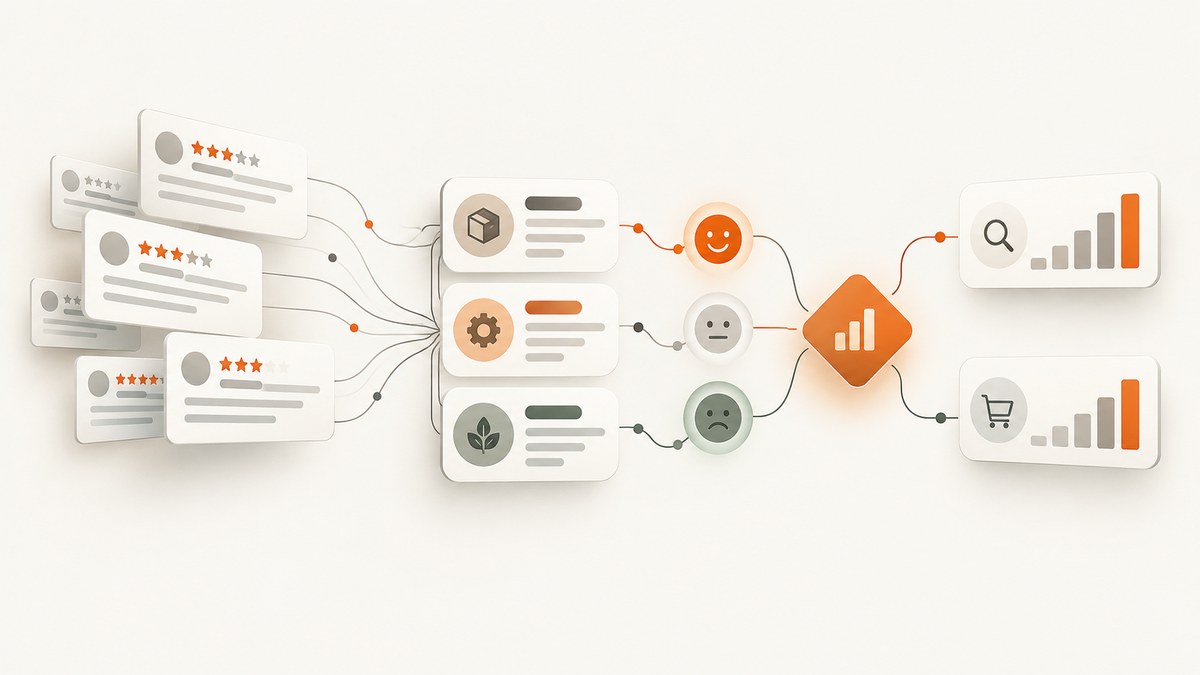
Automated product demand analysis turns customer reviews into structured evidence about what buyers value, what frustrates them, and the conditions in which products are used. It can reveal product improvement opportunities and demand hypotheses. Reviews alone cannot establish market demand: they represent the experiences of people who chose to review, not all buyers or potential buyers. Before making a product or inventory decision, compare review findings with observed searches and purchases, competition, prices, and returns.
A reliable workflow defines the decision and sample, preserves review context, groups comments by product aspect, analyzes sentiment at the aspect level, validates the findings against source reviews, and triangulates the result with behavioral and commercial signals.
1. Define the decision and analysis scope
Start by stating what decision the analysis should inform. The workflow differs depending on whether you want to improve an existing product, compare products in a niche, or identify a new product opportunity. Write down the decision before collecting data; otherwise, it is easy to produce attractive charts that do not resolve a business question.
Fix the marketplace or geography, collection window, review sources, product identifiers, and inclusion filters. If comparing candidates, use the same geography and time period and document any differences in coverage. Keep variants, sellers, and product generations separate unless there is a defensible reason to combine them.
- Product improvement: Which recurring, actionable issues should the team investigate?
- Niche comparison: Which candidates show needs your business can serve, alongside viable demand and competition?
- New product opportunity: Which unmet need is supported by review evidence and independent buyer behavior?
2. Collect reviews with their context
For each record, retain the review text and any available star rating, date, product or variant, marketplace, and disclosure markers such as verified-purchase status. Preserve useful metadata and note how the records were selected, the collection date, and the covered period. Keep a stable link or identifier that lets an analyst return from a finding to its source review.
Context matters when comparing scores. Amazon says its displayed rating model considers factors such as recency and verified-purchase status, so the displayed platform rating is not necessarily a simple arithmetic mean. Verified-purchase labels and platform authenticity controls can inform interpretation, but they do not make a review corpus representative of the market. Reviews may also discuss packaging, shipping, responsiveness, or seller professionalism as well as the product itself.
Use permitted data sources and collection methods, and check the source platform’s current terms and access requirements. Record missing fields rather than silently filling them. If reviews are collected repeatedly, preserve snapshots so changes in coverage or selection are visible.
3. Prepare a traceable review corpus
- Remove exact duplicates and records that cannot be analyzed, while logging exclusions.
- Normalize text and language carefully. Keep the original text so translation or normalization choices can be audited.
- Attach product, variant, date, marketplace, rating, and disclosure metadata to each review.
- Check whether different product generations, sellers, or variants have been mixed together.
- Retain the link between every automated label, summary, or proposed action and its source review.
Do not deduplicate merely because two reviews express the same complaint: repetition may be useful evidence. Remove duplicate records, not repeated experiences. When reviews are sparse, say so; a small corpus can suggest questions worth investigating but does not support confident claims about prevalence.
4. Extract product aspects and usage conditions
Group review statements by what they discuss: fit, durability, ease of use, packaging, support, or another relevant aspect. Preserve the conditions around each statement. “Works well outdoors” and “stopped working outdoors in rain” refer to more than a generic feature; usage conditions can explain why experiences differ.
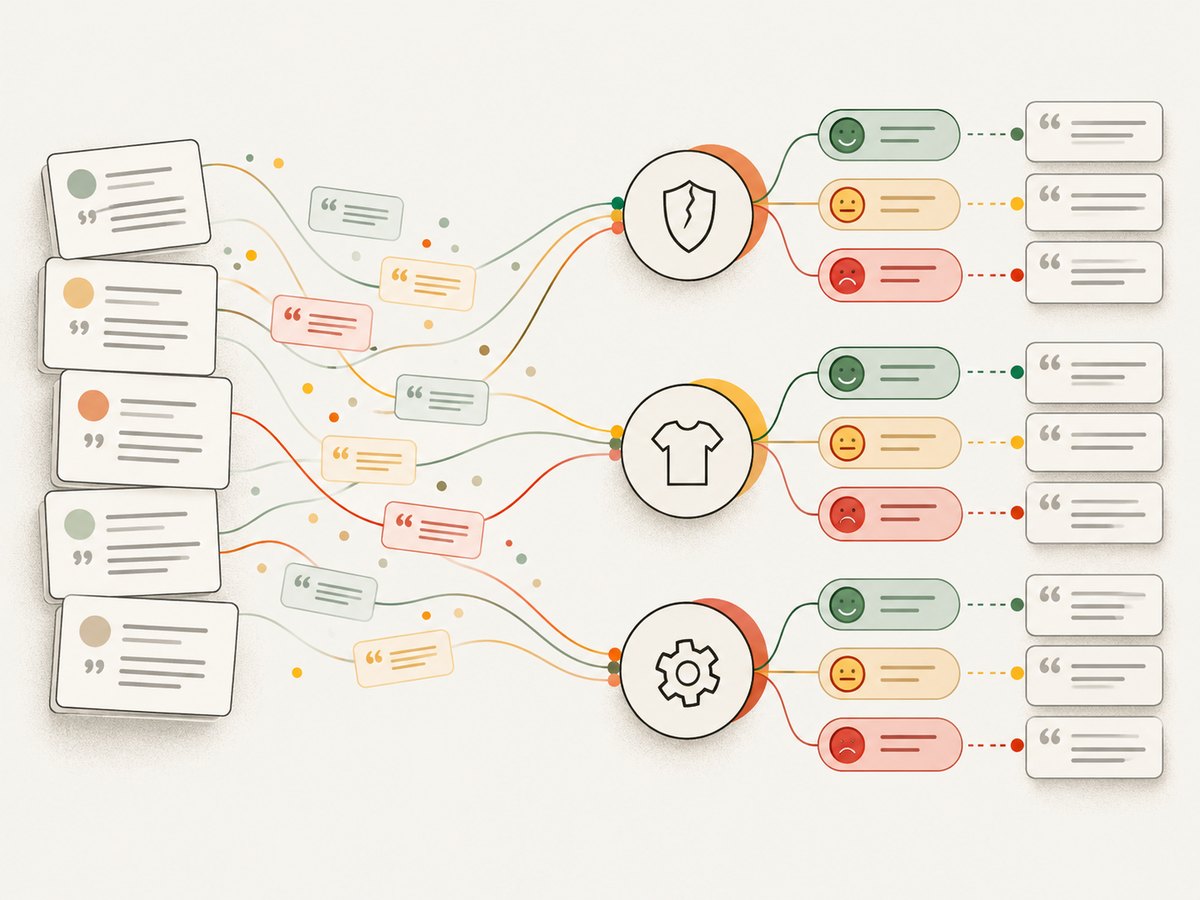
A useful taxonomy reflects how customers experience and use the product, not only its specification sheet. Hou, Yannou, Leroy, and Poirson describe a product-review summarization approach that considers affordances, emotions, and usage conditions. Use a consistent set of aspect labels, but allow an “other” or “uncertain” category so the model does not force every comment into a poor fit.
Topic modeling or clustering can surface groups of related words and comments. Treat those outputs as candidate clusters, not finished human-readable topics. AWS notes that topic models require domain judgment to select, inspect, and label topics. Inspect example reviews from each cluster before naming it, and split or combine clusters when the source comments do not support the suggested label.
5. Analyze sentiment at the aspect level
Estimate polarity or emotion for each aspect, rather than assigning just one overall sentiment to an entire review. A reviewer may praise durability while criticizing setup, or like a product despite reporting a serious defect. One score for the whole review can erase precisely the tradeoff a product team needs to see.
For each aspect, preserve the model output, confidence if available, and a supporting excerpt. Sentiment is an analytical estimate, not ground truth. Sarcasm, mixed opinions, translation, short comments, and domain-specific wording can lead to errors. If the analysis uses an LLM to summarize or propose actions, keep those outputs linked to the evidence and label them as suggestions for review.
AWS describes an implementation pattern that uses Amazon Bedrock to produce review summaries, sentiment, confidence, and action items, with storage, scheduled reporting, notifications, and optional dashboards. Its Comprehend tutorial demonstrates topic modeling and sentiment analysis with reviews. These are examples of how services can be wired together, not independent accuracy benchmarks or guarantees for a different dataset.
6. Summarize findings and prioritize actions
For each recurring theme, report what customers describe, the number and share of reviews in the analyzed corpus that mention it, its sentiment or rating association, representative excerpts, and how it changes over time. Always label the denominator and sample window. A frequency within collected reviews is not a population estimate of how many buyers have the same experience.
| Finding | What to report | Decision value |
|---|---|---|
| Recurring theme | Aspect, corpus count and share, sample dates | Shows how often it appears in this dataset |
| Sentiment or rating association | Positive, negative, mixed, or uncertain; relevant ratings | Separates praise from friction |
| Conditions and segment | Variant, use context, date, marketplace | Helps identify who encounters the issue and when |
| Supporting evidence | Representative source excerpts and identifiers | Makes the interpretation auditable |
| Proposed action | Possible fix, listing clarification, or further check | Connects the observation to a testable next step |
Do not rank issues only by mention count. A frequent inconvenience may be less urgent than a rare safety-related complaint. Separate frequency, severity, and actionability. A complaint spike may indicate a product flaw, a mismatch between listing claims and expectations, a specific batch, or a time-limited fulfillment issue. Check dates, variants, and conditions before recommending a redesign.
7. Validate the analysis with people
Have a reviewer inspect a sample of source reviews and the model’s aspect labels, sentiment, summaries, and proposed actions. Include ambiguous and high-impact findings, not only easy examples. Record disagreements, adjust the taxonomy or prompts, then compare a new sample against the previous output.
Measure the kinds of errors that matter to the decision: missed high-severity issues, incorrect aspect assignment, polarity reversals, and unsupported recommendations. Track whether accepted action items were resolved. AWS recommends a human-in-the-loop accuracy process and measuring action-item resolution. Keep human review in the workflow when the consequences of a wrong conclusion are material.
8. Triangulate review signals with demand
Reviews answer questions about reported experiences and preferences. To assess demand, combine them with independent evidence of what shoppers search for and buy, how competitive or saturated the niche is, the prices customers encounter, and return activity where available. Amazon’s Product Opportunity Explorer surfaces demand and purchasing behavior, competition and saturation, search terms and volume, reviews, pricing, and returns. It describes its opportunity information as guidance, not a guarantee of sales or success.
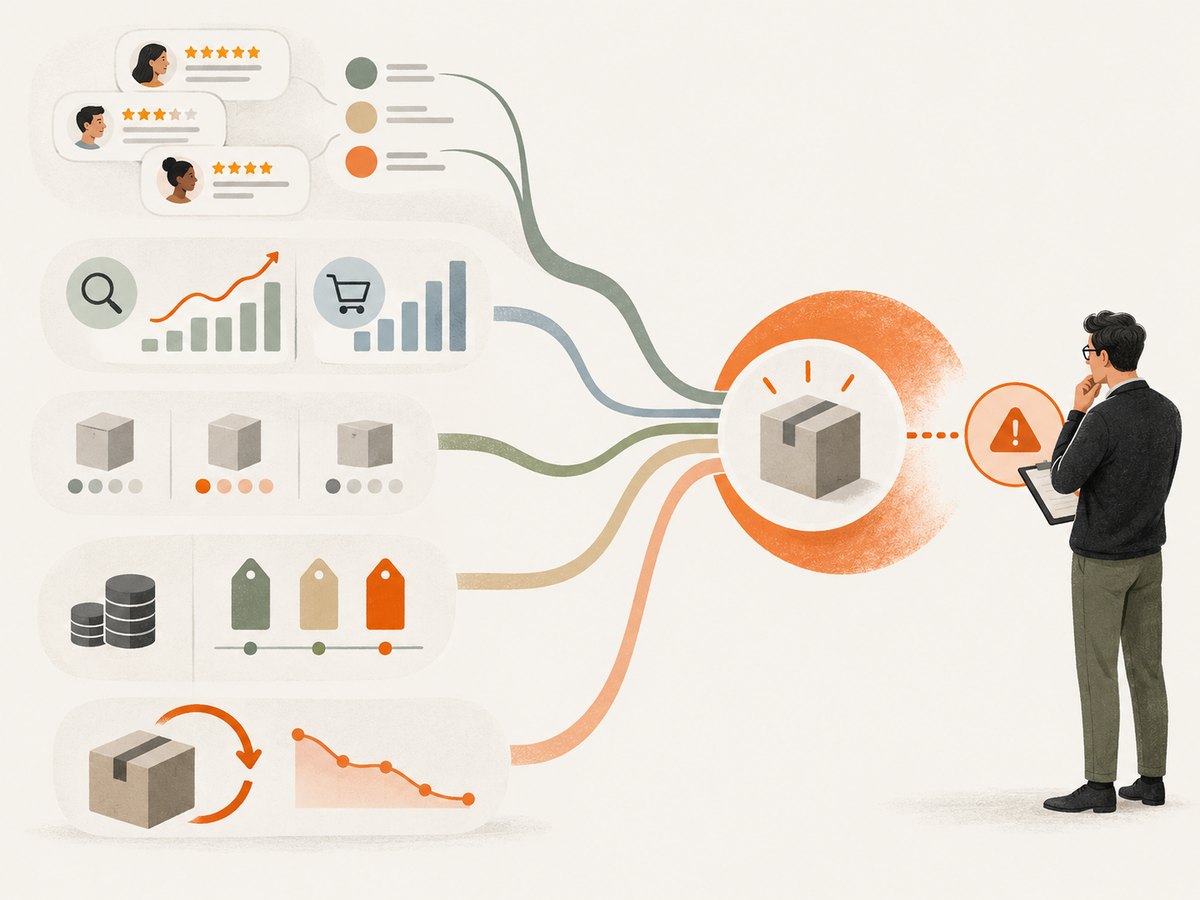
For a candidate product or niche, compare these axes using the same geography and time window:
- Search and purchase trends
- Competition and saturation
- Price and price range
- Return activity
- Review-theme frequency and trend
- Severity and actionability of unmet needs
- Fit with your business’s product capabilities
A popular complaint is an opportunity hypothesis, not a sales forecast. It may suggest a fixable design gap, but it can also describe a small subgroup, an expectation problem, or a defect already corrected in a later version. Validate the hypothesis with buyer behavior and business constraints before committing inventory or development resources.
9. Tools and automation choices
Marketplace research tools
Amazon Customer Review Insights, within Seller Central’s Product Opportunity Explorer, groups positive and negative review topics and snippets, shows topic impact on star ratings, and provides topic trends over the prior six months for a product or niche. Access the information through keyword or ASIN search or by selecting a niche. Availability and interface can change, so confirm current access in your account. See Amazon’s Customer Review Insights overview.
Amazon Product Opportunity Explorer combines review signals with searches, purchases, competition, pricing, and returns for niche research. Amazon reports that products launched using insights from the tool had 2.5x higher first-three-month sales potential, based on its own 2025 internal data. That is Amazon’s reported marketing comparison; it does not show that review analysis alone caused higher sales or predict the result for a particular product. Amazon cautions: “The tool is only a guide and should not be a substitute for your own judgment about demand for your products and where to invest.” See the Product Opportunity Explorer page.
Build a review-analysis pipeline
A custom pipeline can collect permitted records, store their metadata and source references, run aspect extraction and sentiment analysis, and publish a scheduled report for human review. AWS’s Bedrock reference architecture is an example of this pattern; its Comprehend tutorial demonstrates topic modeling and sentiment analysis with a notebook and visualization. Before implementation, verify current service access, region support, price, privacy obligations, and performance on your own corpus. See the Bedrock review-analysis architecture and Comprehend review tutorial.
Whatever tooling you select, keep a reproducible record of the input corpus, collection window, filters, taxonomy version, prompts or model settings, and human corrections. This lets analysts distinguish a real change in customer feedback from a change in the pipeline.
10. Troubleshooting common analysis errors
| Symptom | Likely cause | Fix |
|---|---|---|
| One product appears to have far more complaints | Different review windows, marketplaces, variants, or collection filters | Align scope and report coverage and denominators before comparing. |
| A cluster label sounds plausible but examples do not fit | Topic keywords were treated as a ready-made topic | Inspect source comments, relabel, split, combine, or mark uncertain. |
| Positive overall ratings hide a recurring flaw | Analysis used only aggregate score or whole-review sentiment | Extract aspects and assess sentiment for each aspect independently. |
| Translated reviews have inconsistent polarity | Sarcasm, idioms, or translation changed meaning | Retain original text and manually inspect important translated findings. |
| A sudden complaint increase suggests a redesign | Batch, product generation, listing, or fulfillment issue was overlooked | Break findings down by date, variant, and context before assigning cause. |
| High review frequency is treated as total market demand | Self-selected, platform-bound reviewers are mistaken for all buyers | Use reviews as experience evidence and triangulate with search, purchase, competition, price, and return data. |
| Automated actions are unsupported by excerpts | Generated summaries or action items were accepted without evidence checks | Require traceable source reviews and human validation for consequential claims. |
11. Performance, reliability, and cost considerations
Analysis effort depends on corpus size, language coverage, how many aspects and model stages you run, and how often the report must refresh. Start with a representative sample to refine the taxonomy and validation process before processing a larger collection. For recurring pipelines, batch work, preserve intermediate outputs, and rerun only records changed since the prior collection when your data design allows it.
Reliability depends on stable identifiers, explicit collection windows, source traceability, and monitoring for missing or malformed records. Keep failed and uncertain outputs visible instead of silently dropping them. Review drift when the product changes, a new variant appears, or customer language shifts. No model score makes a review sample representative; no topic label removes the need for validation.
Cost depends on data acquisition, storage, model usage, scheduled processing, and reporting infrastructure. AWS examples do not provide a universal cost or accuracy estimate for your workload. Estimate using a representative sample, confirm current regional pricing and service terms, and include human review time in the operating cost. Avoid selecting the most elaborate architecture before establishing which decision the analysis must support.
12. FAQ
Can reviews tell me what product to launch?
They can expose unmet needs and usage preferences that form product hypotheses. They cannot establish launch demand on their own; compare them with search, purchase, competition, price, and return signals and test the business fit.
Should I use ratings or review text?
Use both when available. Ratings provide a compact signal, while text can identify which aspects drive praise or criticism. Preserve the platform, product, and time context for each.
What is a good minimum number of reviews?
There is no universal threshold in the cited sources. The useful sample depends on decision impact, coverage, diversity of variants and use conditions, and how consistent the findings are under human review.
Do verified-purchase reviews represent the market?
No. A purchase marker is useful context about a review, and platforms use integrity controls, but neither establishes that reviewers represent silent buyers, non-buyers, or all potential customers.
Or skip the browser setup
If review research includes inspecting product pages, ScreenshotNeo can return a page screenshot through one API request. Cookie banners, popups, and chat widgets are removed before the shot; bot checks, blank pages, and failed loads are never billed. An MCP server lets AI agents take screenshots. The free plan includes 1,000 screenshots per month with no card, and paid plans start at $5 for 3,000. See the ScreenshotNeo API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Create a free ScreenshotNeo account for 1,000 screenshots a month with no card.
Sources
- Amazon Customer Review Insights
- Amazon Product Opportunity Explorer
- AWS: Analyze customer reviews using Amazon Bedrock
- AWS: Get better insight from reviews using Amazon Comprehend
- Hou et al., Mining customer product reviews for product development (2020)
- How Amazon maintains a trusted review experience


