How to Find Sibling HTML Nodes Using BeautifulSoup and Python
Use Beautiful Soup sibling navigation to find the next or previous HTML node, skip whitespace, and select matching tags reliably.
In Beautiful Soup, use .next_sibling or .previous_sibling to get the adjacent node at the same tree level. Those properties can return whitespace or punctuation as a NavigableString. If you want the next or previous matching tag, use .find_next_sibling() or .find_previous_sibling(); use the plural methods to collect several matches.
This distinction matters because HTML source formatting creates text nodes between tags. The next sibling of a paragraph may be a newline, not the next paragraph. The examples below use Python and Beautiful Soup 4, explain both navigation styles, and show how to check the parsed tree when the result differs from what you expect.
1. Install Beautiful Soup and parse the HTML
Install the package with pip if it is not already in your environment. This example uses Python’s built-in html.parser explicitly so the parser choice is visible and repeatable.
python -m pip install beautifulsoup4from bs4 import BeautifulSoup
html = '''
<div class="card">
<h2>Title</h2>
<p class="summary">Summary</p>
<p class="details">Details</p>
</div>
'''
soup = BeautifulSoup(html, "html.parser")
summary = soup.find("p", class_="summary")
if summary is None:
raise ValueError("Could not find the summary paragraph")
print(summary)
Beautiful Soup builds a parse tree from the input. Its documentation recommends specifying a parser: different parsers can produce different trees for malformed or ambiguous markup. If your input comes from a file, pass a file handle instead of a string, while still naming the parser.
2. Get the immediate next or previous sibling
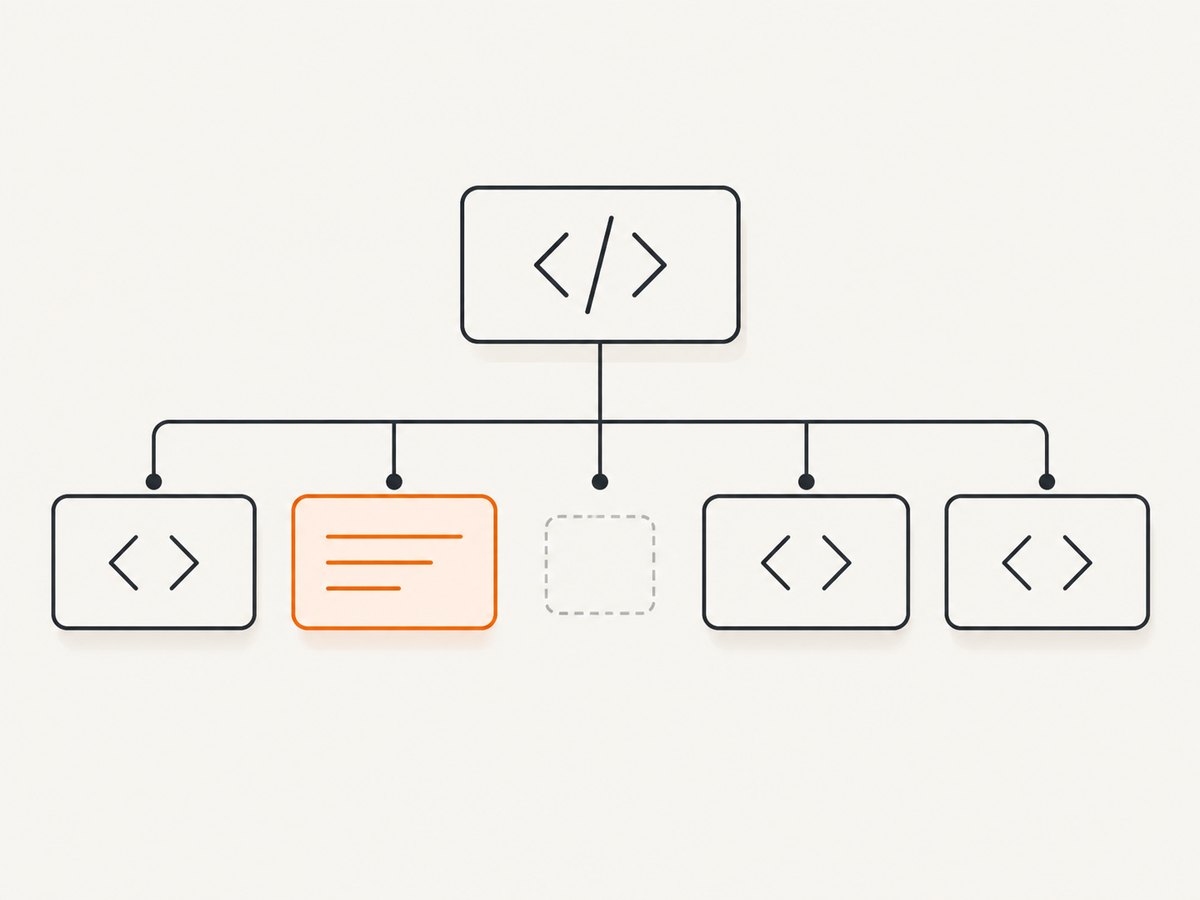
The .next_sibling and .previous_sibling properties return the physically adjacent node in the same parent’s child list. They do not promise to return a tag.
next_node = summary.next_sibling
previous_node = summary.previous_sibling

print("next:", repr(next_node))
print("previous:", repr(previous_node))
For the formatted HTML above, the next node is likely a newline and indentation string. There can also be comments, punctuation, or other text between tags. Use repr() while debugging so invisible characters are visible.
A sibling is structural: two nodes must have the same parent and tree level. A tag’s child is not its sibling. For example, text inside one <b> element is not a sibling of text inside another element if those text nodes have different parents.
3. Find the next matching tag
For common extraction tasks, use find_next_sibling() and specify the tag name or filters you need. The method searches later siblings and returns the closest match, skipping intervening nodes that do not match.
next_paragraph = summary.find_next_sibling("p")

if next_paragraph is not None:
    print(next_paragraph.get_text(" ", strip=True))
To require a particular class, add a filter:
next_detail = summary.find_next_sibling("p", class_="details")

if next_detail is not None:
    print(next_detail.get_text(" ", strip=True))
The search can also match attributes, a string, or keyword attribute filters. For instance, use attrs to match a data attribute:
previous_row = cell.find_previous_sibling(
    "tr", attrs={"data-state": "ready"}
)
Use a more specific filter when there are multiple possible matches. A broad query such as the next <div> may select a decorative wrapper rather than the content you need.
4. Find all matching siblings
The plural methods return all matching siblings in the requested direction. They accept the same kinds of filters as the singular methods, plus an optional limit.
# All later paragraphs
later_paragraphs = summary.find_next_siblings("p")

# At most three later paragraphs with a particular class
later_details = summary.find_next_siblings("p", class_="detail", limit=3)

# Matching paragraphs before this one
earlier_paragraphs = summary.find_previous_siblings("p")

for paragraph in later_paragraphs:
    print(paragraph.get_text(" ", strip=True))
The order follows traversal direction: next siblings are found going forward; previous siblings are found going backward. If you need a stable sequence in document order after searching backward, reverse the results explicitly.
5. Iterate sibling nodes, including text
.next_siblings and .previous_siblings are useful when you need to inspect every later or earlier node, not only matching tags. They yield tags and strings.
for node in summary.next_siblings:
    print(type(node).__name__, repr(node))

for node in summary.previous_siblings:
    print(type(node).__name__, repr(node))
If you want only tags during iteration, filter by node type. Beautiful Soup tags have a name; strings do not.
for node in summary.next_siblings:
    if getattr(node, "name", None) is not None:
        print(node.name, node.get_text(" ", strip=True))
6. Skip whitespace when using direct navigation
If the requirement is specifically “the next tag node,” advance through strings until the next non-string node. Beautiful Soup’s NavigableString includes whitespace-only text and other text content, so decide whether to skip all strings or only whitespace based on your markup.
from bs4 import NavigableString

node = summary.next_sibling
while isinstance(node, NavigableString) and not node.strip():
    node = node.next_sibling

if node is not None:
    print(node.name, node.get_text(" ", strip=True))
This version skips whitespace-only strings but preserves meaningful text. To skip every string, including text content, change the loop condition to while isinstance(node, NavigableString):. Check for None after the loop because the target may be the final child.
For the previous direction, use the same pattern with previous_sibling. If you only need the next matching paragraph or link, the matching methods are shorter and less error-prone.
7. Sibling navigation versus document-order navigation
.next_sibling stays among nodes with the same parent. .next_element follows document order through the tree, including descendants. These are different questions.
# Adjacent node under the same parent
adjacent = summary.next_sibling

# Next node encountered in document order; may be inside a descendant
following_in_tree = summary.next_element
Use sibling methods to stay at the current structural level. Use document-order methods when you mean “whatever comes next in the parsed document,” even if it is nested inside the current element. Crossing a parent boundary is not what sibling navigation does.
8. Complete runnable example
This script demonstrates direct navigation, matching searches in both directions, plural results, and a whitespace-safe tag lookup. Save it as sibling_nodes.py and run it after installing beautifulsoup4.
from bs4 import BeautifulSoup, NavigableString

html = '''
<section>
  <h2>Title</h2>
  <p class="summary">Short overview</p>
  <p class="details" data-state="ready">More detail</p>
  <a class="sister" href="/one">One</a>
  <a class="sister" href="/two">Two</a>
</section>
'''

soup = BeautifulSoup(html, "html.parser")
summary = soup.find("p", class_="summary")
if summary is None:
    raise SystemExit("summary paragraph not found")

print("Immediate next node:", repr(summary.next_sibling))

next_tag = summary.next_sibling
while isinstance(next_tag, NavigableString) and not next_tag.strip():
    next_tag = next_tag.next_sibling
print("Next non-whitespace node:", getattr(next_tag, "name", None))

next_paragraph = summary.find_next_sibling("p")
print("Next paragraph:", next_paragraph.get_text(" ", strip=True)
      if next_paragraph else "none")

ready_detail = summary.find_next_sibling(
    "p", attrs={"data-state": "ready"}
)
print("Ready detail:", ready_detail.get_text(" ", strip=True)
      if ready_detail else "none")

links = summary.find_next_siblings("a", class_="sister")
print("Later sister links:", [link.get("href") for link in links])

previous_heading = summary.find_previous_sibling("h2")
print("Previous heading:", previous_heading.get_text(" ", strip=True)
      if previous_heading else "none")
Expected output is broadly: the immediate node is whitespace; the next non-whitespace node is a p; the matching paragraph contains “More detail”; the later links have /one and /two hrefs; and the preceding heading is “Title”. The exact representation of whitespace depends on the source string.
9. Choosing a sibling method
| Need | Use | What it returns |
|---|---|---|
| One physically adjacent node | .next_sibling / .previous_sibling |
A tag, string, comment, or None |
| Closest later or earlier matching node | .find_next_sibling() / .find_previous_sibling() |
First match or None |
| Every matching sibling | .find_next_siblings() / .find_previous_siblings() |
A list of matches, optionally limited |
| Inspect every sibling node | .next_siblings / .previous_siblings |
An iterator including strings |
| Move in document order through descendants | .next_element / .previous_element |
The next or prior tree node, which may be nested |
10. Common problems and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
next_sibling prints a newline |
Whitespace between tags is a text node | Use a matching sibling method or advance past whitespace-only strings. |
Sibling result is None |
The node is at that end of its parent’s child list, or the lookup did not find the expected target | Check the target lookup, parent structure, and whether a match exists in that direction. |
find_next_sibling() returns no result |
No later sibling matches the filters; the target might be nested elsewhere | Inspect the parent’s children, simplify the filter to diagnose it, and confirm the desired node shares the parent. |
| The “next visible element” is missing | The wanted node is nested under a different parent, so it is not a sibling | Choose an appropriate document-order or descendant search, or locate the correct common parent first. |
| Results change with parser choice | Malformed markup can be repaired into different trees by different parsers | Name the parser explicitly and inspect the parsed structure before changing traversal logic. |
| Attribute filter does not match | Wrong attribute name/value or query does not match the actual tag | Print the candidate tag’s attributes and use attrs={...} or the correct keyword filter. |
| Code raises an attribute error after lookup | A search returned None |
Check for None before calling .get_text(), .get(), or another tag method. |
11. Reliability, performance, and input handling
Sibling traversal is local to the parsed parent’s child list. A matching search may inspect later or earlier siblings until it finds a match or reaches the end. If the page is large, make the initial lookup specific and stop collecting once you have enough results by using limit where supported.
Parser choice is a reliability decision: explicitly selecting a parser avoids silently relying on environment defaults, but the chosen parser still determines how malformed HTML is repaired. When a selector suddenly stops working, inspect the parsed tree and verify the source markup rather than assuming the browser’s visual layout maps directly to sibling relationships.
Beautiful Soup parses HTML already available to your program; it does not fetch a web page or execute its JavaScript. For a static page, obtain the HTML from an authorized source and parse it. For content rendered only after browser-side JavaScript runs, fetch rendered HTML with a browser or capture service first, then apply Beautiful Soup to the returned markup if HTML is available.
For a production scraper, also handle network timeouts and failed responses in the fetching layer, set a reasonable request timeout, and follow the site’s access rules. Those concerns are separate from sibling navigation. A short and specific tree query is generally easier to maintain than scanning the entire document for a vaguely described “next” node.
12. When you need a screenshot instead of parsed HTML
Beautiful Soup is for extracting structure and text. If the output you need is a rendered page image or PDF, ScreenshotNeo is a website screenshot API and MCP server. Its options include full-page screenshots, element capture by CSS selector, custom waits, viewport and device settings, and PDF output. See the ScreenshotNeo API documentation for request parameters.
Or skip the browser setup
For a rendered screenshot, one GET request can return an image or PDF. This cURL example captures a page as WebP:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
- Cookie banners are accepted and removed, and 60+ known consent platforms, newsletter popups, and chat widgets are removed before the shot; each step can be turned off.
- Bot checks, CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing. Response headers report the page verdict and billing status.
- An MCP server provides
take_screenshot,get_page_info, andcapture_pdffor Claude, Cursor, and other MCP clients. - The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000 screenshots.
Sign up for 1,000 free screenshots a month, with no card required.
13. FAQ
Does find_next_sibling() search inside child elements?
No. It searches siblings at the same level. Use a descendant or document-order search if the desired node is nested.
Can a text node be a sibling?
Yes. Whitespace, punctuation, and ordinary text are nodes in the parent’s child list, so direct sibling properties can return them.
What does a sibling search return when nothing matches?
The singular method returns None. The plural method returns an empty list, so handle those cases before using the result.
Why specify html.parser?
It makes the parser choice explicit. Different parsers can build different trees from malformed HTML, which can change which nodes share a parent.
Does Beautiful Soup run JavaScript?
No. It parses markup you provide. If the content only exists after client-side rendering, obtain rendered HTML through a browser workflow before parsing it.


