The Best Apify Alternative for Developers
Compare Apify alternatives by rendering, access, control, operations and cost, then choose the right managed API or open-source crawler.
There is no single best Apify alternative for every developer. The right choice depends on whether you want a managed scraping API or a framework your team operates, which sites you need to access, whether pages require JavaScript rendering, how much session and proxy handling is involved, and how much infrastructure you want to maintain.
For a managed service, start by evaluating Zyte API. Zyte describes it as a single web scraping API with browser rendering, automatic IP rotation, extraction, session management, actions, instant browsers and geographic targeting. For source-level control, evaluate Scrapy, an open-source crawling framework maintained by Zyte engineers and released under a BSD license. ScrapingBee is another API candidate; its official pricing page says it handles headless browsers and rotates proxies, but verify its current feature set and pricing before making a detailed comparison.
Quick decision guide
| Your priority | Best starting point | Why |
|---|---|---|
| Managed rendering, sessions and geographic access | Zyte API | One endpoint covers browser rendering, IP rotation, sessions, actions and extraction. |
| Maximum crawler control and extensibility | Scrapy | You own the spider, parsing logic, scheduling and deployment. |
| API-first collection with headless browser and proxy features | ScrapingBee | Its official pricing page describes those capabilities; check current details before committing. |
| Website screenshots rather than structured scraping | ScreenshotNeo | Clean shots, only clean shots billed, and a $5 paid plan for 3,000 shots. |
Do not compare headline request prices without matching the workload. A JavaScript-rendered product page with retries and a geographic session has a different cost and operational burden from a simple HTTP response.
What makes an Apify alternative different?
Managed API versus framework
A managed API accepts a request and handles some combination of downloading, browser execution, proxy rotation, cookies, sessions, retries and extraction. Your application remains focused on input, output and business logic. This reduces infrastructure work, but provider defaults and per-request pricing shape your control and cost.
A framework such as Scrapy gives you source-level control. You define URL discovery, requests, parsing, item pipelines, concurrency and storage. You also plan deployment, scheduling, retries, observability, proxy or session handling and browser execution when a target needs them. Scrapy is free to use under its BSD licensing; running a production crawler still has infrastructure and maintenance costs.
Target-site requirements
List the domains you need before selecting a tool. Record whether content arrives in the initial HTML or after JavaScript runs, whether login or cookies are required, whether pages vary by country, and whether the site presents rate limits or bot checks. Zyte’s guidance describes these as separate concerns: URL discovery, downloading, parsing, proxy rotation, cookie and session handling, browser-like JavaScript execution and protocol behavior.
Control and customization
Choose a managed service when a stable API and provider-operated access layer are more valuable than custom crawler internals. Choose Scrapy when you need custom scheduling, parsers, item pipelines, storage integrations or domain-specific crawl logic. A hybrid is also practical: use Scrapy for orchestration and a managed browser or proxy service for difficult domains.
Zyte API: the managed alternative to evaluate first
Zyte presents Zyte API as a single web scraping API with automatic ban handling, browser rendering, IP rotation, AI extraction, sessions, actions, instant browsers and geographic targeting. These capabilities address the parts of collection that commonly require separate services in a self-managed stack.
Pricing is workload dependent. Zyte’s pricing documentation separates HTTP responses from browser-rendered requests and varies rates by target website tier. The page accessed for this research listed pay-as-you-go examples from $0.13 per 1,000 HTTP responses to $1.27 across tiers, and from $1.01 to $16.08 per 1,000 browser-rendered requests. Treat those figures as dated illustrations, not a quote: check the current pricing page and estimate using your actual domains, request types, retries and volume.
When Zyte API fits
- You want one managed endpoint instead of operating proxy pools and browser workers.
- Your targets need JavaScript rendering, sessions, actions or geographic targeting.
- You can estimate cost by target website and request type.
- Your team prefers API integration over maintaining crawler infrastructure.
Questions to answer before buying
- Which percentage of requests need a browser?
- Which target domains fall into which pricing tier?
- How many retries and failed requests should the estimate include?
- Do you need persistent sessions, actions or a specific country?
- What extraction format will your application consume?
Scrapy: the open-source framework route
Scrapy is a reasonable Apify alternative when your team wants control over the crawler itself. Zyte describes it as an open-source web crawling framework created by its co-founders and maintained by its engineers. The framework is free to use commercially or otherwise under BSD licensing.
Scrapy does not provide Apify’s hosted operational model by itself. You must decide where spiders run, how jobs are scheduled, how results are stored, how failures are retried and how metrics are collected. If a site needs JavaScript execution, proxy rotation or authenticated sessions, add and operate those pieces or connect to a managed provider.
Minimal runnable Scrapy spider
import scrapy


class ProductSpider(scrapy.Spider):
    name = "products"
    start_urls = ["https://example.com/products"]

    def parse(self, response):
        for card in response.css(".product"):
            yield {
                "name": card.css(".name::text").get(default="").strip(),
                "price": card.css(".price::text").get(default="").strip(),
                "url": response.urljoin(card.css("a::attr(href)").get()),
            }

        next_url = response.css("a.next::attr(href)").get()
        if next_url:
            yield response.follow(next_url, callback=self.parse)
Run it with:
python -m pip install scrapy
scrapy runspider products.py -o products.json
Production checklist for Scrapy
- Set an explicit concurrency limit and download delay for each domain.
- Persist crawl state so a worker restart does not lose progress.
- Record response status, latency, parser errors and item counts.
- Define retry rules for transient failures and stop rules for repeated blocks.
- Keep selectors and schemas versioned; target HTML changes are normal maintenance events.
- Assess applicable law, contracts and site policies for your collection.
ScrapingBee and other API candidates
ScrapingBee’s official pricing search result says its API handles headless browsers and rotates proxies. That is enough to place it on a candidate shortlist for API-first teams, but this research did not establish a complete, directly comparable feature or price matrix. Verify its current documentation, target coverage and pricing before ranking it against Zyte.
Bright Data and Oxylabs also appear in comparison-oriented results, but the research dossier does not contain directly comparable official product and pricing evidence. Treat them as follow-up candidates rather than declaring a winner.
How to compare total cost
Build a representative sample instead of comparing advertised unit prices. Include:
- Successful HTTP pages and browser-rendered pages.
- The mix of target websites and their pricing tiers.
- Expected retries, timeouts and blocked responses.
- Proxy, session, country and action requirements.
- Storage, scheduling, monitoring and engineering time.
- Ongoing parser changes and incident response.
For Scrapy, separate vendor fees from compute, proxy, browser-worker, storage and on-call costs. For a managed API, include the request price for each response type and any minimum or committed spend shown on the current vendor page. Recalculate when your site mix changes.
Reliability and performance considerations
Rendering overhead
Browser rendering generally requires more resources and time than an HTTP response. Use direct HTTP collection when the required data is present in the initial response. Reserve browser execution for pages whose content or interaction requires it.
Retries and idempotency
Retry only transient failures, with exponential backoff and a cap. Make downstream writes idempotent so a retry cannot create duplicate records. Store the request URL, parameters, attempt number and final status for diagnosis.
Sessions and geography
Login state, consent cookies and country-specific content can change the response. Decide whether a session should persist across requests and test the same URL from each required region. Do not assume that a successful request proves every variant works.
Observability
Track success rate, response type, latency, retry count, parser error rate, item yield and cost per useful item. Alert on changes in item yield as well as transport errors; a page can return HTTP 200 while its content has changed.
Or skip the browser setup
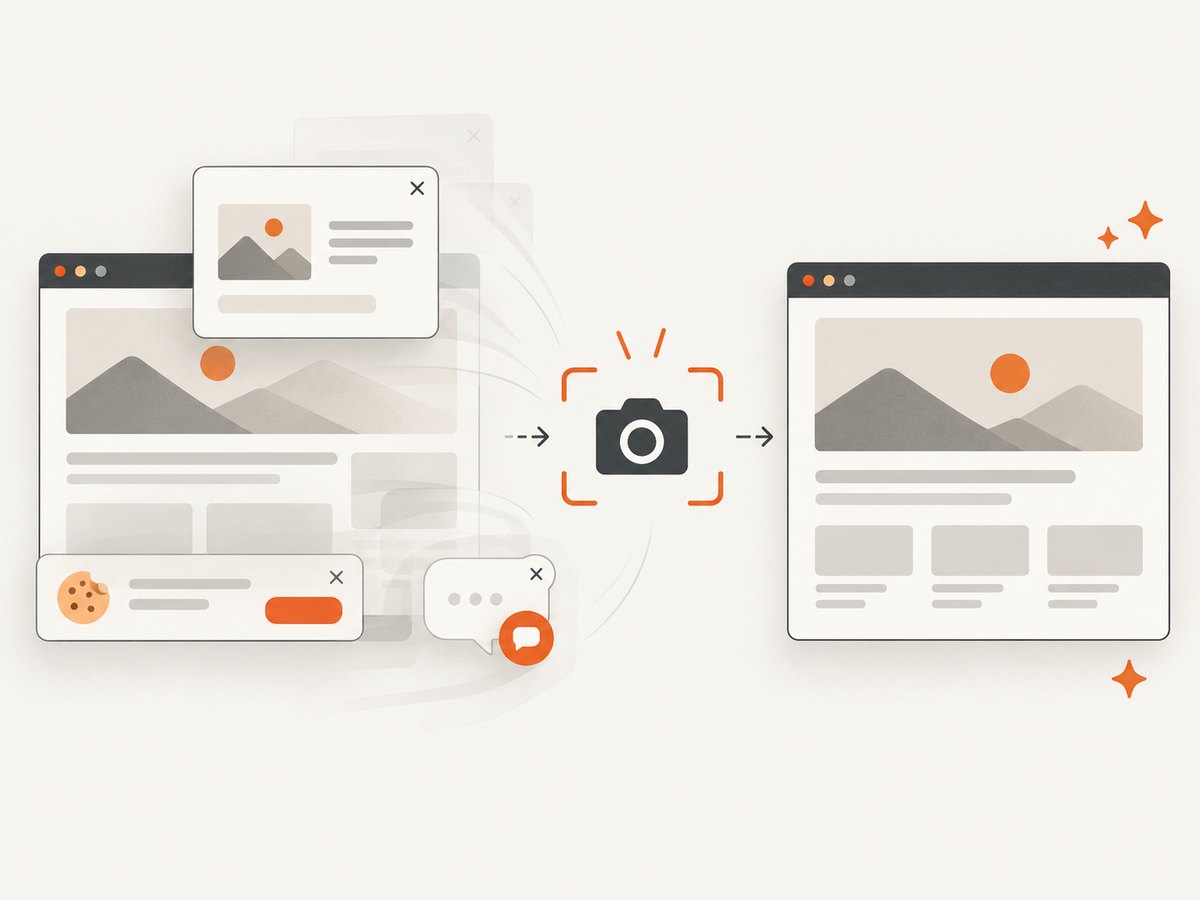
If your job is to capture visual pages rather than extract structured records, ScreenshotNeo is the first service to try. It is a website screenshot API and MCP server: one GET request returns a PNG, JPEG, WebP or PDF. Before capture it accepts cookie or consent banners and removes more than 60 known consent platforms, newsletter popups and chat widgets. Each step can be turned off.
Only clean shots are billed. Bot checks, CAPTCHAs, blank pages, timeouts, failed loads and cache hits cost nothing, and the response reports the result through X-Page-Verdict and X-Billed headers. An MCP server provides take_screenshot, get_page_info and capture_pdf tools for Claude, Cursor and other MCP clients.
See the ScreenshotNeo API documentation for all options.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const body = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('shot.webp', body);
ScreenshotNeo also supports full-page capture with lazy images loaded, CSS-selector element capture, dark mode, 12 device presets or custom viewports, retina scale, PDF paper sizes and page ranges, HTML/CSS to image, custom CSS and JavaScript, clicks, selector or network-idle waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, configurable caching TTLs, signed links, asynchronous jobs with signed webhooks, bulk capture for up to 100 URLs per call, a usage API and an OpenAPI specification. Parameter names used by other screenshot APIs also work to ease migration.
There are 1,000 screenshots per month free with no card. Paid plans start at $5 for 3,000 shots; every feature is available on every plan. Create a free ScreenshotNeo account.
Troubleshooting
The page is empty
Check whether content is JavaScript-rendered, whether a required selector appears, and whether the request was blocked or timed out. For Scrapy, inspect the raw response and add a browser component only when needed. For managed APIs, inspect the response verdict or status details and retry transient failures.
Selectors return no items
Save the response HTML and compare it with the browser DOM. Client-side rendering, A/B tests and changed class names commonly cause this. Prefer stable attributes, add parser tests and alert when item yield falls to zero.
Requests are blocked
Confirm that your collection is permitted, then review request rate, session behavior, geographic requirements and proxy configuration. A managed API may provide rotation or browser execution; with Scrapy, those are operational components you must configure and monitor.
Costs are higher than expected
Separate browser-rendered requests from HTTP responses, include retries and check the target-site tier. For self-managed crawlers, add compute, proxy, storage and maintenance effort to the estimate. Re-run the calculation against a representative sample.
ScreenshotNeo returns a verdict you did not expect
Inspect X-Page-Verdict and X-Billed, then check URL access, wait conditions, selectors, blocking rules and cache settings. A failed load, blank page, bot check or cache hit is not billed.
FAQ
Is Scrapy a hosted replacement for Apify?
No. Scrapy is a framework. Your team operates scheduling, workers, storage, retries and any browser or proxy layer it needs.
Should every scraper use browser rendering?
No. Use direct HTTP collection when the required data is in the initial response. Add browser execution for JavaScript-dependent content or interactions.
How can I compare Zyte API pricing fairly?
Use your real domain mix, HTTP-versus-browser ratio, retries, geographic needs and monthly volume. Zyte’s rates vary by target website and request type.
Can ScreenshotNeo replace a data extraction API?
It is designed for screenshots and PDFs, not structured record extraction. Use it when the required output is a visual capture or document.
What should I verify before collecting data?
Review applicable law, contracts, terms and site policies for your project. Technical access does not determine permission.


