The Best Scrapy Alternative for 2026
Compare Scrapy alternatives for JavaScript rendering, browser automation, scale, and cost, with runnable migration examples and a practical decision guide.
Short answer: there is no single best Scrapy replacement for every project. Keep Scrapy when its asynchronous scheduler, concurrency controls, pipelines, exports, and politeness settings already fit the job. Move to a browser tool when the required data only appears after JavaScript runs or the workflow needs clicks, scrolling, authentication, or other visible browser actions. For an existing Scrapy codebase, try selective rendering with scrapy-playwright. For a new JavaScript or Python project that combines HTTP crawling and browser automation, evaluate Crawlee against your deployment and language requirements. If your real need is a rendered visual or PDF rather than structured extraction, a managed capture API such as ScreenshotNeo can remove browser operations from your application.
This guide explains the trade-offs, gives runnable examples, and shows a migration path that avoids replacing more of your stack than necessary.
What Scrapy does well
Scrapy is a crawling framework, not just an HTML parser. Its architecture includes asynchronous request scheduling, concurrency and politeness controls, duplicate filtering, item pipelines, feed exports, middleware, and extensions. Those pieces matter when you need to visit many URLs, retry failures, limit pressure on a host, normalize records, and write structured output.
Scrapy also supports responses that contain JSON, embedded data, and links to additional resources. A missing element in the first HTML response does not prove that Scrapy is the wrong tool. The official documentation recommends finding the underlying data source and extracting it when practical: Selecting dynamically-loaded content.
Decision matrix: which alternative fits?
| Option | Choose it when | Trade-off |
|---|---|---|
| Keep Scrapy | The required data is in HTTP responses and you need crawl scheduling, pipelines, exports, and concurrency controls. | You must reproduce APIs or embedded data when pages depend on JavaScript. |
| Scrapy plus scrapy-playwright | You have mature spiders but need browser rendering for selected requests. | Browser processes add startup time, memory use, lifecycle failures, and deployment work. |
| Playwright | The workflow depends on a real browser, clicks, scrolling, dialogs, authentication, or JavaScript state. | You build your own queueing, persistence, retries, and extraction conventions. |
| Puppeteer or Selenium | Your team already uses that browser automation stack or its language bindings. | They are browser automation tools, not direct replacements for Scrapy’s crawl framework. |
| Crawlee | You want a new framework combining HTTP crawling and browser automation in a JavaScript/Node.js or Python project. | Confirm language feature parity, integrations, and deployment behavior in the current documentation. |
| Beautiful Soup or MechanicalSoup | You need simple parsing or form/session workflows without full browser execution. | You supply crawl scheduling, persistence, retries, and any browser capability yourself. |
| Scrapy Cloud | The problem is hosting, scheduling, or operations around existing spiders. | Hosted execution does not automatically solve JavaScript rendering or site blocking. |
| Managed scraping API | You want to outsource proxy, browser, and retry infrastructure. | Validate target-site compatibility, limits, data handling, and total cost for your workload. |
A practical migration path
- Write down the failure. Is content absent, interaction impossible, the crawl too slow, deployment unreliable, or maintenance too expensive?
- Inspect the page’s network activity. Use browser developer tools to find JSON or GraphQL requests that contain the data. Reproducing that request is usually lighter and more stable than rendering every page.
- Keep the existing spider where it works. Add browser rendering only to requests that need it. This preserves item pipelines, duplicate filtering, feeds, and crawl controls.
- Choose a browser framework for browser-first work. Use Playwright, Puppeteer, Selenium, or Crawlee when interaction is the primary requirement.
- Choose a managed service for operations pain. Compare the complete cost of browsers, proxies, storage, monitoring, retries, and engineering time rather than a request price alone.
- Measure representative pages. Record success rate, median and tail latency, memory per worker, extracted-field completeness, and cost at your expected volume.
Start with the data request when possible
Suppose a product page renders prices from an API call. First inspect the request in the browser’s Network panel. Check its method, query parameters, request body, headers, cookies, and response format. Then reproduce it in a Scrapy spider.
import scrapy

class ProductApiSpider(scrapy.Spider):
    name = 'product_api'

    def start_requests(self):
        yield scrapy.Request(
            url='https://example.com/api/products/42',
            headers={'Accept': 'application/json'},
            callback=self.parse_product,
        )

    def parse_product(self, response):
        data = response.json()
        yield {
            'id': data.get('id'),
            'name': data.get('name'),
            'price': data.get('price'),
        }
Keep authentication values in settings or environment variables, not in source control. Add pagination, retries, throttling, and validation after the single request is correct.
Use scrapy-playwright for selective rendering
The Scrapy documentation points to Playwright and recommends an integration layer when you need browser rendering inside a Scrapy project. Install the packages and enable the download handler:
pip install scrapy-playwright
playwright install chromium
# settings.py
DOWNLOAD_HANDLERS = {
'http': 'scrapy_playwright.handler.ScrapyPlaywrightDownloadHandler',
'https': 'scrapy_playwright.handler.ScrapyPlaywrightDownloadHandler',
}
TWISTED_REACTOR = 'twisted.internet.asyncioreactor.AsyncioSelectorReactor'
PLAYWRIGHT_BROWSER_TYPE = 'chromium'
CONCURRENT_REQUESTS = 8
DOWNLOAD_TIMEOUT = 60import scrapy
from scrapy_playwright.page import PageMethod
class RenderedSpider(scrapy.Spider):
name = 'rendered'
def start_requests(self):
yield scrapy.Request(
'https://example.com/catalog',
meta={
'playwright': True,
'playwright_page_methods': [
PageMethod('wait_for_selector', '[data-product]'),
PageMethod('evaluate', "window.scrollTo(0, document.body.scrollHeight)"),
],
},
)
def parse(self, response):
for card in response.css('[data-product]'):
yield {
'name': card.css('[data-name]::text').get(),
'url': response.urljoin(card.css('a::attr(href)').get()),
}Use browser requests sparingly. Each page may start a browser context, load fonts and images, execute scripts, and remain open while asynchronous work completes. Set explicit timeouts, close pages and contexts through the integration, and keep concurrency below the point where memory pressure causes cascading failures.
Use Playwright directly for browser-first workflows
A standalone Playwright worker is easier to reason about when every target requires interaction. This example waits for a selector, clicks a consent control, and extracts rendered text.
import asyncio
from playwright.async_api import async_playwright

async def main():
    async with async_playwright() as p:
        browser = await p.chromium.launch(headless=True)
        page = await browser.new_page(viewport={'width': 1440, 'height': 900})
        await page.goto('https://example.com', wait_until='domcontentloaded', timeout=60000)
        consent = page.locator('button:has-text("Accept")')
        if await consent.count():
            await consent.first.click()
        await page.wait_for_selector('main', timeout=30000)
        title = await page.locator('h1').inner_text()
        print(title)
        await browser.close()

asyncio.run(main())
For production, add a bounded queue, retries with backoff, per-host limits, structured logs, and a cleanup path for browser crashes. Persist progress so a worker restart does not restart the entire crawl.
Other alternatives and when they make sense
Crawlee
Crawlee is a candidate for a new project that needs both HTTP crawling and browser automation. Evaluate its JavaScript/Node.js and Python support, request queue behavior, storage model, and deployment fit against your requirements. Treat vendor-authored comparisons as starting points, not independent performance proof.
Beautiful Soup and MechanicalSoup
These tools are useful when parsing is the hard part and pages do not require a full browser. You will still need to design URL scheduling, duplicate handling, retries, persistence, and session management. They are components, not drop-in replacements for Scrapy’s complete crawl architecture.
Puppeteer and Selenium
Choose these when your team already has operational knowledge, test utilities, or language bindings built around them. Model them as browser control layers. You must add the crawl framework concerns that Scrapy provides.
Hosted execution and managed APIs
A hosted Scrapy service can remove server maintenance while preserving spiders. A managed API can remove browser, proxy, and retry operations. Neither choice guarantees access to every target. Test representative domains, authentication flows, rate limits, and legal permissions before committing.
Or skip the browser setup
If your output is a clean screenshot or PDF, ScreenshotNeo is the alternative to try first: it removes cookie banners, newsletter popups, and chat widgets before capture, bills only clean shots, and has the lowest paid plan described here.
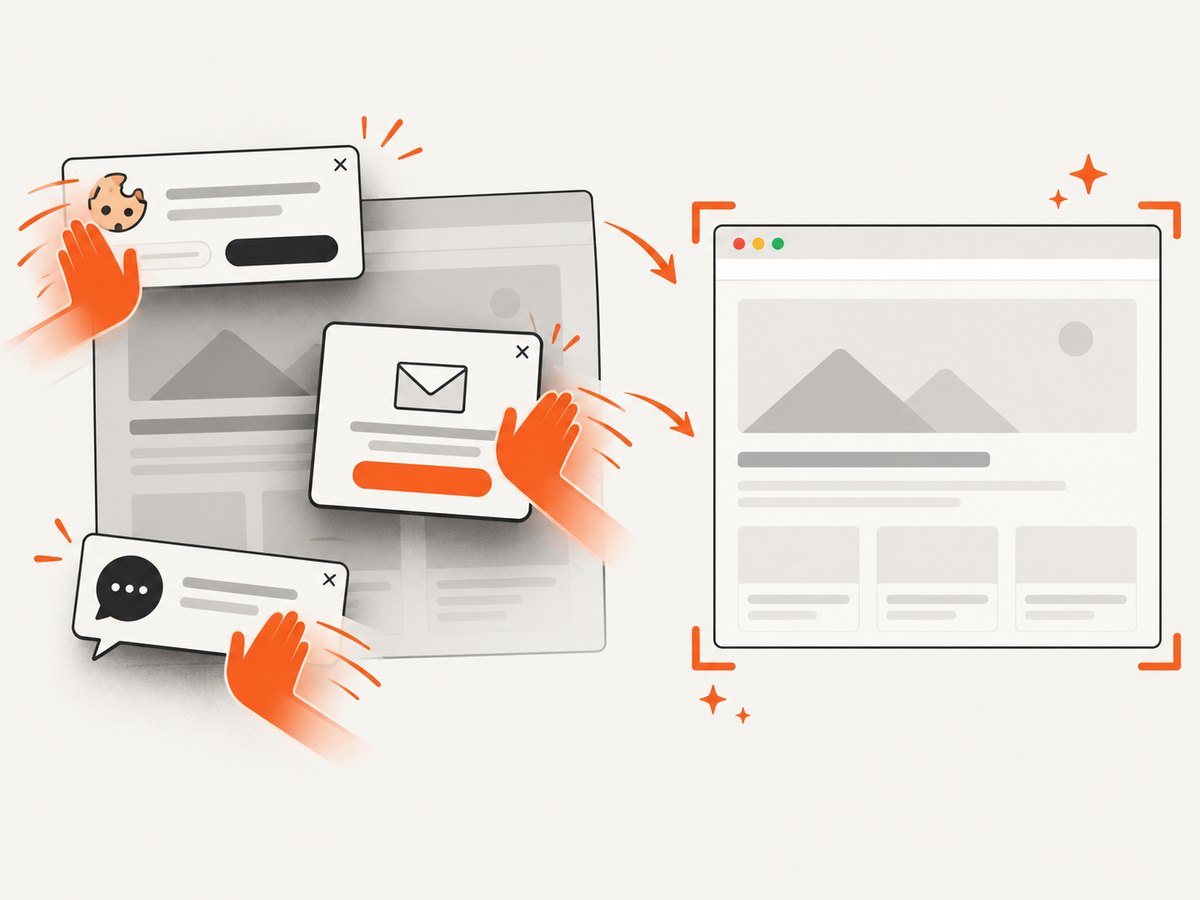
One GET request returns PNG, JPEG, WebP, or PDF. See the ScreenshotNeo API documentation for the complete option list.
cURL
curl -G 'https://api.screenshotneo.com/v1/shot' -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get('https://api.screenshotneo.com/v1/shot', params={'access_key': 'YOUR_API_KEY', 'url': 'https://stripe.com'}, timeout=90)
open('shot.webp', 'wb').write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
ScreenshotNeo supports full-page capture with lazy images loaded, CSS selector element capture, dark mode, 12 device presets or custom viewports, retina scale, PDF paper sizes and page ranges, custom CSS and JavaScript, clicks, selector or network-idle waits, request and resource blocking, headers, cookies, user agents, Authorization, timezone, geolocation, transparent backgrounds, resizing, chosen cache TTLs, signed links, asynchronous jobs with signed webhooks, bulk capture for 100 URLs per call, a usage API, and an OpenAPI specification.
Responses identify outcomes with X-Page-Verdict and X-Billed headers. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
Create a free ScreenshotNeo account: 1,000 screenshots each month with no card. Paid plans start at $5 for 3,000 shots.
Configuration checklist
- Rendering: decide whether HTTP responses, an API call, or a browser is required.
- Interaction: list clicks, scrolls, dialogs, authentication, and waits explicitly.
- Politeness: set per-host concurrency, download delays, robots handling, and a clear user agent.
- Reliability: use bounded retries, idempotent storage, checkpoints, and timeouts for DNS, connection, download, and browser actions.
- Observability: log URL, attempt, status, latency, response size, browser errors, and extracted-field validation.
- Security: keep cookies, tokens, and proxy credentials out of logs and source control.
- Compliance: confirm authorization, terms, robots directives, privacy requirements, and retention rules for every target.
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Selector returns nothing | The content is injected after the initial response. | Inspect network calls; reproduce the API or wait for a browser selector. |
| Playwright times out | Wrong wait condition, slow resource, blocked request, or a page that never becomes idle. | Use a specific selector, set a bounded timeout, and collect console and network errors. |
| Scrapy becomes slow after browser integration | Too many concurrent browser pages or expensive assets. | Lower browser concurrency, block unneeded resources, and keep static requests on Scrapy. |
| Duplicate pages are crawled | Query normalization or duplicate filtering changed during migration. | Canonicalize URLs and preserve a shared fingerprint strategy. |
| Data disappears after a restart | Progress exists only in memory. | Persist request queues, checkpoints, and items; make writes idempotent. |
| 403, CAPTCHA, or bot page | The target detects automation, rate, IP, or fingerprint patterns. | Verify permission, reduce load, use an allowed access method, and do not treat a browser switch as a guaranteed bypass. |
| Incomplete lazy-loaded content | Scrolling or the required wait did not occur. | Scroll in steps, wait for the content selector, and validate item counts. |
| Memory grows continuously | Pages, contexts, responses, or extracted objects remain referenced. | Close browser resources, stream items, cap concurrency, and restart workers at a controlled threshold. |
Performance, reliability, and cost
HTTP extraction normally has lower startup and memory cost than a browser. Browser rendering is justified when it prevents missing data or replaces fragile reverse engineering. Benchmark both paths on the same URL mix, including slow pages and failures. Record p50 and p95 latency, success rate, completeness, CPU, memory, bandwidth, and operator time.
At scale, the largest costs often come from browser concurrency, proxy traffic, storage, and engineering time spent repairing selectors. A slower but deterministic API request can be cheaper than rendering every page. Conversely, a browser may reduce maintenance when a site changes its client-side implementation frequently.
For ScreenshotNeo, clean shots are the billable unit. Cache hits and failed categories identified by the response headers are not billed. Choose a cache TTL that matches freshness requirements, use bulk capture for batches of up to 100 URLs, and use asynchronous jobs with signed webhooks when a synchronous request would exceed your worker timeout.
Migration checklist
- Inventory spiders, middlewares, item pipelines, exports, and scheduling assumptions.
- Classify URLs as static, API-backed, browser-rendered, blocked, or requiring authentication.
- Convert one representative spider and compare extracted fields, not just HTTP status.
- Add explicit waits and validation for every browser-rendered field.
- Load-test with realistic concurrency and failure rates.
- Run old and new paths together until discrepancies are understood.
- Document ownership for selectors, browser versions, credentials, and target permissions.
FAQ
Is Playwright a replacement for Scrapy?
It replaces the browser-control part of a workflow. It does not automatically provide Scrapy’s scheduler, pipelines, feeds, and crawl policies. Use an integration when you need both.
Should I rewrite a working Scrapy project?
No. Keep reliable spiders and change only the requests whose data cannot be obtained from HTTP responses or APIs.
Is Crawlee faster than Scrapy?
The supplied evidence does not establish a universal performance winner. Measure your target mix, language, deployment, and extraction logic.
When is a screenshot API the right abstraction?
Use one when the required result is a rendered image or PDF and operating browsers, waits, consent handling, retries, and output storage would distract from your product.
Can ScreenshotNeo replace a structured data crawler?
No. It returns screenshots or PDFs and page information. Use Scrapy or another crawler when you need records, pagination, and structured extraction.


