How to Capture a Whole Website
Learn how to mirror a public site with HTTrack, verify coverage, handle dynamic pages, resume crawls, and choose an API or archive service.
Direct answer: For an offline copy of a linked public website, use HTTrack. Start with the final canonical URL, set host and path boundaries, run the crawl, then inspect the logs and open the local copy to find missing pages or assets. HTTrack follows discoverable links and downloads files, but it does not execute JavaScript, so it cannot guarantee a complete copy of every modern application state.
If you only need one page, use Internet Archive’s Save Page Now. For recurring organizational preservation, evaluate Archive-It, a paid managed subscription from the Internet Archive.
1. Decide what “whole website” means
Choose the capture method from the outcome you need:
| Need | Approach | Main limitation |
|---|---|---|
| Offline browsing of a linked public site | HTTrack mirror | Coverage depends on links, scope, access, and page construction. |
| One page for citation or sharing | Internet Archive Save Page Now | Saves one page and its resources, not a whole-site crawl. |
| Recurring institutional captures | Archive-It | Paid managed service; confirm current terms with the provider. |
| Rendered screenshots or PDFs of selected pages | ScreenshotNeo or another capture API | Produces visual captures rather than a navigable mirror. |
Before crawling, write down the starting URL, allowed hostnames, allowed paths, whether subdomains and CDNs are in scope, the desired replay format, and the date of capture. A mirror is not the site’s database or a guaranteed reconstruction of forms, searches, accounts, personalized pages, streaming media, or interactive application state.
2. Install HTTrack and start from the final URL
HTTrack’s official site lists Windows, macOS/Linux/Unix/BSD, and Android versions. It describes the program as recursively downloading a site into a local directory and rebuilding relative links for offline browsing. Use the graphical interface if you prefer, or the command line for repeatable jobs.
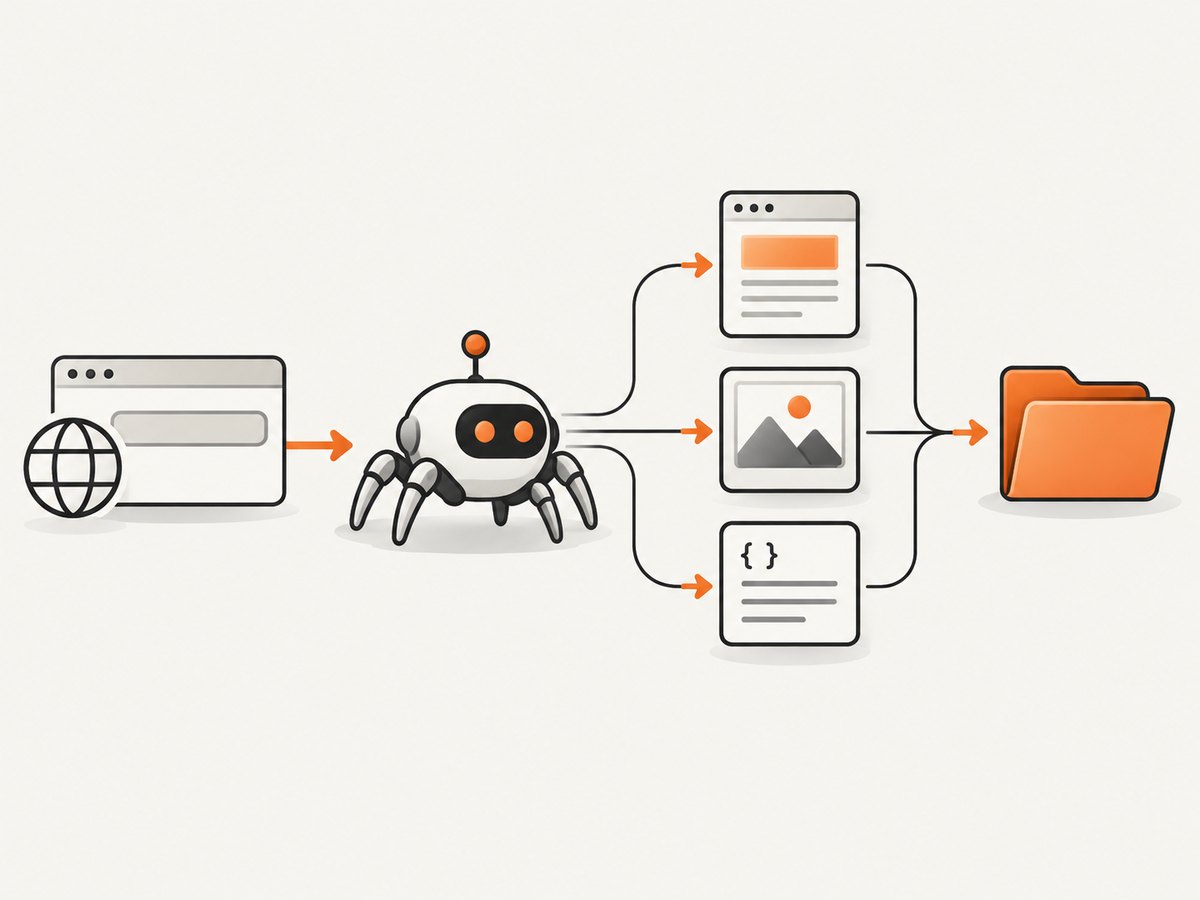
Resolve redirects before starting. If http://example.com redirects to https://www.example.com, start with the final URL. The default crawl stays on the starting host, so beginning on the wrong hostname can stop the crawl at a redirect.
# Basic mirror
httrack "https://example.com/" -O "./mirror-example"

# Mirror with a descriptive project name
httrack "https://www.example.com/" -O "./captures/example-2026-10-01"
HTTrack’s current command guide documents recursive crawling, resume and update operations, filters, sitemap seeding, logs, WARC/WACZ output, and politeness controls. See the official command-line guide for platform-specific syntax.
3. Set crawl boundaries before expanding scope
A narrow scope is easier to verify and places less load on the source server. Start with the original host, then add related hosts only when you know they contain required content.
Host and path scope
- Same host: keeps the crawl on the starting hostname.
- Related subdomains: may be needed for documentation, images, downloads, or a blog, but can also pull in unrelated content.
- CDNs and third-party hosts: include only when the local copy needs those assets and the site owner permits the requests.
- Path filters: include required directories and exclude account areas, search endpoints, calendars, tracking URLs, or other unbounded sections.
- Depth and size limits: useful when a site is broad or you are making a sample capture before committing to a full crawl.
Seed pages that are not linked
A crawler only discovers URLs it can reach from links and other supported sources. HTTrack’s sitemap support is off by default; sitemap URLs still pass through the same scope and filters. Seed a sitemap or a list of known entry points when important pages are not linked from navigation.
Respect access rules
Keep request rates reasonable, follow robots.txt behavior and site instructions, and crawl systems you own or have permission to capture. HTTrack’s documentation explicitly places responsibility for copying a website on the operator; read its documentation and responsible-use guidance before running a large job.
4. Run, resume, and update a mirror
A first crawl can be interrupted by a network failure, laptop sleep, or a server timeout. Re-run the same project to resume the interrupted job. To refresh an existing mirror later, use HTTrack’s update operation documented in the command guide rather than deleting the directory and starting over.
# Resume or continue the existing project directory
httrack "https://example.com/" -O "./mirror-example"

# Update an existing mirror (consult the version's command guide for the exact update switch)
httrack --update "./mirror-example"
Command-line switches vary by platform and release. Check httrack --help and the official guide before putting a command into automation. Preserve the project directory, configuration, logs, and capture date together so a later update has the information it needs.
5. Check whether the local copy is complete
Do not treat a successful process exit as proof that every page was captured. Verify both the crawl records and the rendered result.
- Read
hts-log.txtfor requested, redirected, filtered, and completed URLs. - Read
hts-err.txtfor refused, failed, or otherwise problematic requests. - Open the local index in a browser and follow representative navigation paths.
- Test pages from each major section, including a deep URL that was not on the home page.
- Check images, stylesheets, fonts, JavaScript bundles, PDFs, and other downloads.
- Compare a sample of canonical source URLs with the local link targets.
- Record known gaps, the source URL, capture date, scope rules, and the HTTrack version.
For evidence or preservation work, retain the original URLs and capture timestamps. HTTrack documents WARC output and WACZ packaging for archival and replay workflows; choose the format supported by your intended archive or replay system.
6. Understand what a crawler cannot capture
| Content or condition | Why it may be missing | Practical response |
|---|---|---|
| JavaScript-generated links | HTTrack parses HTML and CSS but does not execute JavaScript. | Provide sitemap or URL seeds, or use a browser-based capture for rendered states. |
| Login-only pages | Authentication and session state are not public crawl inputs. | Use an authorized export or a capture process that supports your access model. |
| Server-side restrictions | The server may refuse requests, require headers, or rate-limit the crawler. | Review permissions and logs; do not bypass controls. |
| Unlinked content | No discoverable link leads to the URL. | Seed URLs or a sitemap, subject to scope filters. |
| Third-party assets | Resources may live outside permitted hosts or block automated requests. | Include approved hosts or document the missing dependency. |
| Personalized or interactive state | The state depends on cookies, accounts, APIs, time, or user actions. | Capture defined states separately and label their conditions. |
| Streaming and backend data | A local file mirror cannot reproduce the remote service or database. | Preserve an export, recording, or archival package appropriate to the system. |
7. Troubleshoot common failures
The crawl stops after a redirect
Cause: the starting hostname redirected to another hostname and the default same-host scope did not follow it. Fix: restart from the final canonical HTTPS URL and confirm the destination host.
Important pages are absent
Cause: pages were not linked, were outside the path filter, or were generated at runtime. Fix: add approved seed URLs or sitemap entries, review filters, and use a browser-based method for JavaScript-only routes.
Images or styles are missing
Cause: assets came from an excluded CDN, were refused, or were loaded dynamically. Fix: inspect hts-log.txt and hts-err.txt, add the required approved host, and recrawl.
The local page opens but navigation returns online
Cause: a link was outside the rewritten scope, used an unsupported runtime route, or was intentionally left external. Fix: inspect the link target, widen scope only when necessary, and document external dependencies.
The crawl appears incomplete after a network interruption
Cause: requests ended before all files finished. Fix: rerun the same project to resume, then inspect the error log and test the affected sections.
The mirror is unexpectedly huge
Cause: broad subdomain or CDN scope, query-string URLs, calendars, search pages, or downloadable files. Fix: narrow host and path filters, set depth or size limits, and exclude unbounded URL patterns.
Pages require a bot check or return blank content
Cause: the origin serves a challenge, denies automated requests, or depends on JavaScript execution. Fix: obtain permission and use an authorized browser or export workflow; do not advise bypassing the site’s controls.
8. Performance, reliability, and storage
- Performance: crawl time grows with page count, asset count, redirects, server latency, and request throttling. Limit scope before increasing concurrency.
- Reliability: use a stable output directory, preserve logs, and resume interrupted projects instead of discarding partial work.
- Storage: estimate space from HTML, images, scripts, fonts, video, PDFs, and duplicate URL variants. A portable external SSD can hold a mirror when local disk space is insufficient; the cited HTTrack material does not establish a universal drive size.
- Verification: sample every major section and inspect logs after each run. A large file count is not a coverage metric by itself.
- Cost: HTTrack is free software under GPL version 3 or later. Your operational costs are storage, bandwidth, and time. Archive-It is a paid subscription service.
9. When a screenshot or PDF API is the better fit
Use a screenshot API when you need a visual record of selected pages, a report, a thumbnail set, or a PDF rather than a navigable offline mirror. In a whole-site project, it can complement HTTrack by capturing representative rendered states that a non-JavaScript crawler cannot reproduce.
10. Or skip the browser setup
ScreenshotNeo is a website screenshot API and MCP server. One GET request returns a PNG, JPEG, WebP, or PDF. It can capture full pages with lazy images loaded, a single CSS-selected element, dark mode, device presets or custom viewports, retina scale, custom CSS and JavaScript, waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs, bulk capture, and usage data. PDF options include paper size, margins, landscape mode, and page ranges.
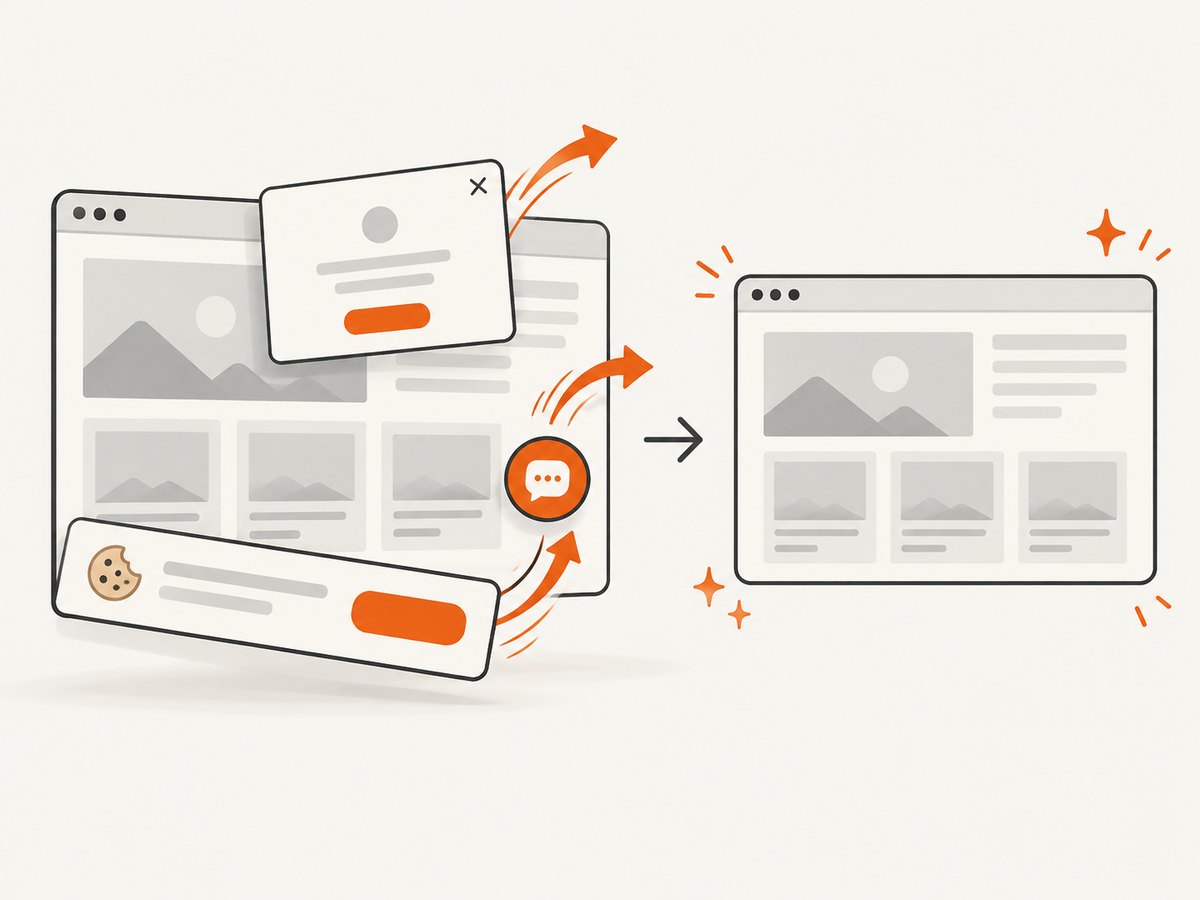
ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture; each cleanup step can be disabled. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. Its MCP server provides take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients.
See the ScreenshotNeo API documentation for all parameters. The following examples save a rendered capture of the target URL:
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
ScreenshotNeo has 1,000 shots per month free with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is available on every plan. Create a free ScreenshotNeo account to begin.
11. Short FAQ
Can HTTrack copy every page on a site?
No. It can only capture content it can discover and access, and it does not execute JavaScript. Authentication, server restrictions, unlinked URLs, and external resources can also limit coverage.
How far does the crawl reach?
By default it follows links on the starting host to any depth allowed by the project settings. Filters, depth limits, size limits, and host boundaries determine the practical reach.
How do I download PDFs on a site?
Allow the PDF paths and host in your filters, then confirm the files in the logs and local copy. If PDFs are generated only after browser interaction, use an authorized browser workflow or a PDF capture API.
How can I resume an interrupted crawl?
Run the same HTTrack project again so it can continue using the existing output and state, then inspect the error log for files that still need attention.
How do I update a mirror?
Use HTTrack’s update operation against the existing project directory and review the resulting logs. Keep the prior capture and metadata when you need historical comparison.
Is a mirror suitable as legal evidence?
The technical material does not settle jurisdiction-specific evidence or permission rules. Preserve source URLs, capture dates, logs, and the exact scope, and obtain advice appropriate to your situation.


