How to Capture Angular Elements With Selenium and Python
Locate, wait for, read, and screenshot Angular elements reliably with Selenium and Python, including dynamic DOM fixes and production tips.
Direct answer: Angular pages are captured with Selenium using ordinary WebDriver locators against the browser’s live, rendered DOM. Locate the element with a stable ID or concise CSS selector, wait for the state you need, then read its text or attributes or save an element screenshot. Angular does not require a special Selenium locator.
What “capture an Angular element” means
In this guide, capture means finding an element rendered by an Angular application and then collecting its content or image. Selenium can:
- Read visible text with
element.text. - Read DOM attributes with
get_attribute(). - Capture one element with
element.screenshot(). - Capture the complete viewport with
driver.save_screenshot(). - Collect multiple matching elements with
find_elements().
Angular component selectors are compile-time rules for component hosts. Angular test helpers such as DebugElement, By.css, and TestBed belong to Angular’s test environment; an external Selenium process uses WebDriver’s By strategies in the browser.
Complete Python example
Install Selenium and ensure a compatible Chrome browser and driver are available:
python -m pip install seleniumReplace the URL and selector with values from the application’s rendered DOM. The data-testid attribute below is only an example.
from pathlib import Path

from selenium import webdriver
from selenium.webdriver.common.by import By
from selenium.webdriver.support import expected_conditions as EC
from selenium.webdriver.support.ui import WebDriverWait

URL = "https://example.test"
CARD_SELECTOR = "[data-testid='result-card']"
OUTPUT = Path("result-card.png")

options = webdriver.ChromeOptions()
# options.add_argument("--headless=new")  # Enable in CI or on a server.
# options.add_argument("--window-size=1440,1200")

driver = webdriver.Chrome(options=options)
wait = WebDriverWait(driver, 15)

try:
    driver.get(URL)

    # Presence means the node exists in the DOM.
    card = wait.until(
        EC.presence_of_element_located((By.CSS_SELECTOR, CARD_SELECTOR))
    )

    # Visibility is a better condition before reading or screenshotting.
    card = wait.until(
        EC.visibility_of_element_located((By.CSS_SELECTOR, CARD_SELECTOR))
    )

    print("Text:", card.text)
    print("Data ID:", card.get_attribute("data-id"))

    # Re-find immediately before capture when the page can re-render.
    card = driver.find_element(By.CSS_SELECTOR, CARD_SELECTOR)
    card.screenshot(str(OUTPUT))
    print(f"Saved {OUTPUT}")

    # To capture the viewport instead, use:
    # driver.save_screenshot("viewport.png")
finally:
    driver.quit()
The official Selenium workflow covers driver startup and navigation, while the locator and wait documentation explains the lookup and synchronization APIs: WebDriver documentation, locator strategies, and waiting strategies.
Locate the right Angular element
1. Inspect the live DOM
Open browser developer tools after the page has rendered. Inspect the element you need and choose an attribute or structure that is unique and controlled by the application. Prefer a predictable ID when one exists. Otherwise use a short CSS selector. Ask the application maintainer to add a stable test attribute when no durable identifier is available.
# ID
(By.ID, "checkout-total")

# Name
(By.NAME, "email")

# CSS attribute
(By.CSS_SELECTOR, "button[data-testid='save']")

# Class (use only when the class is stable)
(By.CLASS_NAME, "price-card")

# XPath (useful for relationships or text conditions)
(By.XPATH, "//button[@type='submit']")
Selenium also supports tag name, link text, and partial link text. Keep selectors readable and scope them beneath a known parent when that removes ambiguity:
panel = driver.find_element(By.CSS_SELECTOR, "[data-testid='results-panel']")
rows = panel.find_elements(By.CSS_SELECTOR, "[role='row']")
2. Choose singular or plural lookup
| Need | API | Result when nothing matches |
|---|---|---|
| One intended element | find_element |
Raises NoSuchElementException |
| Every current match | find_elements |
Returns an empty list |
headline = driver.find_element(By.CSS_SELECTOR, "h1").text
items = driver.find_elements(By.CSS_SELECTOR, "[data-testid='result-card']")
for item in items:
    print(item.text)
Wait for Angular’s rendered state
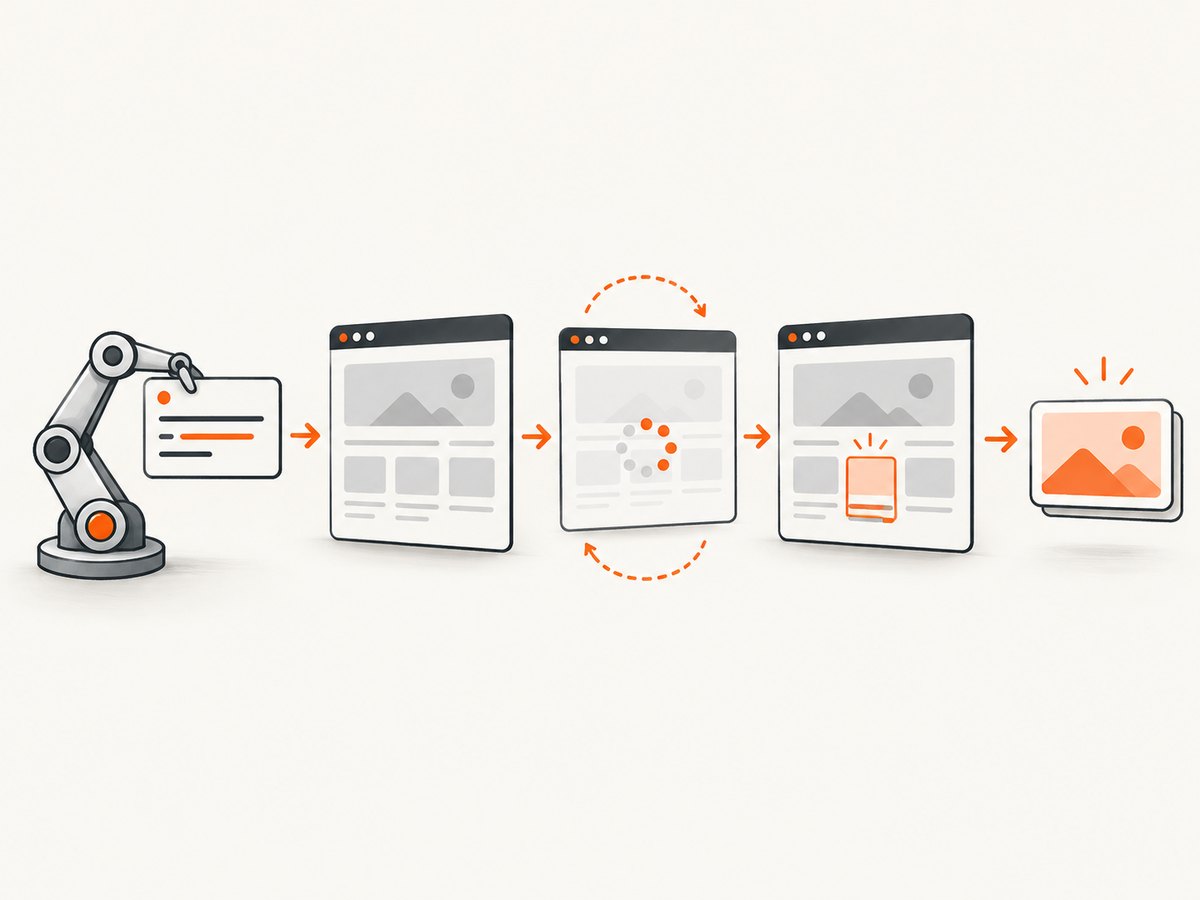
Navigation reaching readyState does not prove that Angular has finished fetching data or replacing nodes. Selenium’s documentation explains that JavaScript can change the page after the initial HTML assets load. Wait for the condition required by the next operation.
| Condition | Use it when |
|---|---|
presence_of_element_located |
The node must exist, even if it is hidden. |
visibility_of_element_located |
You will read or screenshot a visible element. |
element_to_be_clickable |
You will click and need it visible and enabled. |
text_to_be_present_in_element |
Rendering is complete only after specific text appears. |
invisibility_of_element_located |
A loading mask or dialog must disappear. |
wait = WebDriverWait(driver, 20)

wait.until(EC.invisibility_of_element_located(
    (By.CSS_SELECTOR, "[data-testid='loading']")
))
wait.until(EC.text_to_be_present_in_element(
    (By.CSS_SELECTOR, "[data-testid='status']"),
    "Complete"
))
WebDriverWait polls until a condition returns a truthy value. Avoid making fixed sleeps your default: a delay can be too short on a slow run and waste time on a fast one. Do not mix implicit and explicit waits because their timeouts can interact unpredictably.
Capture lists, attributes, and element images
cards = wait.until(lambda d: d.find_elements(
    By.CSS_SELECTOR, "[data-testid='result-card']"
))

for index, card in enumerate(cards, start=1):
    print(index, card.text)
    print("href:", card.get_attribute("href"))

# Save each visible card as its own PNG.
for index, card in enumerate(cards, start=1):
    card.screenshot(f"card-{index}.png")
For a full-page image, Selenium’s viewport screenshot is straightforward, but browser support and full-page behavior vary. If you need a consistent full-page capture, use a browser tool designed for that purpose or a screenshot API.
Interactions before capture
Many Angular elements appear only after a click, route change, or scroll. Wait for the control, perform the action, then locate the target again:
expand = wait.until(EC.element_to_be_clickable(
    (By.CSS_SELECTOR, "button[data-testid='expand-details']")
))
expand.click()

details = wait.until(EC.visibility_of_element_located(
    (By.CSS_SELECTOR, "[data-testid='details-panel']")
))
details.screenshot("details.png")
If an element is below a lazy-loaded region, scroll it into view and wait for the content that should appear:
target = driver.find_element(By.CSS_SELECTOR, "[data-testid='lower-card']")
driver.execute_script(
    "arguments[0].scrollIntoView({block: 'center'});", target
)
wait.until(EC.visibility_of(target))
Why an element cannot be found
Dynamic rendering
Symptom: NoSuchElementException immediately after get().
Cause: Angular has not inserted the node yet.
Fix: Wait for presence or visibility, and wait for a loading indicator to disappear when appropriate.
Wrong selector or wrong DOM state
Symptom: The element is visible manually but Selenium finds nothing.
Cause: The selector targets a source template, generated class, different route, or an iframe.
Fix: Inspect the live DOM, verify the current URL, and switch into the correct iframe before searching:
frame = wait.until(EC.presence_of_element_located(
    (By.CSS_SELECTOR, "iframe[data-testid='embedded-app']")
))
driver.switch_to.frame(frame)
try:
    widget = wait.until(EC.visibility_of_element_located(
        (By.CSS_SELECTOR, "[data-testid='widget']")
    ))
finally:
    driver.switch_to.default_content()
Shadow DOM
Symptom: DevTools shows the node, but a normal document search cannot reach it.
Cause: The node is inside a shadow root.
Fix: Locate the shadow host, obtain its shadow root, and search within that root when the browser and Selenium version support it:
host = wait.until(EC.presence_of_element_located(
    (By.CSS_SELECTOR, "my-widget")
))
shadow = host.shadow_root
button = shadow.find_element(By.CSS_SELECTOR, "button")
Stale element reference
Symptom: StaleElementReferenceException after a click, route transition, or data refresh.
Cause: Angular replaced the DOM node; the old WebElement points to a node that no longer exists.
Fix: Wait for the transition, then run the locator again. Do not keep using the old reference.
save = wait.until(EC.element_to_be_clickable(
    (By.CSS_SELECTOR, "button[data-testid='save']")
))
save.click()
updated = wait.until(EC.visibility_of_element_located(
    (By.CSS_SELECTOR, "[data-testid='saved-result']")
))
Invisible, covered, or disabled element
Symptom: ElementNotInteractableException or ElementClickInterceptedException.
Cause: A modal, cookie banner, animation, or overlay covers the target, or the control is disabled.
Fix: Wait for the overlay to disappear, wait for clickability, scroll into view, and use the application’s normal interaction path. JavaScript clicks should be a last resort because they can bypass real user behavior.
Authentication, bot checks, or network failures
Symptom: The page is blank, redirects to login, or shows a challenge.
Cause: The test session lacks authentication, the environment is blocked, or an API request failed.
Fix: Establish the authenticated session before navigation, capture browser logs and the final URL, and make the test data deterministic. Do not treat a challenge page as the target element.
Locator maintenance checklist
- Use a unique, application-controlled ID when available.
- Otherwise use a concise CSS selector based on semantic attributes.
- Avoid selectors built from Angular’s generated or presentation-only classes.
- Scope searches beneath a stable parent when repeated components exist.
- Keep locator definitions in one place so UI changes require one update.
- Reacquire elements after operations that can re-render their region.
- Use a condition that matches the next action: present, visible, clickable, or text-ready.
Performance and reliability
- Create one driver per test worker and quit it reliably; starting a browser for every element is expensive.
- Use headless mode in CI, but keep a headed reproduction path for visual debugging.
- Set a realistic explicit timeout based on the slowest expected API response, not an arbitrary sleep.
- Capture only the needed element when a full viewport is unnecessary.
- Use deterministic test data and wait on application state instead of elapsed time.
- Record the URL, selector, browser logs, and a failure screenshot when diagnosing intermittent failures.
- Keep retries narrow. Retrying a stale lookup after reacquiring the node can help; retrying every failure can hide real regressions.
Or skip the browser setup
If the goal is a clean image or PDF rather than browser-driven assertions, ScreenshotNeo provides a single request to capture a URL. Its cleanup steps accept cookie or consent banners and remove more than 60 known consent platforms, newsletter popups, and chat widgets before the capture; each cleanup step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response reports the result in X-Page-Verdict and X-Billed headers.
See the ScreenshotNeo API documentation for all options.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
require('node:fs').writeFileSync('shot.webp', Buffer.from(await res.arrayBuffer()));
ScreenshotNeo also supports full-page capture with lazy images loaded, CSS element capture, dark mode, device presets and custom viewports, retina scale, custom CSS and JavaScript, clicks, waits, blocked resource types, headers, cookies, user agents, Authorization, timezone, geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs, webhooks, bulk capture, usage reporting, PDFs, HTML/CSS-to-image, and an MCP server with take_screenshot, get_page_info, and capture_pdf for AI agents.
Free includes 1,000 shots each month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is available on every plan. Create a free ScreenshotNeo account.
FAQ
Do I need an Angular-specific Selenium package?
No. Use Selenium WebDriver’s standard locator and wait APIs against the rendered DOM.
Should I use XPath for every Angular element?
No. Prefer a unique ID or concise CSS selector. XPath is useful for relationships or text-based conditions but can be harder to read and maintain.
Why does find_elements return an empty list?
At that instant no nodes matched. Verify the selector and wait for a representative element before collecting the list.
Why does a saved WebElement become invalid?
Angular may have replaced that DOM node. Locate it again after the update.
Can Selenium capture a component selector such as app-card?
Yes, if that selector is the rendered host element and it is present in the DOM. It does not automatically locate the component’s internal children.


