How to Capture the Visible Content Inside a Div
Learn when to use innerText, textContent, geometry, or a real screenshot to capture what a div contains.
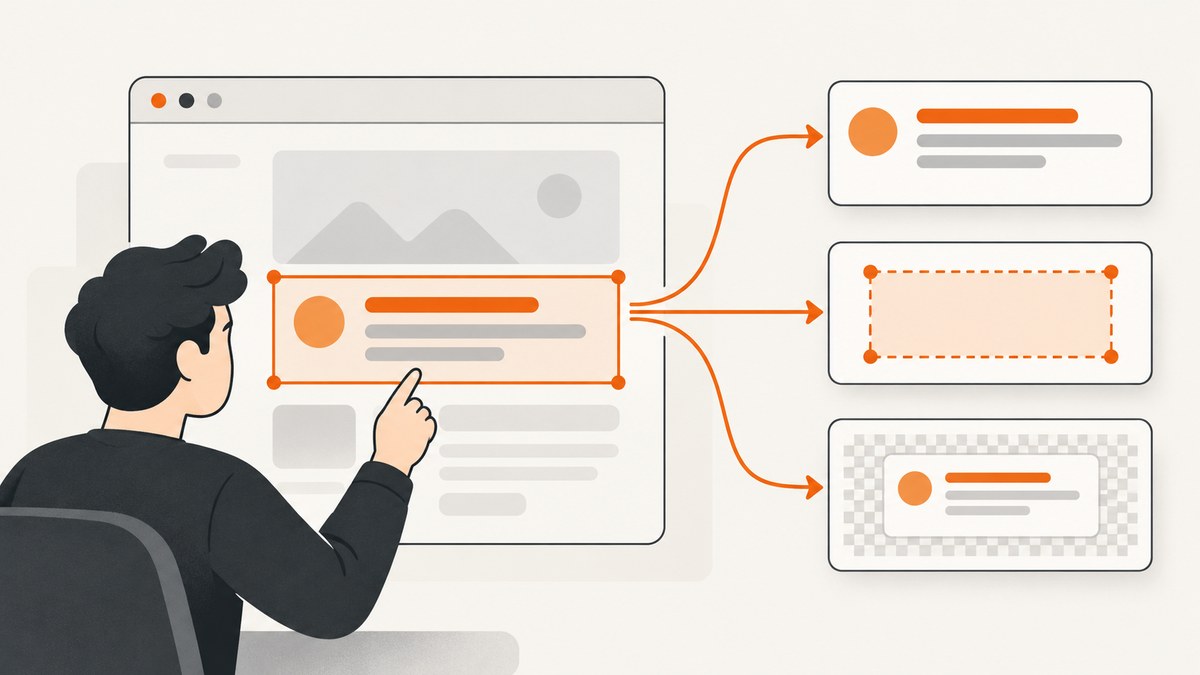
“Capture the visible content inside a div” can mean three different things:
- Read the text a person can see.
- Read every descendant text node, including hidden text.
- Capture the on-screen pixels or measure the region.
For text a user can see, use innerText:
const div = document.querySelector('#my-div');
const visibleText = div?.innerText ?? '';
console.log(visibleText);
innerText follows rendered appearance and approximates selecting the element and copying it. If you need image bytes, use a browser screenshot operation or a screenshot API; DOM text properties do not create an image.
1. Choose the operation that matches your goal
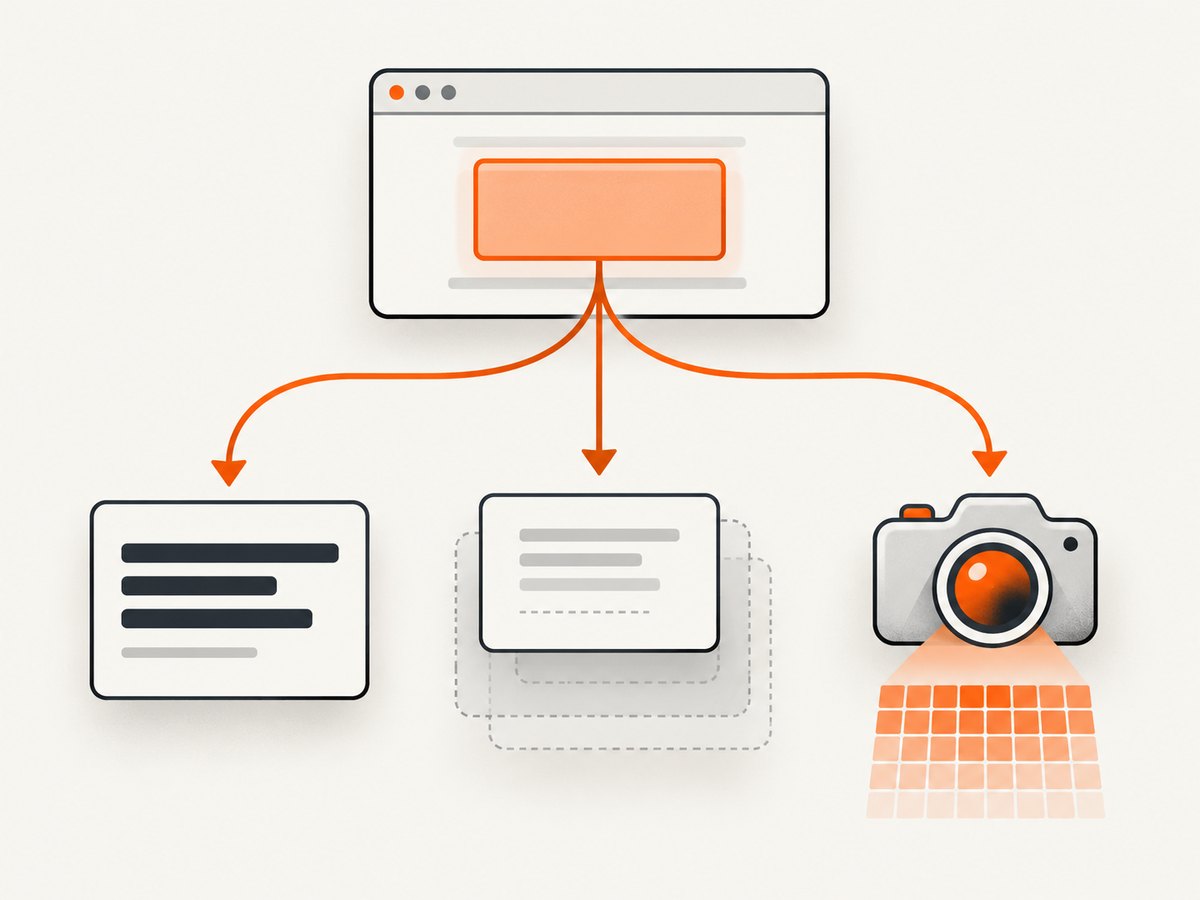
| Goal | Use | What it returns | Main caveat |
|---|---|---|---|
| Text visible to a user | innerText |
Rendered text from the element and descendants | Reading it can trigger layout work |
| All descendant text | textContent |
Concatenated text, including hidden descendants | Includes text in hidden, script, and style nodes |
| Markup | innerHTML |
An HTML string | Not plain visible text; inserting it unsafely can create XSS |
| Element box | getBoundingClientRect() |
Position and dimensions of the border box | Geometry is not text or pixels |
| Content range box | Range.getBoundingClientRect() |
A DOMRect enclosing selected contents | Measures the range; it does not make an image |
| Actual screenshot | Browser screenshot API or rendering service | PNG, JPEG, WebP, or PDF bytes | Requires a capture-capable browser or service |
MDN describes innerText as the rendered text content of a node and its descendants, while textContent represents the text content without modeling rendered visibility: innerText and textContent.
2. Read user-visible text with innerText
Use a stable selector and handle a missing element explicitly:
function getVisibleText(selector) {
  const element = document.querySelector(selector);
  if (!element) {
    throw new Error(`No element matched ${selector}`);
  }
  return element.innerText;
}

const text = getVisibleText('#my-div');
console.log(text);
innerText respects normal CSS rendering. Text inside an element with display: none is omitted. It also reflects rendered line breaks more closely than textContent.
Normalize whitespace when storing or comparing text
const raw = document.querySelector('#my-div')?.innerText ?? '';
const normalized = raw.replace(/\\s+/g, ' ').trim();
Keep the raw value when line breaks carry meaning, such as addresses, code samples, or poetry. Normalize only at the boundary where your application needs a canonical string.
3. Use textContent when hidden text is intentional
textContent is the right choice for indexing, parsing templates, or serializing all descendant text:
const div = document.querySelector('#my-div');
const allText = div?.textContent ?? '';
console.log(allText);
Unlike innerText, this does not consult CSS visibility. It can include text from hidden descendants and from script or style elements. Do not use it as a substitute for “what a visitor can read.”
Example showing the difference
<div id="my-div">
  Visible text
  <span hidden>Template text</span>
</div>

<script>
const div = document.querySelector('#my-div');
console.log(div.innerText);   // Visible text
console.log(div.textContent); // Visible text Template text
</script>
4. Measure the div or its text range
When “capture” means finding the on-screen region, use geometry APIs.
Measure the element box
const div = document.querySelector('#my-div');
if (!div) throw new Error('Missing #my-div');

const rect = div.getBoundingClientRect();
const box = {
  left: rect.left,
  top: rect.top,
  width: rect.width,
  height: rect.height,
  right: rect.right,
  bottom: rect.bottom
};
console.log(box);
The coordinates are relative to the viewport. Add window.scrollX and window.scrollY for document coordinates. The rectangle includes the element’s border box, including areas that may contain padding or empty space.
Measure the union of the contents
const div = document.querySelector('#my-div');
if (!div) throw new Error('Missing #my-div');

const range = document.createRange();
range.selectNodeContents(div);
const textRect = range.getBoundingClientRect();
console.log({
  left: textRect.left,
  top: textRect.top,
  width: textRect.width,
  height: textRect.height
});
Range.getBoundingClientRect() returns a DOMRect enclosing the union of the range’s element rectangles: MDN Range.getBoundingClientRect(). It tells you where the selected contents are, not what they look like as pixels.
5. Capture pixels when you need an image
Text extraction and geometry cannot capture fonts, colors, images, borders, shadows, or the exact visual state. Use a browser automation library when the page is under your control.
Playwright example: screenshot one div
import { chromium } from 'playwright';

const browser = await chromium.launch();
const page = await browser.newPage({ viewport: { width: 1440, height: 900 } });
await page.goto('https://example.com', { waitUntil: 'networkidle' });
await page.locator('#my-div').screenshot({ path: 'div.png' });
await browser.close();
The locator screenshot captures the element, including content that extends beyond the viewport when the automation library supports element screenshots. For a full-page image, capture the page instead:
await page.screenshot({ path: 'page.png', fullPage: true });Capture only the visible viewport portion
const div = page.locator('#my-div');
await div.scrollIntoViewIfNeeded();
await div.screenshot({ path: 'visible-div.png' });
If you need a precise crop from a page screenshot, first read the element rectangle in the page, then pass a clip rectangle to the screenshot method. Account for device scale factor and scrolling when converting CSS pixels to image pixels.
6. Make extraction reliable
Wait for dynamic content
Read or capture only after the application has rendered the target:
await page.waitForSelector('#my-div', { state: 'visible' });
const text = await page.locator('#my-div').innerText();
For data loaded after the element appears, wait for a meaningful child, a loading indicator to disappear, a known network response, or a short bounded delay. Avoid indefinite sleeps.
Handle iframes and shadow DOM
A selector in the top document cannot reach an element inside an iframe. Select the frame first:
const frame = page.frameLocator('iframe[data-widget]');
const text = await frame.locator('#my-div').innerText();
For open shadow roots, use a locator that pierces the shadow boundary where your automation library supports it. Closed shadow roots are not directly queryable from page JavaScript.
Control visibility deliberately
Visibility can change with media queries, animation, collapsed panels, and user state. Set the viewport, color scheme, locale, and authentication state explicitly before reading innerText or taking a screenshot.
7. Troubleshooting
| Symptom | Cause | Fix |
|---|---|---|
null or “cannot read properties of null” |
The selector matched nothing or ran before the DOM was ready | Check the selector and wait for the element |
| Hidden text appears | You used textContent |
Use innerText for rendered text |
| Expected text is missing | The node is hidden, collapsed, inside an iframe, or rendered later | Make it visible, select the correct frame, and wait for content |
| Whitespace differs between runs | Responsive wrapping, fonts, or rendering state changed | Fix viewport and fonts; normalize whitespace only if appropriate |
| Screenshot is blank | Capture ran before navigation or rendering completed | Wait for navigation and the target selector; check for bot checks and errors |
| Element screenshot is clipped | Overflow, transforms, or a library’s element-capture behavior | Scroll into view, inspect the rectangle, and use a clipped page screenshot when needed |
| Reading text is slow | innerText may force layout |
Read once, cache the result, and avoid polling in a tight loop |
8. Performance, reliability, and cost
- Prefer one read: store
innerTextortextContentinstead of repeatedly reading it during a loop. - Scope selectors: query the target div directly rather than scanning the entire document repeatedly.
- Batch work: if you need several fields, run one page evaluation that returns them together.
- Stabilize rendering: use fixed viewport, fonts, timezone, and data state for reproducible screenshots.
- Bound waits: set navigation and selector timeouts so a failed page does not consume a worker indefinitely.
- Browser cost: self-hosted capture consumes CPU, memory, and browser startup time; reuse browser processes where safe and close contexts.
For text-only extraction, a browser may be unnecessary if the source HTML is already available. For pixels, layout, lazy images, and JavaScript-rendered pages, a real browser render is required.
9. Or skip the browser setup
ScreenshotNeo provides a one-request website screenshot API. It can capture a specific element by CSS selector, full pages with lazy images loaded, custom viewports and device presets, dark mode, retina scale, custom CSS and JavaScript, waits, blocking rules, headers, cookies, user agents, timezone and geolocation, image resizing, caching, signed links, PDFs, async jobs, and bulk capture. See the ScreenshotNeo documentation for the complete option list.
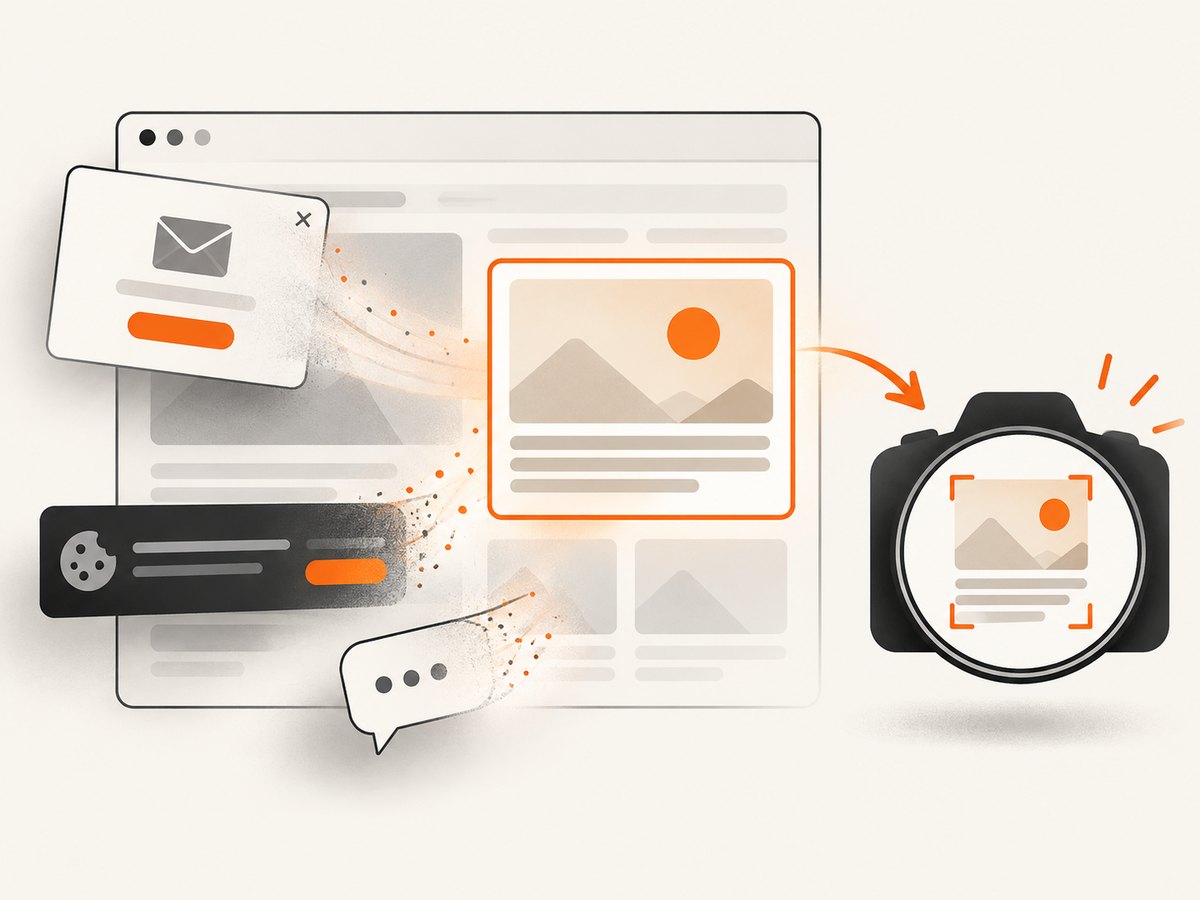
Use the element selector option when you need the pixels inside one div. The API returns PNG, JPEG, WebP, or PDF according to the request.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://example.com \
  -o div.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://example.com"},
    timeout=90,
)
r.raise_for_status()
open("div.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const image = Buffer.from(await res.arrayBuffer());
await import('node:fs/promises').then(fs => fs.writeFile('div.webp', image));
ScreenshotNeo accepts the parameter names used by other screenshot APIs, which helps when switching. Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, timeouts, failed loads, and cache hits cost nothing, and the response reports the result with X-Page-Verdict and X-Billed headers. Its MCP server includes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients.
The Free plan includes 1,000 shots per month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free. Start with the free ScreenshotNeo account.
10. FAQ
Does innerText return only text currently visible in the viewport?
No. It models rendered visibility in the element’s subtree. Content below the fold can still be included if it is rendered and not hidden by CSS.
Can I use innerHTML to capture visible content?
innerHTML returns markup, not visible plain text or pixels. Use it only when you explicitly need the HTML structure and handle inserted markup safely.
How do I capture text selected by the user?
Use window.getSelection() for the user’s selection. Use a Range when your code defines the content programmatically.
Why does a screenshot differ from innerText?
A screenshot includes visual details such as images, icons, spacing, clipping, and colors. innerText is only the rendered text representation.


