How to Collect Twitter Data for Sentiment Analysis
A complete guide to querying X posts, handling pagination and limits, preparing text, and building a defensible sentiment dataset.
Short answer: collect public X (formerly Twitter) posts through the official X API, define a precise query and time window, retrieve every response page, save collection metadata, then clean and validate the text before sentiment classification. A keyword result is a query-defined sample, not a complete measure of public opinion. Protected, deleted, and region-withheld posts may be absent, and access, quotas, pricing, and policies can change.
This guide shows a reproducible workflow for recent or historical collection, with Python and raw HTTP examples, pagination, filtering, storage, retries, preprocessing, quality checks, and interpretation limits.
1. Define the population before writing code
Write a one-paragraph collection specification first. State:
- The topic and vocabulary you intend to capture.
- Language or languages.
- Start and end times in UTC.
- Whether replies and reposts are included.
- Whether you need posts about a topic, posts by selected accounts, or both.
- The fields required for analysis and the retention rules permitted by X policy.
A query is an inclusion rule. It can miss people who use different words and include posts where a term has another meaning. Keep the query and inclusion rules unchanged for a time-series comparison, and record every revision.
Useful search operators
| Goal | Example |
|---|---|
| Exact phrase | "electric vehicle" |
| Hashtag | #ElectricVehicles |
| Posts from an account | from:example |
| Replies to an account | to:example |
| Language | lang:en |
| Exclude reposts | -is:retweet |
| Exclude replies | -is:reply |
| Combine terms | ("electric vehicle" OR EV) lang:en -is:retweet |
Check the current operator reference before production use; syntax and access requirements can change.
2. Choose recent or full-archive search
X documents two main search windows. Recent search covers approximately the last seven days. Full-archive search reaches back to March 2006, but the official quickstart says it requires Self-serve or Enterprise access. Confirm your account’s eligibility, current plan, quota, and price before promising historical coverage.
For a live campaign monitor, recent search is usually sufficient. For a historical comparison, use full archive only after verifying access and documenting the exact dates. Send ISO 8601 UTC boundaries such as 2026-01-01T00:00:00Z and 2026-02-01T00:00:00Z.
3. Register an application and protect credentials
- Create a developer project and app in X’s developer portal.
- Request the access level that supports your query and date range.
- Generate a Bearer Token for application-only search.
- Store the token in an environment variable or secret manager.
- Review the developer policy and current storage, redistribution, and research rules.
Never commit a token to source control or include it in notebooks that will be shared. Rotate it if it appears in logs.
4. Retrieve every page with Python
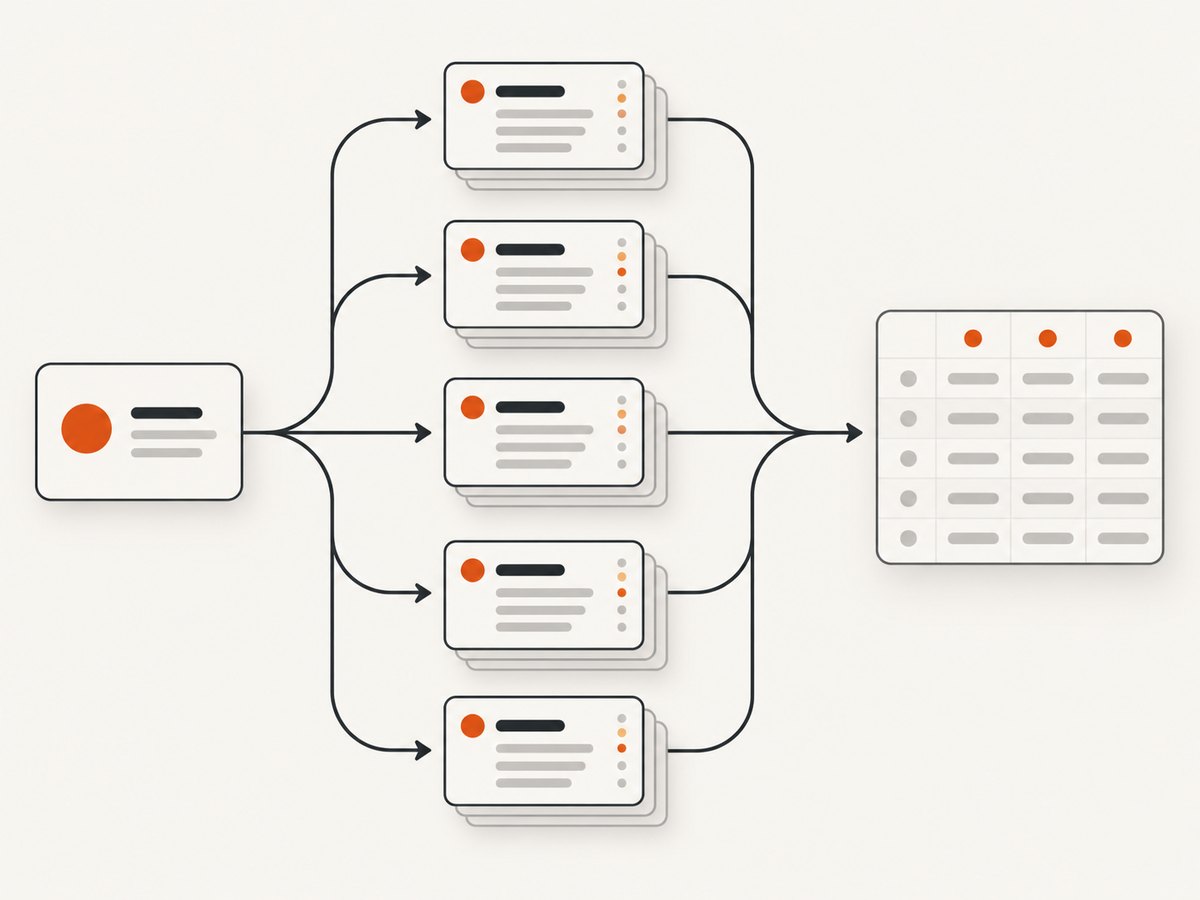
The following client uses the documented search endpoint and manually follows next_token. It requests up to 100 posts per page, writes newline-delimited JSON, and records the query and collection time.
import json
import os
import time
from datetime import datetime, timezone

import requests

TOKEN = os.environ["X_BEARER_TOKEN"]
URL = "https://api.x.com/2/tweets/search/recent"
QUERY = '("electric vehicle" OR EV) lang:en -is:retweet -is:reply'
START = "2026-09-20T00:00:00Z"
END = "2026-09-30T00:00:00Z"

params = {
    "query": QUERY,
    "start_time": START,
    "end_time": END,
    "max_results": 100,
    "tweet.fields": "id,text,created_at,lang,author_id,conversation_id,public_metrics,context_annotations",
    "expansions": "author_id",
    "user.fields": "id,username,verified,public_metrics",
}
headers = {"Authorization": f"Bearer {TOKEN}"}

with open("x_posts.ndjson", "w", encoding="utf-8") as out:
    page = 0
    while True:
        page += 1
        response = requests.get(URL, headers=headers, params=params, timeout=60)
        if response.status_code == 429:
            retry_after = int(response.headers.get("retry-after", "60"))
            time.sleep(min(retry_after, 900))
            continue
        response.raise_for_status()
        payload = response.json()

        metadata = {
            "collected_at": datetime.now(timezone.utc).isoformat(),
            "query": QUERY,
            "start_time": START,
            "end_time": END,
            "page": page,
            "result_count": payload.get("meta", {}).get("result_count", 0),
        }
        for post in payload.get("data", []):
            out.write(json.dumps({"post": post, "collection": metadata}, ensure_ascii=False) + "\n")

        token = payload.get("meta", {}).get("next_token")
        if not token:
            break
        params["next_token"] = token

print("Collection complete")
For full archive, change the endpoint to the full-archive route documented in the official quickstart, keep the UTC boundaries, and verify that your account is entitled to use it. The Python XDK can also iterate pages for you, but you still need to save the query, dates, response metadata, and errors.
5. Make the same request with cURL
export X_BEARER_TOKEN='YOUR_BEARER_TOKEN'
curl --get 'https://api.x.com/2/tweets/search/recent' \\
  --header "Authorization: Bearer $X_BEARER_TOKEN" \\
  --data-urlencode 'query=("electric vehicle" OR EV) lang:en -is:retweet -is:reply' \\
  --data-urlencode 'start_time=2026-09-20T00:00:00Z' \\
  --data-urlencode 'end_time=2026-09-30T00:00:00Z' \\
  --data-urlencode 'max_results=100' \\
  --data-urlencode 'tweet.fields=id,text,created_at,lang,author_id,public_metrics'
Inspect the JSON meta.next_token. If it exists, repeat the request with next_token=... until it is absent. Do not count one successful response as the complete dataset.
6. Node.js pagination example
const token = process.env.X_BEARER_TOKEN;
const endpoint = 'https://api.x.com/2/tweets/search/recent';
const query = '("electric vehicle" OR EV) lang:en -is:retweet -is:reply';
let nextToken;

for (;;) {
  const params = new URLSearchParams({
    query,
    start_time: '2026-09-20T00:00:00Z',
    end_time: '2026-09-30T00:00:00Z',
    max_results: '100',
    'tweet.fields': 'id,text,created_at,lang,author_id,public_metrics'
  });
  if (nextToken) params.set('next_token', nextToken);

  const response = await fetch(`${endpoint}?${params}`, {
    headers: { Authorization: `Bearer ${token}` }
  });
  if (response.status === 429) {
    const seconds = Number(response.headers.get('retry-after') || 60);
    await new Promise(resolve => setTimeout(resolve, Math.min(seconds, 900) * 1000));
    continue;
  }
  if (!response.ok) throw new Error(`${response.status}: ${await response.text()}`);
  const page = await response.json();
  for (const post of page.data || []) console.log(JSON.stringify(post));
  nextToken = page.meta?.next_token;
  if (!nextToken) break;
}
7. Save metadata for reproducibility
Store a manifest beside the posts. Include:
- Query text and the operator reference version you used.
- Endpoint (recent or full archive), start and end times, and timezone.
- Collection start and end timestamps.
- Requested fields, page size, page count, result count, and next-token errors.
- Application identifier and access tier, without storing the Bearer Token.
- Code version, dependency versions, and any post-collection exclusions.
Keep post IDs and timestamps needed for your analysis, and follow X’s current policy for content storage, deletion handling, and redistribution. A reproducible manifest lets another researcher understand exactly what “the dataset” means.
8. Prepare text for sentiment analysis
Define the unit and deduplicate
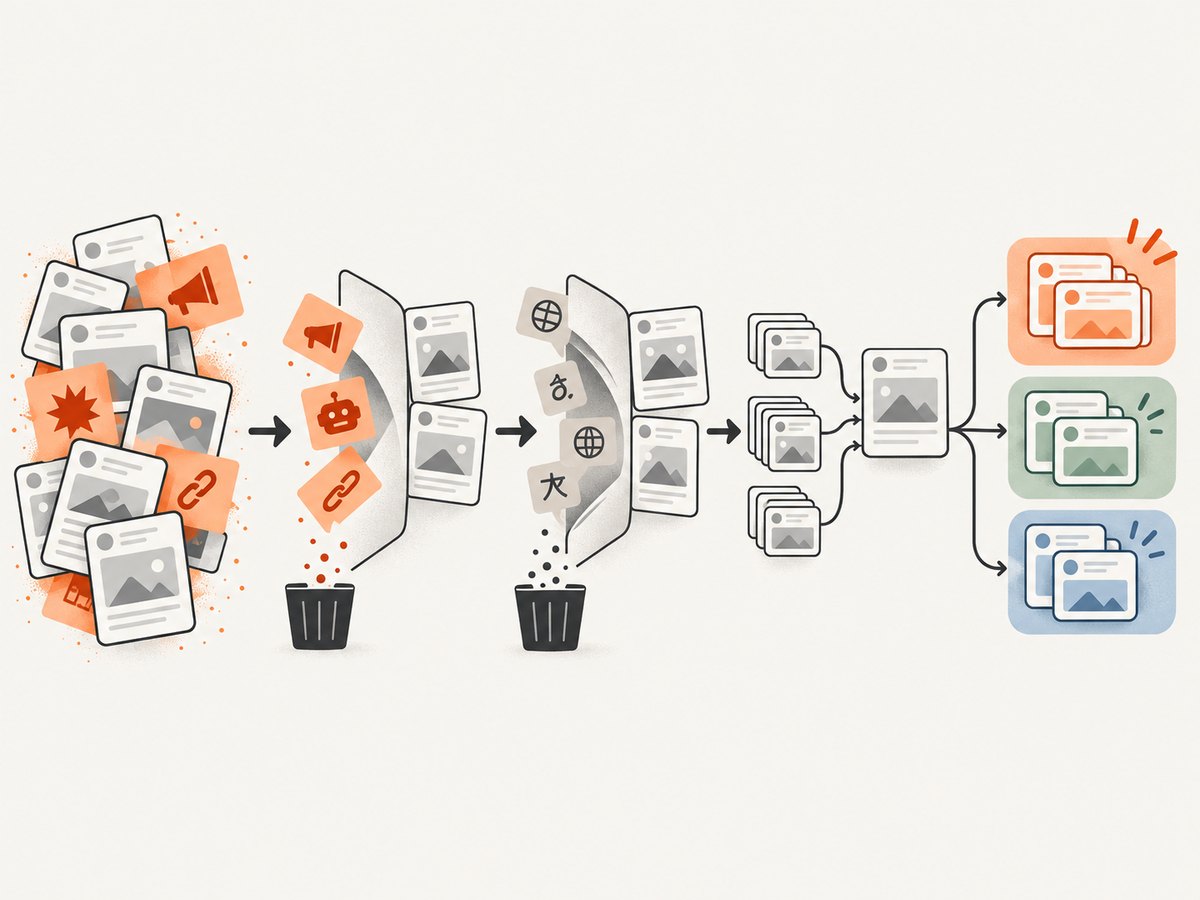
Usually one post is one classification unit. Decide whether quoted posts, replies, and reposts are separate observations. Deduplicate by post ID; do not silently collapse near-identical text if repetition is part of the phenomenon you are measuring.
Normalize without erasing signal
Preserve the original text. Create a second analysis field where you can normalize URLs, mentions, whitespace, and repeated characters. Keep emojis, hashtags, capitalization, punctuation, and negation available because they can carry sentiment. Record every transformation in code.
Handle language and context
The lang field is a useful filter, not a perfect language diagnosis. Multilingual collections may require language-specific models or separate evaluation. Sarcasm, slang, quoted text, domain terminology, and replies that depend on the parent post can all reduce classifier accuracy. If context is required, retain conversation identifiers and define how much surrounding context is retrieved.
Validate labels
Model output is not ground truth. Sample posts for human annotation, measure agreement, inspect errors by language and topic, and report how the classifier handles negation, sarcasm, and ambiguous cases. If you compare models, evaluate them on a held-out sample from your own query rather than relying on a benchmark from another domain.
9. Coverage, bias, and interpretation
Describe results as “posts matching this query and available through this API during this period.” Do not claim that they represent all X users or public opinion. Posts from protected accounts, deleted posts, and content withheld in some regions may not be returned. Search and usage caps can also truncate a collection.
Historical evidence about the former Academic API cannot establish current X API completeness. A 2022 study found evidence that the former service could produce almost complete samples for many search terms, but that finding does not prove current coverage or representativeness. A 2024 literature review reported 27,453 studies across 7,432 venues, 1,303,142 citations, and 14 disciplines; those figures describe its literature search, not the size or quality of a sentiment dataset.
For comparisons over time, keep query, language, exclusions, and pagination logic constant. Report missing pages, rate-limit pauses, and any policy-driven deletions. Treat sudden volume changes as potentially caused by vocabulary, access, or platform changes as well as genuine sentiment shifts.
10. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| 401 Unauthorized | Missing, expired, or malformed Bearer Token. | Set the token in the environment, send Authorization: Bearer ..., and regenerate credentials if needed. |
| 403 Forbidden | Your app or plan lacks the requested endpoint or archive access. | Check current eligibility and request the required access level. |
| 400 Bad Request | Invalid operator, date format, field, or query length. | Reduce the query, use ISO 8601 UTC, and validate operators against current documentation. |
| 429 Too Many Requests | Rate or usage cap exceeded. | Honor retry-after, use exponential backoff with jitter, and reduce concurrency. The error guide documents this response. |
| Only one page returned | next_token was ignored. |
Loop until meta.next_token is absent and log page counts. |
| Fewer posts than expected | Query terms, exclusions, caps, protected/deleted posts, or regional withholding. | Inspect the query, metadata, date window, and response errors; do not infer completeness from HTTP 200. |
| Sentiment looks wrong | Sarcasm, slang, negation, emojis, multilingual text, or missing conversation context. | Annotate an in-domain sample, preserve text signals, and evaluate or fine-tune an appropriate model. |
11. Performance, reliability, and cost
- Performance: request the largest permitted page, select only fields you need, and write pages incrementally so a process failure does not lose earlier results.
- Reliability: make retries idempotent, persist the last successful page, add bounded exponential backoff, and checkpoint the manifest.
- Parallelism: partition independent date windows only when your quota permits it. Concurrent workers can trigger 429 responses and complicate deduplication.
- Cost: X access tiers, quotas, and archive eligibility are volatile. Check the current product pages for your account and region instead of copying historical prices.
- Reproducibility: pin dependencies, keep UTC boundaries, hash exported files, and save the exact query and code revision.
Or skip the browser setup
If your workflow also needs screenshots of posts, dashboards, or result pages, ScreenshotNeo provides a single screenshot API request. It accepts consent banners like a visitor and removes more than 60 known consent platforms, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing status. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
See the ScreenshotNeo API documentation for all options, including full-page capture, CSS selectors, custom headers and cookies, JavaScript, waits, blocking rules, caching, signed links, asynchronous jobs, bulk capture, and PDF output.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);The free plan includes 1,000 screenshots each month with no card. Paid plans start at $5 for 3,000 shots, and every feature is available on every plan. Create a free ScreenshotNeo account.
FAQ
Can I collect the entire history of X?
Only if your account has current full-archive eligibility and your query, quota, and policy permissions allow it. Verify access before designing the study.
How many posts should I collect?
There is no universal number. Determine it from the question, time resolution, expected volume, model validation needs, and available quota. Report the rule you used.
Should reposts and replies be removed?
That is a study decision. Exclude them when measuring original reactions, or retain them when diffusion and conversation are the subject. Encode the choice in the query and manifest.
Is API sentiment representative of public opinion?
No. It represents posts matching your query and available through your access during collection. Explain vocabulary, language, account, deletion, regional, and access biases.
Can I share the collected text?
Check X’s current developer and research policies before storing or redistributing content. When required, share identifiers and reproducible procedures rather than unrestricted text exports.


