How to Combine Multiple HTML Pages Into One Document in C#
Parse multiple HTML files, merge their body content safely in C#, handle IDs, assets and scripts, then troubleshoot common composition errors.
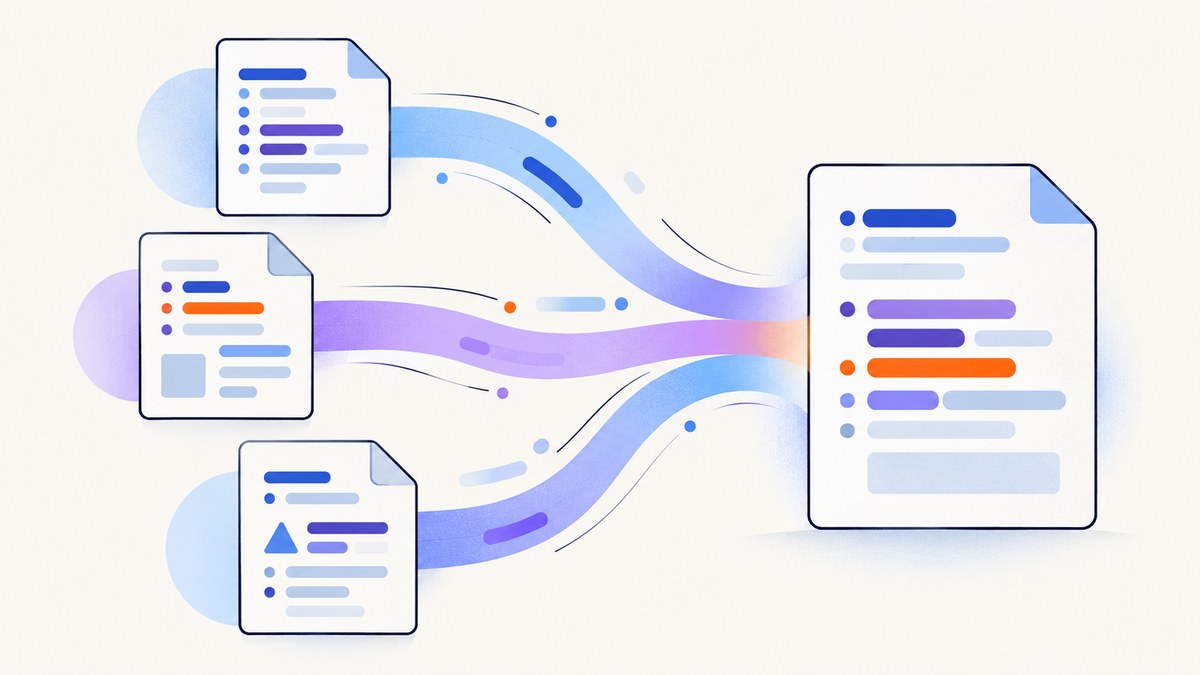
Short answer: parse each HTML page, create one destination document, and append cloned content from each source body in order. Do not concatenate complete <html>, <head> and <body> strings, because that creates duplicate document roots and makes styles, scripts, IDs and relative URLs ambiguous.
1. Choose a merge policy first
Before writing code, decide what the output document should contain:
- Input type: complete HTML documents, body fragments, or a mixture.
- Order: the sequence in which source pages appear in the result.
- Head content: title, metadata, stylesheets, scripts, base URL and favicon.
- Body content: all body children, selected elements, or a wrapper around each page.
- Collisions: duplicate
idattributes, named forms, anchors and CSS selectors. - Resources: how relative images, stylesheets, fonts and links should resolve.
HTML has separate document and fragment parsing algorithms, so parse complete pages as documents and use fragment-oriented parsing when inserting markup into a particular element context. See the WHATWG HTML parsing specification.
2. Complete C# example with HtmlAgilityPack
HtmlAgilityPack can load HTML from files or strings and lets you select and manipulate nodes. Install it with:
dotnet add package HtmlAgilityPackThe following console program accepts several input files, copies their body children into one output document, and writes combined.html. Each source page is wrapped in a section so that page boundaries remain visible and can be styled independently.
using HtmlAgilityPack;

if (args.Length < 2)
{
    Console.Error.WriteLine("Usage: dotnet run -- output.html input1.html input2.html ...");
    return 1;
}

var outputPath = args[0];
var inputPaths = args[1..];

var output = new HtmlDocument();
output.LoadHtml("<!doctype html><html><head><meta charset=\\"utf-8\\"><title>Combined document</title></head><body></body></html>");

var outputBody = output.DocumentNode.SelectSingleNode("/html/body")
    ?? throw new InvalidOperationException("Output template has no body element.");

foreach (var inputPath in inputPaths)
{
    var source = new HtmlDocument
    {
        OptionFixNestedTags = true,
        OptionAutoCloseOnEnd = true
    };
    source.Load(inputPath);

    var sourceBody = source.DocumentNode.SelectSingleNode("/html/body");
    var pageSection = output.CreateElement("section");
    pageSection.SetAttributeValue("data-source", Path.GetFileName(inputPath));

    if (sourceBody is not null)
    {
        foreach (var child in sourceBody.ChildNodes)
        {
            pageSection.AppendChild(child.CloneNode(deep: true));
        }
    }
    else
    {
        // Treat a document without a body as a fragment.
        foreach (var child in source.DocumentNode.ChildNodes)
        {
            if (child.Name is not "html" and not "head")
            {
                pageSection.AppendChild(child.CloneNode(deep: true));
            }
        }
    }

    outputBody.AppendChild(pageSection);
}

output.Save(outputPath);
Console.WriteLine($"Wrote {outputPath}");
return 0;
This approach follows HtmlAgilityPack’s documented file/string parsing and node manipulation APIs. Cloning matters: it gives the destination document its own node tree instead of trying to move nodes that still belong to a source document.
Merge strings instead of files
static HtmlDocument Parse(string html)
{
    var document = new HtmlDocument
    {
        OptionFixNestedTags = true,
        OptionAutoCloseOnEnd = true
    };
    document.LoadHtml(html);
    return document;
}

var source = Parse("<html><body><h2>Second page</h2><p>Content</p></body></html>");
var body = source.DocumentNode.SelectSingleNode("//body");
3. AngleSharp alternative for HTML5 parsing
AngleSharp builds a standards-oriented .NET DOM and supports document and fragment parsing. It is a good choice when browser-like HTML5 tree construction, CSS selectors or fragment insertion are central to your application.
dotnet add package AngleSharpusing AngleSharp.Html.Parser;
var parser = new HtmlParser();
var document = parser.ParseDocument("<html><body><p>Page one</p></body></html>");
var body = document.Body ?? throw new InvalidOperationException("Missing body");
// Parse a fragment when inserting markup into a known context.
var fragment = parser.ParseFragment("<p>Page two</p>", body);
foreach (var node in fragment)
{
body.AppendChild(node);
}
Console.WriteLine(document.DocumentElement.OuterHtml);Check the exact API for the AngleSharp version used by your project. Its documentation includes DOM manipulation examples and fragment parsing guidance.
4. Handling complete pages and fragments
| Input | Recommended treatment |
|---|---|
| Complete document | Parse it, select body, clone its children. |
| Body fragment | Parse as a fragment or load it and copy top-level nodes. |
| Mixed inputs | Detect html/body; use the body when present, otherwise treat nodes as a fragment. |
| Page with meaningful head assets | Extract selected links, style blocks and metadata into the destination head using an explicit deduplication policy. |
Do not copy every source head blindly. Multiple titles, canonical links, viewport tags and scripts can conflict. A practical policy is one destination title and charset, deduplicated stylesheet URLs, and scripts included only when you know they are safe to run together.
5. IDs, links and resource URLs
Duplicate IDs
Duplicate IDs break getElementById, fragment links and CSS selectors. Before appending each page, scan its elements and prefix IDs:
static void PrefixIds(HtmlNode root, string prefix)
{
    var elements = root.SelectNodes(".//*[@id]");
    if (elements is null) return;

    foreach (var element in elements)
    {
        var id = element.GetAttributeValue("id", "");
        if (!string.IsNullOrWhiteSpace(id))
            element.SetAttributeValue("id", $"{prefix}-{id}");
    }
}
If scripts refer to IDs by literal strings, update those references too or isolate the page in an iframe instead of merging it into one DOM.
Relative URLs and <base>
After composition, relative href, src and url() values resolve against the output document’s URL. A source page’s <base> element does not automatically preserve the intended origin after its content moves. Options include:
- Rewrite relative URLs to absolute URLs before merging.
- Choose one destination
<base>URL and remove conflicting source bases. - Serve the combined file from a location whose URL hierarchy matches the resources.
6. Styles and scripts
- Styles: duplicate class names can change appearance when style blocks are combined. Scope each page under a wrapper such as
[data-source="page-a.html"]where practical. - Scripts: scripts may execute twice, depend on page-specific globals, or query elements that now coexist with another page. Prefer extracting static content and omitting scripts unless execution is required.
- Events: inline handlers and delegated listeners can target duplicate selectors. Rebind them after composition if needed.
- Forms: give forms unique names and IDs, and verify that submit actions still point to the intended endpoint.
7. Preserving page boundaries
Wrapping each source in a section makes ordering and styling explicit:
<section data-source="page-a.html">...</section>
<section data-source="page-b.html">...</section>
For print output, add CSS such as break-before: page to each section after the first. For interactive pages that must retain independent JavaScript state, use iframes instead of combining their DOM trees.
8. Validate the result
- Open the generated file in the same consumer that will display or convert it.
- Check that there is exactly one
html,headandbody. - Search for duplicate IDs and broken relative URLs.
- Inspect browser console errors for scripts and resource loading.
- Verify forms, anchors, images, fonts and print pagination.
- Compare the output with a known-good fixture containing malformed markup and empty bodies.
9. Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| Only the first page appears | Each source document was assigned as the output instead of appending nodes. | Create one destination body and append cloned children for every input. |
| Nested or duplicated body tags | Complete documents were concatenated as strings. | Parse documents and copy body content only. |
| Styles from one page affect another | Global selectors or duplicate class names. | Scope styles, rename classes, or keep pages in iframes. |
| Images or CSS return 404 | Relative URLs changed base context. | Rewrite URLs, set one deliberate base URL, or serve from a compatible path. |
| JavaScript runs twice | Scripts were copied from every head. | Deduplicate scripts and load only the bundles required by the merged document. |
| Null body selection | Input is a fragment or malformed document. | Use a fragment fallback and test for a missing body. |
| Duplicate anchor targets | Repeated IDs across pages. | Prefix IDs and update internal links. |
| Output encoding is wrong | No explicit charset or inconsistent source encoding. | Set UTF-8 in the destination head and load files with the correct encoding. |
10. Performance, reliability and cost
- Memory: parsing and cloning creates multiple DOM trees. For very large pages, process inputs sequentially and release source documents after cloning.
- Throughput: avoid repeated serialization inside the loop; serialize once after all pages are appended.
- Reliability: keep deterministic input ordering, record source filenames, and fail clearly when an input cannot be read.
- Security: treat HTML as untrusted. Sanitise user-provided markup and avoid executing copied scripts unless the content is trusted.
- Cost: local parsing has no API charge, but browser rendering, PDF conversion or screenshot capture adds CPU, memory and service costs.
11. Or skip the browser setup
If your goal is to capture the resulting pages as images or PDFs rather than build a DOM yourself, ScreenshotNeo provides a single screenshot API request. See the ScreenshotNeo API documentation for request options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo removes cookie banners, newsletter popups and chat widgets before capture. Bot checks, blank pages and failed loads are never billed, and response headers report the page verdict and billing result. Its MCP server lets AI agents use take_screenshot, get_page_info and capture_pdf. The Free plan includes 1,000 screenshots each month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
12. FAQ
Can I merge pages by string concatenation?
Only when the inputs are known-safe fragments. Complete documents should be parsed and composed through a DOM.
Should I use AngleSharp or HtmlAgilityPack?
Use AngleSharp when standards-oriented HTML5 and fragment parsing are priorities. Use HtmlAgilityPack for straightforward loading and node manipulation or when it is already part of your application.
How do I keep each page’s JavaScript isolated?
Use an iframe per page. A single merged DOM shares globals, IDs, styles and event targets.
Can a parser render JavaScript-generated content?
No. These libraries parse and manipulate markup; they do not reproduce a browser’s full rendering and script execution environment. Use a browser renderer when content appears only after JavaScript runs.


