Making Concurrent Requests in Python to Scrape Multiple Pages
Fetch multiple pages concurrently in Python with thread pools or asyncio. Learn to limit load, handle failures, preserve result order, and tune timeouts.
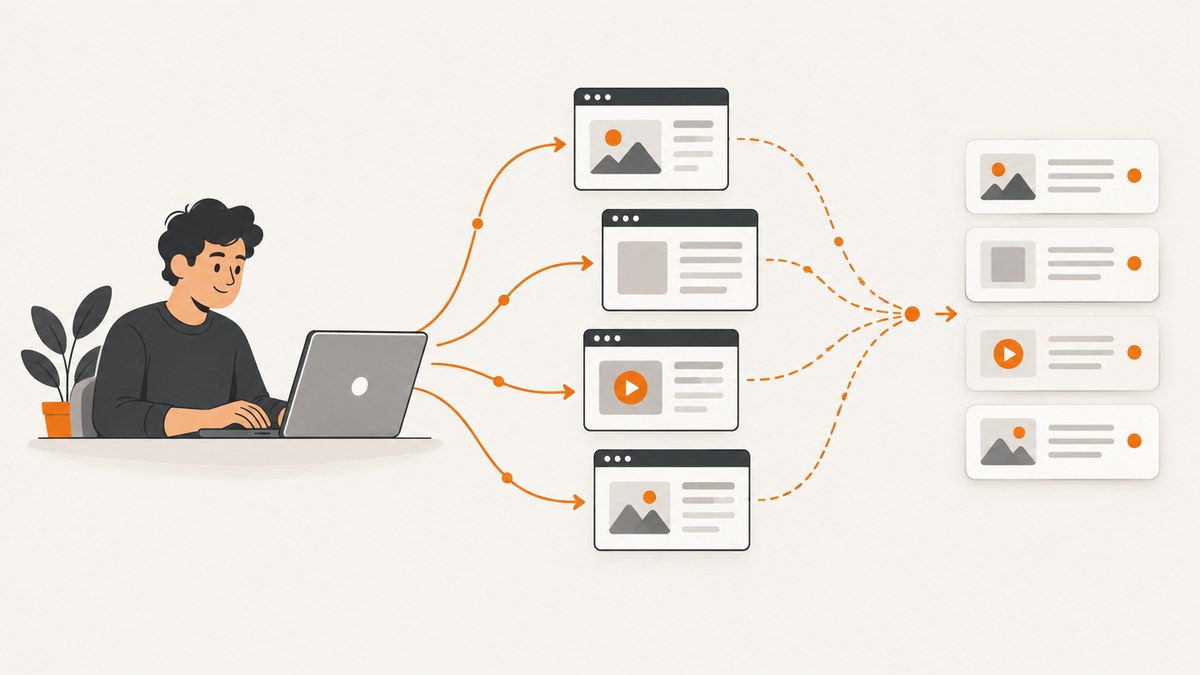
To scrape multiple pages without waiting for each network request in sequence, run your blocking HTTP calls in a bounded concurrent.futures.ThreadPoolExecutor, or use asyncio with an async HTTP client such as aiohttp. In either case, reuse a session, set finite timeouts, keep each result associated with its URL, and choose concurrency based on the destination’s rules and tolerance. There is no universally safe or fastest concurrency setting.
This guide shows both approaches, including per-URL failures, input-order results, per-host limits, robots guidance, and operational tradeoffs. Use an official API or documented bulk endpoint when the site offers one.
1. Check access rules before sending concurrent requests
Concurrency increases the number of requests in flight; it does not grant permission to retrieve a page. Before collecting pages:
- Read the site’s terms and its
robots.txt. Robots directives and terms are separate considerations, and neither should be treated as a complete legal determination. - Look for a documented API, export, or bulk endpoint. Scrapy’s guidance notes that official APIs can be faster for the client and cheaper for the website.
- Respect published rate guidance. If the site documents a crawl delay or request rate, configure your crawler accordingly.
- Use a descriptive user agent where appropriate, and reduce concurrency or stop if responses indicate throttling, errors, or bans.
Python’s urllib.robotparser can inspect some robots directives, including can_fetch, crawl_delay, and request_rate. Check its behavior against your Python version and the site’s current file; parsing robots rules is not a substitute for reviewing terms.
from urllib.robotparser import RobotFileParser

robots = RobotFileParser("https://example.com/robots.txt")
robots.read()
user_agent = "ExampleResearchBot/1.0 (+https://example.org/bot)"
path = "/catalog/item-1"

if not robots.can_fetch(user_agent, "https://example.com" + path):
    raise SystemExit(f"Robots rules disallow {path}")

print("crawl-delay:", robots.crawl_delay(user_agent))
print("request-rate:", robots.request_rate(user_agent))
This small check is illustrative: production crawlers should handle unavailable or malformed robots files deliberately and apply the target’s documented access policy.
2. Choose threads or async I/O
| Approach | Best fit | Concurrency control | Key concern |
|---|---|---|---|
ThreadPoolExecutor + Requests |
Existing synchronous code and blocking HTTP calls | max_workers |
Keep sessions and shared state safe for your usage pattern |
asyncio + aiohttp |
An async application or many coordinated I/O operations | Connector limits and optionally a semaphore | Do not call blocking clients in the event loop |
Python describes asyncio as a framework for concurrent code and says it is often a good fit for I/O-bound network code. This is not a promise that async is always faster. Results depend on response latency, target throttling, task count, client setup, and local processing.
3. Synchronous example: Requests with a thread pool
Requests is synchronous, so each call occupies a worker while waiting for its response. A session persists configuration and cookies and reuses connections through pooling. The example creates one session per worker thread, sets connect and read timeouts, raises on HTTP error responses, and records failures without losing the URL that caused them.

from concurrent.futures import ThreadPoolExecutor, as_completed
import threading
import requests

URLS = [
    "https://example.com/",
    "https://example.com/about",
    "https://example.com/contact",
]
MAX_WORKERS = 4  # Tune for the target; this is not a universal safe rate.
TIMEOUT = (5, 20)  # connect timeout, read timeout in seconds

_thread_local = threading.local()

def get_session():
    if not hasattr(_thread_local, "session"):
        session = requests.Session()
        session.headers.update({"User-Agent": "ExampleResearchBot/1.0"})
        _thread_local.session = session
    return _thread_local.session

def fetch(url):
    response = get_session().get(url, timeout=TIMEOUT)
    response.raise_for_status()
    return response.status_code, response.text

def scrape_one(url):
    try:
        status, html = fetch(url)
        # Parse or extract the fields you need here.
        return {"url": url, "status": status, "html": html, "error": None}
    except requests.RequestException as exc:
        return {"url": url, "status": None, "html": None, "error": str(exc)}

def main():
    results_by_url = {}
    with ThreadPoolExecutor(max_workers=MAX_WORKERS) as pool:
        future_to_url = {pool.submit(scrape_one, url): url for url in URLS}
        for future in as_completed(future_to_url):
            url = future_to_url[future]
            try:
                result = future.result()
            except Exception as exc:
                # Catch unexpected task errors too, retaining URL context.
                result = {"url": url, "status": None, "html": None,
                          "error": f"Unexpected error: {exc}"}
            results_by_url[url] = result
            if result["error"]:
                print(f"FAILED {url}: {result['error']}")
            else:
                print(f"OK {url}: HTTP {result['status']}")

    # Completion order differs from input order; restore it when needed.
    ordered_results = [results_by_url[url] for url in URLS]
    return ordered_results

if __name__ == "__main__":
    results = main()
    print("Completed", len(results), "URLs")
Install the dependency with python -m pip install requests. Save the script as a .py file and run it with Python. Replace the example URLs and user agent with values appropriate to your task.
Why map futures back to URLs?
as_completed yields whichever task finishes next, not the URLs in input order. The mapping lets the program report the correct URL if a future itself raises. The function above also returns a result record per page, so one failed request does not discard successful results. Store records by URL and rebuild a list from the original URL sequence when stable ordering matters.
Choosing max_workers
max_workers caps simultaneous worker threads. A larger number may help when requests spend most of their time waiting, but it can also increase pressure on the target, trigger throttling, or consume more sockets and memory. Start conservatively, follow published limits, monitor status codes and timeouts, and adjust per domain. Do not infer a safe rate from a library default or from another website’s behavior.
4. Async example: aiohttp with bounded connections
Use an asynchronous HTTP library in async code. aiohttp’s reusable ClientSession encapsulates a connection pool and supports keep-alive. Its TCPConnector can cap total connections and connections per host; ClientTimeout puts a finite bound on request duration. The example catches failures for each URL and returns records in input order because asyncio.gather keeps the order of its input awaitables.
import asyncio
import aiohttp

URLS = [
    "https://example.com/",
    "https://example.com/about",
    "https://example.com/contact",
]

async def fetch_one(session, url):
    try:
        async with session.get(url) as response:
            response.raise_for_status()
            html = await response.text()
            return {"url": url, "status": response.status,
                    "html": html, "error": None}
    except (aiohttp.ClientError, asyncio.TimeoutError) as exc:
        return {"url": url, "status": None, "html": None,
                "error": str(exc)}

async def main():
    timeout = aiohttp.ClientTimeout(total=25, connect=5, sock_read=20)
    connector = aiohttp.TCPConnector(limit=12, limit_per_host=3)
    headers = {"User-Agent": "ExampleResearchBot/1.0"}

    async with aiohttp.ClientSession(
        timeout=timeout, connector=connector, headers=headers
    ) as session:
        results = await asyncio.gather(
            *(fetch_one(session, url) for url in URLS)
        )

    for result in results:
        if result["error"]:
            print(f"FAILED {result['url']}: {result['error']}")
        else:
            print(f"OK {result['url']}: HTTP {result['status']}")
    return results

if __name__ == "__main__":
    asyncio.run(main())
Install aiohttp with python -m pip install aiohttp. Set limit for the whole connector and limit_per_host for a host-specific cap. These are client-side connection limits, not a declaration that the target accepts that rate. If the input list is very large, avoid creating an unbounded number of tasks at once: feed URLs through a bounded queue or process them in batches, keeping the connector limits in force.
When you need completion order in async code
Use asyncio.as_completed to process each coroutine as soon as it finishes, carrying the URL in the coroutine’s returned record. Keep exceptions local to each task as above, or wrap each await in its own exception handler. For very large URL sets, combine this pattern with a bounded worker queue so task creation itself does not grow without limit.
5. Common configuration choices
| Need | Threaded Requests | aiohttp |
|---|---|---|
| Timeout | timeout=(connect, read); a single number can be used when appropriate |
ClientTimeout(total=..., connect=..., sock_read=...) |
| Connection reuse | Reuse a Session rather than calling top-level requests.get repeatedly |
Reuse one ClientSession for the batch |
| Global concurrency | ThreadPoolExecutor(max_workers=N) |
TCPConnector(limit=N), optionally also a semaphore |
| Per-host concurrency | Group work by host or use a per-host limiter | TCPConnector(limit_per_host=N) |
| Headers and cookies | Set defaults on the session or per request | Set session defaults or pass request-specific values |
For a thread pool spanning multiple domains, a single worker limit only controls total simultaneous work. If one domain needs a lower cap, add a host-specific limiter or schedule each domain separately. For aiohttp, the connector provides a direct per-host setting. Be deliberate about retries: retry only transient failures, use a small bounded attempt count and backoff, and avoid retry storms against a struggling server. Honor any rate guidance during retries too.
6. Troubleshooting common failures
| Symptom | Likely cause | What to do |
|---|---|---|
| Connection or read timeout | Slow server, network path, or timeout set too tightly | Keep a finite timeout; inspect connect versus read failures, then adjust cautiously. Reduce load and check target status before retrying. |
| HTTP 429 | Rate limit reached | Stop or slow down, honor Retry-After when present, reduce per-host concurrency, and review access guidance. |
| HTTP 403 | Access denied, permissions or policy restrictions, or request rejected | Do not try to evade a restriction. Check terms and documented access paths; use an official API or ask the site owner. |
| Many 5xx responses | Target instability or excessive load | Lower concurrency, pause, and retry only transient errors with bounded backoff. |
| One exception aborts a whole batch | Exception escaped the per-task boundary | Catch request errors inside each task and return a URL-tagged error record. |
| Results appear shuffled | Tasks finish at different times | Associate results with URLs and reorder from the original input list if required. |
| Async program hangs or blocks | A blocking client or CPU-heavy parsing is running in the event loop | Use aiohttp for network I/O. Move blocking or CPU-heavy work to an appropriate executor or separate stage. |
| Too many open connections or memory growth | Excessive concurrency, unclosed responses, sessions, or tasks | Use context managers, reuse sessions, lower limits, and process large inputs in bounded batches. |
7. Performance, reliability, and cost
Concurrency overlaps network waiting; it does not eliminate server response time, page rendering, parsing, or local storage. Measure the work you actually need. If downloading and parsing large documents dominates, connection concurrency alone may not improve the bottleneck. Reuse connections, collect only required fields, bound in-flight work, and record per-URL status and elapsed time so slow hosts are visible.
Reliability comes from explicit timeouts, isolated failures, bounded retries, and preserving request context. A request may return an HTTP error status without a transport exception, which is why the examples call raise_for_status(). Decide whether redirects, cookies, and response encodings match your use case. Save partial successful results as they complete for long jobs, rather than keeping every full HTML body in memory.
For a public website, the main cost is often operational rather than a client library charge: bandwidth, storage, parsing, and the impact on the site. Scraping can also fail when a page requires JavaScript rendering; these HTTP examples retrieve response HTML and do not run a browser. If rendered visual output is what you need, use a browser capture workflow instead.
8. Or skip the browser setup
If your task is to capture page images or PDFs rather than parse response HTML, ScreenshotNeo provides a one-request website screenshot API. The example saves the returned image bytes; see the ScreenshotNeo API documentation for request options and response details.

curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
const fs = await import('node:fs/promises');
await fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer()));- Cookie banners, popups, and chat widgets are removed before the shot.
- Bot checks, blank pages, and failed loads are never billed.
- An MCP server lets AI agents take screenshots.
- 1,000 screenshots per month are free with no card; paid plans start at $5 for 3,000.
Create a free ScreenshotNeo account to get 1,000 screenshots a month with no card.
9. Frequently asked questions
How many URLs can I submit to a thread pool?
There is no fixed universal maximum. The practical limit depends on available memory, the job’s duration, and the sites’ access rules. For very large collections, use a bounded producer and worker pattern instead of submitting and retaining every task at once.
Will async always beat threads?
No. Both can overlap I/O. Choose based on your application and client libraries, then measure under permitted load. The documentation establishes concurrency mechanisms, not a blanket performance winner.
Does Requests execute JavaScript?
No. Requests fetches HTTP responses; it does not render a page in a browser. If the data appears only after client-side JavaScript runs, look for a documented endpoint or use a browser automation or screenshot tool suited to rendered pages.
Should every URL be retried on failure?
No. A permanent 4xx response, access denial, or robots disallowance is not fixed by repeating the request. Retry only transient failures with a small attempt limit and backoff, while respecting rate limits.