Convert cURL Commands to Python
Translate cURL commands into Python Requests while preserving methods, parameters, headers, bodies, files, authentication, redirects, and errors.
To convert a cURL command to Python, keep the same method, URL, query parameters, headers, body, cookies, authentication, and relevant transport settings. For common HTTP requests, Python’s requests library provides direct interfaces: use params= for query values, headers= for headers, json= for JSON, data= for form data, files= for multipart uploads, and auth= for Basic authentication. Then check the HTTP status and set a timeout. The examples below show how to translate each part and where a literal one-to-one conversion needs care.
1. Install Requests and translate a simple GET
Install Requests in the Python environment that runs your script:
python -m pip install requestsA cURL command that fetches a page:
curl https://api.example.com/itemsbecomes:
import requests

response = requests.get("https://api.example.com/items", timeout=30)
response.raise_for_status()
print(response.text)
requests.get() returns a Response object. Its text property decodes the response body as text; use content for bytes, such as an image or archive. raise_for_status() raises an exception for unsuccessful HTTP status codes, which prevents a script from treating an error page as a successful result. A timeout bounds how long the request waits. Requests documents these interfaces in its Quickstart and API reference.
2. Read the whole cURL command before converting
Do not translate only the URL. First identify what each option contributes to the request. cURL has many options, and some affect transport behavior rather than the HTTP message itself. The cURL manual is the reference for what a flag means.
| cURL intent | Requests equivalent | Notes |
|---|---|---|
Query string, such as -d key=value with GET or --get |
params={...} |
Requests encodes the values. Prefer this to manually concatenating values that may need URL escaping. |
Custom method, -X PATCH |
requests.patch() or requests.request("PATCH", ...) |
Use the method that the server expects, including for unusual methods. |
Header, -H 'Name: value' |
headers={...} |
Keep header values intact; avoid manually setting transport-generated headers unless required. |
| JSON payload | json=payload |
Encodes a Python object as JSON and sets the JSON content type. |
Form fields, -d 'a=b' |
data={...} |
For ordinary URL-encoded form submission. |
Multipart form and file, -F |
files=, plus data= for other fields |
Let Requests construct the multipart boundary. |
Cookie, -b or Cookie header |
cookies={...} |
Prefer the structured argument for ordinary cookie values. |
Basic authentication, -u user:pass |
auth=(user, password) |
Do not hard-code real credentials in source. |
Save response to a file, -o file |
Write response.content |
Use bytes, and check status before saving. |
Follow redirects, -L |
allow_redirects=True |
Requests follows redirects by default for GET and several other methods; set explicitly when fidelity matters. |
Repeated cURL flags, quoted values, file paths, and flags for TLS, proxies, compression, or raw transfer can all affect behavior. Record those details before changing languages. Not every cURL option has a direct Requests parameter.
3. Convert query parameters, headers, and methods
For a request with a query string and API token header:
curl -G 'https://api.example.com/search' \
  --data-urlencode 'q=red shoes' \
  -H 'Accept: application/json' \
  -H 'Authorization: Bearer YOUR_TOKEN'
Write:
import requests

url = "https://api.example.com/search"
params = {"q": "red shoes"}
headers = {
    "Accept": "application/json",
    "Authorization": "Bearer YOUR_TOKEN",
}
response = requests.get(url, params=params, headers=headers, timeout=30)
response.raise_for_status()
print(response.url)
print(response.json())
response.url is useful when checking how parameters were encoded. Keep secrets out of committed source; load tokens from an environment variable or a secret store in a real application. For a non-GET method, use the matching convenience method, such as requests.patch(url, ...), or the general form:
response = requests.request(
    "PATCH",
    "https://api.example.com/items/42",
    headers={"Authorization": "Bearer YOUR_TOKEN"},
    json={"name": "Updated"},
    timeout=30,
)
4. Convert request bodies: JSON and form data
For a JSON request, cURL might send a serialized body and declare its content type:
curl 'https://api.example.com/items' \
  -H 'Content-Type: application/json' \
  -d '{"name":"sample","active":true}'
With Requests, pass a Python dictionary using json=:
import requests

payload = {"name": "sample", "active": True}
response = requests.post(
    "https://api.example.com/items",
    json=payload,
    timeout=30,
)
response.raise_for_status()
print(response.json())
This is more than a convenience: json= encodes the object and sets the appropriate content type. Passing a JSON string using data= does not by itself add Content-Type: application/json. If the original command sends a raw body with a special encoding or exact bytes, preserve that deliberately instead of converting it into an object.
For URL-encoded form fields, use data=:
response = requests.post(
    "https://api.example.com/login",
    data={"username": "sam", "remember": "yes"},
    timeout=30,
)
response.raise_for_status()
Requests ignores the json= argument when data= or files= is also supplied. These arguments describe alternative body encodings; do not combine them expecting both bodies to be sent. If the source command uses a form plus an uploaded file, use data= for ordinary fields and files= for file parts.
5. Convert cookies and authentication
A cookie supplied to cURL can usually be represented as a cookie dictionary:
response = requests.get(
    "https://example.com/account",
    cookies={"session": "YOUR_SESSION_VALUE"},
    timeout=30,
)
response.raise_for_status()
For HTTP Basic authentication, cURL’s -u user:pass maps to an auth tuple:
response = requests.get(
    "https://api.example.com/private",
    auth=("YOUR_USERNAME", "YOUR_PASSWORD"),
    timeout=30,
)
response.raise_for_status()
Requests also supports authentication through netrc when explicit authentication is not supplied. Check the Requests authentication guide if credentials appear to be sent without being present in the script. Never paste live cookies or passwords into an article example, issue, or shared log.
6. Convert multipart uploads and save downloads
For a cURL multipart upload, Requests accepts a file handle through files=. Open the file in binary mode and keep it open until the request finishes:
import requests

with open("report.pdf", "rb") as upload:
    response = requests.post(
        "https://api.example.com/upload",
        data={"purpose": "archive"},
        files={"document": upload},
        timeout=60,
    )
response.raise_for_status()
print(response.text)
To control the uploaded filename and content type, provide a tuple:
files = {
    "document": ("report.pdf", upload, "application/pdf"),
}
Requests can also accept per-part headers in a file tuple. Do not manually guess or set the top-level multipart boundary: the library needs to generate a boundary that matches the body. For large uploads, consider the timeout and the server’s upload limits; a short timeout or a proxy limit can interrupt transfer.
For a binary download corresponding to curl -o archive.zip:
import requests

response = requests.get("https://example.com/archive.zip", timeout=60)
response.raise_for_status()
with open("archive.zip", "wb") as output:
    output.write(response.content)
This buffers the complete response in memory. For large files, use streaming so the full file need not be held at once:
import requests

with requests.get(
    "https://example.com/archive.zip",
    stream=True,
    timeout=(10, 60),
) as response:
    response.raise_for_status()
    with open("archive.zip", "wb") as output:
        for chunk in response.iter_content(chunk_size=64 * 1024):
            if chunk:
                output.write(chunk)
7. Handle status codes, JSON, timeouts, and redirects
Keep transport success, HTTP success, and response parsing separate. A response can contain valid JSON even when its HTTP status signals an error. Calling response.json() only tells you that the body could be decoded; it does not establish that the request succeeded. Check status_code or call raise_for_status() before treating the result as a success.
import requests

try:
    response = requests.get(
        "https://api.example.com/items",
        timeout=(5, 30),  # connect timeout, read timeout
    )
    response.raise_for_status()
    result = response.json()
except requests.exceptions.Timeout:
    print("The server did not respond within the timeout")
except requests.exceptions.HTTPError as exc:
    print("The server returned an unsuccessful status:", exc)
except requests.exceptions.RequestException as exc:
    print("The request failed:", exc)
else:
    print(result)
A timeout is not a total deadline for every possible multi-step workflow; it controls connection and response waiting according to the library’s timeout behavior. Choose values that fit the endpoint and your application. If the cURL command explicitly follows redirects, specify allow_redirects=True for clarity, and inspect response.url and response.history while diagnosing unexpected destinations.
Credentials deserve special attention on redirects. cURL documents that Authorization and Cookie headers are not forwarded to other origins on redirects by default. Verify the behavior you require when translating a command, especially if the destination changes host or scheme. Do not disable TLS certificate verification merely to silence a certificate error; fix the certificate trust configuration or use the correct endpoint.
8. Translate carefully when cURL has unusual flags
Before declaring a conversion complete, compare the cURL options to the behavior of the Python client. Check these categories:
- Redirects: Does the command follow them? Does the request method or body change on a redirect? Are credentials restricted when the origin changes?
- TLS: Is the command using a custom CA file, client certificate, or altered verification behavior? Requests exposes TLS options, but the certificate paths and expected security behavior must be preserved intentionally.
- Proxy: Does cURL specify a proxy or inherit one from the environment? Check the Requests environment and session settings if the route differs.
- Compression and transfer: Is the command negotiating compression, sending binary data, or requiring exact raw bytes? Compare actual body and response handling rather than assuming a flag is cosmetic.
- Repeated headers and flags: Determine whether repetition replaces a prior value or adds another value. A Python dictionary cannot represent duplicate keys in the same way as a sequence of command-line arguments.
- File references and shell quoting: Confirm paths exist in the Python process’s working directory and that spaces, special characters, and shell expansions were interpreted as intended in the original command.
The cURL manual and Requests API reference are the authoritative places to resolve an option whose meaning is not obvious. Requests is a convenient documented option for common HTTP requests; the behavior of an unusual command should be verified against that command’s specific flags and destination.
9. Troubleshooting common conversion errors
| Symptom | Likely cause | Fix |
|---|---|---|
| Server says the JSON body is malformed or unsupported | JSON text was passed through data= without the expected content type, or the payload was encoded differently. |
Pass a Python object with json=, or set the content type explicitly if preserving a raw body. |
| Multipart upload is rejected | The top-level content type or boundary was manually set incorrectly. | Use files= and let Requests generate the boundary. Check the field name expected by the API. |
| Python receives 401 or 403 while cURL works | A header, cookie, authentication method, token scope, or redirect behavior was omitted. | Compare all headers and credentials without sharing their secret values; inspect redirect history and final URL. |
| Request hangs or raises a timeout | No timeout was set, the selected timeout is too short, or the server/network is slow. | Set a deliberate connect/read timeout, distinguish slow connection from slow response, and retry only if the operation is safe to repeat. |
response.json() raises an error |
The server returned an empty body, HTML, or another non-JSON response, possibly with an error status. | Check status and content type, then inspect a safe portion of response.text before parsing. |
| Response body differs from cURL | Redirect, compression, cookies, user agent, proxy, or binary/text handling differs. | Inspect response URL, history, headers, and bytes; revisit the cURL flags affecting transport. |
| File not found or wrong file uploaded | Relative paths resolve from a different working directory. | Use a known path or resolve the path explicitly, and open the upload in binary mode. |
| TLS certificate error | The Python environment does not trust the certificate chain or uses a different CA configuration. | Install/configure the correct CA bundle or verify the endpoint certificate; do not turn off verification as a routine fix. |
10. Performance, reliability, and cost
For one-off requests, a top-level call such as requests.get() is straightforward. For repeated calls to the same service, a requests.Session can reuse connections and share session configuration such as headers, cookies, and authentication. Reuse can reduce connection setup overhead, but it does not make a slow server faster. Close sessions when the work is complete.
import requests

with requests.Session() as session:
    session.headers.update({"Accept": "application/json"})
    response = session.get(
        "https://api.example.com/items",
        timeout=(5, 30),
    )
    response.raise_for_status()
    print(response.json())
Use timeouts in production scripts, stream large downloads, and avoid retrying non-idempotent operations automatically unless the API provides a safe idempotency mechanism. A timeout can occur after a server has processed a request but before the client receives the response, so repeating a POST could duplicate a side effect. For cost, the Python client itself is an HTTP library; charges, rate limits, and quotas come from the service you call and any infrastructure you run. Read that API’s terms and pricing rather than inferring cost from the cURL command.
11. Screenshot API example: convert cURL to Python
A screenshot API is an HTTP request, so the same conversion rules apply. This cURL request saves a screenshot as WebP:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpThe matching Python Requests code is:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
with open("shot.webp", "wb") as output:
    output.write(r.content)
Keep the API key private. The target URL is a query parameter and the response is binary image content, so save r.content in binary mode instead of printing r.text. See the ScreenshotNeo API documentation for supported parameters and response details.
12. Or skip the browser setup
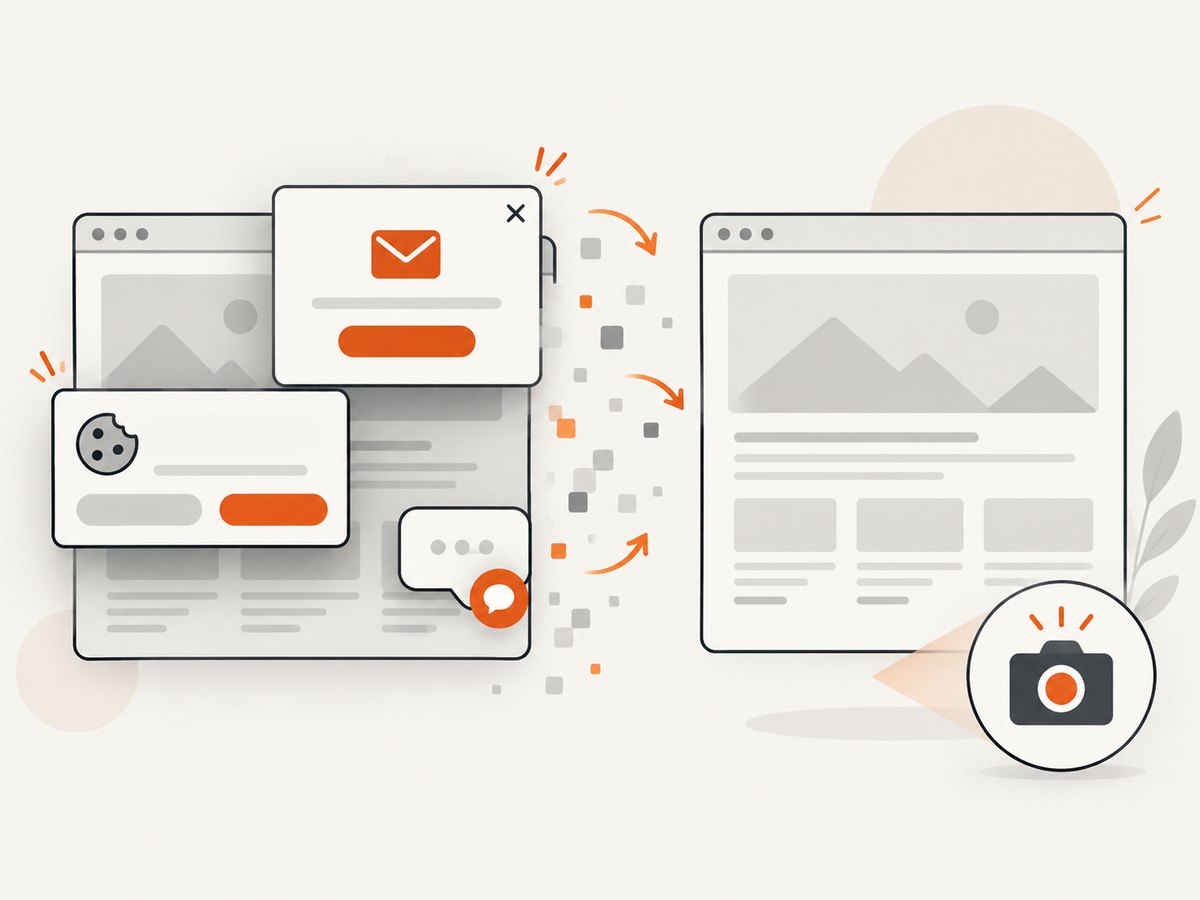
If you need screenshots rather than a browser automation environment, ScreenshotNeo provides a screenshot API and MCP server. One GET request with a URL returns a PNG, JPEG, WebP, or PDF. Cookie banners are accepted and removed before capture, along with known consent platforms, newsletter popups, and chat widgets; each cleanup step can be turned off. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing status. AI agents can use the MCP server’s take_screenshot, get_page_info, and capture_pdf tools.
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
open("shot.webp", "wb").write(r.content)
See the API docs for options including full-page capture, CSS selector capture, device sizes, PDF output, custom headers, waiting, and caching. The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account to get an API key.
13. cURL, Python, and Node.js reference examples
These examples make the same basic screenshot request in each client. Replace the API key and target URL. For Python, python -m pip install requests installs the dependency. For additional screenshot options, use the ScreenshotNeo docs.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests

r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
await import('node:fs/promises').then(fs => fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer())));
14. FAQ
Can every cURL command be converted automatically?
No. Many everyday HTTP features map cleanly, but cURL includes transport and command-line options that may not have an identical Requests setting. Check the original flag’s meaning and verify the behavior needed for that endpoint.
Should I use requests.get() or requests.request()?
Use the convenience method when it expresses the method clearly. Use requests.request(method, url, ...) when the method is dynamic or lacks a convenient method call.
Why does valid JSON still indicate a failed request?
HTTP status and JSON decoding answer different questions. The server can return a JSON error body with an unsuccessful status, so check status_code or call raise_for_status().
Does a cURL command with -d always mean JSON?
No. The data may be form-encoded or a raw body, depending on the other flags and headers. Preserve the original content type and encoding; use json= only when the request body is JSON.