How to Convert HTML to PDF in MVC Razor with iTextSharp
Render your Razor view to XHTML, parse it with iTextSharp XML Worker, return a PDF from MVC, and avoid common CSS, asset, and licensing problems.
Short answer: Render the Razor view completely inside ASP.NET MVC, then pass the resulting XHTML and CSS to iTextSharp XML Worker. XML Worker parses finished markup; it does not render Razor views, resolve ASP pages, execute JavaScript, or behave like a browser.
This workflow is useful for an existing MVC application that already uses iTextSharp 5. However, iTextSharp is end of life and XML Worker is deprecated. NuGet lists itextsharp.xmlworker 5.5.13.6 and recommends the current iText/pdfHTML direction for new projects. Review the package status and dependency graph before starting: itextsharp.xmlworker on NuGet.
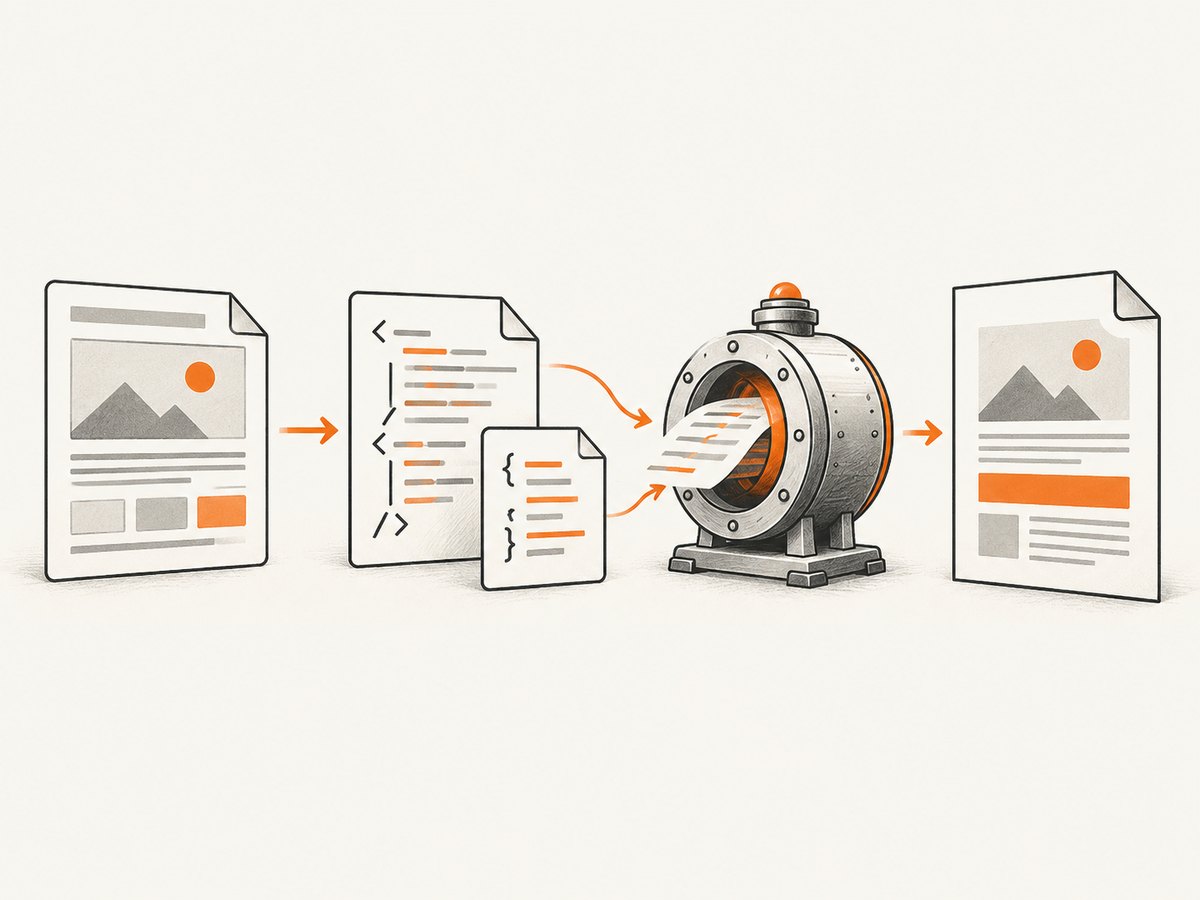
How the conversion works
- MVC evaluates the Razor view, layout, model, partials, and helpers.
- Your application obtains the completed HTML as a string.
- You make that output XHTML-compatible and provide the CSS required by the PDF.
- iTextSharp creates a PDF document and XML Worker parses the HTML and CSS into it.
- The controller returns the generated bytes with an
application/pdfresponse.
The separation matters. XML Worker is a parser for XHTML and a subset of CSS, not a browser engine. It does not fetch and execute a live Razor page, run JavaScript, or reproduce arbitrary browser layout. The iText documentation describes it as appropriate for predictable HTML templates and simple reports (Parsing XML and XHTML; How to convert HTML to PDF).
1. Install the iTextSharp packages
For a legacy ASP.NET MVC application, install the core library and XML Worker package that match your existing dependency graph:
Install-Package iTextSharp
Install-Package itextsharp.xmlworker
Do not assume a package shown in an old tutorial is current. The package listing identifies iTextSharp as end of life with security fixes only planned, and XML Worker as deprecated. For a new implementation, evaluate current iText and pdfHTML instead.
2. Produce finished XHTML from the Razor view
Razor rendering is an MVC concern. The exact view-to-string code depends on your MVC version, view engine, layouts, controller context, URL helpers, and request context, so there is no universal helper that can be pasted into every application. Keep the boundary explicit:
// The MVC-specific part of your application must render the view first.
string html = RenderRazorViewToString("Invoice", invoiceModel);

// Then pass the completed markup to the PDF conversion method below.
byte[] pdf = ConvertXhtmlToPdf(html, css);
return File(pdf, "application/pdf", "invoice.pdf");
Adapt RenderRazorViewToString to your MVC version and existing rendering infrastructure. Verify that the returned string contains the final data, not a Razor template with @ expressions still in it.
3. Make the markup XML Worker can parse
XML Worker expects well-formed XHTML. Close every element, nest elements correctly, quote attributes, and use XHTML forms such as <br />. The vendor specifically documents these requirements (Does my HTML have to be valid XML?).
- Use a complete document fragment or document with correctly nested tags.
- Close void elements:
<img />,<meta />,<link />, and<br />. - HTML-encode user data before it reaches the view.
- Declare UTF-8 when non-ASCII characters are possible.
- Prefer simple selectors and layout rules that XML Worker supports.
Browser-valid HTML is not automatically XML Worker-valid HTML. If your source contains incomplete tags, clean it before parsing or fix the Razor template.
4. Convert the rendered HTML and CSS to PDF
The following method follows the official document, writer, and XMLWorkerHelper pattern. It accepts the already-rendered HTML and an optional CSS string, then returns PDF bytes suitable for an MVC File response.
using System;
using System.IO;
using System.Text;
using iTextSharp.text;
using iTextSharp.text.pdf;
using iTextSharp.tool.xml;

public static class PdfConverter
{
    public static byte[] ConvertXhtmlToPdf(string html, string css = null)
    {
        if (String.IsNullOrWhiteSpace(html))
            throw new ArgumentException("Rendered HTML is required.", nameof(html));

        using (var output = new MemoryStream())
        using (var document = new Document(PageSize.A4, 36, 36, 36, 36))
        {
            PdfWriter writer = PdfWriter.GetInstance(document, output);
            document.Open();

            using (var htmlStream = new MemoryStream(Encoding.UTF8.GetBytes(html)))
            {
                if (String.IsNullOrWhiteSpace(css))
                {
                    XMLWorkerHelper.GetInstance().ParseXHtml(
                        writer,
                        document,
                        htmlStream);
                }
                else
                {
                    using (var cssStream = new MemoryStream(Encoding.UTF8.GetBytes(css)))
                    {
                        XMLWorkerHelper.GetInstance().ParseXHtml(
                            writer,
                            document,
                            htmlStream,
                            cssStream,
                            Encoding.UTF8);
                    }
                }
            }

            document.Close();
            return output.ToArray();
        }
    }
}
The simpler overload with a TextReader is also suitable when there is no separate stylesheet. The important order is to create the Document, create the PdfWriter, open the document, parse the streams, close the document, and then read the generated bytes.
5. Return the PDF from an MVC controller
public ActionResult Invoice(int id)
{
    InvoiceViewModel model = invoiceService.GetInvoice(id);
    string html = RenderRazorViewToString("Invoice", model);
    string css = System.IO.File.ReadAllText(
        Server.MapPath("~/Content/pdf/invoice.css"));

    byte[] pdf = PdfConverter.ConvertXhtmlToPdf(html, css);
    return File(pdf, "application/pdf", "invoice-" + id + ".pdf");
}
This controller example assumes that your application supplies the view-rendering method and invoice service. Those pieces vary by MVC project; the conversion method itself only receives completed markup and CSS.
CSS, fonts, images, and links
XML Worker supports some CSS, but it does not guarantee browser-level support for every stylesheet rule. Treat assets as part of the PDF-specific implementation:
| Asset or rule | Practical approach |
|---|---|
| CSS | Use a small, dedicated stylesheet. Test layout rules instead of passing an entire site bundle. |
| Images | Use paths or streams that the server-side conversion process can actually resolve. Verify permissions and deployment paths. |
| Fonts | Register and embed the fonts required for your character set; confirm that the deployed server has access to the font files. |
| Relative URLs | Do not assume a browser base URL exists. Resolve paths explicitly for the PDF request. |
| JavaScript | Move required values into the rendered HTML. Scripts will not run during XML Worker parsing. |
| Modern layout | Expect differences with flexbox, grid, advanced selectors, and browser-specific features. Simplify the PDF template when necessary. |
HTMLWorker versus XML Worker
If you maintain older iTextSharp code, use XML Worker when you need XHTML and CSS support. The vendor describes the older HTMLWorker as limited and abandoned, with XML Worker as its successor for this iText 5 workflow. This does not make XML Worker a browser renderer; its parser limits still apply.
Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
XMLWorker throws an XML parsing exception |
Unclosed or incorrectly nested HTML | Inspect the rendered string, close every tag, and use XHTML syntax such as <br />. |
| PDF is blank | Empty rendered HTML, content hidden by unsupported CSS, or the document was never opened | Log the final HTML length, open the Document before parsing, and remove hiding rules while isolating the template. |
| CSS has no effect | CSS stream was omitted, paths point to unavailable files, or the rule is unsupported | Pass a UTF-8 CSS stream, use a PDF-specific stylesheet, and test with simple rules. |
| Images are missing | Relative or virtual paths cannot be resolved by the server process | Resolve an accessible physical path or provide image data through a controlled asset handler. |
| Characters display as boxes | Required font is not registered or embedded | Choose a font covering the characters and configure it for the conversion path. |
| Razor expressions appear in the PDF | The template was passed directly instead of rendered output | Render the view through MVC first and pass the resulting HTML string. |
| JavaScript-generated content is absent | XML Worker does not execute scripts | Generate that content on the server before conversion or use a browser-based rendering approach. |
| Layout differs from Chrome | XML Worker supports a narrower HTML/CSS subset | Simplify the template or choose a renderer designed for browser layout. |
Performance, reliability, and cost considerations
- Render and convert only the data needed for the document; large HTML trees and embedded images increase memory use.
- Reuse a dedicated PDF stylesheet instead of loading your full application bundle.
- Keep conversion synchronous only for small reports. For large documents, move work to a background job and store the result.
- Set request and job timeouts around your own MVC action and any asset loading code.
- Make output deterministic: pin fonts, use stable asset paths, and avoid JavaScript-dependent values.
- Do not treat a successful HTTP response as proof of visual correctness. Keep representative invoices and multilingual fixtures for regression checks.
- Review iTextSharp’s AGPL or commercial licensing terms for your deployment. The applicable obligations depend on how your application is distributed; obtain qualified legal advice for your situation (iText licensing explanation).
When this approach is the wrong tool
Choose another conversion strategy when the requirement depends on JavaScript execution, exact browser layout, third-party web components, dynamic charts, or arbitrary public websites. XML Worker is designed for completed XHTML and supported CSS, not for rendering a live page as a user’s browser would.
Or skip the browser setup
If your actual requirement is to capture a website or rendered page rather than generate a controlled MVC report, ScreenshotNeo provides a website screenshot API and MCP server. One request returns PNG, JPEG, WebP, or PDF, and the API accepts the URL directly.
See the ScreenshotNeo API documentation for the complete option list.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);- Cookie and consent banners, newsletter popups, and chat widgets are removed before the shot.
- Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed. Response headers identify the page verdict and billing result.
- An MCP server lets Claude, Cursor, and other MCP clients use
take_screenshot,get_page_info, andcapture_pdf. - The service includes full-page capture, CSS selector element capture, custom CSS and JavaScript, device presets, PDF controls, headers, cookies, blocking rules, caching, signed links, async jobs, bulk capture, and a usage API.
- Free usage includes 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 screenshots, and every feature is available on every plan.
Create a free ScreenshotNeo account and start with 1,000 screenshots a month without a card.
FAQ
Can XML Worker convert a Razor view URL directly?
No. Render the Razor view inside MVC and pass the completed HTML to XML Worker.
Does XML Worker execute JavaScript?
No. JavaScript-dependent content must be generated before parsing or handled by a browser-based renderer.
Do I need to use a separate CSS stream?
Use one when the PDF has stylesheet rules. The official API also supports parsing HTML without a separate CSS stream.
Should a new project start with iTextSharp?
Usually not without a deliberate compatibility reason. iTextSharp is end of life and XML Worker is deprecated; evaluate current iText/pdfHTML and its licensing terms.
Why does valid browser HTML fail?
Browser parsers repair malformed markup. XML Worker expects XHTML-style closed and correctly nested elements, so output that browsers tolerate can still fail conversion.


