HTML to PDF in JavaScript: GitHub Libraries and Examples
Compare Puppeteer, Playwright, html2pdf.js and jsPDF, with runnable JavaScript examples, print controls, caveats and a ScreenshotNeo option.

Short answer: use Puppeteer or Playwright when a server-side script must render a complete HTML page in a real browser and print it to PDF. Use html2pdf.js when a browser user needs to export one DOM element. Use jsPDF when your application is constructing a PDF from data and drawing commands rather than printing a rendered page.
This distinction determines text searchability, CSS behavior, deployment requirements and how much control you have over pagination.
Choose the right JavaScript approach
| Need | Best starting point | Why |
|---|---|---|
| Print a URL or complete HTML page on a server | Puppeteer or Playwright | A browser renders the page, applies print CSS and exposes PDF options. |
| Let a user export an element in the browser | html2pdf.js | It chains a DOM element through html2canvas and jsPDF entirely client-side. |
| Create invoices, reports or forms from structured data | jsPDF | You place text, lines, images and other PDF primitives directly. |
| Capture a URL without maintaining a browser | ScreenshotNeo | Its API can return a PDF and handles page preparation for you. |
1. Convert HTML to PDF with Puppeteer
Puppeteer launches Chromium, navigates to a URL (or receives HTML), then calls page.pdf(). Its PDF guide documents the basic lifecycle and says PDF generation waits for fonts by default.
import puppeteer from 'puppeteer';

const browser = await puppeteer.launch();
try {
  const page = await browser.newPage();
  await page.goto('https://example.com', { waitUntil: 'networkidle2' });
  await page.pdf({
    path: 'page.pdf',
    format: 'A4',
    printBackground: true,
    margin: { top: '16mm', right: '16mm', bottom: '16mm', left: '16mm' }
  });
} finally {
  await browser.close();
}
Print an HTML string
import puppeteer from 'puppeteer';

const html = `<!doctype html>
<html><head>
  <meta charset="utf-8">
  <style>
    @page { size: A4; margin: 18mm; }
    body { font-family: Arial, sans-serif; }
    .avoid-break { break-inside: avoid; }
  </style>
</head><body>
  <h1>Monthly report</h1>
  <section class="avoid-break">Report content</section>
</body></html>`;

const browser = await puppeteer.launch();
try {
  const page = await browser.newPage();
  await page.setContent(html, { waitUntil: 'networkidle0' });
  await page.pdf({ path: 'report.pdf', format: 'A4', printBackground: true });
} finally {
  await browser.close();
}
Options you will commonly adjust
format, or explicitwidthandheight, sets paper dimensions.margincontrols the printable area.printBackground: trueincludes background colors and images.landscape: truerotates the page.pageRangeslimits output to selected pages.displayHeaderFooter,headerTemplateandfooterTemplateadd running content.- Use CSS
@page,break-before,break-afterandbreak-insidefor pagination.
Puppeteer and Playwright use print media by default. Put print-specific rules in @media print. If a page is designed for the screen, explicitly switch media before generating the PDF or create a print stylesheet.
2. Convert HTML to PDF with Playwright
Playwright exposes the same browser-printing model with Chromium, Firefox and WebKit support. The API documents that page.pdf() generates a PDF using print CSS media by default.
import { chromium } from 'playwright';

const browser = await chromium.launch();
try {
  const page = await browser.newPage();
  await page.goto('https://example.com', { waitUntil: 'networkidle' });
  await page.pdf({
    path: 'page.pdf',
    format: 'A4',
    printBackground: true,
    margin: { top: '16mm', right: '16mm', bottom: '16mm', left: '16mm' }
  });
} finally {
  await browser.close();
}
Use screen CSS instead of print CSS
await page.goto('https://example.com', { waitUntil: 'networkidle' });
await page.emulateMedia({ media: 'screen' });
await page.pdf({ path: 'screen-styled.pdf', format: 'A4', printBackground: true });
Playwright’s PDF options include paper format, explicit dimensions, margins, scale, page ranges, background printing and header/footer templates. Option names and browser behavior can change between package versions, so pin the version used by your deployment and consult the current API reference.
3. Export an element with html2pdf.js
html2pdf.js is intended for a browser-side “Export” button. Its documented pipeline converts a DOM element through a cloned container, canvas, image and PDF, then saves the file. It does not run in Node.js.
const element = document.getElementById('element-to-print');
html2pdf().from(element).save();
Set page size, margins and page-break rules
const element = document.getElementById('invoice');

html2pdf()
  .set({
    margin: 10,
    filename: 'invoice.pdf',
    image: { type: 'jpeg', quality: 0.95 },
    html2canvas: { scale: 2, useCORS: true },
    jsPDF: { unit: 'mm', format: 'a4', orientation: 'portrait' },
    pagebreak: { mode: ['css', 'legacy'] }
  })
  .from(element)
  .save();
If you use separate, unbundled scripts, the project README specifies loading jsPDF first, html2canvas second and html2pdf.js third. The bundled distribution avoids that ordering work.
Important html2pdf.js limitations
- The rendered page is rasterized. Text is not selectable or searchable, and files can be larger than a PDF produced by browser printing.
- html2canvas may fail to reproduce some CSS or external content. Cross-origin images need suitable CORS headers.
- The library clones and resizes content. CSS depending on the original width can reflow during conversion.
- Very large documents can exceed the browser canvas maximum and produce a blank result.
- Custom Promise implementations can conflict with the worker chain.
4. Generate a PDF directly with jsPDF
jsPDF is a PDF-generation library rather than a browser page printer. Choose it when you already have structured data and want deterministic placement of text, shapes and images.
import { jsPDF } from 'jspdf';

const doc = new jsPDF({ format: 'a4', unit: 'mm' });
doc.setFontSize(20);
doc.text('Monthly report', 20, 25);
doc.setFontSize(11);
doc.text('Revenue: $12,400', 20, 38);
doc.line(20, 45, 190, 45);
doc.save('report.pdf');
For a full HTML layout, jsPDF alone does not replace a browser’s CSS layout engine. You must calculate positions, line wrapping and page breaks yourself or use it as the PDF stage in another browser-side conversion chain.
5. Make print output predictable
- Wait for readiness: use a navigation condition, a known selector, an application-ready flag or an explicit delay for client-rendered content. “Network idle” is not a universal guarantee that application data is complete.
- Wait for fonts and images: browser PDF APIs wait for fonts according to their documented behavior, but lazy images and application data may need their own readiness logic.
- Control colors: enable background printing and review print-color-adjust CSS when exact colors matter.
- Design pagination: use
@page, fixed margins and break rules. Avoid placing a very large unbreakable element on one page. - Keep assets reachable: authenticated images, blocked third-party requests and cross-origin resources are common causes of missing content.
6. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| PDF contains an empty shell | Rendering finished before client data loaded. | Wait for a specific selector or readiness signal before calling pdf(). |
| Styles look different | Print media rules are active. | Inspect @media print; in Playwright, emulate screen media when appropriate. |
| Backgrounds are missing | Background printing is disabled. | Set printBackground: true or the equivalent option. |
| Fonts fall back | Font files are unavailable or not loaded. | Serve fonts to the browser, wait for them and check network errors. |
| Images are absent | CORS, authentication or lazy loading prevented loading. | Allow the browser request, provide credentials and wait for images to finish. |
| html2pdf text cannot be selected | Its documented canvas pipeline rasterizes the page. | Use Puppeteer or Playwright for browser-printed, searchable text. |
| Large html2pdf document is blank | Canvas dimensions exceeded browser limits. | Split the document, reduce scale or print it with a browser PDF API. |
| Process runs out of memory | Each browser or very large page consumes substantial memory. | Reuse a controlled browser, close pages, limit concurrency and split oversized jobs. |
7. Performance, reliability and cost
Browser automation has startup and memory costs. Reusing a browser process while creating and closing pages can reduce repeated startup work, but concurrency must match the memory available in your deployment. Set navigation and job timeouts, log the URL and readiness condition, and retry only failures that are safe to repeat.
html2pdf.js avoids a server browser but moves rendering and memory use into the user’s browser. High canvas scale improves visual resolution while increasing processing time and file size. jsPDF is usually the most direct path for data-driven documents because it skips HTML layout, but you own wrapping and pagination.
None of these libraries provides a universal fidelity or speed guarantee. Compare your actual templates, fonts, images and page counts before choosing deployment limits.
Or skip the browser setup
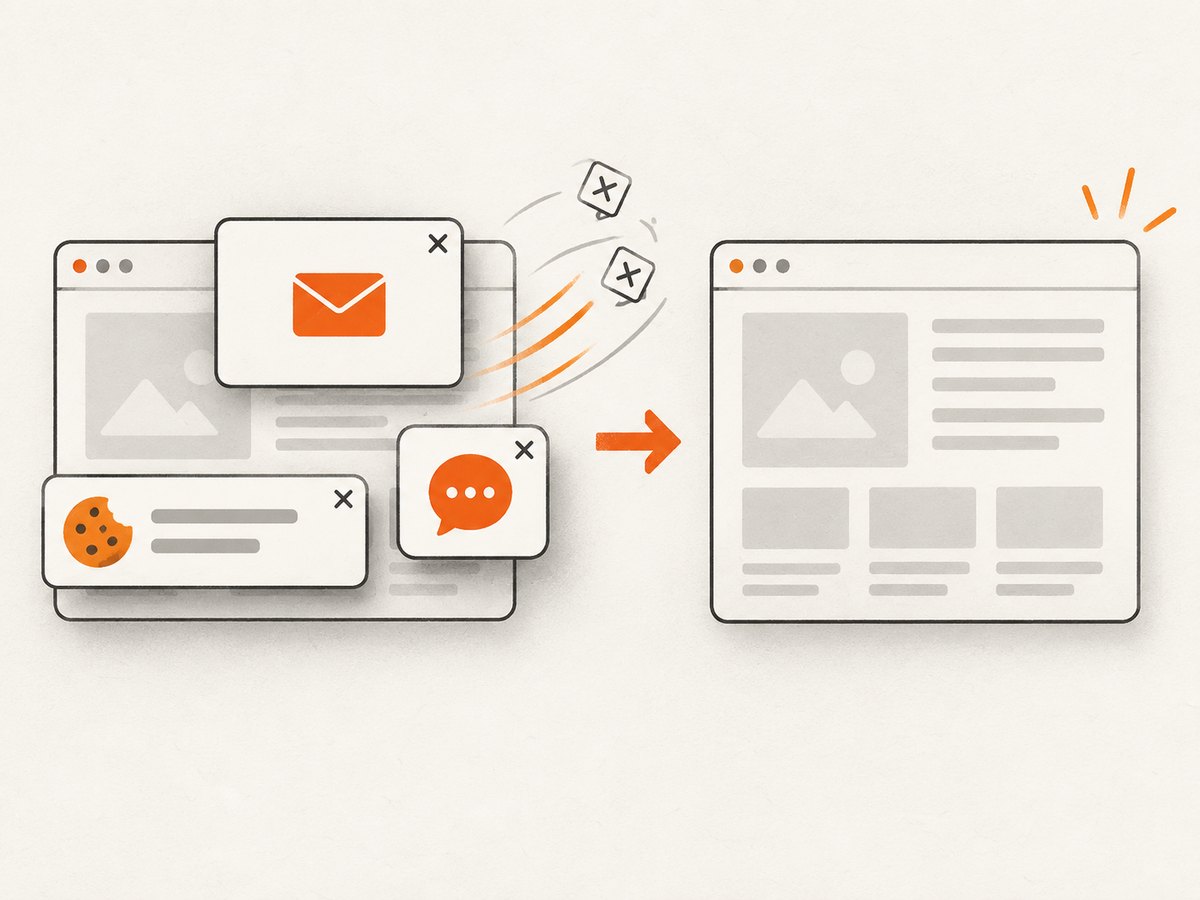
ScreenshotNeo provides a website screenshot API that can also return PDFs. The request is a single GET call; its preparation can accept cookie banners and remove more than 60 known consent platforms, newsletter popups and chat widgets before capture. Bot checks, blank pages, timeouts, failed loads and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers.
See the ScreenshotNeo API documentation for the complete option list, including paper size, margins, landscape mode and page ranges.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);It also offers an MCP server with take_screenshot, get_page_info and capture_pdf tools for Claude, Cursor and other MCP clients. The Free plan includes 1,000 shots per month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
FAQ
Can I convert HTML to PDF without Node.js?
Yes. html2pdf.js runs in the browser. Puppeteer and Playwright require a JavaScript runtime capable of launching their browser automation packages.
Which option keeps PDF text searchable?
Browser printing with Puppeteer or Playwright normally preserves rendered text as PDF text. html2pdf.js documents that its canvas-based output is not selectable or searchable.
Should I use Puppeteer or Playwright?
Both support browser navigation and PDF printing. Choose based on your existing automation stack, supported browsers and the API version you deploy; do not assume one is universally faster or more accurate.
Can jsPDF import an entire webpage?
jsPDF is designed for constructing PDF content from JavaScript. For a complete CSS-driven webpage, use a browser printer or a browser-side conversion library.
How do I prevent a heading from being separated from its content?
Wrap the heading and its content in a container and apply break-inside: avoid, then verify the result at the target paper size.