Convert URLs and HTML to DOCX with Ruby
Convert local HTML or fetched web pages to DOCX in Ruby with Pandoc. Learn URL handling, styling, troubleshooting, and when Ruby DOCX libraries fit.
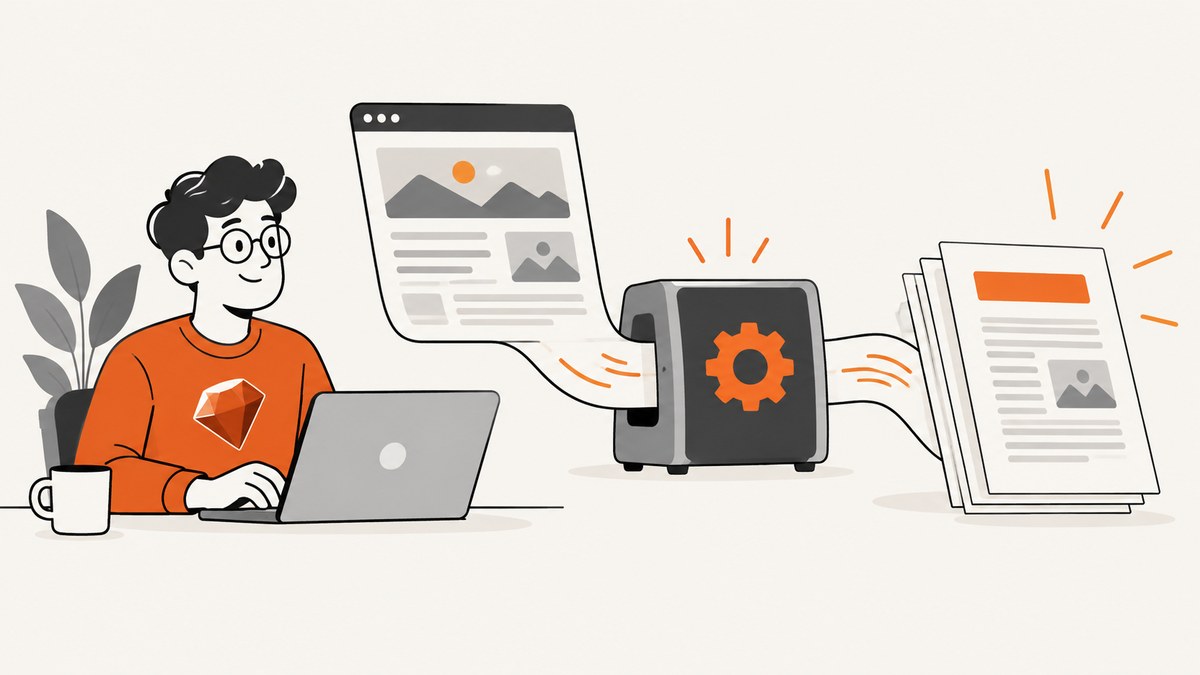
Use Pandoc as the conversion engine, and call it from Ruby. For a local HTML file, pass the file to Pandoc and request DOCX output. For a URL, fetch the page first, inspect the returned HTML, then convert that HTML. A Ruby gem can provide a Ruby interface, but the pandoc-ruby wrapper still needs the Pandoc executable installed and available on PATH (or configured explicitly). A gem such as ruby-docx is for working with existing DOCX files, not converting HTML.
This guide covers local HTML, HTML strings, and fetched URLs; styling DOCX output; operational safeguards; common errors; and the boundaries of conversion fidelity. Pandoc supports HTML input and DOCX output, and its reference DOCX option lets you set document styles and properties. That does not guarantee that arbitrary browser layouts or CSS will look identical in Word, so validate the pages and viewers that matter to your workflow.
1. Choose the input workflow
First identify what you have. A local file is already HTML input. An HTML string must be written to a file or sent to Pandoc through standard input. A URL adds a separate retrieval step: your Ruby application must fetch the page successfully and decide whether the retrieved markup is suitable for conversion.

| Input | Recommended flow | What to check |
|---|---|---|
| Local HTML file | Pass the file directly to Pandoc. | Encoding, relative image paths, linked resources. |
| HTML string | Write a temporary HTML file or pipe content to Pandoc. | Valid markup and resource paths. |
| URL | Fetch with an HTTP client, inspect the response and HTML, then convert. | Authentication, redirects, scripts, network errors, and page-specific markup. |
A web URL is not the same thing as a local HTML file. This workflow does not assume Pandoc will render a live website as a browser does. The research-backed route is to retrieve HTML as its own step, then give that content to the conversion tool.
2. Install Pandoc and confirm it is callable
Install Pandoc using the package or deployment method appropriate for your environment, then confirm the executable is available. The wrapper gem alone does not include the external program.
pandoc --versionIf using the wrapper, install the gem in your application:
gem install pandoc-rubyIn production, install both the Ruby dependency and the Pandoc executable in the runtime image or host. Make the executable path explicit if it is not on PATH. Pin and update dependencies using your normal release process, and verify the deployed environment, since a developer machine having Pandoc installed does not make it available to a worker or container.
3. Convert a local HTML file
This is the shortest Ruby integration: invoke the Pandoc command as a child process. Ruby’s Open3.capture3 returns standard output, standard error, and a process status, so the application can distinguish a successful conversion from a useful error.
require "open3"

input = "page.html"
output = "page.docx"

stdout, stderr, status = Open3.capture3(
  "pandoc", input,
  "--from=html",
  "--to=docx",
  "--output=#{output}"
)

unless status.success?
  warn "Pandoc failed (#{status.exitstatus}): #{stderr}"
  exit 1
end

puts "Created #{output}"
Passing an argument array avoids shell interpolation of filenames. Keep stderr in logs suitable for diagnosing conversion failures, and surface a clear failure to the caller rather than reporting success because a subprocess was started. Use an input path that the process can read and an output directory the application is allowed to write.
4. Fetch a URL, then convert the returned HTML
Fetching and conversion should be separate operations. This example uses Ruby’s standard Net::HTTP library to make a basic GET request, checks the response, saves the body as HTML, then converts it. It deliberately does not claim to run page JavaScript or reproduce browser rendering.
require "net/http"
require "uri"
require "open3"

url = URI("https://example.com/")
response = Net::HTTP.start(
  url.host,
  url.port,
  use_ssl: url.scheme == "https",
  open_timeout: 10,
  read_timeout: 30
) do |http|
  http.get(url.request_uri)
end

unless response.is_a?(Net::HTTPSuccess)
  abort "Fetch failed: HTTP #{response.code} #{response.message}"
end

html_path = "downloaded.html"
docx_path = "downloaded.docx"
File.binwrite(html_path, response.body)

_, stderr, status = Open3.capture3(
  "pandoc", html_path,
  "--from=html",
  "--to=docx",
  "--output=#{docx_path}"
)

unless status.success?
  abort "Pandoc failed (#{status.exitstatus}): #{stderr}"
end

puts "Created #{docx_path} from #{url}"
Replace the example URL with the intended page. Real URL workflows may require redirect handling, headers, cookies, authentication, or a retrieval policy tailored to the application. Check the HTTP status and inspect the HTML before conversion, especially if the returned document is an error page, a consent screen, or a script shell with little useful content. Establish request timeouts and bound the size of responses accepted by your application.
5. Convert an HTML string
For generated HTML, writing a temporary file is straightforward and makes the input and output lifecycle visible. Use a unique temporary directory for concurrent jobs, and clean it up in an ensure block.
require "tmpdir"
require "fileutils"
require "open3"

html = <<~HTML
  <!doctype html>
  <html><head><meta charset="utf-8"><title>Report</title></head>
  <body><h1>Quarterly report</h1><p>Generated from Ruby.</p></body></html>
HTML

Dir.mktmpdir("html-docx-") do |dir|
  input = File.join(dir, "input.html")
  output = File.join(dir, "output.docx")
  File.write(input, html, mode: "w:UTF-8")

  _, stderr, status = Open3.capture3(
    "pandoc", input, "--from=html", "--to=docx", "--output=#{output}"
  )
  abort "Pandoc failed: #{stderr}" unless status.success?

  FileUtils.cp(output, "report.docx")
end
For large inputs, avoid holding multiple copies of the HTML and generated document in memory unnecessarily. Decide how to handle embedded and external assets: HTML references may point to files or URLs unavailable to the conversion process, and relative paths depend on the working directory and input location.
6. Style the DOCX with a reference document
Pandoc’s reference DOCX mechanism controls Word styles and document properties. Start with a reference DOCX produced by Pandoc, modify that file in Word to establish the styles and properties you need, and pass it during conversion.
pandoc --print-default-data-file reference.docx > reference.docxThen use the reference file in the Ruby subprocess invocation:
require "open3"

_, stderr, status = Open3.capture3(
  "pandoc", "page.html",
  "--from=html",
  "--to=docx",
  "--reference-doc=reference.docx",
  "--output=styled-page.docx"
)
abort "Pandoc failed: #{stderr}" unless status.success?
Keep the reference document alongside the application configuration or package it into the runtime image, and use a stable path. Verify the resulting file in the Word viewer used by recipients. The reference DOCX provides a styling mechanism; it does not promise pixel-for-pixel browser layout, since HTML and Word have different layout models.
7. Use a Ruby wrapper or edit the output afterward
pandoc-ruby offers a Ruby-facing interface to Pandoc. It can be useful if you prefer a wrapper API, but it does not remove the executable dependency. Confirm the executable is on PATH in the process environment or configure its path as the wrapper documents.
The similarly named ruby-docx / docx library has a different role: its documented operations include reading and editing DOCX paragraphs, tables, headers, and footers, then saving the document. Use it when your pipeline needs to inspect or modify a DOCX, potentially after Pandoc converts the HTML. Do not choose it as the HTML-to-DOCX conversion engine.
Metanorma’s html2doc gem is another distinct option, but its documented target is legacy .doc, not native .docx. Its README documents an SVG limitation and an additional Word-based save workflow to reach DOCX. If native DOCX is required, Pandoc is the more direct documented route among these choices.
8. Validate output and handle edge cases
Conversion success means the tool produced a file; it does not establish that all content appears as intended. Review representative outputs containing the content your application actually uses.
- Check headings, paragraphs, lists, and tables for structure and legibility.
- Check images and links, including whether referenced assets are accessible to the conversion process.
- Check styles in the target Word viewer and compare with the supplied reference DOCX.
- Try pages with long tables, unusual markup, missing assets, or non-ASCII text when those occur in your input set.
- Inspect fetched HTML to make sure it contains the page content you expect, rather than a login page or mostly empty script-driven shell.
- Open or otherwise validate the DOCX before distributing it in an automated workflow.
For remote pages, distinguish HTTP retrieval errors from conversion errors in logs and retry policy. Retrying a transient fetch failure may help; repeatedly retrying invalid HTML or a deterministic conversion error usually will not. Place reasonable limits on network time, response size, concurrent Pandoc processes, and job duration based on your service’s requirements.
9. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
pandoc: command not found or executable error |
Pandoc is missing from the runtime or not on its PATH. |
Install Pandoc in the host/container and verify from the same user and process environment. Configure an explicit executable path if needed. |
| Wrapper installs but conversion fails | The Ruby gem is present, but the external Pandoc program is not callable. | Install the executable separately and confirm the wrapper’s configured path. |
| HTTP error or empty document | Fetch failed, redirected unexpectedly, requires authentication, or returned content unlike the expected page. | Check status, final response, headers and body; add appropriate retrieval handling and inspect HTML before conversion. |
| Missing images or odd relative links | Assets are remote, inaccessible, or resolved relative to an unexpected directory. | Make assets available to the conversion workflow and check the HTML’s paths and working directory. |
| Layout differs from the browser | HTML/CSS browser layout is not reproduced exactly by document conversion. | Use semantic HTML, simplify unsupported layout assumptions, configure styles with a reference DOCX, and inspect the result in the target viewer. |
| Output file is missing despite no visible error | Subprocess status was ignored, output path is unwritable, or the process ran in another directory. | Check exit status and stderr, use an explicit output path, and verify directory permissions. |
| Overlapping jobs corrupt temporary inputs | Jobs share a fixed temporary filename. | Give each job a unique temporary directory and clean it up after conversion. |
10. Performance, reliability, and cost
This approach has two distinct workloads: retrieving the page and converting its HTML. Network latency, remote server behavior, and response size affect fetching; process startup, input complexity, and output handling affect conversion. The research sources provide no comparative benchmark, so size concurrency and timeouts using representative workload measurements from your own environment.

For reliability, use explicit timeouts on network requests, check HTTP status and subprocess exit status, capture diagnostic stderr, and keep each conversion’s files isolated. A failed fetch and a failed conversion should be reported as different errors. For a batch pipeline, bound concurrency so it does not create unbounded network requests or Pandoc processes.
The conversion components described here are software dependencies; the research does not establish a service price or a performance guarantee. Budget engineering effort for packaging Pandoc, maintaining the Ruby wrapper if used, storing temporary inputs and outputs, and validating results. If the input is a dynamic page whose visual state matters more than its HTML source, use a browser screenshot workflow for an image or PDF capture rather than treating DOCX conversion as browser rendering.
Or skip the browser setup
If what you need is a clean visual capture of a URL rather than an editable Word document, ScreenshotNeo is a website screenshot API and MCP server. It does not convert HTML into DOCX; it returns PNG, JPEG, WebP, or PDF. The do-it-yourself DOCX flow above remains the route for an editable Word file. For a screenshot, one GET request is enough:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpSee the ScreenshotNeo API documentation for request options. Cookie banners are accepted and removed along with 60+ known consent platforms, newsletter popups, and chat widgets before capture; each step can be turned off. Bot checks/CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers say which verdict applied and whether the shot was billed. Its MCP server lets Claude, Cursor, and other MCP clients use take_screenshot, get_page_info, and capture_pdf. The free plan includes 1,000 shots a month with no card; paid plans start at $5 for 3,000 shots. Every feature is on every plan.
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
open("shot.webp", "wb").write(r.content)
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
Sign up for ScreenshotNeo’s free plan: 1,000 screenshots a month, no card required.
11. Frequently asked questions
Can Pandoc convert a URL directly into a DOCX?
For this workflow, treat retrieval as a separate step: fetch the page, inspect the HTML, and pass that HTML to Pandoc. This makes network, authentication, and page-content failures visible before conversion.
Does the ruby-docx gem convert HTML?
Its documented purpose is reading and editing DOCX documents. Use Pandoc for the conversion, then use a DOCX library if your application needs post-conversion inspection or changes.
How do I control Word styles?
Use a Pandoc reference DOCX, modify its styles and properties, and pass it with --reference-doc. Check the output in the viewer your recipients use.
Will the result look exactly like the webpage?
Do not assume so. The researched documentation establishes format support and style configuration, not exact preservation of arbitrary browser layout and CSS. Validate representative pages.
Is HTML-to-DOCX the right format for a visual record?
Use DOCX when recipients need an editable Word document. If the requirement is a visual capture of a web page, a screenshot or PDF capture is a different output workflow.
Sources
- Pandoc User’s Guide — supported formats and reference DOCX behavior.
- pandoc-ruby documentation — dependency on the Pandoc executable.
- ruby-docx documentation — reading and editing DOCX documents.
- Metanorma html2doc README — legacy DOC output and documented limitations.