Converting HTML to PDF Using iText in Java
Convert HTML and CSS to PDF in Java with iText pdfHTML, including Maven setup, complete code, CSS limits, licensing, errors, and production guidance.
Use iText pdfHTML and its HtmlConverter API. Add the com.itextpdf:html2pdf Maven dependency, keep its version compatible with your iText Core version, then convert an HTML input stream to a PDF output stream.
For new Java projects, pdfHTML is the current iText add-on for HTML and CSS conversion. Older entry points such as HTMLWorker and XML Worker are legacy approaches and should not be the starting point for new code.
1. Add pdfHTML to a Java project
With Maven, add com.itextpdf:html2pdf. Select a version that matches the iText Core version licensed and used by your application. Check iText’s installation guidance and compatibility matrix before pinning a release: iText installation documentation.
<dependency>
  <groupId>com.itextpdf</groupId>
  <artifactId>html2pdf</artifactId>
  <version>YOUR_COMPATIBLE_VERSION</version>
</dependency>
Do not copy a “latest” version into production without checking the Core/pdfHTML compatibility table. Release numbers change, and a mismatched add-on can fail during dependency resolution or behave differently from the version you evaluated.
2. Minimal HTML-to-PDF conversion
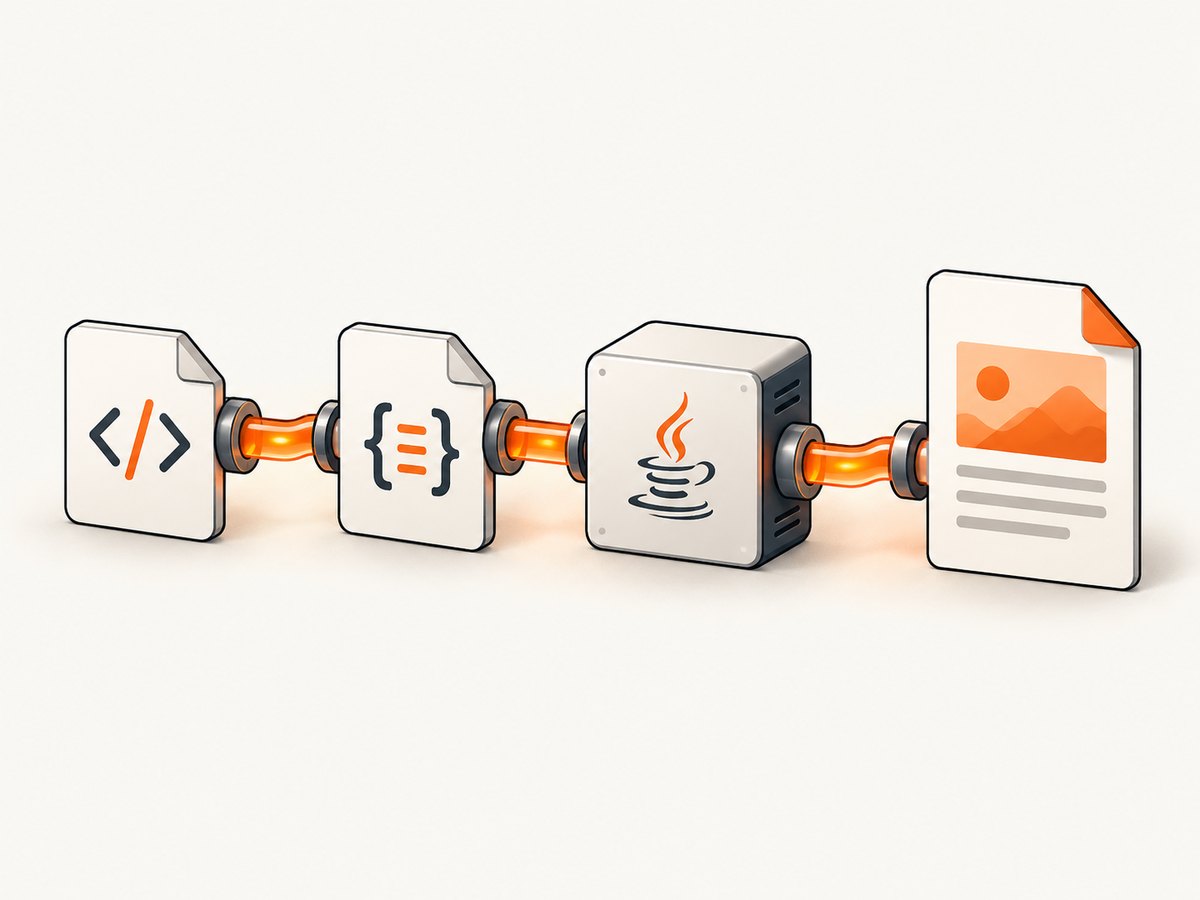
This complete example reads input.html and writes output.pdf. It uses try-with-resources so file handles are closed even when conversion fails.
import com.itextpdf.html2pdf.ConverterProperties;
import com.itextpdf.html2pdf.HtmlConverter;

import java.io.FileInputStream;
import java.io.FileOutputStream;
import java.io.InputStream;
import java.io.OutputStream;

public class HtmlToPdf {
    public static void main(String[] args) throws Exception {
        ConverterProperties properties = new ConverterProperties();

        try (InputStream html = new FileInputStream("input.html");
             OutputStream pdf = new FileOutputStream("output.pdf")) {
            HtmlConverter.convertToPdf(html, pdf, properties);
        }
    }
}
The API accepts HTML and produces a PDF directly. For a string, use a ByteArrayInputStream; for a web resource, download the content yourself, validate the source, and pass the resulting stream to pdfHTML.
Convert an HTML string
import com.itextpdf.html2pdf.ConverterProperties;
import com.itextpdf.html2pdf.HtmlConverter;

import java.io.ByteArrayInputStream;
import java.io.ByteArrayOutputStream;
import java.nio.charset.StandardCharsets;
import java.nio.file.Files;
import java.nio.file.Path;

public class HtmlStringToPdf {
    public static void main(String[] args) throws Exception {
        String html = """
            <!doctype html>
            <html>
              <head>
                <meta charset=\"UTF-8\">
                <style>body { font-family: sans-serif; } h1 { color: #1f2937; }</style>
              </head>
              <body>
                <h1>Invoice</h1>
                <p>Generated from an HTML string.</p>
              </body>
            </html>
            """;

        ConverterProperties properties = new ConverterProperties();
        ByteArrayOutputStream pdf = new ByteArrayOutputStream();

        try (ByteArrayInputStream input = new ByteArrayInputStream(
                html.getBytes(StandardCharsets.UTF_8))) {
            HtmlConverter.convertToPdf(input, pdf, properties);
        }

        Files.write(Path.of("output.pdf"), pdf.toByteArray());
    }
}
3. Base URLs, relative assets, and fonts
Relative links such as css/app.css, images/logo.png, and web fonts need a base URI. Set it on ConverterProperties so pdfHTML can resolve those resources.
ConverterProperties properties = new ConverterProperties();
properties.setBaseUri(Path.of("src/main/resources/templates").toAbsolutePath().toString());

try (InputStream html = new FileInputStream("src/main/resources/templates/invoice.html");
     OutputStream pdf = new FileOutputStream("output.pdf")) {
    HtmlConverter.convertToPdf(html, pdf, properties);
}
For production templates, keep HTML, CSS, images, and fonts in a controlled directory or resource store. Avoid allowing an untrusted document to resolve arbitrary local files or internal network addresses. Restrict resource loading at the application boundary and validate URLs before conversion.
Register fonts when the template requires them
PDF output depends on the fonts available to the converter. If a template uses a font that is not installed on the server, text can be substituted or layout can change. Register a known font directory through the font provider APIs for your pdfHTML version, then test the rendered output on the same type of runtime used in production. The exact font-provider API is version-sensitive, so follow the documentation for your selected release.
4. HTML and CSS support
pdfHTML supports many HTML elements and CSS properties, but it is not a browser engine. Support depends on the exact pdfHTML release. Review the versioned feature matrix for your release before depending on advanced layout, CSS, fonts, SVG, forms, or accessibility behavior: pdfHTML feature support FAQ.
The surfaced feature table is scoped to pdfHTML 6.3.3 with iText Core 9.7.0. It lists PDF/A and PDF/UA capabilities, but advertised support does not prove that every generated document conforms. Validate representative output with the relevant archival or accessibility tools.
The pdfHTML 6.3.3 release note, dated July 8, 2026, records support for CSS :is(), :where(), and :not(), plus fixes involving malformed CSS, CSS Grid pagination, and list rendering. Treat release notes as version-specific information; verify behavior against your own templates.
Design templates for print output
- Use explicit print-oriented dimensions and margins.
- Define page breaks deliberately instead of relying on browser viewport behavior.
- Keep critical content in normal document flow so it can paginate.
- Use local, deterministic assets when reproducibility matters.
- Test long tables, repeated headers, images, footnotes, and non-Latin text.
5. Page size, margins, and page breaks
Use CSS print rules such as @page for paper size and margins, and page-break properties where supported by your selected pdfHTML version.
@page {
  size: A4;
  margin: 18mm 15mm 20mm;
}

.invoice-page-break {
  break-before: page;
}

.avoid-split {
  break-inside: avoid;
}
Always inspect output with content that spans multiple pages. A layout that looks correct for one short record can split headings, rows, or signatures when real data is longer.
6. Licensing: AGPL or commercial terms
iText documents AGPL downloads for open-source use and says commercial use requires a commercial license for both iText Core and pdfHTML. This is vendor guidance, not legal advice. Review the actual license terms for your application, distribution model, and deployment architecture before rollout.
- AGPL route: determine whether your application can satisfy the obligations of the AGPL.
- Commercial route: obtain the required commercial licensing for Core and pdfHTML.
- Internal review: record which versions and licenses are approved for the shipped artifact.
7. Legacy APIs: HTMLWorker and XML Worker
Do not start a new implementation with HTMLWorker. iText states that the class was deprecated many years ago and was removed in recent iText versions. It was intended for simple snippets and did not provide full HTML and CSS support.
XML Worker was an older iText 5 add-on designed for predictable XHTML-oriented content. It is not a modern URL-to-PDF browser renderer. If you are migrating old code, plan a template review and conversion test suite instead of assuming that every legacy input will render identically through pdfHTML. See iText’s migration tutorial for the historical distinction: iText pdfHTML tutorial.
8. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Maven cannot resolve dependencies | Missing repository, typo, or incompatible Core/pdfHTML versions | Use Maven Central or the iText repository documented for your release, then verify the compatibility matrix. |
| CSS appears ignored | The property or selector is outside the release’s support scope | Check the versioned feature matrix and replace unsupported layout with print-oriented CSS. |
| Images are missing | Relative URLs have no base URI, or the resource cannot be read | Set ConverterProperties.setBaseUri, use accessible resources, and verify paths and permissions. |
| Fonts or text look different | Font is unavailable, not embedded, or lacks required glyphs | Provide and register the required fonts; test Unicode and fallback behavior on the production runtime. |
| Output is blank or incomplete | Malformed HTML, blocked resources, or an exception hidden by broad error handling | Validate the input, log the complete exception, simplify the template, and add resources back incrementally. |
| Content splits badly across pages | Browser-style layout assumptions do not map to paginated PDF layout | Use @page, break properties, explicit table structure, and multi-page fixtures. |
| PDF/A or PDF/UA validation fails | Feature support does not guarantee conformance for a particular document | Use the required conformance settings and validate the generated file with an appropriate validator. |
| Conversion is slow or memory usage grows | Large images, huge DOMs, many fonts, or repeated conversions in one process | Resize source images, keep templates bounded, reuse stable configuration, process jobs with limits, and measure with representative documents. |
9. Reliability, performance, and cost considerations
Reliability checklist
- Pin and document compatible Core and pdfHTML versions.
- Keep a fixture set containing short, long, multilingual, image-heavy, and malformed inputs.
- Fail the job clearly when required assets or fonts are unavailable.
- Write output atomically so consumers never read a partially written PDF.
- Log the template version, library versions, duration, output size, and failure category.
Performance
iText’s surfaced documentation does not provide a general conversion benchmark. Measure your own workload. Conversion time is affected by HTML size, CSS complexity, images, fonts, page count, and resource access. Keep a warm JVM for recurring jobs, avoid downloading the same assets repeatedly, and set application-level timeouts around untrusted or remote inputs.
Cost
Besides licensing, account for CPU, memory, storage, font licensing, and any remote asset retrieval. Do not estimate capacity from a single small HTML file. Record p50 and worst-case durations and memory for the templates your users actually submit.
10. Or skip the browser setup
If your real input is a public URL and you need a screenshot or PDF rather than server-side Java HTML rendering, ScreenshotNeo provides a single GET request. It removes cookie and consent banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. Its MCP server lets Claude, Cursor, and other MCP clients use take_screenshot, get_page_info, and capture_pdf.
See the ScreenshotNeo API documentation for the available capture options.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const fs = require('node:fs/promises');

const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`ScreenshotNeo request failed: ${res.status}`);
await fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer()));
ScreenshotNeo includes full-page capture with lazy images loaded, PDF options, custom CSS and JavaScript, waits, headers, cookies, user agents, blocking controls, caching, signed links, async jobs, bulk capture, usage reporting, and an OpenAPI specification. Every plan includes every feature. The Free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
11. FAQ
Is pdfHTML the same as rendering a page in Chrome?
No. It converts HTML and CSS according to pdfHTML’s supported feature set. Validate complex templates instead of assuming browser-equivalent output.
Can I keep using HTMLWorker?
It is a legacy API that iText says was deprecated and removed in recent versions. Use pdfHTML for new work.
Do I need both iText Core and pdfHTML licensing?
iText’s installation guidance says commercial use requires a commercial license for both components. Review the applicable terms for your project.
How do I know whether a CSS property is supported?
Check the feature matrix for the exact pdfHTML and Core versions in your build, then test a representative document.
Should I use iText or ScreenshotNeo?
Use iText pdfHTML when your Java application owns the HTML-to-PDF conversion and needs programmatic template control. Use ScreenshotNeo when a URL capture or PDF from a live page is the simpler workflow and you want browser setup handled by an API.


