Convert HTML to PDF With Links
Convert HTML to a PDF that keeps external, internal, and fragment links clickable with WeasyPrint, Puppeteer, or wkhtmltopdf.
Short answer: keep normal <a href="..."> elements in your HTML, give the renderer a correct base URL, wait for scripts that create links, and test the generated PDF in the viewer your users will use. Choose WeasyPrint for mostly static HTML/CSS in Python, Puppeteer when JavaScript and browser rendering determine the page, and wkhtmltopdf when its command-line controls fit your deployment.
1. Keep links clickable: the rules
- Use ordinary anchor elements. Do not replace links with click handlers only.
- Use absolute URLs, or configure a base URL so relative links can be resolved.
- Keep the target element’s
idwhen using fragment links such as/guide#install. - Wait until JavaScript has inserted or rewritten links before rendering.
- Open the final PDF and click representative external, internal, and fragment links.
A renderer can preserve link annotations, but the result still depends on the HTML, CSS, scripts, loaded resources, and the PDF viewer. There is no universal link-retention percentage to assume.
2. Choose the renderer
| Renderer | Use it when | Link and rendering notes |
|---|---|---|
| WeasyPrint | Python workflow; mostly static HTML and CSS | Accepts a URL, filename, or HTML string and documents clickable internal and external hyperlinks. |
| Puppeteer | The page needs JavaScript, browser APIs, or precise browser rendering | Runs Chromium. PDF output uses print CSS by default; emulate screen media when required. |
| wkhtmltopdf | A standalone CLI and explicit switches suit your deployment | Provides controls for external and internal links, JavaScript, images, forms, and local files. |
3. WeasyPrint in Python
Install WeasyPrint using the method for your operating system, then render a URL directly:
from weasyprint import HTML

HTML(url="https://example.com/article").write_pdf("article.pdf")
That is enough for a page whose links already use absolute URLs. For HTML strings or local files, set a base URL so relative links resolve:
from weasyprint import HTML
html = """
Article
Details
"""
HTML(string=html, base_url="https://example.com/").write_pdf("article.pdf")WeasyPrint documents hyperlinks, bookmarks, attachments, and forms in its PDF output. It also documents PDF/A and PDF/UA variants, but a requested variant is not a guarantee that the result passes every conformance check; validate the finished file when archival or accessibility compliance matters.
WeasyPrint considerations
- It is not a browser JavaScript runtime. Links created after page load will not appear unless they are present in the HTML supplied to WeasyPrint.
- Resolve relative assets and links with
base_urlor absolute URLs. - For a site that requires client-side rendering, generate the final HTML with a browser first or use Puppeteer.
4. Puppeteer in Node.js
Puppeteer renders the page in Chromium, waits for the network to settle, and writes a PDF:
import puppeteer from "puppeteer";

const browser = await puppeteer.launch();
const page = await browser.newPage();
await page.goto("https://example.com/article", {waitUntil: "networkidle0"});
await page.pdf({path: "article.pdf", format: "A4", printBackground: true});
await browser.close();
page.pdf() uses the print CSS media type by default. If the screen stylesheet is the intended output, emulate it before creating the PDF:
import puppeteer from "puppeteer";

const browser = await puppeteer.launch();
const page = await browser.newPage();
await page.goto("https://example.com/article", {waitUntil: "networkidle0"});
await page.emulateMediaType("screen");
await page.pdf({
  path: "article-screen.pdf",
  format: "A4",
  printBackground: true,
  preferCSSPageSize: true
});
await browser.close();
Wait for links and assets created by JavaScript
await page.goto("https://example.com/article", {waitUntil: "domcontentloaded"});
await page.waitForSelector("article a[href]");
await page.waitForFunction(() => document.fonts.status === "loaded");
await page.pdf({path: "article.pdf", format: "A4", printBackground: true});
Use a page-specific readiness selector when possible. A generic network-idle condition can finish too early for delayed timers or long-lived connections.
Useful Puppeteer PDF settings
| Setting | Purpose |
|---|---|
format |
Choose a paper preset such as A4. |
printBackground |
Include background colors and images. |
preferCSSPageSize |
Honor CSS @page dimensions when defined. |
landscape |
Use landscape orientation. |
margin |
Set top, right, bottom, and left margins. |
displayHeaderFooter |
Add Chromium header and footer templates when needed. |
5. wkhtmltopdf from the command line
Make link and JavaScript behavior explicit in scripts that must be reproducible:
wkhtmltopdf --enable-external-links --enable-internal-links \
  --enable-javascript --javascript-delay 500 \
  page.html page.pdf
The project documents controls for external and internal links, JavaScript, images, forms, and local-file access. External and internal links are enabled by default, but explicit switches make deployment intent clear.
When local files or delayed resources are involved
- Confirm the input path is readable by the process.
- Use the documented local-file option only when your deployment requires it.
- Increase the JavaScript delay only enough for your page’s links and assets to settle; it increases each conversion’s wait time.
6. Preserve each kind of link
External links
Prefer fully qualified URLs:
<a href="https://example.com/pricing">Pricing</a>If you use /pricing or ../pricing, supply a correct base URL and verify the result in the PDF viewer.
Internal document links
<a href="#installation">Installation</a>

<h2 id="installation">Installation</h2>
The destination needs a stable id. Do not depend on an automatically generated heading ID that can change between builds.
Links inserted by JavaScript
Render with a browser, wait for the selector or application-ready signal, then create the PDF. WeasyPrint and other non-browser renderers will not execute the code that creates those anchors.
7. A repeatable validation checklist
- Generate the PDF from the same URL or HTML fixture used in production.
- Check an external HTTPS link, a relative link, an internal fragment, and a link inside a repeated component.
- Open the file in at least one desktop viewer and one browser PDF viewer used by your audience.
- Inspect the link annotation destination when a click appears to do nothing.
- Repeat after changing print or screen CSS, JavaScript timing, fonts, or asset hosting.
8. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Links are visible but not clickable | The renderer received text or an element without an href. |
Keep real <a href> elements in the source and inspect the generated PDF. |
| Relative links open the wrong place | No correct base URL was supplied. | Use absolute URLs or set WeasyPrint base_url; verify the page URL passed to the browser or CLI. |
| Fragment links do nothing | The target id was removed or changed. |
Keep a stable target ID and test the final PDF. |
| JavaScript links are missing | Rendering finished before the application created them. | Use Puppeteer, wait for a readiness selector, and then call page.pdf(). |
| Screen layout changed in the PDF | Puppeteer used print media by default. | Call page.emulateMediaType("screen"), or adjust print CSS intentionally. |
| Images or fonts are absent | Resources were not loaded, were blocked, or were local files without permission. | Check URLs, credentials, network access, and local-file settings; wait for fonts and images before capture. |
| Output is blank or incomplete | Navigation, scripts, or a protected page failed. | Capture console and network errors, use a page-specific readiness condition, and verify the source URL independently. |
| PDF/A or PDF/UA validation fails | Renderer support does not guarantee conformance. | Use valid semantic HTML, run a conformance checker, and fix the reported violations. |
9. Performance, reliability, and cost
- Performance: browser rendering generally costs more startup and memory than a direct HTML/CSS renderer. Reuse a Puppeteer browser process for batches, but isolate pages and close them after each job.
- Reliability: set navigation and conversion timeouts, log the source URL and renderer version, and retry only transient navigation failures. A retry cannot fix broken HTML or a permanently blocked resource.
- Determinism: pin fonts, CSS, browser versions, and time-dependent data when PDFs are compared or archived.
- Cost: measure total conversion time, CPU, memory, browser downloads, and storage in your own deployment. The cited renderer documentation does not publish universal speed or resource figures.
10. Or skip the browser setup
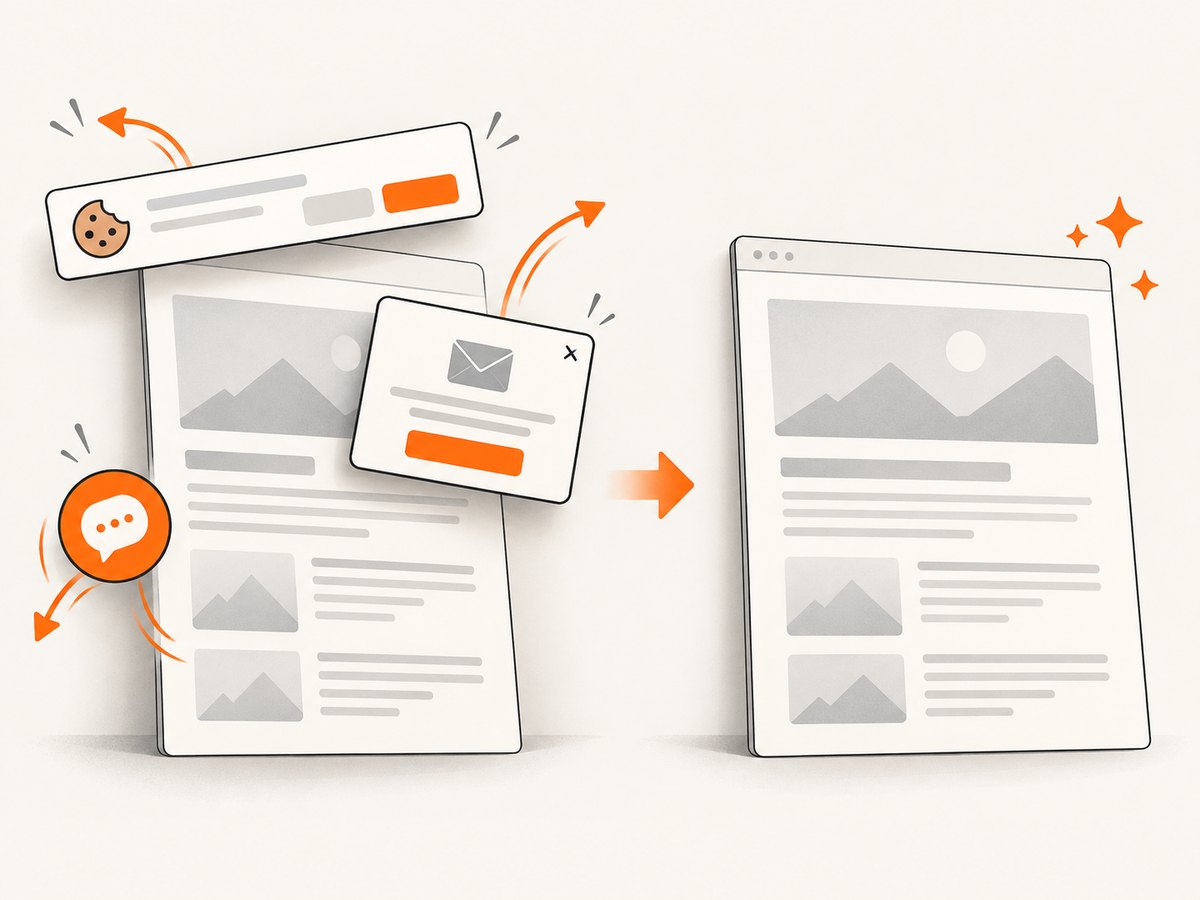
ScreenshotNeo provides a website capture API and MCP server. One GET request returns a clean screenshot or PDF, while its capture pipeline accepts consent banners like a visitor and removes more than 60 known consent platforms, newsletter popups, and chat widgets before capture. Each cleanup step can be turned off.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);See the ScreenshotNeo API documentation for PDF output and the available capture options. Bot checks, CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed; the response identifies the result with X-Page-Verdict and X-Billed headers. Its MCP server exposes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 shots per month without a card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
11. FAQ
Do PDFs keep links automatically?
Only when the renderer emits link annotations and receives valid anchors. Always test the final file in your target viewer.
Which option handles a React or Vue page?
Use Puppeteer and wait for the application-specific ready state before calling page.pdf().
Can I use relative URLs?
Yes, if the renderer has a correct base URL. Absolute URLs remove one common source of failures.
Should I use print or screen CSS?
Use print CSS for a document-oriented layout. Call Puppeteer’s emulateMediaType("screen") when the screen design is the intended PDF.
How do I prove links survived a build?
Keep a fixture containing external, relative, internal, and fragment links, generate the PDF in CI, and click or inspect each annotation in the output.


