Convert HTML URLs to PDF Online
Convert a live HTML URL to PDF with browser rendering, local tools, or an API. Compare JavaScript support, privacy, controls, limits, and automation.

Use a hosted browser-rendering service when you have a live URL and need a PDF that matches what a browser displays. Use a local browser converter when the HTML must stay on your device. Use an HTML-to-PDF API for repeatable jobs, authentication, callbacks, batching, and application integration.
A live URL and raw HTML are different inputs. Before choosing a tool, check whether it accepts a URL, raw markup, or both; whether it executes JavaScript; how it handles fonts and external assets; and what it does with supplied data.
Choose the right conversion method
| Need | Best fit | Trade-offs |
|---|---|---|
| One public page, occasional use | Online URL-to-PDF converter | Fastest setup, limited automation and control |
| Recurring jobs or an application | HTML-to-PDF API | Requires credentials, quota planning, and request handling |
| Supplied HTML must remain local | Browser-local converter | Cannot fetch a live page reliably; remote assets may be blocked |
| Authenticated or JavaScript-heavy pages | Hosted browser API or your own browser automation | Requires cookies, headers, waiting rules, and careful failure handling |
What happens during URL-to-PDF conversion
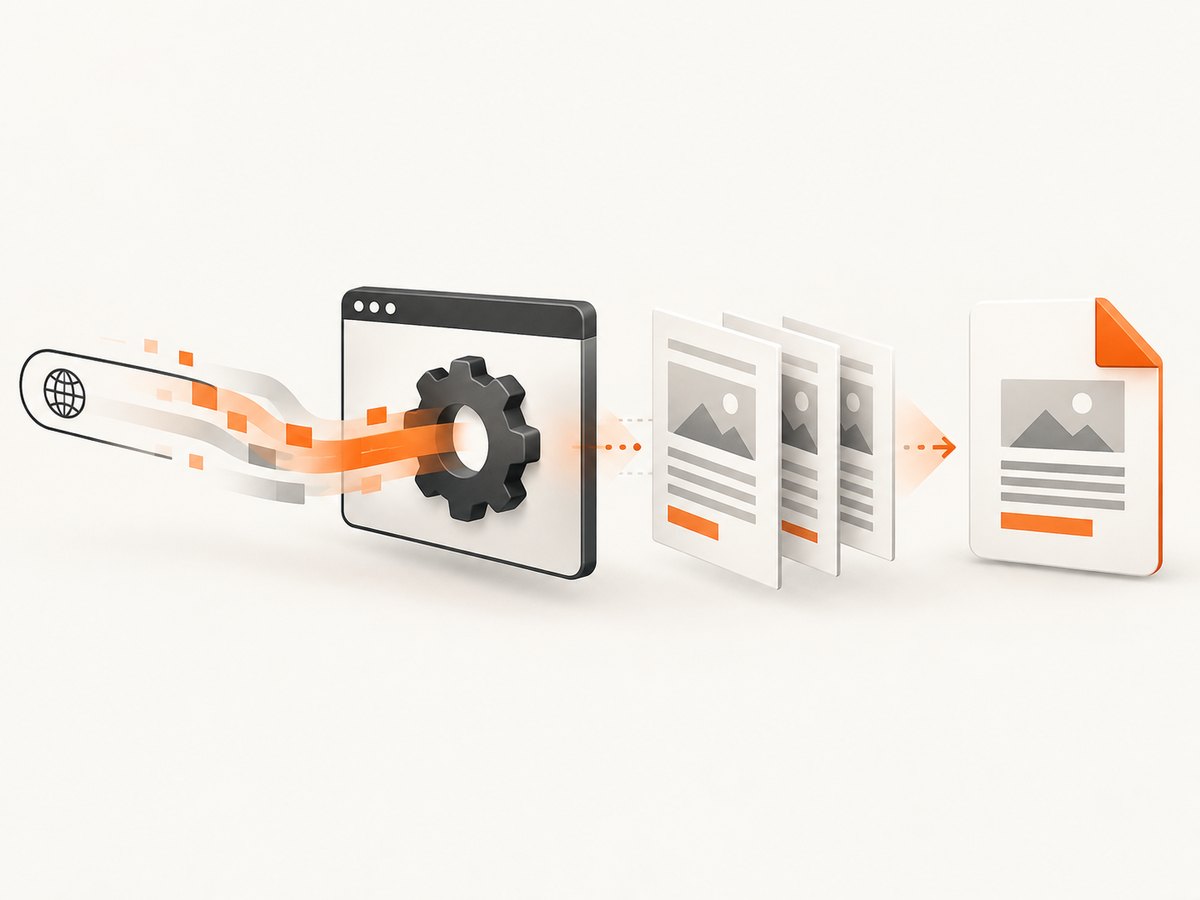
- The converter opens the URL in a browser engine or HTML renderer.
- It loads stylesheets, fonts, images, and scripts that the service permits.
- It waits for a configured condition, such as a selector, a delay, or network idle.
- It applies print settings: paper size, margins, orientation, page ranges, headers, and footers.
- It generates a PDF and returns it synchronously or through an asynchronous job.
Simple HTML-to-PDF libraries can work for static markup, but modern sites often need browser-style rendering. JavaScript may build the page after the initial response, lazy images may load only after scrolling, and authenticated content may require cookies or authorization headers.
Convert a public URL with a browser locally
A local browser keeps the conversion process on your machine. This is useful for privacy-sensitive HTML that you already have, or when you need full control over browser automation. It still sends requests to any external assets referenced by the page.
Node.js and Playwright
Install Playwright and its browser once:
npm install playwright
npx playwright install chromium
Save this as url-to-pdf.mjs:
import { chromium } from 'playwright';

const url = process.argv[2] || 'https://example.com';
const output = process.argv[3] || 'page.pdf';

const browser = await chromium.launch();
const page = await browser.newPage({
  viewport: { width: 1440, height: 900 },
  deviceScaleFactor: 1
});

try {
  await page.goto(url, { waitUntil: 'networkidle', timeout: 90_000 });
  await page.emulateMedia({ media: 'print' });
  await page.pdf({
    path: output,
    format: 'A4',
    printBackground: true,
    margin: { top: '16mm', right: '14mm', bottom: '16mm', left: '14mm' }
  });
  console.log(`Wrote ${output}`);
} finally {
  await browser.close();
}
node url-to-pdf.mjs https://example.com example.pdfPython and Playwright
pip install playwright
playwright install chromium
from pathlib import Path
from playwright.sync_api import sync_playwright
url = 'https://example.com'
output = Path('page.pdf')
with sync_playwright() as p:
browser = p.chromium.launch()
page = browser.new_page(viewport={"width": 1440, "height": 900})
try:
page.goto(url, wait_until='networkidle', timeout=90_000)
page.emulate_media(media='print')
page.pdf(
path=str(output),
format='A4',
print_background=True,
margin={"top": "16mm", "right": "14mm", "bottom": "16mm", "left": "14mm"}
)
finally:
browser.close()
print(f'Wrote {output}') Make the page print correctly
Add print-specific CSS when you control the page:
@media print {
  nav, .cookie-banner, .chat-widget, .ads { display: none !important; }
  a { color: inherit; text-decoration: none; }
  h1, h2, h3 { break-after: avoid; }
  table, img, pre { break-inside: avoid; }
}
For a page you do not control, inject CSS before calling page.pdf():
await page.addStyleTag({ content: `
  .cookie-banner, .chat-widget, .newsletter-modal { display: none !important; }
` });
Convert a URL through an HTML-to-PDF API
An API is usually the better choice when a backend must convert URLs repeatedly. Verify these capabilities before committing:
- URL input versus raw HTML input
- JavaScript execution and browser-like rendering
- CSS injection, custom fonts, and external resources
- Cookies, authorization headers, and user-agent control
- Paper size, margins, orientation, page ranges, headers, and footers
- Request-size and page-count limits
- Synchronous response versus asynchronous jobs and callbacks
- Retention, logging, regional processing, and deletion terms
Documented services and where they fit
| Service | Documented capability | Good fit |
|---|---|---|
| Cloudflare Browser Run | The /pdf endpoint accepts url or html, supports CSS injection, and documents a 50 MB maximum request body. |
Browser rendering integrated with Cloudflare REST or Workers Bindings. |
| Adobe PDF Services | Supports static and dynamic HTML, ZIP, and URL inputs through its PDF Services API, with REST examples and SDK links. | Teams already using Adobe authentication, SDKs, or document workflows. |
| PDFCrowd | Supports URL, HTML-file, and HTML-snippet conversion through HTTP and official SDKs; also offers online, WordPress, Zapier, and Make integrations. | Mixed developer, no-code, and one-off workflows. |
| PDF.co | Provides URL and raw-HTML endpoints, JavaScript processing, custom margins, asynchronous jobs, callbacks, and controls for how fully page loading is awaited. Its raw-HTML documentation states a request limit below 4 MB. | Automations needing callbacks and explicit load controls. |
| Falcon browser-only HTML-to-PDF | Renders supplied HTML in a locked iframe on the user’s computer. It does not fetch a live page by address and blocks external images, fonts, and stylesheets unless assets are embedded. | Local conversion of self-contained HTML. |
Convert a URL with cURL
For an API, save binary output with -o and check the HTTP status. The exact parameters vary by provider, so use the provider’s current API documentation for authentication, PDF format, margins, and waiting options.
curl -X POST 'https://api.example.invalid/pdf' \
  -H 'Authorization: Bearer YOUR_API_KEY' \
  -H 'Content-Type: application/json' \
  --data '{"url":"https://example.com","format":"A4","printBackground":true}' \
  -o page.pdf
Dynamic pages, login sessions, and protected URLs
JavaScript-rendered content
Wait for a page-specific readiness signal instead of assuming the initial HTML is complete:
await page.goto(url, { waitUntil: 'domcontentloaded' });
await page.waitForSelector('[data-report-ready="true"]', { timeout: 60_000 });
await page.pdf({ path: 'report.pdf', printBackground: true });
If no selector exists, use a short delay after the main navigation, but treat delays as a fallback. A fixed delay can be too short on a slow run and waste time on a fast run.
Cookies and authorization
Authenticate before navigation when the page requires a session. Keep credentials out of URLs because URLs are commonly logged.
await context.addCookies([
  { name: 'session', value: process.env.SESSION_COOKIE, domain: 'example.com', path: '/' }
]);
await page.setExtraHTTPHeaders({
  Authorization: `Bearer ${process.env.ACCESS_TOKEN}`
});
Lazy-loaded images
Full-page PDF generation may not trigger every lazy image. Scroll through the document before printing:
await page.evaluate(async () => {
  await new Promise(resolve => {
    let y = 0;
    const step = 600;
    const timer = setInterval(() => {
      window.scrollBy(0, step);
      y += step;
      if (y >= document.body.scrollHeight) {
        clearInterval(timer);
        window.scrollTo(0, 0);
        resolve();
      }
    }, 100);
  });
});
Privacy and sensitive HTML
Hosted conversion sends the URL or HTML to a service. A URL can reveal private paths, query parameters, or document identifiers even when the page itself is protected. Review retention and logging terms before sending confidential material.
Local conversion can keep supplied HTML on-device, but the browser may still request remote images, fonts, scripts, analytics, and stylesheets. To keep processing local, embed required assets and disable network access where your browser tooling supports it.
Page size, margins, fonts, and layout controls
- Paper: A4 and Letter are common defaults; use a custom width and height for receipts or long-form reports when supported.
- Margins: Set them explicitly. Browser default margins can create unexpected whitespace.
- Orientation: Use landscape for wide tables and dashboards.
- Backgrounds: Enable print backgrounds when color panels or charts matter.
- Fonts: Wait for
document.fonts.readyand ensure the renderer can reach the font files. - Page breaks: Use
break-before,break-after, andbreak-insidein print CSS. - Page ranges: Generate only required pages when an API supports ranges; this reduces transfer size and processing time.
await page.evaluate(() => document.fonts.ready);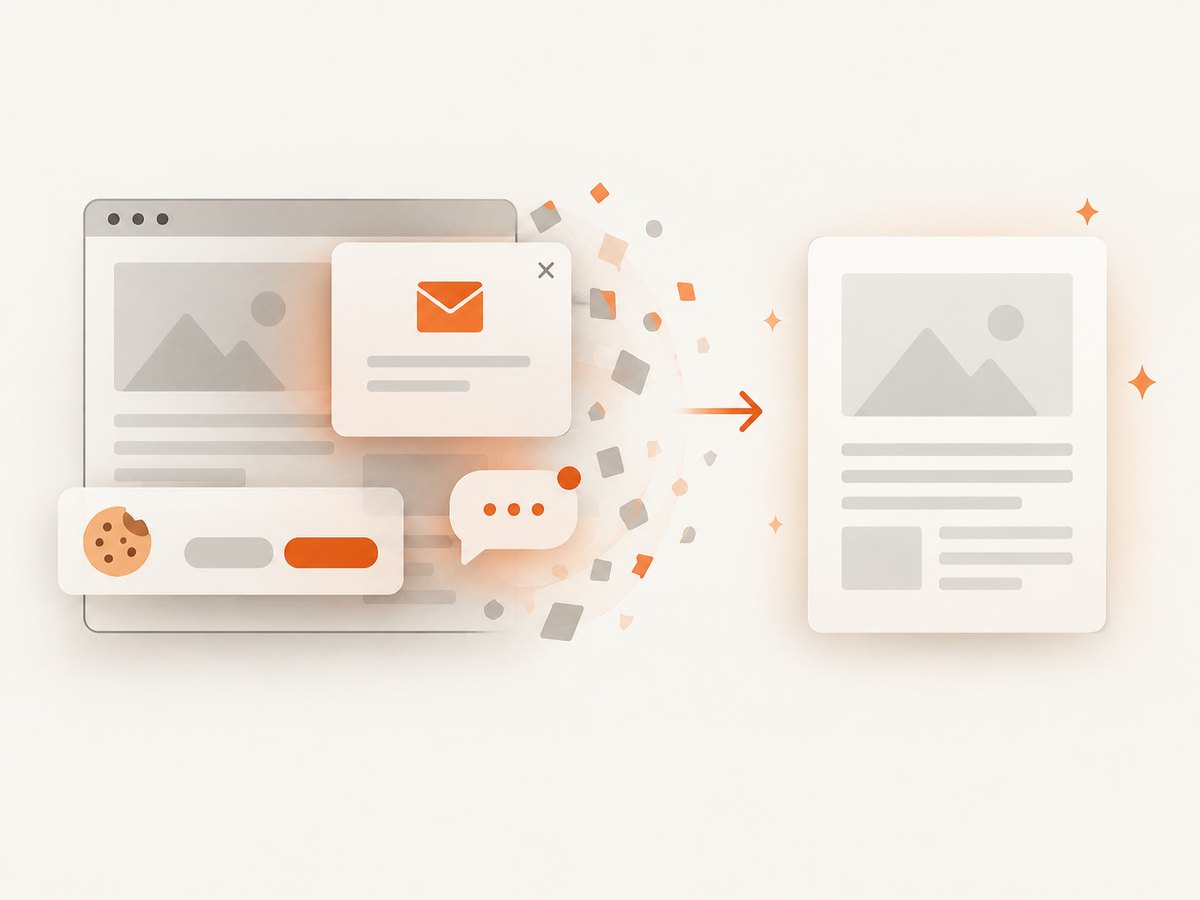
Or skip the browser setup
ScreenshotNeo provides a hosted browser-rendering API for website captures, including PDF output. Its API can handle full-page rendering, custom waiting rules, cookies, headers, authorization, timezone, geolocation, custom CSS and JavaScript, and PDF paper size, margins, landscape mode, and page ranges. See the ScreenshotNeo API documentation for the current parameters.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. An MCP server lets AI agents use take_screenshot, get_page_info, and capture_pdf. The Free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000.
Create a free ScreenshotNeo account and start with the included 1,000 screenshots.
Performance, reliability, and cost
Performance
- Prefer a readiness selector or network-idle rule over an unnecessarily long fixed delay.
- Reuse a browser process in self-hosted automation instead of launching Chromium for every URL.
- Reduce page work by blocking analytics, ads, and nonessential resources when the PDF does not need them.
- Use asynchronous jobs for slow pages, large documents, or high-volume queues.
- Cache stable URLs and invalidate the cache when source content changes.
Reliability
- Set a timeout and retry only transient failures.
- Use idempotency keys or job identifiers when a provider supports them.
- Record the source URL, conversion settings, status code, and failure reason.
- Validate that the response is a PDF before storing it; an HTML error page can otherwise be saved with a
.pdfextension. - For authenticated pages, refresh expired cookies and avoid sharing one session across unrelated jobs.
Cost
Compare per-document pricing, included quota, overage rates, browser time, storage, callback fees, and the cost of retries. A provider that does not charge failed loads can be cheaper for unreliable public pages than one that bills every request. Also account for bandwidth when PDFs contain large images or embedded fonts.
Troubleshooting
| Problem | Likely cause | Fix |
|---|---|---|
| PDF is blank | JavaScript has not finished, navigation failed, or the page requires a session. | Wait for a readiness selector, inspect the final URL and status, and provide the required cookies or headers. |
| Charts or content are missing | Lazy loading or canvas rendering occurs after the initial load. | Scroll the page, wait for the chart container, and enable print backgrounds. |
| Fonts look wrong | Font files are blocked, cross-origin access fails, or printing starts before fonts load. | Make fonts reachable, embed them when appropriate, and wait for document.fonts.ready. |
| Cookie banner covers content | The page requires consent before showing the main layout. | Accept or remove the banner before capture, or inject print CSS that hides it. |
| Login redirects to a sign-in page | Cookies expired or authorization headers were not sent. | Create a fresh session, set cookies before navigation, and verify the final URL. |
| Request times out | Slow third-party resources, a never-ending connection, or an overloaded page. | Block nonessential resources, use a specific readiness condition, and increase the timeout within provider limits. |
| Output is clipped | Fixed-height containers, overflow rules, or unsuitable page size. | Remove print-time fixed heights, set overflow to visible where needed, and choose a larger paper size or landscape orientation. |
| Images are missing | External assets are blocked, URLs require authentication, or lazy images were never triggered. | Allow the asset hosts, pass authentication, embed assets for local conversion, or scroll before printing. |
| API returns an HTML error instead of a PDF | Authentication, validation, quota, or upstream browser failure. | Check status and content type, log the response body safely, and fix the reported request error before saving the file. |
Conversion checklist
- Confirm whether the input is a live URL or raw HTML.
- Confirm JavaScript execution and external-resource behavior.
- Test an authenticated page if production pages require login.
- Set paper size, margins, orientation, backgrounds, and page ranges explicitly.
- Wait for a selector or other reliable readiness signal.
- Check request-size, timeout, quota, retention, and callback limits.
- Validate status code and content type before storing the PDF.
- Run representative pages with tables, images, charts, custom fonts, and long content.
FAQ
Can I convert a URL to PDF without downloading the HTML first?
Yes. A hosted browser-rendering API or online converter can fetch the URL and return the PDF. A local converter normally needs the page to be opened by your local browser.
Will a URL-to-PDF service execute JavaScript?
Only if its renderer supports JavaScript and its waiting behavior allows scripts to finish. Confirm this before using it for single-page applications or dashboards.
Is converting a URL to PDF private?
Hosted conversion sends the URL or HTML to the provider. Local conversion keeps supplied markup on your machine, but external resources may still be requested unless assets are embedded or network access is restricted.
Why does the PDF differ from the browser window?
PDF generation uses print media rules, paper dimensions, margins, and pagination. Compare the page under print preview and add explicit print CSS for layout-sensitive content.
Should I use synchronous or asynchronous conversion?
Synchronous requests are convenient for short pages. Use asynchronous jobs and callbacks when rendering can be slow, files are large, or the workflow processes many URLs.
Can I convert private URLs?
Yes when the converter supports cookies, authorization headers, or another access method. Do not place secrets in query strings, and review the provider’s data-retention terms.


