How to Convert a Webpage URL to PDF in Ruby
Convert any webpage URL to a PDF in Ruby with Grover, PDFKit, or Rails integrations, with complete code, options, troubleshooting, and a hosted alternative.
Direct answer: The most capable Ruby approach for modern webpages is Grover, a Ruby wrapper around Puppeteer and Chromium. Pass the URL to Grover.new, set PDF options such as paper size, and call to_pdf. Grover handles JavaScript-rendered pages, but your deployment must include Node.js, Puppeteer, and a Chromium browser.
For older Rails applications, PDFKit and Wicked PDF are alternatives built around the wkhtmltopdf executable. They can work well for simple HTML, but their rendering engine is Qt WebKit and the upstream wkhtmltopdf repository has been archived. This guide shows the complete setup, URL and HTML workflows, page options, authentication, asset handling, Rails integration, troubleshooting, and a hosted option when you do not want to operate a browser runtime.
1. Choose a Ruby PDF approach
| Approach | Best fit | Runtime requirement | Main caveat |
|---|---|---|---|
| Grover | Modern JavaScript sites and standalone Ruby | Ruby, Node.js, Puppeteer, Chromium | Browser deployment adds memory and startup work |
| PDFKit | Small Ruby apps using existing wkhtmltopdf infrastructure | Ruby and wkhtmltopdf executable | Executable must be installed and discoverable |
| Wicked PDF | Rails views and controller responses | Rails and wkhtmltopdf | Asset URLs must be available outside Rails |
| FerrumPdf | Projects already using Ferrum | Ruby browser integration and Chromium | Check compatibility for your exact application |
There is no source-backed benchmark proving that one library is universally faster or more faithful. Evaluate your own pages, fonts, JavaScript, and deployment limits. Grover is generally the clearest starting point when the source page depends on current browser behavior.
2. Convert a URL with Grover
Install the Ruby gem and browser dependency
# Gemfile
gem 'grover'
Install the bundle, then install Puppeteer as described by the Grover project:
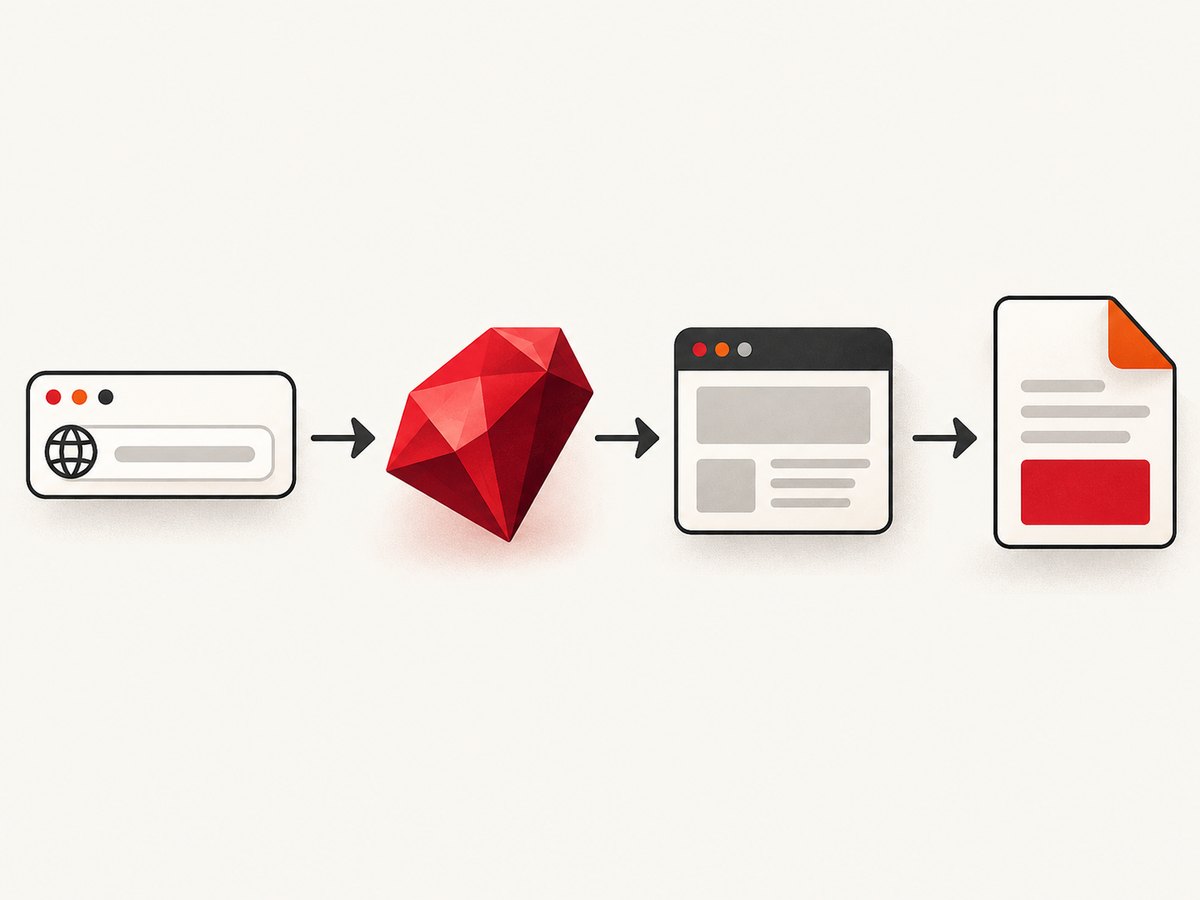
bundle install
npm install puppeteer
The browser executable must be available to the process that runs your Ruby application. In containers and CI, install Chromium during the image build and make sure the user running Ruby can execute it.
Minimal URL-to-PDF script
require 'grover'

url = ARGV.fetch(0, 'https://example.com')
pdf = Grover.new(url, format: 'A4').to_pdf

File.binwrite('page.pdf', pdf)
puts 'Wrote page.pdf'
to_pdf returns PDF bytes. Writing in binary mode matters on platforms where text mode can alter line endings. The format: 'A4' option selects the paper size; you can use another Puppeteer-supported format or provide explicit dimensions.
Useful PDF options
options = {
  format: 'A4',
  landscape: false,
  print_background: true,
  margin: {
    top: '16mm',
    right: '12mm',
    bottom: '16mm',
    left: '12mm'
  },
  display_header_footer: false,
  prefer_css_page_size: true
}

pdf = Grover.new('https://example.com', options).to_pdf
File.binwrite('page.pdf', pdf)
Option names follow Puppeteer PDF options through Grover. Verify the names against the version installed in your application because wrapper versions can differ. Common choices include:
format: standard paper sizes such as A4 or Letter.widthandheight: explicit dimensions when a custom page is required.landscape: rotate the page orientation.margin: top, right, bottom, and left values with CSS units.print_background: include background colors and images.page_ranges: export selected pages, such as1-3.prefer_css_page_size: honor CSS@pagedimensions when present.display_header_footer,header_template, andfooter_template: add print headers and footers when supported by your installed Puppeteer version.
3. Control print styles, fonts, and page breaks
Puppeteer generates PDFs using the print media type by default and waits for fonts to load. If your stylesheet has separate screen and print rules, the PDF may intentionally differ from the browser view. To use screen styles, emulate the screen media type before calling PDF generation. Grover exposes browser and page configuration through its options and middleware; check its documentation for the exact hook syntax for your version.
For predictable pagination, add print CSS to the page:
@page {
  size: A4;
  margin: 16mm 12mm;
}

.keep-together {
  break-inside: avoid;
}

.page-break {
  break-before: page;
}

@media print {
  nav, .cookie-banner, .chat-widget {
    display: none !important;
  }
}
Long tables, flex layouts, and elements with fixed heights are common sources of clipped content. Prefer normal document flow, allow table rows to break where appropriate, and test pages containing unusually long text.
4. Convert HTML instead of a public URL
Grover can render an HTML string, which is useful for invoices, reports, and Rails views. Relative assets need special care. When raw HTML has relative CSS, images, or fonts, Chromium resolves them against a display URL. Grover documents that the default display URL is http://example.com; provide a suitable display URL or convert asset paths to absolute URLs.
require 'grover'

html = <<~HTML
  <!doctype html>
  <html>
    <head>
      <meta charset="utf-8">
      <style>body { font-family: sans-serif; }</style>
    </head>
    <body>
      <h1>Monthly report</h1>
      <p>Generated at #{Time.now.utc}</p>
    </body>
  </html>
HTML

pdf = Grover.new(
  html,
  format: 'A4',
  display_url: 'https://your-app.example/reports/'
).to_pdf

File.binwrite('report.pdf', pdf)
For local images and fonts, use absolute HTTPS URLs, data URLs, or a display URL whose host can serve the assets. Ensure the rendering process can reach private asset hosts from its network.
5. Rails: render a view and return a PDF
Render the view to a string, pass the resulting HTML to Grover, and send the bytes with the PDF content type:
class ReportsController < ApplicationController
  def show
    html = render_to_string(
      template: 'reports/show',
      formats: [:html],
      locals: { report: Report.find(params[:id]) }
    )

    pdf = Grover.new(
      html,
      format: 'A4',
      display_url: report_url(params[:id])
    ).to_pdf

    send_data pdf,
      filename: "report-#{params[:id]}.pdf",
      type: 'application/pdf',
      disposition: 'inline'
  end
end
If your template references the Rails asset pipeline, ensure the generated URLs are absolute and reachable from the browser process. A request that works in a normal browser can fail in a container if DNS, authentication, or internal networking differs.
6. PDFKit and Wicked PDF with wkhtmltopdf
PDFKit wraps the wkhtmltopdf command-line program:
# Gemfile
gem 'pdfkit'
require 'pdfkit'

kit = PDFKit.new('https://example.com', page_size: 'A4')
File.binwrite('page.pdf', kit.to_pdf)
The gem alone is insufficient. Install the wkhtmltopdf executable and configure its path when it is not found automatically. PDFKit can also accept HTML or a local file. Its root_url and protocol options help resolve relative assets, but stylesheet handling differs when the input itself is a URL or file.
Wicked PDF adds Rails conventions around the same executable:
# Gemfile
gem 'wicked_pdf'
def invoice
  respond_to do |format|
    format.html
    format.pdf do
      render pdf: 'invoice',
             template: 'invoices/show',
             page_size: 'A4',
             print_media_type: true
    end
  end
end
Wicked PDF’s documentation warns that wkhtmltopdf runs outside the Rails application. Use absolute references for CSS, JavaScript, and images. The upstream wkhtmltopdf repository was archived on January 2, 2023 and is read-only, which is a maintenance consideration for new systems.
7. Authentication, JavaScript, and dynamic pages
- Authenticated pages: pass cookies or authorization headers through the browser configuration supported by your chosen wrapper, or render server-side HTML with the required data.
- JavaScript data: wait for the page’s application state to finish loading before PDF generation. A fixed delay is less reliable than waiting for a specific selector when your wrapper supports it.
- Fonts: host fonts where Chromium can reach them and wait for font loading. Missing fonts change line wrapping and page count.
- External APIs: make sure outbound requests are allowed from the worker or container. Timeouts often come from blocked DNS, private networks, or API calls that never resolve.
- Cookies and consent: provide the right cookie state when the page would otherwise show a consent wall or hide content.
8. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
Browser was not found |
Puppeteer or Chromium is not installed in the runtime image. | Install the documented Puppeteer dependency, include Chromium in the deploy image, and configure the executable path if required. |
| PDF contains a blank page | The page has not finished rendering, or navigation failed. | Check application logs, wait for a stable selector, and verify DNS and outbound access from the worker. |
| CSS or images are missing | Relative URLs resolve against the wrong host, or assets require authentication. | Use absolute URLs, set a display URL for HTML input, and provide the required cookies or headers. |
| Screen layout differs from PDF | Print media rules are active by default. | Review @media print; emulate screen media when screen styling is the requirement. |
| Text overlaps or is clipped | Fixed heights, unsupported CSS, or a browser-specific layout. | Remove rigid heights, simplify problematic layout rules, and add print-specific CSS. |
wkhtmltopdf executable not found |
PDFKit or Wicked PDF cannot locate the binary. | Install the executable and set the configured binary path. |
| Rails assets work locally but not in production | The external browser cannot reach local or relative asset URLs. | Generate absolute asset URLs and confirm network access from the rendering process. |
9. Performance, reliability, and cost
Browser PDF generation consumes substantially more memory than string formatting because a Chromium process loads the page, JavaScript, fonts, and images. Reuse a browser process where your integration supports it, limit concurrency to the memory available on the worker, and place conversion jobs in a background queue for user-triggered reports. Set navigation and rendering timeouts so one broken page cannot occupy a worker indefinitely.
For reliability, record the source URL, rendering options, browser version, duration, and failure reason. Retry transient network failures with a limit, but do not repeatedly retry deterministic errors such as an invalid URL or missing executable. Store generated PDFs in object storage when they need to be downloaded later instead of keeping large byte strings in application memory.
Ruby libraries and open-source executables do not remove infrastructure costs: account for browser memory, worker time, container image size, and maintenance. The research sources do not provide controlled speed, fidelity, or cost benchmarks, so measure representative pages in your own environment.
10. Or skip the browser setup
ScreenshotNeo provides a hosted website capture API that can return a PDF from one GET request. It handles the browser runtime for you and exposes options for paper size, margins, landscape mode, and page ranges. See the ScreenshotNeo documentation for the complete parameter list.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://example.com \
  -d format=pdf \
  -o page.pdf
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={
        "access_key": "YOUR_API_KEY",
        "url": "https://example.com",
        "format": "pdf",
    },
    timeout=90,
)
r.raise_for_status()
open("page.pdf", "wb").write(r.content)
Node.js
const fs = require('node:fs/promises');

const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://example.com',
  format: 'pdf'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
await fs.writeFile('page.pdf', Buffer.from(await res.arrayBuffer()));
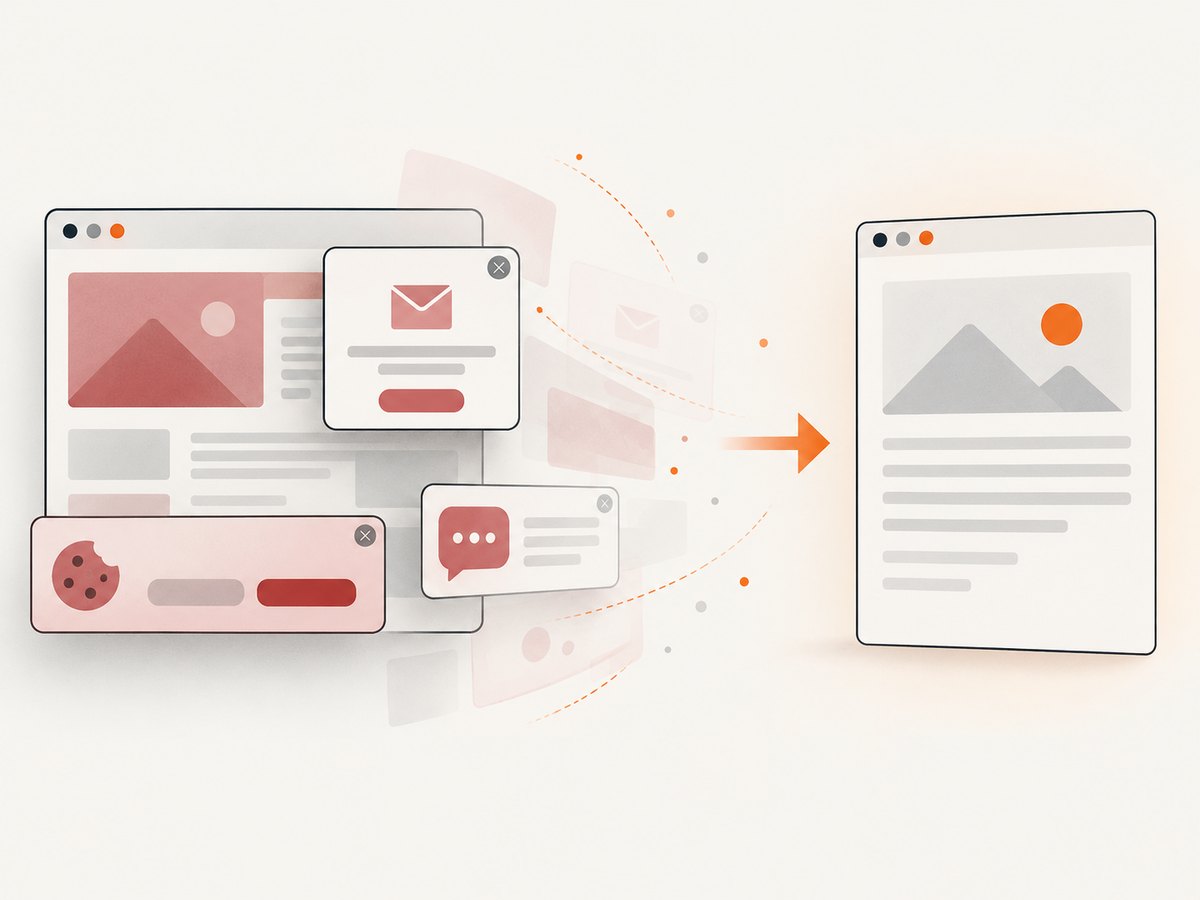
ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed; response headers identify the page verdict and billing status. It also offers custom headers, cookies, user agents, authorization, JavaScript, CSS, selector capture, waiting rules, blocking controls, caching, signed links, asynchronous jobs, webhooks, bulk capture, and an MCP server for AI agents.
There are 1,000 free screenshots per month with no card. Paid plans start at $5 for 3,000 screenshots, and every feature is available on every plan. Create a free ScreenshotNeo account.
11. Ruby PDF conversion checklist
- Choose Grover for current browser behavior or an existing wkhtmltopdf integration.
- Install every runtime dependency in the same image or host that runs Ruby.
- Use absolute asset URLs or configure a display URL for HTML input.
- Decide whether print or screen media should control the layout.
- Set paper size, margins, orientation, backgrounds, and page ranges explicitly.
- Wait for dynamic content and fonts before generating the PDF.
- Log failures and keep browser concurrency within available memory.
- Test long tables, missing images, authenticated pages, and pages with consent banners.
FAQ
Can Ruby convert a URL to PDF without Rails?
Yes. Grover and PDFKit both support standalone Ruby scripts. Rails is only needed for integrations such as rendering a controller view.
Does Grover require Node.js?
Yes. Grover wraps Puppeteer, so deploy Node.js, Puppeteer, and a compatible Chromium runtime alongside the Ruby application.
Why is my PDF different from the browser screenshot?
PDF generation uses print media by default, and print CSS can change visibility, spacing, and page breaks. Review print rules or emulate screen media when appropriate.
Should a new project use wkhtmltopdf?
It can be reasonable when your organization already operates it, but the upstream repository is archived. Evaluate maintenance and rendering requirements before choosing it for new work.
Can I convert a private URL?
With a self-hosted browser, provide the required network access, cookies, or authorization headers. With a hosted API, confirm that the service can reach the URL and configure supported authentication options.


