How to Use CSS Selectors in Node.js for Web Scraping
Learn to select and extract web page data with Cheerio and Puppeteer in Node.js, with runnable examples, selector patterns, and fixes for common errors.
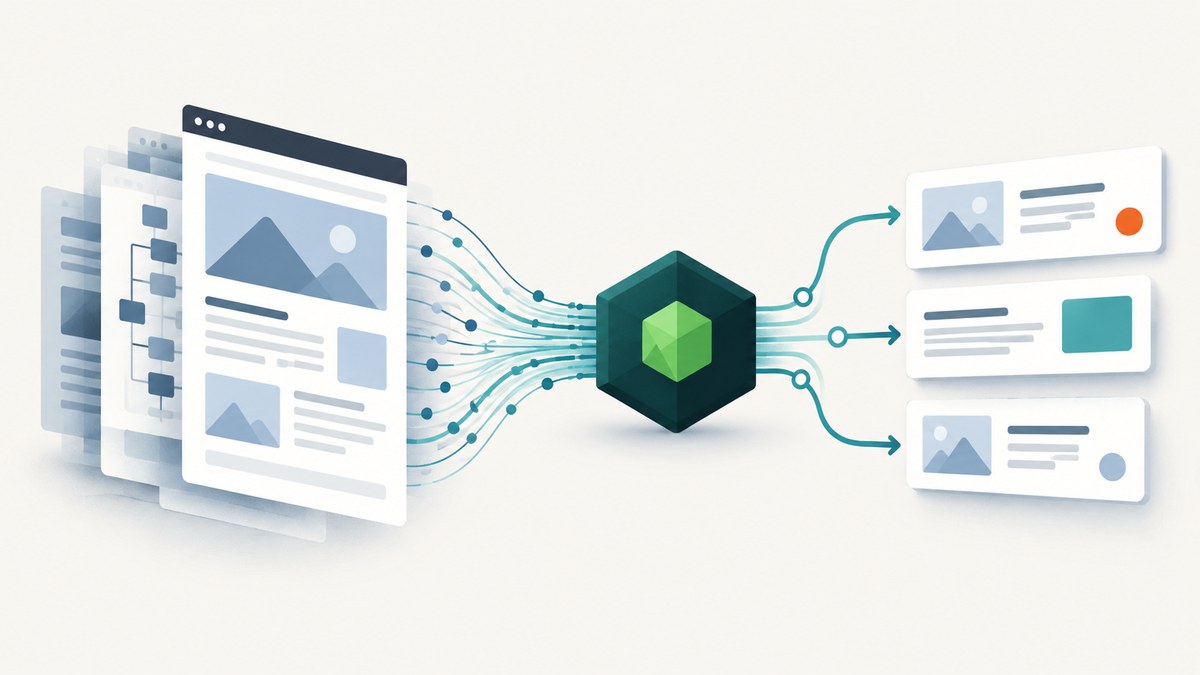
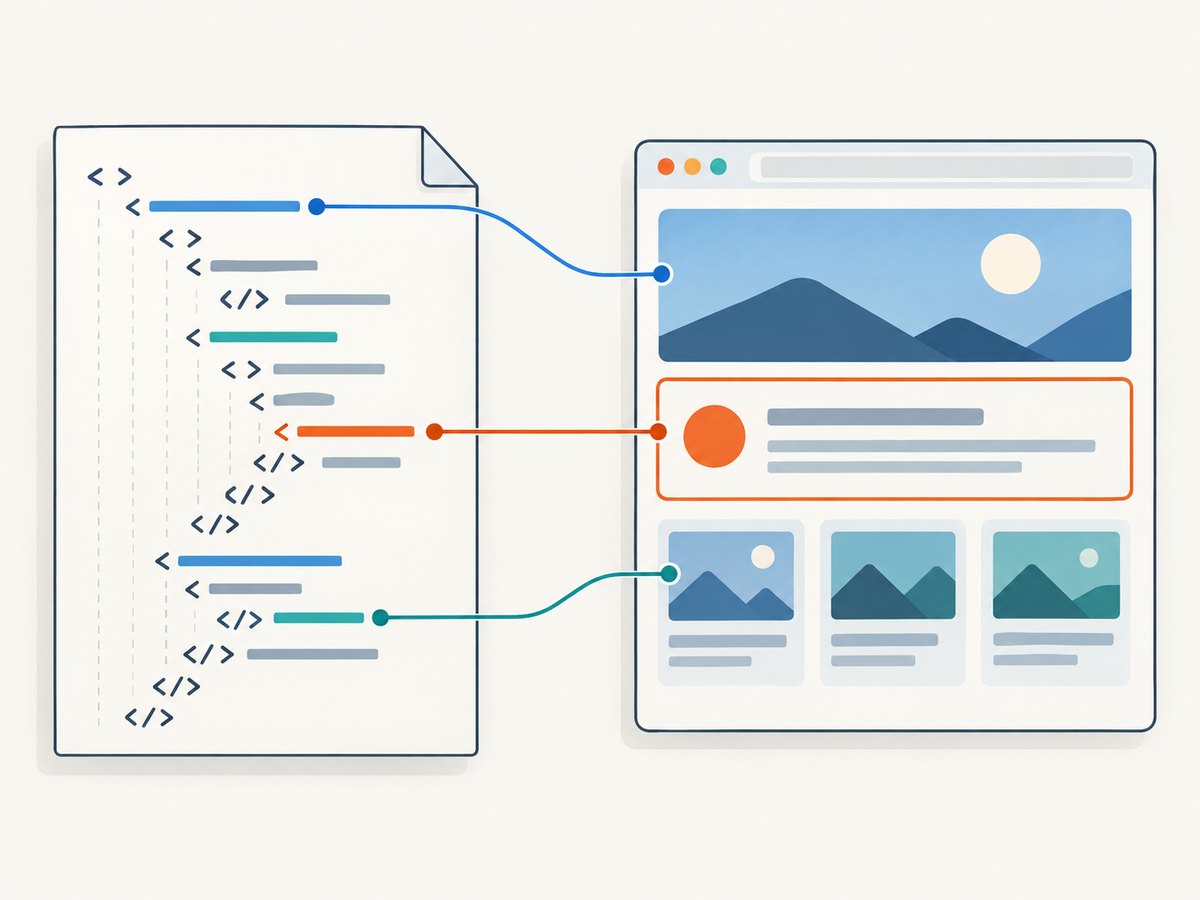
CSS selectors describe which elements to match in a document. In Node.js, use Cheerio to query HTML you have already loaded, or use Puppeteer when you need to query a page running in a browser. A selector does not fetch a page, execute its JavaScript, or extract a complete record by itself: first obtain the document, then select elements, then read their text or attributes.
This guide builds a working Cheerio scraper, explains common selectors and extraction patterns, shows when browser-based querying is useful, and covers errors and operational concerns.
1. Install Cheerio and run a scraper
Start with a Node.js project and install Cheerio. The following example fetches a page with Node’s built-in fetch, checks the HTTP response, loads its HTML, and extracts article titles and links. Change the target URL and selectors to match a page you are permitted to access.
mkdir selector-scraper
cd selector-scraper
npm init -y
npm install cheerio
Save this as scrape.mjs and run node scrape.mjs. The page’s structure is only an example: inspect the actual markup and adapt article h2 and a to the document you receive.
import * as cheerio from 'cheerio';

const url = 'https://example.com/';
const response = await fetch(url, {
  headers: { 'user-agent': 'Example research scraper/1.0' },
});

if (!response.ok) {
  throw new Error(`Request failed: ${response.status} ${response.statusText}`);
}

const contentType = response.headers.get('content-type') ?? '';
if (!contentType.includes('text/html')) {
  throw new Error(`Expected HTML, received ${contentType || 'unknown content type'}`);
}

const html = await response.text();
const $ = cheerio.load(html);

const records = $('article').map((_, article) => {
  const card = $(article);
  const link = card.find('h2 a').first();
  const href = link.attr('href');

  return {
    title: link.text().trim(),
    url: href ? new URL(href, url).href : null,
    summary: card.find('p').first().text().trim(),
  };
}).get();

console.log(JSON.stringify(records, null, 2));
The selector chooses matching nodes; .text() and .attr() read values from them. .map() builds one output record per article and .get() converts the Cheerio collection into a regular array. An absent link produces null rather than a broken URL. For dependable extraction, explicitly decide what should happen when each expected field is missing.
2. Read and combine CSS selectors
Cheerio’s $ function accepts selectors and returns a collection. These familiar forms cover most scraping tasks:
| Selector | What it matches | Example |
|---|---|---|
p |
Every paragraph element | $('p') |
.price |
Elements with the class | $('.price') |
#main |
The element with that ID | $('#main') |
[data-kind="note"] |
Elements with a matching attribute value | $('[data-kind="note"]') |
article h2 |
Any matching heading inside an article | $('article h2') |
article > h2 |
A heading that is a direct child | $('article > h2') |
h1, h2 |
Either heading type | $('h1, h2') |
p.notice |
A paragraph that also has the class | $('p.notice') |
Spaces and combinators express different relationships. A space means descendant: div p includes paragraphs nested at any depth inside a div. A greater-than sign means direct child: div > p excludes paragraphs inside a nested list. The plus sign selects the immediately following sibling, as in h2 + p; the tilde selects later siblings under the same parent, as in h2 ~ p. A comma separates alternatives. Writing selectors together, such as p.notice, requires one element to satisfy both conditions.
Prefer a short selector tied to meaningful markup when possible. A long chain can break when a site adds a wrapper or rearranges layout. Inspect the received HTML and check the selector’s match count before relying on it. A class, ID, or data attribute is useful only if the target page actually has it and your selector matches the intended elements.
3. Extract text, attributes, and structured records
Selection and extraction are separate steps. .text() returns text from the selected element and its descendants; .attr('href') reads an attribute. Normalize values deliberately, and resolve relative URLs against the page address when you need absolute links.

const $ = cheerio.load(`
  <article>
    <h2><a href="/guide">  A guide </a></h2>
    <span class="price">$12</span>
    <span class="stock" data-state="available">In stock</span>
  </article>
`);

const article = $('article').first();
const title = article.find('h2 a').text().trim();
const relativeHref = article.find('h2 a').attr('href');
const price = article.find('.price').text().trim();
const availability = article.find('.stock').attr('data-state') ?? null;
const link = relativeHref ? new URL(relativeHref, 'https://example.com').href : null;

console.log({ title, price, availability, link });
Use .first() when you need one result from a collection. Test whether the element exists before assuming an attribute is present. If multiple values are expected, map them into an array rather than reading only the first match. Cheerio also provides traversal methods for moving between ancestors, descendants, and siblings; use them when the field you want is related structurally to a selected element. See the Cheerio traversal guide.
Cheerio’s extract method can describe a data shape using selectors, which is convenient when many fields follow a repeatable structure. For a small scraper, explicit selection often makes missing-field handling easier to see. In either style, validate the resulting values before saving or using them downstream.
4. Use Cheerio-only selector extensions carefully
Cheerio supports many standard CSS selectors and also documents extensions such as :contains(), :first, :last, and :eq(n). For example, li:eq(1) selects the second matching list item because the index is zero-based. These extensions can be convenient within Cheerio, but they are not all standard CSS and should not be assumed to work in browser APIs or other selector engines.
const $ = cheerio.load('<ul><li>Apple</li><li>Banana</li></ul>');
console.log($('li:contains("Ban")').text());
console.log($('li:eq(1)').text());
When code may move between Cheerio and a browser, stick to portable selectors such as tags, classes, IDs, attributes, combinators, and selector lists. Check the selector engine’s documentation for its supported pseudo-classes rather than assuming every feature is shared.
5. Choose Cheerio or Puppeteer based on the document
Cheerio queries markup that your code loaded. It is a good fit when the response HTML already contains the fields you need. It does not behave as a full browser page: a selector cannot make a site’s client-side application render missing content. When a page’s content depends on browser execution or you need browser interactions, use a browser automation tool such as Puppeteer and select against the page it exposes.
Puppeteer’s page.locator(selector) accepts CSS selectors and also supports Puppeteer-specific selector syntax for other query types. Here is a minimal browser example that opens a page and reads text from a matching element:
import puppeteer from 'puppeteer';

const browser = await puppeteer.launch({ headless: true });
try {
  const page = await browser.newPage();
  await page.goto('https://example.com/', { waitUntil: 'domcontentloaded' });
  const heading = await page.locator('h1').map(element => element.textContent).wait();
  console.log(heading?.trim() ?? 'No h1 found');
} finally {
  await browser.close();
}
Use browser DOM methods when you are already executing code in the page context: document.querySelector(selector) returns the first matching element or null; document.querySelectorAll(selector) returns all matches. Invalid selector syntax raises a SyntaxError. In Puppeteer, locators operate on a browser page, while Cheerio collections operate on loaded markup. Choose the context that contains the data you need.
6. Troubleshoot selectors and extraction
| Symptom | Likely cause | What to do |
|---|---|---|
| Zero matches | The received markup does not have the assumed structure, or the content is created later by browser code. | Inspect the actual response HTML; check the selector and match count. If the content requires a running page, use a browser context. |
| Too many matches | A descendant selector reaches nested content, or the selector is too broad. | Scope it to a containing element or use > when only direct children should match. |
| Wrong text or duplicated text | .text() includes descendant text, possibly from nested labels or hidden markup. |
Select a narrower node and inspect its HTML. Normalize whitespace only after deciding which text belongs in the field. |
| Missing URL or attribute | The selected element lacks that attribute, or the link is relative. | Check the element and attribute name; guard missing values and resolve relative URLs with new URL(href, baseUrl). |
| Selector syntax error | Malformed CSS or an identifier containing characters that need escaping. | Correct the selector. In browser code, use CSS.escape(value) for dynamic class or ID components. |
| Cheerio works but browser code fails | The selector uses a Cheerio-specific extension. | Replace it with standard CSS or use an API supported by the browser selector context. |
| HTML fetch fails | Network failure, non-success HTTP status, or a non-HTML response. | Check the URL, status, content type, and network error separately from selector logic. |
MDN notes that querySelector() requires a valid CSS selector string and that invalid identifiers in class or ID values must be escaped before using them in a selector. That matters especially when building selectors from scraped or user-provided values. Do not concatenate arbitrary text into a selector without escaping it.
7. Reliability, performance, and operating costs
A scraper has at least two distinct failure points: obtaining the document and interpreting its structure. Log the requested URL, HTTP status, content type, and number of matched records so an empty result is distinguishable from a failed fetch. For recurring jobs, make extraction tolerant of optional fields, but fail visibly when required fields disappear; silently writing empty records can hide a site redesign.
Keep request and browser concerns separate from selectors. Add appropriate timeouts and retry handling for transient network failures, and use bounded concurrency when processing multiple pages so the job does not create an uncontrolled burst of requests. Respect the target site’s rules and access restrictions. A browser may take more setup and resources than parsing markup because it must run a page, but there is no universal speed or cost figure: workload, page behavior, and hosting determine the result. Measure your own pipeline rather than assuming a benchmark.
Selectors themselves are inexpensive expressions compared with fetching a page or running a browser, but broad selectors can produce large collections and unnecessary downstream work. Scope queries to the smallest relevant container, extract only needed fields, and avoid launching a browser when the response HTML already contains the data. For large jobs, track memory use and process results in batches rather than retaining every page and record indefinitely.
8. Or skip the browser setup
If the goal is to capture a page visually rather than build a browser pipeline, ScreenshotNeo provides a website screenshot API and MCP server. A single GET request can return a PNG, JPEG, WebP, or PDF. It is a screenshot service, so it does not replace Cheerio when you need structured fields from HTML; it is useful when your deliverable is a screenshot or PDF.
For a single-call capture, see the ScreenshotNeo API documentation:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://example.com \
  -o shot.webp
import requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://example.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({
access_key: 'YOUR_API_KEY',
url: 'https://example.com',
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
await Bun.write('shot.webp', res);With Node.js, save the response body using Node’s filesystem API if you are not using Bun:
import { writeFile } from 'node:fs/promises';
const bytes = Buffer.from(await res.arrayBuffer());
await writeFile('shot.webp', bytes);- Cookie and consent banners, newsletter popups, and chat widgets can be removed before capture, with each step configurable.
- Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed; response headers identify the page verdict and billing status.
- An MCP server offers
take_screenshot,get_page_info, andcapture_pdftools for AI agents and MCP clients. - The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Every feature is on every plan.
Create a free ScreenshotNeo account and get 1,000 screenshots a month with no card.
9. Frequently asked questions
Do CSS selectors download a web page?
No. A selector matches elements in a document that your code already has. Fetch the response or open a browser page first.
Should I learn XPath instead?
Use the query language supported by your chosen tool and the structure you need to express. The examples here use CSS because both Cheerio and browser APIs accept common CSS selectors.
Can a selector identify a field reliably forever?
No selector can guarantee that a site will preserve its markup. Check results and validate important fields whenever your scraper runs.
Can I use Cheerio to make a screenshot?
Cheerio parses markup and provides selection and traversal methods; it does not render a page like a browser. Use a browser-based workflow or a screenshot API for visual output.
10. A practical checklist
- Confirm whether the required content exists in fetched HTML or needs browser execution.
- Inspect the document and select a meaningful container before extracting individual fields.
- Choose descendant, child, sibling, and comma selectors based on the actual relationship.
- Read text and attributes explicitly, guard missing values, and resolve relative links.
- Check status, content type, selector counts, and required output fields.
- Use standard CSS when selectors must work across Cheerio and browser APIs.
The core workflow is simple: acquire a document, select the elements that contain your data, then extract and validate each field. Keeping those stages separate makes it easier to tell whether a problem comes from the request, the page context, the selector, or the data shape.