How to Design Effective Web Scraper Input Schemas
Design scraper inputs as a clear contract: choose useful fields, defaults, validation rules, and UI controls, with runnable Apify and Python examples.
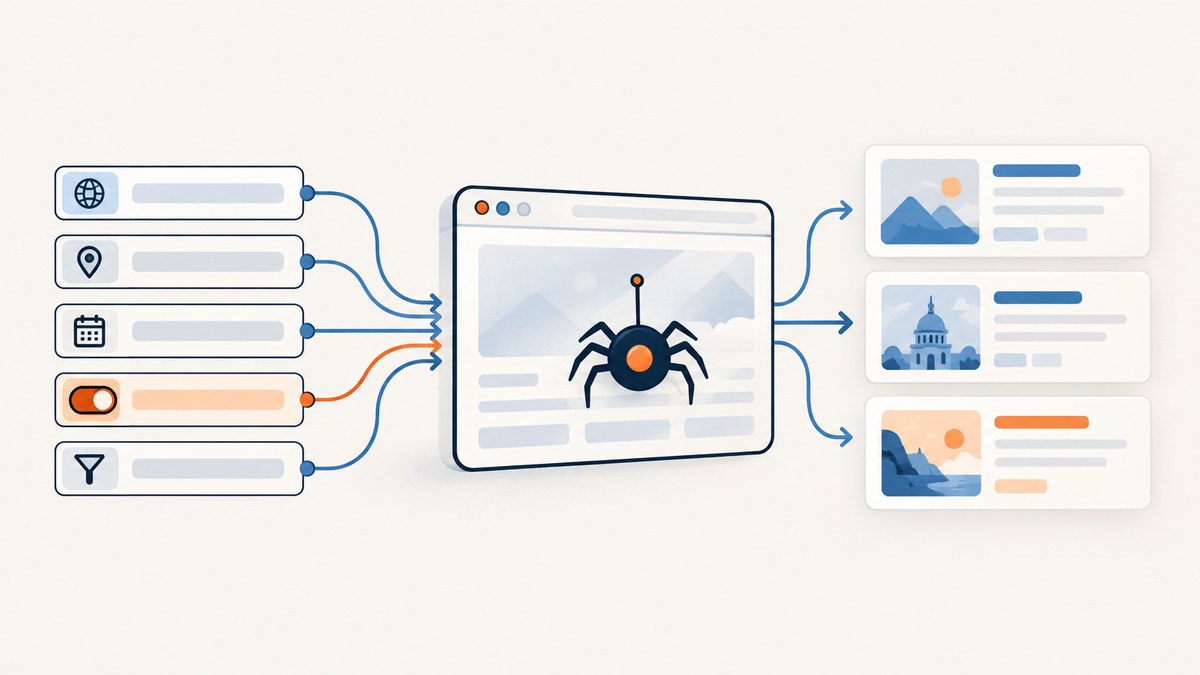
A good web scraper input schema tells callers exactly what they can configure, catches invalid values before a run begins, and keeps ordinary runs simple. Treat it as a public contract between the person or system starting the scraper and the scraper implementation: require only information the scraper cannot infer, give sensible defaults to optional behavior, and validate constraints that matter.
This guide walks through field design, defaults and prefills, validation, generated forms, compatibility, and dynamic pages. Its concrete schema syntax and form settings use Apify Actor input schema; the principles apply broadly, but other frameworks may use different syntax or provide no generated UI.
1. Start with the caller’s decisions
Before choosing types or writing JSON, list the decisions a caller genuinely needs to make. For a typical scraper, those might be the starting URLs, a maximum number of pages, a result format, or a site-specific query. These are examples, not a universal field list. A scraper that always targets one site may need a search term rather than a generic URL list; an internal scheduled job may have no need for configurable output format.
Keep implementation details out of the public contract unless callers need to control them. If a timeout, retry policy, or request header can be managed safely inside the scraper, avoid asking every caller to supply it. Each additional field increases documentation and validation work and creates another way a run can be misconfigured.
- Identify the launchers. Will humans use a form, or will API clients, a CLI, schedules, and other programs launch runs? A field that seems obvious to the developer may be unclear to a person filling out a form.
- List caller-controlled choices. Separate inputs that change the target or desired result from implementation settings that can remain internal.
- Group by purpose. Common groups include targets, crawl limits, extraction options, and advanced request settings. Use nested objects only when they make related values easier to understand.
- Define the smallest useful run. Decide what a caller must provide and what behavior the scraper can choose by default.
In Apify, an input schema can define validation and drive the Actor’s input UI, API documentation, and integration examples. That makes the schema part of the interface, rather than merely a convenient list of configuration keys.
2. Distinguish required values, defaults, and prefills
These three concepts look similar in a form but mean different things to callers:
| Setting | What it means | Use it when |
|---|---|---|
| Required | The run cannot reasonably proceed without the value. | There is no meaningful target or other way to infer the needed input. |
| Default | The scraper uses this value when the caller omits it. | A normal behavior is safe and useful for most runs. |
| Prefill | A UI example or starting value for a person to edit. | A field has no sensible default, but an example helps explain its shape. |
Apify documents that defaults are applied when a field is omitted, including when a run is started through API, CLI, scheduler, or Console. A prefill, by contrast, is for the UI: it demonstrates a value and makes testing easier, but it does not set the value for API callers. Do not make a field required merely to force callers to repeat a safe default.
For example, a start URL may be required when the Actor has no fixed target. A crawl limit can often have a conservative default. An advanced query object might have no universal value, so a UI prefill can show its expected shape without silently imposing that example on programmatic users.
3. Choose types, labels, and actual constraints
Use a type that reflects the value the scraper consumes. Apify’s documented input types include string, array, object, boolean, and integer. Give each property a human-facing title and description; the key name is for code, while the title and description explain the decision to a person.
- Strings: use minimum or maximum lengths and a pattern when those conditions are real requirements. For URLs, validate what your scraper actually supports rather than claiming that a basic string pattern proves a URL will be reachable.
- Enumerations: offer a select for a genuinely closed set, such as a fixed output mode. Do not use an enumeration for values that change frequently or are user-defined.
- Numbers: set minimum and maximum bounds for crawl limits, page counts, or other bounded quantities. Explain units and whether a boundary is inclusive.
- Arrays: set item types and array size limits when the scraper has real operational bounds. Say whether an empty list is meaningful.
- Objects: use nested properties for cohesive settings, such as pagination controls. Avoid nesting a single field without a clear reason.
- Booleans: use them for clear on/off decisions. If a choice has more than two meaningful states, a select is clearer.
A useful validation rule prevents an invalid or unsafe-to-process input from reaching the crawl. A rule that only encodes a guess makes the contract brittle. Pair constraints with plain-language validation messages that tell the caller how to fix the value.
4. Runnable example: an Apify input schema
This example accepts one or more start URLs and an optional bounded crawl limit. It is illustrative: adapt titles, limits, and field requirements to the scraper’s actual behavior. Apify’s schema resembles JSON Schema but has platform-specific extensions and differences, so validate it using Apify’s tooling rather than assuming a generic JSON Schema validator will behave identically.
{
  "schemaVersion": 1,
  "title": "Product page scraper",
  "description": "Collect product details from the supplied starting pages.",
  "type": "object",
  "properties": {
    "startUrls": {
      "title": "Start URLs",
      "type": "array",
      "description": "Pages where the crawl should begin.",
      "editor": "stringList",
      "minItems": 1,
      "maxItems": 50,
      "items": {
        "type": "string",
        "pattern": "^https?://"
      }
    },
    "maxPages": {
      "title": "Maximum pages",
      "type": "integer",
      "description": "Maximum number of pages to process across this run.",
      "default": 100,
      "minimum": 1,
      "maximum": 5000
    },
    "includeVariants": {
      "title": "Include product variants",
      "type": "boolean",
      "description": "Collect available variant details for each product.",
      "default": false
    },
    "advanced": {
      "title": "Advanced options",
      "type": "object",
      "description": "Optional site-specific query settings.",
      "editor": "json",
      "prefill": {
        "sort": "popular"
      },
      "properties": {
        "sort": {
          "title": "Sort order",
          "type": "string",
          "enum": ["popular", "newest"]
        }
      },
      "additionalProperties": false
    }
  },
  "required": ["startUrls"],
  "additionalProperties": false
}
The platform’s field editors can make the interface match the data: a URL list editor for start URLs, a select for a closed set, or a code editor for code-valued input. Descriptions function as practical help text. Apify supports UI capabilities such as these, but editor names and generated-form features are framework-specific.
The sample explicitly rejects unknown root and nested properties. Apify documents permissive behavior by default for additional properties; setting additionalProperties to false makes typos fail validation instead of being silently accepted. Before tightening a published schema, check existing API and scheduled callers for fields they may already send.
5. Validate before execution and keep the contract compatible
Schema validation is most useful when it fails before expensive work starts. Apify states that input failing validation is rejected before the Actor starts. Keep runtime checks too, for facts the schema cannot establish, such as whether a URL is reachable or whether a site returns the expected page.
Make schema changes with callers in mind:
- Adding an optional field is often a compatible extension if old runs retain their behavior.
- Adding a required field can break callers that omit it. Prefer a safe default when that matches the intended behavior.
- Changing a default changes the behavior of existing callers that omit the field. Document the change and consider versioning if the impact is significant.
- Rejecting additional properties can expose misspellings, but it can also reject fields that clients already send. Audit callers first.
- Renaming or changing a type is a breaking interface change. If both old and new callers must work, support a migration path.
Apify’s specification documents schema version 1 and a maximum input-schema file size of 500 kB. These are Apify platform facts, not universal limits. Keep schemas readable even when the platform permits larger files.
6. For dynamic pages, inspect the request that supplies the data
A scraper input schema should express choices callers need to make; it should not compensate for an unexplored page-loading strategy. When content appears only after JavaScript runs, inspect the browser’s network activity and locate the request that delivers the data. The response may be structured data that can be fetched directly, avoiding a full browser render.
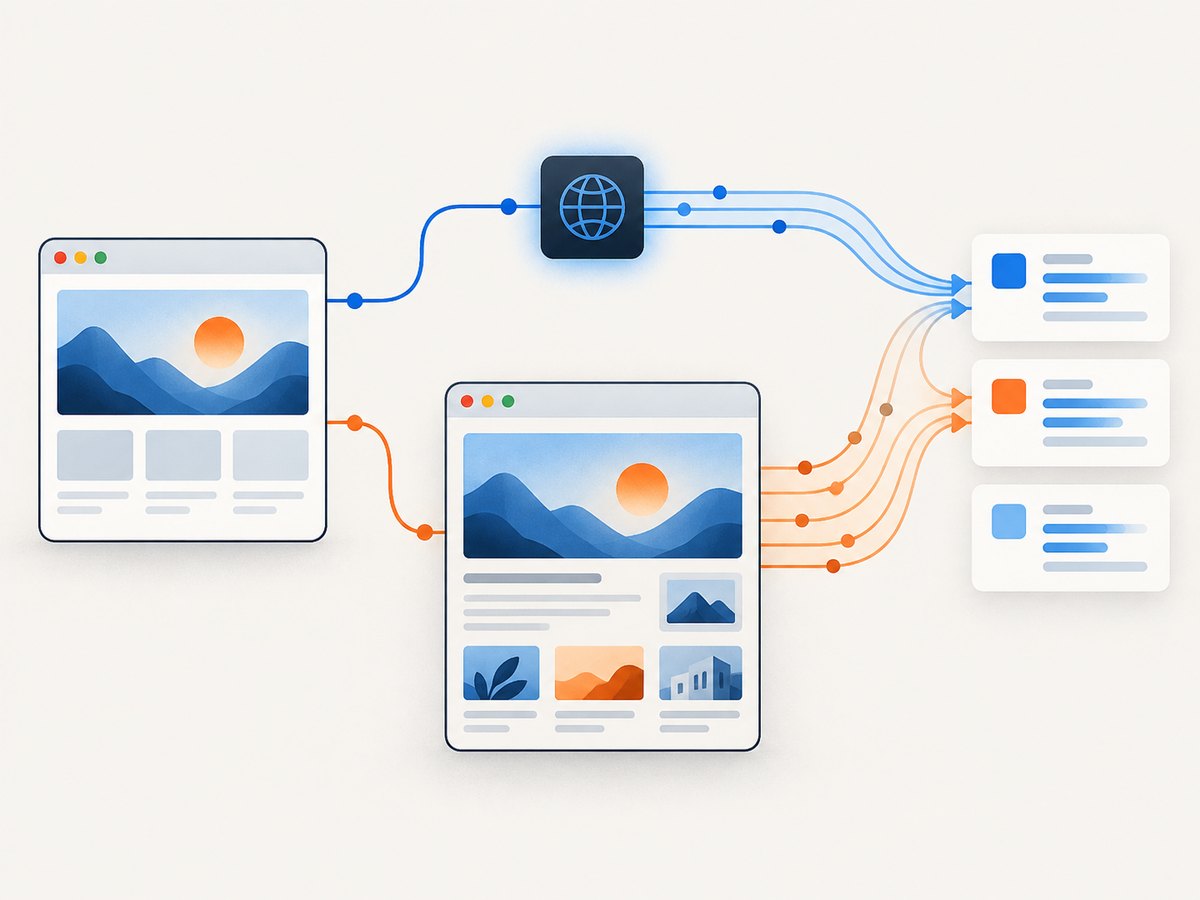
Scrapy’s documentation recommends reproducing the relevant request, including its method and URL and, as required by that request, body, headers, or form parameters. If direct retrieval is impractical, or the task requires a browser-visible result such as a screenshot, JavaScript rendering or a headless browser may be appropriate. The exact integration is framework-specific; the cited Scrapy workflow reference is version 2.1.0.
- Open the page with developer tools and inspect network requests as the content loads.
- Find the request whose response contains the missing records or page data.
- Determine which request details are essential and which can be obtained from the page or session.
- Reproduce the request in the scraper and verify pagination and error behavior.
- Expose caller-controlled query or pagination values in the schema only when users have a real reason to change them.
If a screenshot itself is the output, a screenshot API can avoid maintaining browser setup. ScreenshotNeo is a website screenshot API and MCP server; it is useful for capture workflows, while a scraper that needs structured records still needs an extraction strategy.
7. Or skip the browser setup
For a page capture, one GET request returns an image or PDF. See the ScreenshotNeo API documentation for options and response details.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);- Cookie and consent banners are accepted like a visitor; 60+ known consent platforms, newsletter popups, and chat widgets are removed before capture. Each step can be turned off.
- Bot checks, CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing. Response headers identify the page verdict and whether the request was billed.
- An MCP server provides
take_screenshot,get_page_info, andcapture_pdftools for Claude, Cursor, and other MCP clients. - The free plan includes 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000; every feature is on every plan.
Create a free ScreenshotNeo account to get 1,000 screenshots a month with no card.
8. Troubleshooting schema and scraper inputs
| Symptom | Likely cause | What to check |
|---|---|---|
| The run fails before it starts | The input does not satisfy the schema, or the schema itself is invalid. | Compare submitted keys and types with the schema; validate with the platform’s own validator and read the field-level error. |
| An omitted option behaves unexpectedly | A prefill was mistaken for a default, or no default was defined. | Check the API payload and schema default. Prefills help UI users; they do not supply omitted API values. |
| A field appears in the form but not in API runs | The UI prefilled it, but the API caller omitted it. | Use a real default when the value should apply to all callers, or make the field required when the run cannot proceed without it. |
| A familiar field is rejected | Unknown properties are disallowed, or a field was renamed. | Check additionalProperties at the relevant object level and review compatibility before changing strictness. |
| A URL passes validation but the crawl fails | A string pattern checks shape, not reachability, redirects, access, or page structure. | Perform runtime request checks and report a useful per-URL failure. |
| JavaScript content is missing | The scraper fetched initial HTML while data arrived in a later request. | Inspect network activity; reproduce the data request or use browser rendering when necessary. |
| Large runs consume more resources than expected | The URL list, page limit, or fan-out is too permissive. | Set honest bounds, validate pagination, and document whether the cap is per URL or for the whole run. |
9. Performance, reliability, and cost
Input design affects how much work a scraper can trigger. Bound arrays and crawl counts to prevent accidental runs over far more targets than intended. Be explicit about whether a maximum applies globally or separately to each start URL. Defaults should favor a useful, predictable run, and descriptions should state the practical effect of raising a limit.
Validation avoids wasting time on malformed input, but it cannot guarantee that a target site is available or stable. Runtime behavior should handle redirects, empty result sets, request failures, and changing page structure. When a run has multiple targets, decide whether one failed URL stops everything or produces partial results; document that choice if callers depend on it.
Direct data requests can avoid browser rendering when the site exposes a usable source endpoint. Browser rendering may be needed for client-side content or visual output, but adds setup and execution work. Choose based on the actual target and required result rather than exposing a generic rendering switch by default.
For ScreenshotNeo page captures, the stated plans are Free: 1,000 shots/month, Starter: $5 for 3,000, Growth: $15 for 15,000, Pro: $39 for 60,000, Scale: $99 for 250,000, and Business: $249 for 1,000,000; yearly billing gives two months free. Only clean shots are billed, with cache hits and failed/blank or blocked results free. These are capture-plan facts and do not price or replace a scraper’s own compute, proxy, or data-storage costs.
10. Schema design checklist
- Does every required field represent information the scraper cannot reasonably infer?
- Do optional fields have useful defaults where appropriate?
- Are UI prefills clearly examples rather than hidden API defaults?
- Do types, bounds, enumerations, and array limits reflect actual scraper constraints?
- Are titles, descriptions, and validation errors understandable to the caller?
- Is the editor suited to the value, and are framework-specific controls labeled as such?
- Is unknown-field behavior intentional at the root and nested object levels?
- Have existing API, CLI, and scheduled callers been considered before breaking changes?
- Has dynamic content been traced to its source request before adding browser complexity?
- Are runtime failures and partial-result behavior defined beyond schema validation?
FAQ
Should every scraper accept a list of start URLs?
No. Use the form that matches the scraper’s actual target model. A fixed-site scraper may need a search query, category, or identifier instead; an Actor example that uses start URLs is not a universal requirement.
Can a schema prove a submitted URL is safe and reachable?
No. Schema constraints can check input shape, but network reachability, redirects, access restrictions, and the content returned require runtime handling.
Should I expose custom headers as an input?
Only when callers genuinely need them and you can handle sensitive values appropriately. A fixed header or authentication mechanism that belongs to the scraper should not automatically become a public field.
Can I use a generic JSON Schema validator for an Apify schema?
Do not assume full compatibility. Apify documents similarities as well as extensions and differences; use its platform validator to confirm behavior.


