How to Download All Images from a Webpage with Python
Learn how to find, normalize, and stream every accessible image from one webpage with Python, plus handle lazy loading, duplicates, errors, and JavaScript.
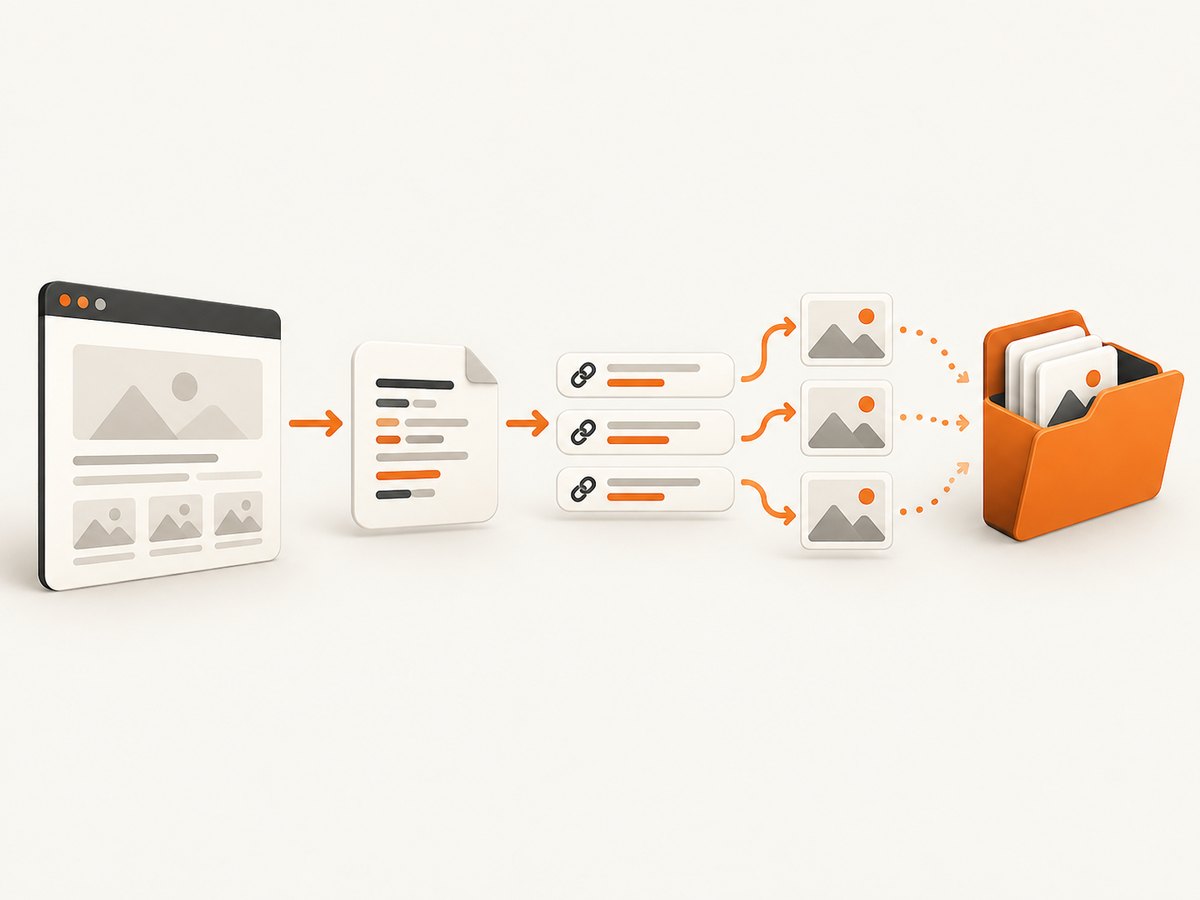
Direct answer: fetch the webpage HTML, parse its <img> elements, resolve each image reference against the page URL, remove duplicates, and stream each response to a uniquely named file. The complete script below uses Requests and Beautiful Soup. It handles relative URLs, redirects, missing attributes, duplicate images, filename collisions, HTTP errors, non-image responses, and interrupted downloads.
This method inventories image references present in the server-delivered HTML. It does not guarantee every image a browser eventually displays. JavaScript-rendered images, CSS backgrounds, srcset variants, authenticated resources, consent-gated content, and images loaded after scrolling need additional handling. Use the code only for pages you are permitted to access and download.
1. Install the dependencies
Requests performs HTTP requests and supports streamed responses. Beautiful Soup parses the returned HTML. Install both packages in a virtual environment:
python -m venv .venv
# macOS/Linux
source .venv/bin/activate
# Windows PowerShell
# .venv\Scripts\Activate.ps1

python -m pip install requests beautifulsoup4
Beautiful Soup’s documentation describes parser selection and tree searches. Requests’ Quickstart documents GET requests and saving streamed content with iter_content.
2. A complete downloader for one webpage
Save this as download_images.py. Replace PAGE_URL with a page you are allowed to retrieve.
from pathlib import Path
from urllib.parse import urljoin, urlparse, unquote
import hashlib
import mimetypes
import re

import requests
from bs4 import BeautifulSoup

PAGE_URL = "https://example.com/article"
OUTPUT_DIR = Path("downloaded-images")
TIMEOUT = (10, 60)  # connect timeout, read timeout
CHUNK_SIZE = 64 * 1024


def safe_name(value: str) -> str:
    """Keep a filename portable across common operating systems."""
    value = unquote(value)
    value = re.sub(r"[^A-Za-z0-9._-]+", "_", value).strip("._")
    return value or "image"


def extension_for(response: requests.Response, url: str) -> str:
    """Choose an extension from Content-Type, then from the URL path."""
    content_type = response.headers.get("Content-Type", "").split(";", 1)[0].lower()
    extension = mimetypes.guess_extension(content_type) if content_type else None
    if extension in {".jpe", ".jpeg"}:
        extension = ".jpg"
    if extension:
        return extension
    path_extension = Path(urlparse(url).path).suffix.lower()
    return path_extension if re.fullmatch(r"\.[a-z0-9]{1,5}", path_extension) else ".bin"


def main() -> None:
    OUTPUT_DIR.mkdir(parents=True, exist_ok=True)
    session = requests.Session()
    session.headers.update({
        "User-Agent": "image-downloader/1.0 (contact: you@example.com)",
        "Accept": "text/html,application/xhtml+xml",
    })

    page_response = session.get(PAGE_URL, timeout=TIMEOUT)
    page_response.raise_for_status()
    soup = BeautifulSoup(page_response.content, "html.parser")

    raw_urls = []
    for tag in soup.find_all("img"):
        # src is the normal attribute; data-src is common for lazy loading.
        candidate = tag.get("src") or tag.get("data-src")
        if candidate:
            raw_urls.append(candidate.strip())

    image_urls = []
    seen = set()
    for raw_url in raw_urls:
        if not raw_url or raw_url.startswith(("data:", "blob:", "javascript:")):
            continue
        absolute = urljoin(PAGE_URL, raw_url)
        if absolute not in seen:
            seen.add(absolute)
            image_urls.append(absolute)

    print(f"Found {len(image_urls)} unique image URLs")
    used_names = set()
    failures = []

    for index, image_url in enumerate(image_urls, start=1):
        try:
            with session.get(image_url, stream=True, timeout=TIMEOUT, allow_redirects=True) as response:
                response.raise_for_status()
                content_type = response.headers.get("Content-Type", "").lower()
                if content_type and not content_type.startswith("image/"):
                    raise ValueError(f"unexpected Content-Type: {content_type}")

                url_name = Path(urlparse(image_url).path).name
                stem = safe_name(Path(url_name).stem) or f"image-{index:04d}"
                extension = extension_for(response, image_url)
                filename = f"{stem}{extension}"
                if filename in used_names:
                    digest = hashlib.sha256(image_url.encode()).hexdigest()[:10]
                    filename = f"{stem}-{digest}{extension}"
                used_names.add(filename)

                destination = OUTPUT_DIR / filename
                with destination.open("wb") as output:
                    for chunk in response.iter_content(chunk_size=CHUNK_SIZE):
                        if chunk:
                            output.write(chunk)
                print(f"saved {destination} <- {image_url}")
        except (requests.RequestException, OSError, ValueError) as error:
            failures.append((image_url, str(error)))
            print(f"failed {image_url}: {error}")

    print(f"Downloaded {len(image_urls) - len(failures)} of {len(image_urls)} images")
    if failures:
        print("Failures:")
        for url, error in failures:
            print(f"- {url}: {error}")


if __name__ == "__main__":
    main()
Run it with:
python download_images.pyThe script uses urljoin instead of string concatenation. That correctly handles absolute references such as https://cdn.example/image.jpg, root-relative paths such as /media/image.jpg, path-relative paths such as ../media/image.jpg, and scheme-relative paths such as //cdn.example/image.jpg.
3. How each stage works
Retrieve the page
session.get downloads the HTML. Separate connect and read timeouts prevent a dead host from blocking the entire run indefinitely. raise_for_status() turns 4xx and 5xx responses into visible failures instead of parsing an error page as if it were an article.
Parse image references
soup.find_all("img") finds image elements in the HTML tree. The example checks src and the common lazy-loading attribute data-src. A page may use other names such as data-lazy-src, so inspect that site’s markup before adding site-specific rules.
Normalize and deduplicate
URL normalization makes every reference requestable from the original page context. A set removes repeated references while preserving the first-seen order. Query strings are retained because they can select a different image transformation or size.
Stream the bytes
With stream=True, Requests does not load the complete file into memory. iter_content writes 64 KiB chunks directly to disk, which is safer for large originals. The filename extension is selected from Content-Type when available; a URL ending in .jpg is not proof that the response contains JPEG bytes.
4. Finding more than img[src]
srcset and responsive images
Responsive markup can contain several candidates:
<img src="small.jpg" srcset="small.jpg 480w, large.jpg 1200w">If you need every candidate, parse the comma-separated srcset value and resolve each URL with urljoin. The browser normally chooses one candidate for the viewport; downloading every candidate may multiply requests and storage.
Lazy-loading attributes
Sites commonly place the real URL in data-src, data-original, or a custom attribute and leave a placeholder in src. Add the attributes used by the target site, and deduplicate after normalization.
Linked originals
A thumbnail may be wrapped in an anchor pointing to a larger file. If your permitted use requires originals, inspect <a href> around each image and apply an explicit site rule. Do not assume every link is an image; validate the response’s media type.
CSS backgrounds and inline styles
Images in background-image: url(...) are not represented by img tags. Extracting them requires parsing stylesheets and inline CSS, then handling CSS escapes and relative URL bases. External stylesheets may also be blocked, authenticated, or generated dynamically.
JavaScript-rendered content
Beautiful Soup parses bytes already present in the response; it does not execute JavaScript. If the initial HTML has no gallery, a browser-rendering workflow or a documented site export is required. Treat browser automation as a separate engineering project with its own access, rate, and terms requirements.
5. Standard-library alternative with urllib.request
If adding Requests is undesirable, Python’s standard library can perform the downloads. Beautiful Soup can still parse the HTML, or you can use an HTML parser from the standard library. A minimal retrieval looks like this:
from urllib.request import Request, urlopen

request = Request(
    "https://example.com/article",
    headers={"User-Agent": "image-downloader/1.0"},
)
with urlopen(request, timeout=30) as response:
    html = response.read()
urllib.request.urlretrieve is another option, but you still need to validate status, content type, filenames, and incomplete transfers. Python’s urllib.request documentation describes ContentTooShortError when a retrieval is shorter than the reported Content-Length. Requests generally offers a simpler session, timeout, and streaming workflow.
6. Reliability and responsible request handling
- Throttle politely: add a delay between image requests for large pages, and avoid parallel bursts that can trigger rate limits.
- Retry transient failures: retry selected 429 and 5xx responses with exponential backoff, honoring a server’s
Retry-Afterheader. Do not endlessly retry 401, 403, or a malformed URL. - Preserve partial work: write each image separately and record failures. A later run can skip files that already exist after checking their size or checksum.
- Use a bounded timeout: a timeout is not a total job deadline. Track elapsed time if the page has hundreds of images.
- Check redirects and media types: a redirect can lead to an HTML login page or an error document. Reject unexpected content types and consider checking magic bytes for high-assurance pipelines.
- Protect credentials: use a session cookie only when you are authorized to access the page, and never print authorization headers or private URLs.
Google Search Central explains that a robots.txt file tells search engine crawlers which URLs they can access and can help manage crawler traffic, including media files. It is not a security mechanism and does not decide copyright permission. Review the site’s terms and your intended reuse separately.
7. Common errors and fixes
| Error or symptom | Likely cause | Fix |
|---|---|---|
Invalid URL or requests to the wrong host |
A relative src was concatenated manually. |
Resolve with urljoin(page_url, raw_src). |
| Zero images found | The gallery is rendered by JavaScript, or images use nonstandard attributes. | Inspect the raw HTML; add known lazy attributes or use an authorized rendering workflow. |
| 403 or 429 responses | The host requires permission, cookies, or rate control. | Respect access rules, slow down, and use documented authentication. A custom User-Agent does not bypass access controls. |
| Saved files open as HTML | The server returned an error, login page, or challenge. | Check status and Content-Type before writing; log the final URL after redirects. |
| Files overwrite one another | Different URLs share the same basename. | Use a collision suffix derived from the full URL, as the script does. |
| Images are incomplete | A connection ended early or the process stopped. | Stream in chunks, keep failures visible, compare bytes with Content-Length when present, and retry safely. |
| Only thumbnails downloaded | src points to a thumbnail while the original is in an anchor or srcset. |
Parse the permitted original URL pattern explicitly. |
8. Performance, storage, and cost considerations
Runtime is approximately the page request plus the sum of image transfer times. Network latency, image sizes, redirects, throttling, and server speed dominate CPU cost. Streaming keeps memory close to the chunk size instead of the total size of all images. Disk usage is the sum of response bytes, so check available space before downloading large galleries.
Sequential requests are easiest to reason about and are polite to the host. If you have permission and the server documents a safe rate, bounded concurrency can improve throughput, but use a small worker pool, per-host limits, retries with backoff, and cancellation. Do not treat concurrency as a way around rate limits.
For repeat jobs, store a manifest containing source URL, final URL, status, byte count, content type, checksum, and timestamp. Conditional requests using ETag or Last-Modified can avoid transferring unchanged files when the server supports them. Cache only where the site’s terms and your privacy requirements allow it.
9. Or skip the browser setup
If your real goal is to obtain a clean visual capture rather than raw image files, ScreenshotNeo provides a website screenshot API. It accepts one GET request and returns PNG, JPEG, WebP, or PDF. Before capture it accepts cookie or consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing state.
See the ScreenshotNeo API documentation for parameters and response details.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Relevant capture controls include full-page shots with lazy images loaded, a single element selected by CSS, dark mode, device presets or custom viewports, retina scale, custom CSS and JavaScript, clicks, selector hiding, waits for a selector or network idle, request and resource blocking, custom headers and cookies, user agents, authorization, timezone and geolocation, transparent backgrounds, resizing, and a chosen cache TTL. You can also submit asynchronous jobs with signed webhooks, capture up to 100 URLs per bulk call, create PDFs, use signed links for public <img> tags, and read usage through the usage API. An MCP server exposes take_screenshot, get_page_info, and capture_pdf to Claude, Cursor, and other MCP clients.
ScreenshotNeo has 1,000 free shots each month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is available on every plan. Create a free ScreenshotNeo account.
10. FAQ
Does this download every image visible in a browser?
No. It downloads accessible references found in the HTML and attributes you parse. JavaScript, CSS backgrounds, authentication, and viewport-dependent loading require additional logic.
Should I use requests.content or streaming?
Use response.content for small HTML documents. Stream image responses with iter_content so large files do not occupy memory all at once.
Why keep query strings when deduplicating?
Image CDNs often use query parameters to select format, crop, or width. Removing them can collapse distinct resources into one URL.
Can a User-Agent header guarantee access?
No. It can identify your client, but it does not override authentication, robots policies, rate limits, bot checks, or the site’s terms.
When is a screenshot API a better fit?
Use a rendering service when you need the page as a visual artifact, including JavaScript-rendered content, full-page layout, consent cleanup, or PDF output, instead of separately downloading source image files.


