How to Download a Website for Offline Browsing
Use HTTrack or GNU Wget to save a website for offline browsing. Learn how to scope a mirror, handle missing assets, and understand what may not work offline.

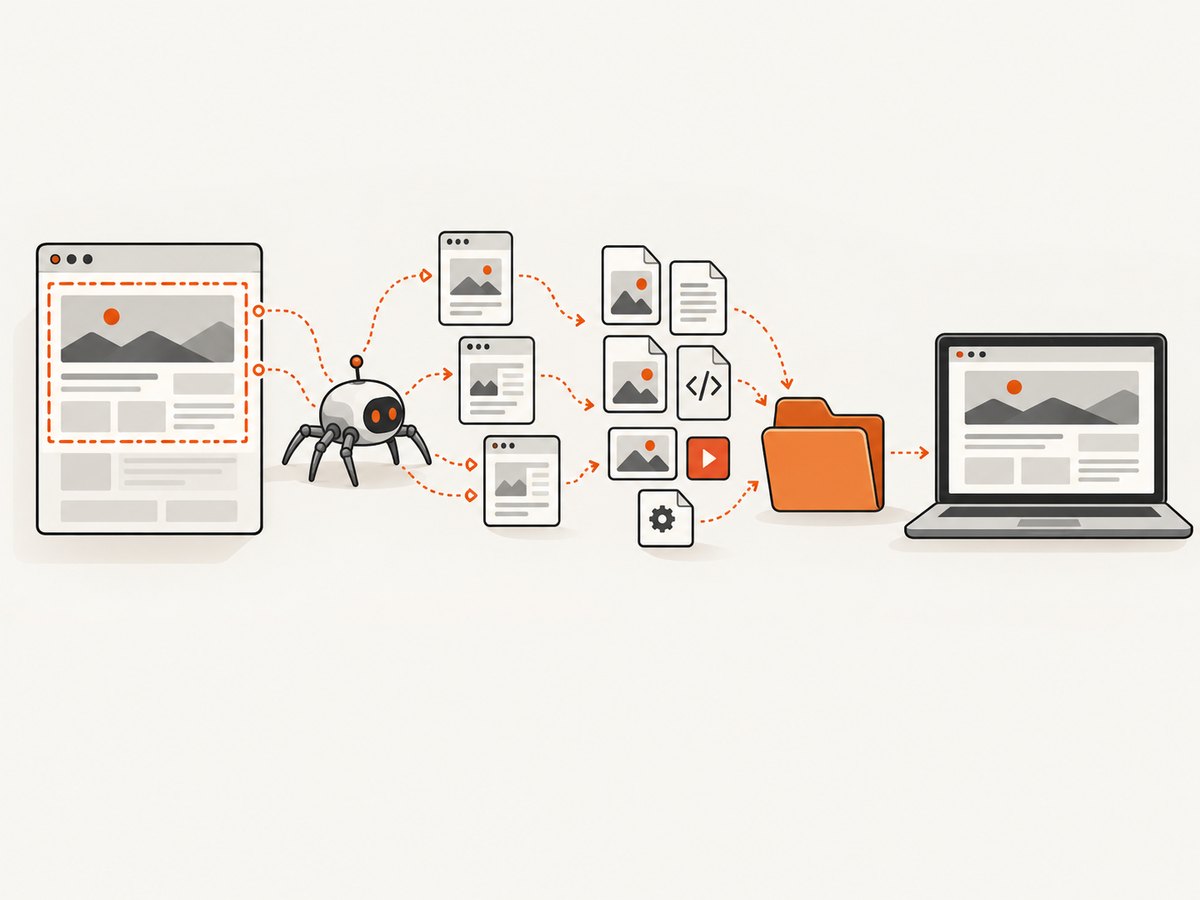
To download a website for offline browsing, use HTTrack for a guided mirror or GNU Wget for a repeatable command-line workflow. Both can follow links and save linked resources into a local directory whose pages can be opened in a browser. Choose a narrow, authorized part of the site, allow enough disk space, wait for the crawl to finish, then open the saved index page. A mirror is a copy of retrieved files: it may not preserve interactive features, account data, or content assembled later by JavaScript.
If you only need a visual record of a page rather than a browsable copy of the site, [ScreenshotNeo](https://screenshotneo.com) captures a URL as an image or PDF. A screenshot is not an offline website mirror: links and interactions are not preserved.
1. Decide what you need offline
“Download a website” can mean several different things. Decide which outcome you need before starting, because a full crawl can take much longer and use much more storage than saving a few pages.
| Need | Good starting point | What you get |
|---|---|---|
| Browse a linked section offline | HTTrack or Wget recursive mode | A directory of retrieved pages and assets, with local links where conversion succeeds. |
| Save a short list of known files | HTTrack get-files mode or a direct downloader | A targeted set without following every page link. |
| Keep a visual record of one page | ScreenshotNeo | A screenshot or PDF, not a navigable offline copy. |
| Preserve a site behind forms or browser-driven navigation | HTTrack browser-capture workflow | A capture of addresses reached through its documented local proxy workflow; results depend on the site. |
For an offline mirror, set a starting URL and a boundary: for example, a documentation section on one host. Avoid beginning at a large home page and letting the crawler roam across unrelated hosts, calendars, search results, or generated URL combinations. Confirm you are allowed to retrieve the content, especially if it is private or access-controlled.
2. Mirror a website with GNU Wget
Wget is a good fit when you want a command you can repeat, save in a script, or run on a schedule. The following command mirrors the selected path and fetches resources needed to render pages:
wget --recursive --page-requisites --convert-links --no-parent https://example.com/section/Replace the example URL with the section you are authorized to save. Run the command in a directory where you want the mirror stored. Wget creates a local directory structure based on the remote site.
| Option | Purpose | When to adjust it |
|---|---|---|
--recursive |
Follows links and retrieves pages recursively. | Use a different depth or scope if the target contains many linked pages. |
--page-requisites |
Fetches resources needed to display a page, such as images and stylesheets. | Keep it enabled for a useful visual copy; review file filters if assets are missing. |
--convert-links |
Rewrites downloaded references so retrieved pages can point to local files. | Use it when the goal is local browsing. It cannot rewrite resources that were never downloaded. |
--no-parent |
Keeps traversal from climbing above the selected path. | Remove it only when you intentionally need parent pages and have checked the scope. |
Open the saved page in a browser after the command completes. Wget’s manual documents following links in HTML, XHTML, and CSS, recreating directory structure, converting links for offline viewing, and respecting the Robot Exclusion Standard (robots.txt). None of that guarantees a modern application will behave as it does online: content can depend on API calls, scripts, authentication, or browser state.
Keep a Wget run manageable
- Start at the narrowest useful section URL rather than the whole domain.
- Check available space before a large recursive job; pages can reference many large assets.
- Keep a log so you can identify the URLs and files that failed instead of guessing after the run.
- Review the saved tree and test several local links, including pages near the edge of the chosen scope.
- Use reasonable request rates and obey the site’s terms and crawler rules.
Wget supports additional controls for depth, domains, file types, and continuation. Select them based on the site and purpose rather than copying a long option list blindly. A domain restriction can keep linked third-party sites out of the mirror; a depth limit can cap how far links are followed. If a crawl is interrupted, inspect the partial output and use Wget’s continuation behavior deliberately, since remote files may have changed since the first attempt.
3. Mirror a website with HTTrack
HTTrack provides a project workflow as well as command-line interfaces. Its product documentation describes downloading a website into a local directory, building directories, and retrieving HTML, images, and other files. It rewrites relative links for local browsing, can resume interrupted downloads, and can update an existing mirror.
- Install HTTrack from its [official site](https://www.httrack.com/).
- Create a project and enter a name and destination directory with enough free space.
- Enter the starting URL. For a linked site, choose the normal website-download action; for a finite list of addresses, use get-files mode.
- Set the scope with depth, domain, path, and file-type filters. Check whether linked hosts should be included before allowing them into the crawl.
- Start the job and review its reported errors when it finishes.
- Open the local start page or index in a browser, click through several pages, and confirm images and styles load locally.
- Keep the project if you may need to continue an interrupted job or update the mirror later.
HTTrack documents interfaces for Windows, macOS/Linux/Unix, Android, and command-line use. Its documentation also describes proxy support, filters and limits, continuation, and a browser-capture workflow for pages reached through forms or scripts. The exact setup depends on the platform and the way the site navigates, so use the official documentation for the installed version.
Choose between HTTrack and Wget
| Situation | Start with | Reason |
|---|---|---|
| You prefer guided desktop setup | HTTrack | Its project workflow exposes scope, filters, resume, and update controls. |
| You need repeatable scripts or scheduled jobs | Wget | Command-line options can be saved and run again. |
| You only need a handful of URLs | HTTrack get-files mode or a direct downloader | A finite list avoids following unneeded links. |
| Pages are reached through forms or scripts | HTTrack browser capture | Its documentation describes a local-proxy browser workflow for requested addresses. |
This is a comparison of documented capabilities, not a performance benchmark. For simple sites, either tool may be sufficient; the site’s structure and your scope usually matter more than the choice.
4. Validate the offline copy
A command finishing successfully does not prove that the copy is complete. Check the mirror before relying on it, especially if you are preserving technical documentation or a reference site.
- Open the local entry page. Use the generated index or saved start page rather than a remote bookmark.
- Test navigation. Click links within the intended section and verify the address remains local.
- Check page assets. Look for missing images, stylesheets, fonts, and downloads.
- Test representative pages. Include a long page, a page with media, and a page near the crawl boundary.
- Check online dependencies. A page that still calls remote scripts or APIs may appear incomplete or stop working without a network connection.
- Keep a record. Store the starting URL, date, tool settings, and error log with the mirror so you know what it covers.
If the copy is larger than the space available on your computer, an external SSD or USB flash drive can hold the mirror. Estimate the required capacity from the completed or partial download rather than assuming a site’s size from its visible page count.
5. Dynamic pages, accounts, and other limits
A static downloader retrieves responses and resources; it does not automatically reproduce the whole browser session. A page may show a shell of HTML first and build its content from JavaScript or later API requests. Some features may require login state, client-side storage, a form submission, or a service that is unavailable offline. In those cases, the downloaded HTML can exist while the page still looks empty or behaves differently.
For authorized login-protected content, session handling is site-specific. HTTrack documents cookie import and browser capture for some cases, but neither makes every authenticated application mirrorable. Do not try to bypass access controls. If the goal is to keep material from an account, use the service’s export or offline feature where available, and avoid including credentials in shared scripts or logs.
Large sites also require time and storage. Images, videos, downloadable archives, and duplicate URL variants can make a crawl much larger than expected. Narrow the path and file types first. If you intend to update a mirror, keep the project or command settings and check whether the content changed between runs.
6. Responsible downloading
Check the site’s terms and permissions before mirroring it. Keep the scope limited to material you are entitled to retrieve, use a reasonable request rate, and avoid collecting private or access-controlled content without authorization. HTTrack identifies itself and documents respecting robots.txt; the GNU Wget manual says it respects the Robot Exclusion Standard as well. Google Search Central explains that robots.txt can manage crawler traffic and keep selected areas from being crawled. A crawler rule is useful guidance, but it does not replace checking site terms or obtaining permission when needed.
Primary references: [HTTrack product page](https://www.httrack.com/), [HTTrack documentation](https://www.httrack.com/html/), [GNU Wget manual](https://www.gnu.org/software/wget/manual/wget.html), and [Google Search Central’s robots.txt guidance](https://developers.google.com/search/docs/crawling-indexing/robots/intro).
7. Or skip the browser setup
If you need an image or PDF of a page rather than a browsable offline site, ScreenshotNeo takes one GET request and returns the capture. For example, use this cURL call to save a WebP screenshot of a page:

curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com -o shot.webpSee the [ScreenshotNeo API documentation](https://screenshotneo.com/docs/) for request options. ScreenshotNeo accepts cookie and consent banners like a visitor and removes more than 60 known consent platforms, newsletter popups, and chat widgets before capture; each cleanup step can be turned off. Bot checks and CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers report the page verdict and billing status. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
The free plan includes 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 screenshots; every feature is available on every plan. Screenshots do not provide offline navigation or preserve page interactions. [Create a free ScreenshotNeo account](https://screenshotneo.com/account/sign-up/) to try the API with 1,000 screenshots a month and no card.
8. Troubleshooting common problems
| Symptom | Likely cause | What to do |
|---|---|---|
| Links still open the live site | Link conversion was not enabled, or the target was not downloaded. | For Wget, include --convert-links; for either tool, confirm the linked page falls within scope and inspect the saved reference. |
| Images or styles are missing | Page requisites were omitted, filters excluded assets, or files failed to download. | Use Wget’s --page-requisites, review file-type filters and logs, then rerun within the allowed scope. |
| The page is blank or incomplete offline | Content is populated by JavaScript, an API, or another online dependency. | Check the page while online and inspect its network-dependent behavior. A static mirror may not be enough; use an authorized export or capture workflow if appropriate. |
| The crawl includes unrelated pages | Links led outside the intended path or host. | Stop the run, narrow the starting URL, and add path, depth, or domain restrictions before restarting. |
| The download is unexpectedly large | The crawler reached broad link paths or large media and duplicate URL variants. | Limit depth and scope, exclude unneeded file types, and check available storage before resuming. |
| Some pages require a login | The content depends on an authenticated session or access policy. | Only proceed if authorized. Check the service’s export option; HTTrack documents cookie import and browser capture for some cases, but support varies. |
| The job stopped partway through | Network interruption, disk exhaustion, or a failed request. | Review the error log and free space. Use HTTrack’s continuation or carefully rerun Wget with continuation settings; verify files afterward. |
| The site blocks or slows the crawl | Traffic limits or crawler policy. | Respect the site’s rules, reduce request rate, narrow the scope, or ask the site owner for an archive or permission. |
9. Performance, reliability, and cost
Mirror time depends on how many pages and assets are in scope, the response sizes, connection speed, and the site’s behavior. There is no useful universal time or size estimate without inspecting the particular site. A narrow path and deliberate file filters reduce both network transfer and disk use. Start with a small section if you are unsure how quickly the site expands.
Reliability improves when you keep the logs and project settings, allow the crawler to resume after interruption, and validate the resulting files. A mirror can become stale as the original changes, so record when it was made and update it when needed. Do not treat one successful download as proof that all dynamic or protected content is preserved.
HTTrack and Wget are software tools; the retrieved files consume your network allowance and local storage. If using an external drive, select capacity after measuring the output and leave room for future updates. ScreenshotNeo is priced by plan when the requirement is screenshot capture rather than offline browsing: free includes 1,000 shots monthly, then paid tiers start at $5 for 3,000, with larger listed tiers up to 1,000,000 for $249. Yearly billing gives two months free. Those capture credits do not create a local mirror.
10. Frequently asked questions
Can I browse a website without an internet connection?
Yes, if its pages and required assets were saved locally and the parts you need do not depend on online services. Open the local entry page and test the important links before disconnecting.
Can I download an entire website in one command?
Wget can recursively retrieve linked pages, but “entire” depends on the starting URL, crawl boundaries, links exposed to the crawler, and site behavior. Set a defined scope and expect that some dynamically generated or protected material may be missing.
Will the offline version work exactly like the live site?
Usually not for sites that rely on live APIs, accounts, forms, or scripts that fetch content after the initial page loads. A mirror saves retrieved files; it does not duplicate the server or services behind them.
Can I save a website to a USB drive?
Yes. Save or move the completed mirror to a USB flash drive or external SSD, then open its local index from that drive. Check the capacity against the mirror’s actual size and test it on the computer where you plan to browse it.


