How to Download a Website From the Wayback Machine
Learn what the Wayback Machine can save, how to inventory captures, and how to build a local offline copy with HTTrack.
Direct answer: the Wayback Machine does not have a button that downloads an entire archived website. Save Page Now stores one submitted page, including the files captured for that page; it does not follow the page’s outlinks or start a whole-site crawl. To make a local copy, first identify the URLs and capture dates that exist, then mirror those archived URLs with a tool such as HTTrack, and finally inspect the result for missing pages, images, scripts, and links.
This distinction matters because an archived site is a collection of historical captures, not a guaranteed backup. The Internet Archive says it cannot guarantee that a site was archived, that every asset exists, or that replay will reproduce server-side and JavaScript behavior. A careful workflow gives you the best available local copy while making gaps visible.
What the Wayback Machine can and cannot download
| Task | Wayback feature | Result |
|---|---|---|
| Preserve one page now | Save Page Now | One archived URL and the files captured for that page |
| Review historical versions | URL search and calendar | Available captures grouped by date and time |
| Find archived files for a domain | Wildcard URL search | A list of captures that may include pages and assets |
| Create an offline directory | Third-party mirroring software | Local HTML, media, and rewritten links where captures are accessible |
| Run recurring institutional crawls | Archive-It | A separate subscription service for organizations |
Internet Archive’s guidance is explicit: “Please note, this method only saves a single page, not the whole site.” Treat Save Page Now as a preservation action for a URL, not as an exporter.
Step 1: Define the historical copy you need
Write down the scope before downloading anything:
- Domain: for example,
example.com, including or excluding subdomains. - Cutoff date: a specific capture date, year, product release, or legal record.
- Pages: home, documentation, pricing, contact, and any URL that must be present.
- Assets: images, stylesheets, JavaScript, PDFs, fonts, and downloadable files.
- Output: a browsable local mirror, a folder of individual files, or a citation list of archived URLs.
A single homepage capture does not prove that the rest of the site exists. Decide whether you need one historical page or a best-effort reconstruction of a site section.
Step 2: Inspect captures and build a URL inventory
- Open the Wayback Machine and enter the exact domain or page URL.
- Use the calendar and date range controls to select the historical period.
- Open representative pages and record the timestamp in each archived URL. The timestamp uses
yyyymmddhhmmss. - Review the wildcard pattern
http://web.archive.org/*/www.yoursite.com/*with your own domain substituted. This helps reveal files captured under the site. - Create a plain text inventory, one URL per line. Include important alternate paths, downloads, and assets that the wildcard results reveal.
# urls.txt
https://www.example.com/
https://www.example.com/about/
https://www.example.com/assets/site.css
https://www.example.com/images/logo.png
Verify every important URL. Pages may never have been discovered, may have been excluded, may be blocked, or may depend on JavaScript-generated links that a crawler did not see. An archived page can also show a closest-date capture or, when replay is incomplete, content from the live web. Check the timestamp shown by the Wayback interface and in the URL before treating a page as historical evidence.
Step 3: Try a single-page save when that is all you need
For one page, use Save Page Now and submit the page URL. Wait for the capture to finish, then open the returned archived URL in a new tab. Check the page at the recorded timestamp and verify its images, styles, and links. Save the archived URL alongside your notes. Save Page Now does not collect outlinks, so repeat the operation for each page that must be preserved.
Step 4: Create a local mirror with HTTrack
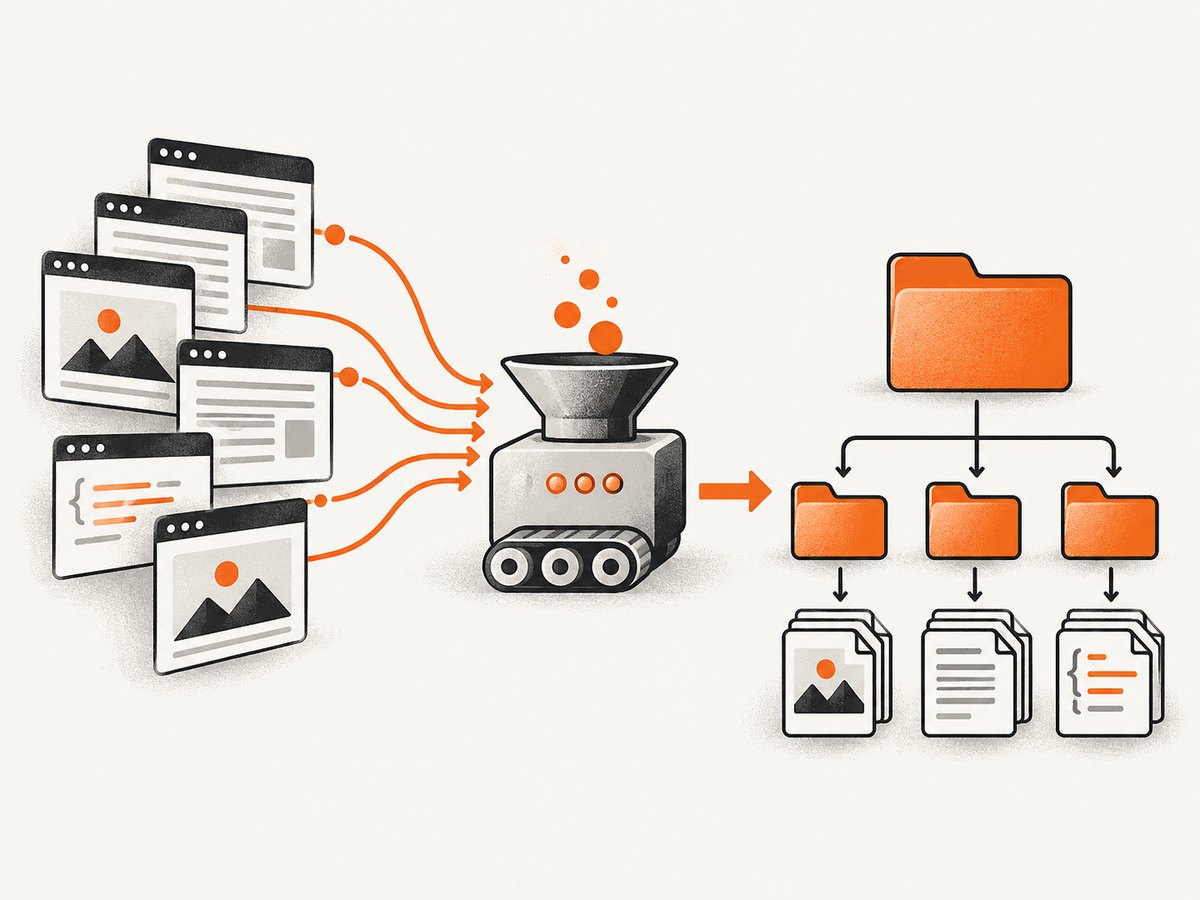
HTTrack is documented as free website-copying software. Its normal workflow is to enter site addresses, choose a mirror action, set crawl boundaries, select a local project directory, and review the generated logs. The exact screens and supported operating systems can change, so follow the current instructions on the official site.
Configure the project
- Install HTTrack from its official download page.
- Create a new project such as
example-archive-2019. - Enter the relevant Wayback URLs or the archived host you intend to mirror.
- Set the local destination to a directory with enough free space.
- Restrict the crawl to the intended host and path. A broad crawl can mix dates or leave the archive boundary.
- Start the mirror and keep the log file.
HTTrack’s general mirroring behavior does not guarantee complete reconstruction of every Wayback capture. If you point it at replay URLs, it can only copy responses that the archive serves and that the crawler can reach. Review the output instead of assuming a successful process means a complete site.
Command-line pattern
HTTrack command-line flags vary by version and platform. Use the installed version’s help output to confirm syntax before running a large job. A safe operational pattern is:
httrack "https://web.archive.org/web/20190101000000/https://www.example.com/" \
  -O "./example-archive-2019" \
  -v
Use this as a starting point only. Add host and path filters after checking your version’s documentation, and avoid allowing the crawler to leave the intended archive scope. If the tool follows an archived link into a different timestamp or host, stop and refine the boundaries.
Step 5: Validate the offline copy
Open the generated index file locally and test the site as a reader would:
- Navigate from the homepage to several deep pages.
- Open navigation menus and verify that links remain local.
- Check images, CSS, fonts, video posters, and downloadable documents.
- Search the directory for zero-byte files and unexpected live URLs.
- Compare key pages with their archived timestamps.
- Read the HTTrack log for denied requests, redirects, and missing resources.
Keep a manifest containing the original URL, capture timestamp, local path, and validation status. For evidence or long-term research, retain the archived URL as well as the local file; the local mirror is a convenience copy, not a replacement for the source record.
Why pages or images are missing
The file was never captured
The most common explanation for a broken image is that the image was not archived. Search the exact asset URL in the Wayback Machine. If no capture exists, the mirror cannot recover it from the archive.
The page was not discoverable
Orphan pages, unlinked downloads, robots exclusions, and crawl limits can keep URLs out of the collection. Add known URLs manually to your inventory and test them individually.
JavaScript created the link or content
Archive crawlers generally handle simple HTML better than links and content generated only after scripts run. A replay may show an empty shell even though the original site rendered data in a browser.
The site required server behavior
Search, login, forms, personalized pages, API calls, and server-side image maps may not work offline. A static capture cannot recreate a database or an authentication service.
The replay mixed dates
When a resource is missing at one timestamp, replay may use the closest available capture. Inspect each asset’s timestamp and keep date boundaries tight in your crawler configuration.
Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
| Only the homepage exists | Save Page Now captured one URL | Inventory and capture or mirror each required path |
| Images are broken | No archived image or wrong timestamp | Search the exact asset URL and test nearby captures |
| Links open the live site | Incomplete replay or rewritten absolute links | Inspect the timestamp, constrain the mirror, and replace only verified links |
| HTTrack stops quickly | Boundary, redirect, robots, or access issue | Read the log, narrow the host/path, and add known archived URLs |
| Styles are missing | CSS was not captured or references unavailable assets | Search stylesheet URLs and capture the matching timestamp |
| Interactive features fail | JavaScript or server state was not replayed | Document the limitation; preserve screenshots or source files separately |
| Different dates appear together | Closest-capture fallback | Record every resource timestamp and use a fixed historical window |
Performance, storage, and reliability
A mirror’s size depends on the number of captured resources, not just the number of HTML pages. Images, videos, fonts, and duplicate assets can consume most of the storage. Write the project to a local directory with room for logs and a second validated copy. An external SSD can help with a large collection, but no particular capacity is required by the documented workflow.
Run smaller batches by section or year instead of one unrestricted crawl. This makes failures easier to diagnose and reduces the chance of mixing capture dates. Save the configuration, URL inventory, and logs with the output so another person can reproduce the process.
Reliability is limited by the archive’s coverage and replay behavior. Internet Archive does not promise that every site will be archived or remain fully replayable. For recurring organizational collection work, Internet Archive points institutions to Archive-It, a separate subscription service. That is a different use case from making a one-time local copy.
Or skip the browser setup
If your goal is a current screenshot of a page rather than a historical Wayback reconstruction, ScreenshotNeo returns an image or PDF from one GET request. See the API documentation for all options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers report the page verdict and billing status. It also provides an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots per month without a card; paid plans start at $5 for 3,000 shots. These captures are for the page you request and do not recreate missing historical Wayback files.
Create a free ScreenshotNeo account to get 1,000 screenshots each month with no card.
FAQ
Can I download an entire archived website in one click?
No. Save Page Now saves one page. A local site copy requires URL discovery, a mirror workflow, and validation.
Can I use a homepage capture as a full backup?
No. Other pages and assets may never have been captured, and replay can depend on unavailable scripts or server behavior.
Is HTTrack guaranteed to rebuild a Wayback site?
No. HTTrack is documented for general website mirroring. Its result depends on which historical responses the archive serves and what the crawler can reach.
How do I prove which version I downloaded?
Keep the archived URL, including its yyyymmddhhmmss timestamp, alongside the local file and your validation manifest.
Should an organization use Archive-It?
Consider it when you need recurring, managed collection crawls. It is a separate subscription service from a one-time individual download.


