How to Evaluate JavaScript in a Headless Browser
Run JavaScript in Playwright or Puppeteer, pass values across contexts, await promises, handle DOM objects, and troubleshoot reliable evaluations.
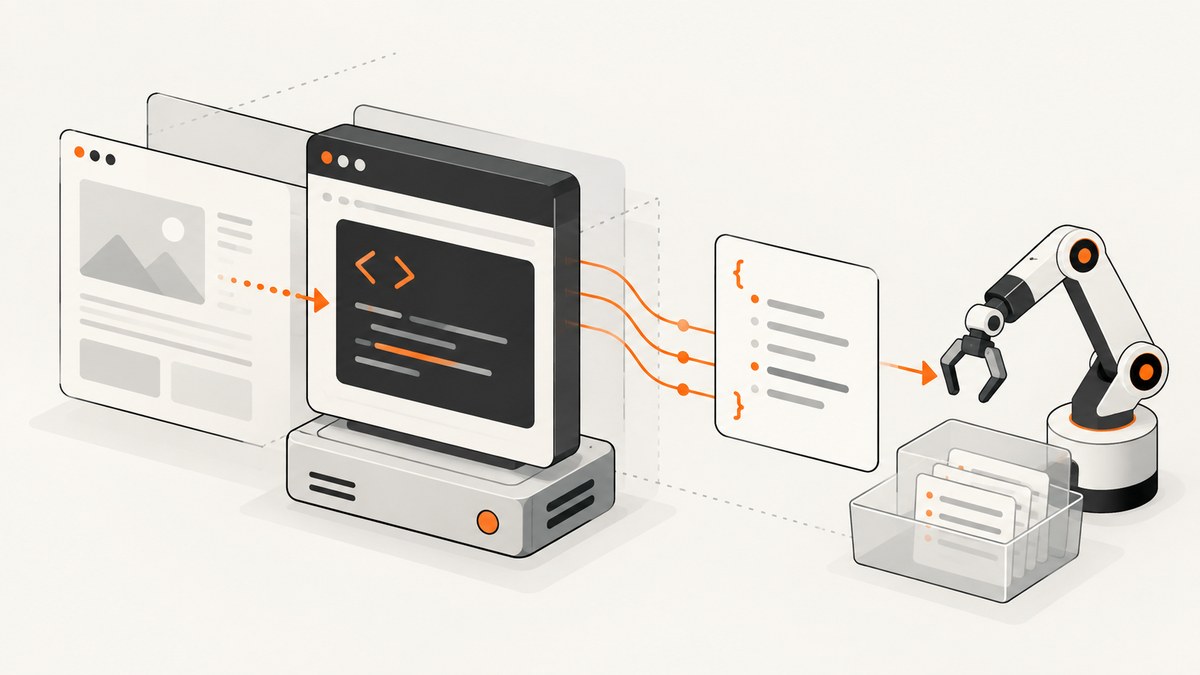
Direct answer: use Playwright’s page.evaluate() or Puppeteer’s page.evaluate(). The callback runs inside the web page’s JavaScript context, where window, document, and the page’s loaded scripts exist. Its return value crosses back to your automation process. Pass outside values as explicit arguments, await asynchronous callbacks, and return serializable data unless you deliberately need a live DOM handle.
This context boundary explains most evaluation bugs. Your Node.js automation script and the browser page are separate JavaScript environments. A variable declared in the automation script is not automatically visible inside the callback running in the page.
What evaluate actually does
When you call page.evaluate(), the browser serializes the function and executes it in the page. The automation library then transfers the result back. Playwright documents this model in its JavaScript evaluation guide; Puppeteer exposes the same operation through Page.evaluate().
const title = await page.evaluate(() => document.title);
console.log(title);
document.title is read in the page, while console.log runs in your automation process. The returned string is ordinary transferable data.
Set up a headless browser
Playwright
npm install playwright
npx playwright install chromium
const { chromium } = require('playwright');
(async () => {
const browser = await chromium.launch({ headless: true });
const page = await browser.newPage();
await page.goto('https://example.com', { waitUntil: 'domcontentloaded' });
const title = await page.evaluate(() => document.title);
console.log(title);
await browser.close();
})();Puppeteer
npm install puppeteerconst puppeteer = require('puppeteer');
(async () => {
const browser = await puppeteer.launch({ headless: true });
const page = await browser.newPage();
await page.goto('https://example.com', { waitUntil: 'domcontentloaded' });
const title = await page.evaluate(() => document.title);
console.log(title);
await browser.close();
})();Both examples launch Chromium, navigate, execute page-side JavaScript, print the result in Node.js, and close the browser. Pin the library and browser versions in CI when reproducibility matters.

Pass values across the context boundary
Do not rely on closure variables. Pass each value as an argument after the callback. This keeps the code explicit and avoids the common “variable is not defined” failure.
const selector = 'h1';
const heading = await page.evaluate((css) => {
  return document.querySelector(css)?.textContent?.trim() ?? null;
}, selector);

console.log(heading);
Arguments must be values the framework can serialize. Strings, numbers, booleans, arrays, and plain objects are the safest choices. For a configuration object:
const result = await page.evaluate(({ selector, attribute }) => {
  const element = document.querySelector(selector);
  return element ? element.getAttribute(attribute) : null;
}, { selector: 'meta[name="description"]', attribute: 'content' });
Keep page-side code self-contained. Imports, Node.js modules, filesystem APIs, and variables from the outer script are unavailable unless you expose data explicitly or inject a script into the page.
Evaluate asynchronous page code
If the callback returns a Promise, Playwright and Puppeteer wait for it to settle. Mark the callback async and return the value your automation process needs.
const status = await page.evaluate(async () => {
  const response = await fetch(location.href);
  return response.status;
});

console.log(status);
For application state, wait for a page condition before evaluating. A timer alone is often brittle because network and rendering times vary.
await page.waitForSelector('[data-ready="true"]');
const state = await page.evaluate(() => ({
  ready: document.body.dataset.ready,
  rows: document.querySelectorAll('table tbody tr').length
}));
You can also perform asynchronous work and return structured data:
const products = await page.evaluate(async () => {
  const response = await fetch('/api/products');
  if (!response.ok) throw new Error(`HTTP ${response.status}`);
  const data = await response.json();
  return data.items.map(item => ({ id: item.id, name: item.name }));
});
Errors thrown in the page are propagated to the automation script. Catch them there if you need a retry, diagnostic screenshot, or a custom failure message.
Read elements, attributes, and computed styles
const details = await page.evaluate((selector) => {
  const element = document.querySelector(selector);
  if (!element) return null;

  const style = getComputedStyle(element);
  const rect = element.getBoundingClientRect();
  return {
    text: element.textContent?.trim() ?? '',
    href: element instanceof HTMLAnchorElement ? element.href : null,
    display: style.display,
    width: rect.width,
    height: rect.height
  };
}, 'main h1');

console.log(details);
Return a plain object rather than the element itself. This makes the result stable and serializable and avoids transferring more page state than necessary.
When to use evaluation handles
A DOM node is a live object owned by the page. Returning it through ordinary evaluation does not give your Node.js code a normal, live DOM element. Puppeteer’s JavaScript execution guide explains that you should use evaluateHandle() or an ElementHandle for page objects; Playwright provides the corresponding evaluateHandle() API.
const handle = await page.evaluateHandle(() => document.querySelector('h1'));
const text = await handle.evaluate(element => element?.textContent?.trim() ?? null);
console.log(text);
await handle.dispose();
Use handles for operations that require the object to remain in the page, such as repeated property reads or passing a node to another page-side function. Dispose of handles when finished, especially in loops, to prevent retained objects from accumulating.
Frames and isolated execution
An iframe has its own document and JavaScript context. Evaluating on the main page cannot directly read cross-frame DOM. Locate the frame, then evaluate against that frame.
const frame = page.frames().find(f => f.url().includes('/checkout'));
if (!frame) throw new Error('Checkout frame was not found');

const total = await frame.evaluate(() => {
  return document.querySelector('[data-total]')?.textContent?.trim() ?? null;
});
Cross-origin restrictions still apply. A page cannot inspect another origin’s DOM through normal browser APIs. Evaluate inside the target frame only when the browser and page permit it.
Playwright and Puppeteer: practical differences
| Concern | Playwright | Puppeteer |
|---|---|---|
| Method | page.evaluate() |
page.evaluate() |
| Argument shape | Callback followed by serializable arguments | Callback followed by serializable arguments |
| Live page objects | evaluateHandle() |
evaluateHandle() or ElementHandle |
| Browser choice | Chromium, Firefox, and WebKit projects | Chrome and Firefox automation |
| Headless mode | Headless shell or a browser channel such as Chromium | Configured through launch options |
The core evaluation semantics are the same. Choose based on the runtime, browser coverage, fixtures, and existing project conventions. Chrome for Developers describes Puppeteer as a high-level browser automation API; the documentation does not establish a universal speed or quality winner.
Choose the browser mode deliberately
Headless implementations can differ. Playwright’s browser guide explains that its default headless shell is distinct from the newer Chromium channel mode, which uses the real Chrome browser, and warns that behavior can vary between them. If pixel fidelity, browser-specific APIs, or production parity matters, name the channel or executable in your configuration and validate in that same mode.
const { chromium } = require('playwright');
const browser = await chromium.launch({
  headless: true,
  channel: 'chromium'
});
Record the browser version, operating system, viewport, timezone, locale, and relevant feature flags with evaluation results. Those inputs can change layout and page behavior.
Reliable evaluation patterns
Wait for a meaningful condition
await page.goto(url, { waitUntil: 'domcontentloaded' });
await page.waitForFunction(() => window.app?.status === 'ready');
const data = await page.evaluate(() => window.app.export());
Return only what you need
Extract a small object or array instead of serializing an entire document. Smaller results reduce transfer time and make failures easier to diagnose.
Make failures observable
try {
  const value = await page.evaluate(() => document.querySelector('#result')?.textContent ?? null);
  if (value === null) throw new Error('Result element is missing');
} catch (error) {
  console.error('Page evaluation failed:', error);
  await page.screenshot({ path: 'evaluation-failure.png', fullPage: true });
  throw error;
}
Avoid unsafe string construction
Prefer an argument over interpolating untrusted input into a function string. Arguments preserve the boundary and reduce accidental code injection. Never pass secrets into page JavaScript unless the target page genuinely needs them; page scripts and third-party resources may be able to read them.
Performance considerations
- Reuse a browser process and create pages or contexts per job; launching a browser for every small evaluation adds startup overhead.
- Evaluate once to extract a complete record instead of making dozens of round trips for individual fields.
- Wait on selectors or application state rather than long fixed delays.
- Use a narrow selector and return compact data.
- Close pages and contexts after work, and dispose evaluation handles.
- For parallel jobs, cap concurrency according to available CPU, memory, and the target site’s rate limits.
Evaluation itself is usually cheap compared with browser startup, navigation, JavaScript execution, and network idle time. Measure your complete workflow if latency matters; the documentation provides API behavior, not a universal benchmark.

Troubleshooting common errors
| Error or symptom | Likely cause | Fix |
|---|---|---|
ReferenceError: x is not defined |
The callback cannot see an outer variable. | Pass x as an explicit argument. |
Result is undefined |
The callback did not return a value, or the selector matched nothing. | Add an explicit return and use optional chaining with a clear null check. |
| Promise result arrives too early | Asynchronous work was started but not returned. | Return or await the Promise inside an async callback. |
| DOM node becomes an empty object | A live page object was serialized as ordinary data. | Use evaluateHandle() or extract properties inside the page. |
| Element is missing in an iframe | The evaluation ran in the main frame. | Find the correct frame and call its evaluate(). |
| Timeout while waiting | The application never reached the assumed state, or the timeout is too short. | Inspect network and console logs, wait on a real condition, and set a bounded timeout. |
| Different result in CI | Browser channel, fonts, viewport, timezone, or page data differs. | Pin inputs and use the same browser mode as production. |
| Navigation succeeds but data is empty | Client rendering or API requests finish after navigation. | Wait for a selector, a known state variable, or the relevant response. |
Or skip the browser setup
If your goal is a clean screenshot rather than running arbitrary assertions, ScreenshotNeo provides a single GET request that returns PNG, JPEG, WebP, or PDF. Its capture pipeline accepts cookie and consent banners as a visitor and removes more than 60 known consent platforms, newsletter popups, and chat widgets before the shot. Each step can be turned off.
Only clean shots are billed. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers identify the page verdict and whether it was billed. The service also includes custom JavaScript and CSS, selector capture, waits, device presets, headers, cookies, user agents, authentication, blocking rules, PDF options, caching, signed links, asynchronous jobs, bulk capture, and an MCP server with take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients.
See the ScreenshotNeo documentation for all parameters. A minimal request is:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({
access_key: 'YOUR_API_KEY',
url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('shot.webp', buffer);ScreenshotNeo includes 1,000 shots per month free with no card. Paid plans start at $5 for 3,000 shots; every feature is available on every plan. Create a free ScreenshotNeo account.
FAQ
Does evaluate() run in Node.js?
No. The callback runs in the browser page. The returned value is delivered to Node.js.
Can I use browser globals?
Yes, inside the callback. window, document, and page-defined globals are available there.
Should I use a fixed delay?
Only when a delay is part of the behavior you need. Prefer a selector, response, or application state condition for deterministic automation.
Which library is faster?
The supplied documentation does not establish a universal winner. Compare your own browser mode, workload, and concurrency requirements.
Why did a returned element lose its methods?
Ordinary results are serialized. Use an evaluation handle for a live page object, or extract the needed fields before returning.