How to Export HTML to PDF with jsPDF
Export a browser-rendered HTML element to PDF with jsPDF, configure page layout, and troubleshoot fonts, images, page breaks, and canvas limits.
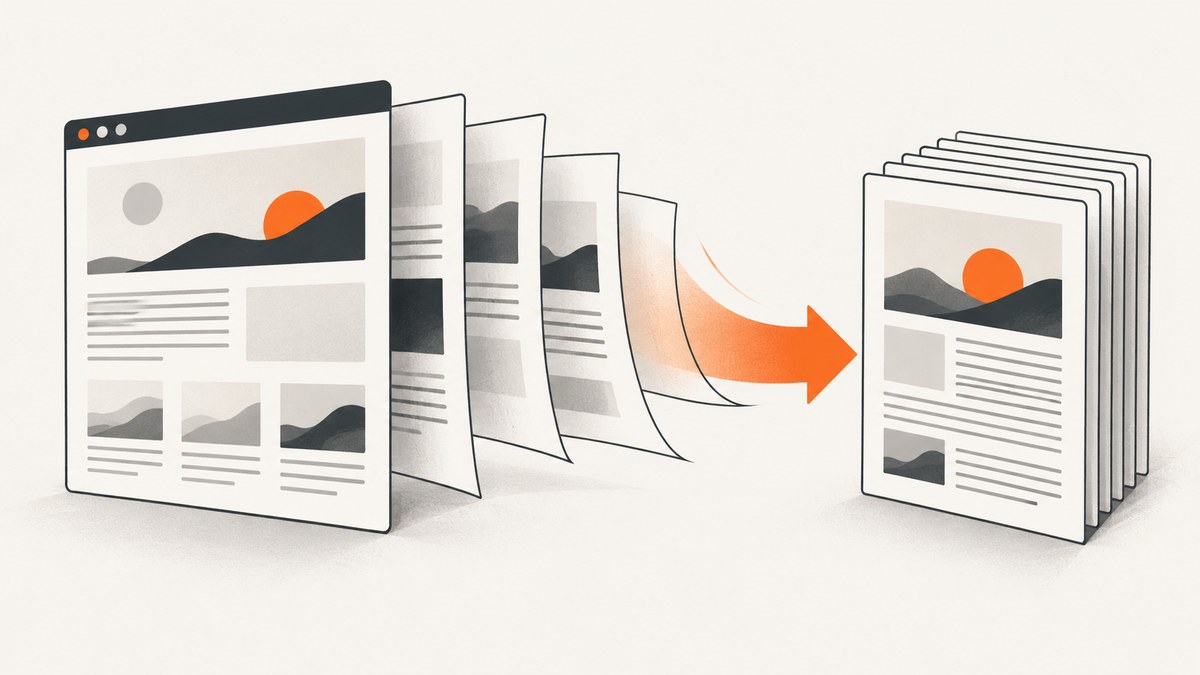
To export HTML to PDF with jsPDF, install jspdf, select a rendered DOM element, create a jsPDF document, and call doc.html(element, options). This renders the page through html2canvas, so the result is effectively a browser-rendered image placed into a PDF. It is a practical fit for visual exports, but text may not remain selectable, large pages can exceed canvas limits, and cross-origin images can fail.
This guide covers the direct jsPDF method first, then the separate html2pdf.js wrapper for page-break controls, fonts, security, troubleshooting, and alternatives when you need a PDF with real text. For exporting a web page as an image or PDF through an API instead of running browser code in your app, see the ScreenshotNeo website screenshot API.
1. Install jsPDF and render a DOM element
The jsPDF project documents html() as a browser-side method. Its HTML rendering depends on html2canvas; when you pass an HTML string rather than an element, DOMPurify is also needed. The packages are loaded dynamically when required, but installing them directly makes dependencies explicit in your build.
npm install jspdf html2canvas dompurifyIn a browser app, wait until the target element is present and its content has rendered before calling html(). Here is a minimal module example:
import { jsPDF } from 'jspdf';

const element = document.querySelector('#invoice');
if (!element) throw new Error('Could not find #invoice');

const doc = new jsPDF({
  orientation: 'portrait',
  unit: 'mm',
  format: 'a4'
});

await doc.html(element, {
  callback: (pdf) => pdf.save('invoice.pdf'),
  x: 10,
  y: 10,
  width: 190,
  windowWidth: element.scrollWidth
});
This assumes your app has an element such as <main id="invoice">...</main> in the document. The width is the rendered content width in the PDF’s document units. windowWidth tells the renderer the CSS viewport width to use; setting it to the element’s scroll width often helps keep the layout close to the source page. Check the result in your target browser because CSS, fonts, and external assets affect rendering.
The API is asynchronous in practice because html2canvas must render the element. Use the Promise form with await where supported by your installed jsPDF version. The callback form shown above is also useful when your codebase follows the documented callback pattern. Keep the PDF creation in a user-initiated browser action if the browser blocks downloads that are not connected to a click.
2. Choose the right rendering route
Direct jsPDF html() method
Use doc.html(element, options) when you already use jsPDF and want to control the document instance yourself. You can set document orientation, units, format, and then position and size the HTML rendering. The method is a bridge from DOM content into jsPDF; it does not turn arbitrary CSS into native PDF text layout.
html2pdf.js wrapper
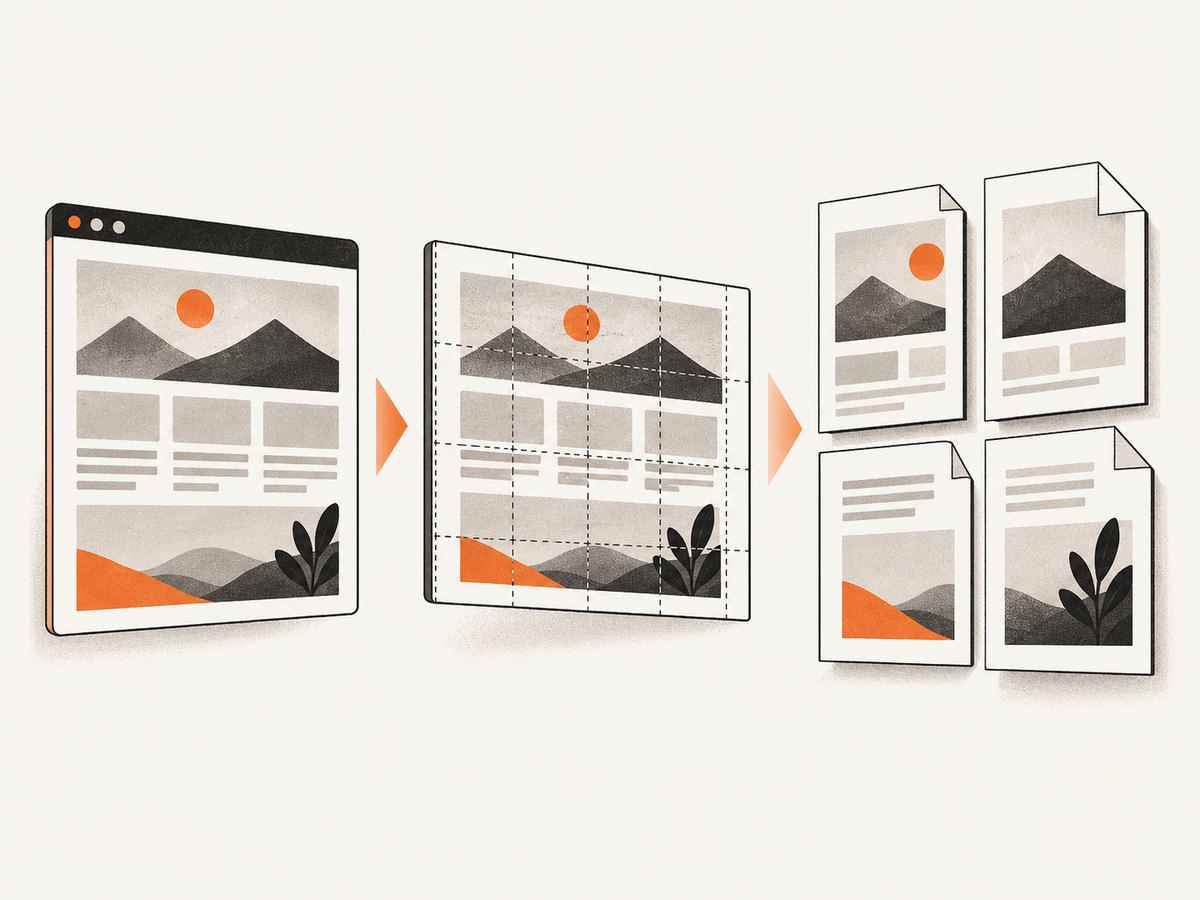
html2pdf.js is a separate client-side wrapper that chains html2canvas rendering into jsPDF output. Its flow is source element, container, canvas, image, PDF, then save. Use it when its fluent configuration and page-break options suit your page export. It is not the same API as jsPDF’s direct html() method.
import html2pdf from 'html2pdf.js';

const element = document.querySelector('#report');
if (!element) throw new Error('Could not find #report');

await html2pdf()
  .set({
    margin: [12, 10, 12, 10],
    filename: 'report.pdf',
    image: { type: 'jpeg', quality: 0.95 },
    html2canvas: { scale: 2, useCORS: true },
    jsPDF: { unit: 'mm', format: 'a4', orientation: 'portrait' },
    pagebreak: { mode: ['css', 'legacy'] }
  })
  .from(element)
  .save();
Install the wrapper with npm install html2pdf.js in addition to its peer rendering packages as needed. The margin values are top, right, bottom, and left. image controls the raster image type and quality; html2canvas passes renderer options; jsPDF sets PDF dimensions and orientation; and pagebreak controls how content is divided. Consult the wrapper’s README for the accepted options and current behavior.
| Need | Starting point | Trade-off |
|---|---|---|
| Integrate into an existing jsPDF flow | doc.html(element, options) |
Direct method, but layout remains browser-rendered |
| Fluent options and page-break rules | html2pdf().set(...).from(element).save() |
Convenient wrapper; output remains rasterized |
| Selectable, searchable text and document semantics | Generate the PDF from structured text/data or use a document-focused PDF tool | Requires a different layout approach than screenshotting the DOM |
3. Set page size, scale, and page breaks
jsPDF accepts standard page formats such as A4 and letter, orientation, and measurement units. Select the paper size for the audience and set dimensions intentionally. If a 190 mm content width is squeezed into a narrower printable area, the resulting page can look too small even though the PDF opens correctly.
- Margins: Reserve space with the document position and dimensions in direct jsPDF, or use html2pdf.js
margin. - Orientation: Use landscape for wide tables or dashboards, but check how content flows across pages.
- Scale: A higher html2canvas scale can improve visual detail, while increasing memory use and output size.
- Page breaks: In html2pdf.js, use its page-break modes and CSS break rules to keep headings and related blocks together. Test long tables and elements taller than a page.
For a repeatable export, give the source element a print-oriented class that fixes its width, background, and typography. Avoid relying on responsive breakpoints that change with the capture viewport. Wait for asynchronous content and web fonts before capturing; otherwise the PDF can contain fallback fonts, unloaded images, or a partially rendered page.
4. Fonts, Unicode, and text
There are two different font questions. In HTML rendering, the browser renderer needs the font resource to be available when the capture happens. For jsPDF’s native text APIs, the built-in PDF fonts have limited character coverage. The jsPDF documentation describes embedding TTF font data and registering it before selecting the font.
If you need native selectable text, add a TTF font that contains the required glyphs to jsPDF’s virtual file system, register it, and select it with setFont(). If you are rendering HTML through html2canvas, verify that the browser has loaded the font first. Unicode characters, CJK text, emoji, and symbols are useful test cases because a font can render Latin text while missing other glyphs.
// Native jsPDF text example after registering a suitable TTF font
const doc = new jsPDF();
doc.addFileToVFS('Custom.ttf', fontFileAsBase64);
doc.addFont('Custom.ttf', 'Custom', 'normal');
doc.setFont('Custom');
doc.text('Unicode text: café — 東京', 15, 20);
fontFileAsBase64 must contain the actual TTF file encoded as base64; it is a placeholder, not a built-in variable. Follow the jsPDF font documentation to create the VFS registration data. The selected font must include the characters you need.
5. Images, CORS, and content security
html2canvas cannot bypass browser cross-origin restrictions. If an image comes from another origin without suitable CORS permission, the canvas can be tainted and become unreadable. The useCORS: true option asks the renderer to load cross-origin images with CORS; it does not grant permission or override the remote server’s policy. Serve assets from your own origin, configure the asset host to allow the requesting origin, or omit the unavailable asset.
Test background images, SVGs, web fonts, and images behind authentication separately. A page that looks correct in the browser can still export with missing resources if the renderer cannot access them. Wait for image completion and font readiness before starting the capture.
For HTML strings or user-controlled content, sanitize input. The jsPDF project explicitly advises: “We strongly advise you to sanitize user input before passing it to jsPDF!” DOMPurify is the documented dependency for the string-input path, but sanitizing content does not make arbitrary active content or untrusted URLs safe by itself. Prefer a known DOM element built from trusted app data.
6. Export an existing website as a PDF
A front-end export captures the DOM in the browser where the script runs. It does not fetch a public URL and render that site by itself. If the goal is to export a URL your application can access, load and render that page in an appropriate browser context, then call the capture method on its element. Cross-origin framing and browser security boundaries may prevent inspecting another site’s DOM.
For a one-off export of the current page, a browser’s print-to-PDF feature can be simpler and can preserve text better depending on the browser and page print styles. For generated reports, server-side HTML-to-PDF tools may provide more predictable control over fonts and pagination. Choose based on whether visual similarity, text selection, CSS fidelity, or server automation matters most.
7. Performance, reliability, and cost
DOM-to-canvas export uses browser memory for the rendered canvas and intermediate image data. A long document at high scale can consume substantial memory, take longer to render, or exceed canvas dimension limits. html2pdf.js documents that very large canvas dimensions can fail and produce blank output. Split long exports into logical sections, reduce scale, or generate a document in a format that does not require one enormous canvas.
Because the capture depends on page state, reliability improves when the page is deterministic: wait for data, fonts, and images; use fixed export styles; avoid animations; and keep network resources available. Re-run after transient load failures, and report export failures to the user instead of silently saving a blank file. There is no universal size or speed threshold in the project documentation; test with the largest real report in the browsers and devices you support.
The libraries are open-source packages, so the main costs are engineering time, browser execution, memory, and any infrastructure you use to render pages. For remote rendering, an API can remove the need to maintain browser capture infrastructure. ScreenshotNeo’s API returns a PDF or image from one GET request, with usage-based plan limits and a free tier; its behavior and available parameters are documented at the ScreenshotNeo API docs.
8. Troubleshooting common export problems
| Symptom | Likely cause | Fix |
|---|---|---|
| PDF is blank | Capture started before content rendered, a rendering error occurred, or canvas dimensions were too large | Wait for app data, fonts, and images; inspect browser errors; reduce scale or split the document |
| Images disappear | Cross-origin policy, inaccessible URL, or image not loaded before capture | Use same-origin assets or configure CORS on the asset host; wait for image completion |
| Text is blurry or not selectable | HTML was rasterized through canvas | Use native PDF text or a document-focused generator when searchable text is required; increasing scale only improves raster sharpness |
| Text is clipped at page edges | Content width, margins, or viewport width do not match | Set a deliberate export width, adjust margins, and inspect at the chosen paper size |
| Sections split awkwardly | Automatic pagination encountered a tall block or missed a break rule | Add CSS break rules and html2pdf.js page-break configuration; test tables and repeated headers |
| Non-Latin characters become boxes | The selected font lacks glyphs | Load a font containing those glyphs; for native jsPDF text, embed and register a suitable TTF |
| Changes are missing from the PDF | Capture ran before state updates, font loading, or image decoding completed | Await the render/data pipeline and font readiness before calling html() |
| Download does not start | Browser blocked an automatic download or a Promise rejected | Trigger export from a user action and handle errors from the asynchronous call |
How do I fit the entire content in one page when printing it to PDF?
First decide whether a single page is actually readable. Reduce the element width only as needed, select landscape for wide content, and adjust scale or margins. A very long page shrunk onto one sheet can make text unusable and may create a canvas too large to render. If the content is naturally multi-page, let it flow across pages or split it into smaller exports rather than forcing everything onto one canvas.
9. Or skip the browser setup
If you need a screenshot or PDF of a public URL without adding browser capture dependencies to your app, use ScreenshotNeo. Its API accepts a URL in one GET request, can return PNG, JPEG, WebP, or PDF, and the request options cover full-page capture, page size, and other capture settings. See the API documentation for the complete parameter list.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
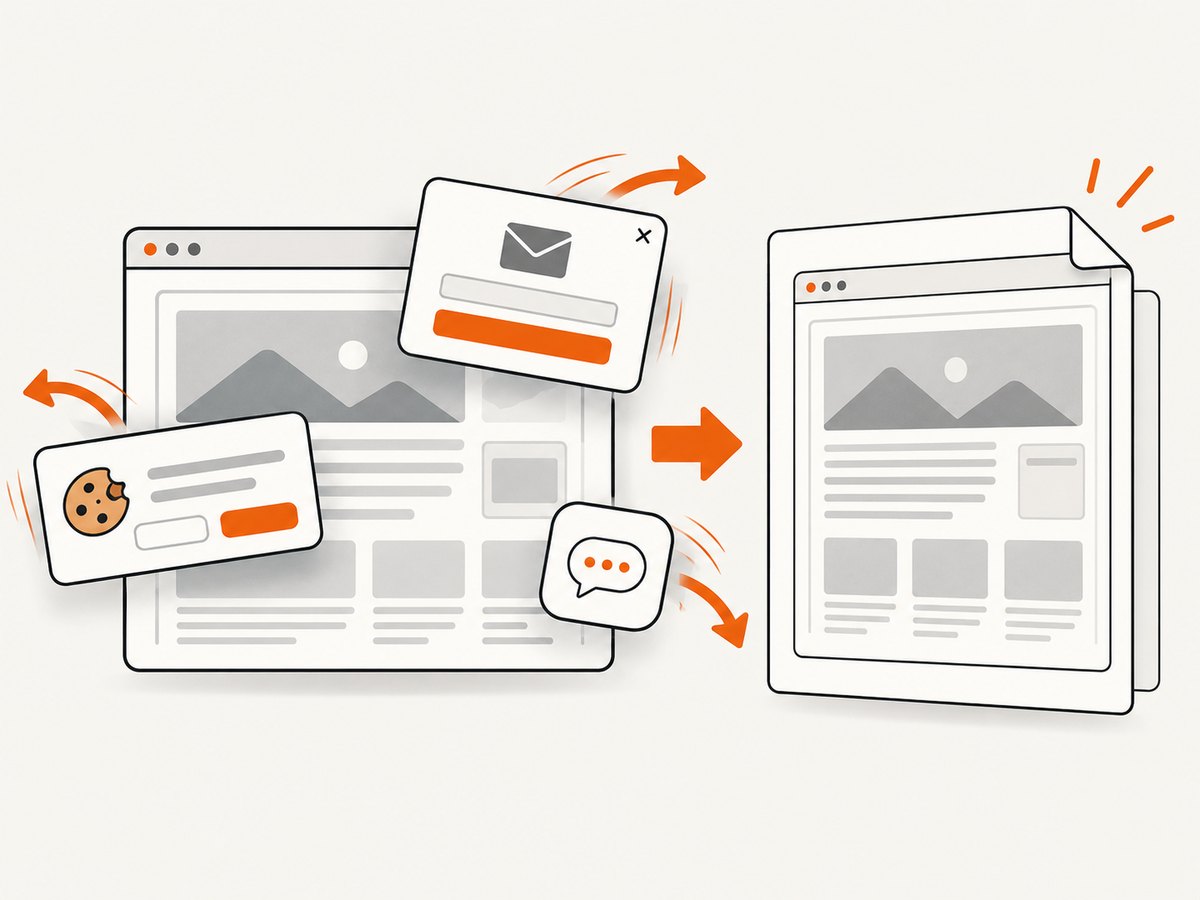
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);For PDF output, use the PDF format options described in the docs. ScreenshotNeo accepts cookie banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets before capture; each step can be turned off. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers report the page verdict and billing status. Its MCP server gives AI agents tools to take screenshots, get page information, and capture PDFs. The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account and start with 1,000 screenshots a month at no charge and no card required.
10. FAQ
Does jsPDF run in Node.js?
jsPDF has Node usage, but its html() route depends on browser DOM and canvas rendering. For server-side PDF generation, use a workflow designed for a server runtime or supply structured content through jsPDF’s native APIs.
Does html2pdf.js preserve selectable text?
No. Its HTML rendering path produces rasterized output, so text is not searchable or selectable. Choose a text-based PDF generation method when document semantics matter.
Can I convert an arbitrary URL with jsPDF?
Not directly. jsPDF’s HTML method renders a DOM element available to the running page. Loading an arbitrary URL and accessing its DOM is subject to browser security restrictions.
Which method should I choose?
Use direct jsPDF HTML rendering when you want the jsPDF method and already control the page DOM; use html2pdf.js when its wrapper options and page-break workflow fit. Use another PDF generation approach if selectable text, robust pagination, or large documents are essential.
Sources
- jsPDF project README and documentation for installation, HTML dependencies, security guidance, and font registration.
- html2pdf.js README for workflow, options, rasterization, and canvas limits.
- html2canvas documentation for browser rendering and cross-origin restrictions.