How to Export a Web Page to PDF With FPDF
Learn what FPDF can export, how to generate PDFs in PHP, and when to use a browser renderer for a real web page.
Short answer: FPDF creates PDF documents from content your PHP code supplies. It is a good fit for invoices, reports, letters, and other generated documents. It is not a browser engine and cannot reproduce an arbitrary, real-world web page with its CSS, JavaScript, responsive layout, and loaded assets. The official FPDF FAQ explicitly says it cannot convert real-world HTML pages; that is a different problem from building a PDF with PHP.
If you control the content, use FPDF. If you need a faithful capture of an existing URL, use a browser-based renderer such as ScreenshotNeo, which loads the page before creating a PDF.
What FPDF does—and does not do
FPDF is a PHP library for constructing PDF files. Your script chooses the page size, orientation, fonts, text, and other supported elements, then writes the result to a destination. The official tutorial demonstrates this sequence with an FPDF object, AddPage(), a font selection, text output, and Output():
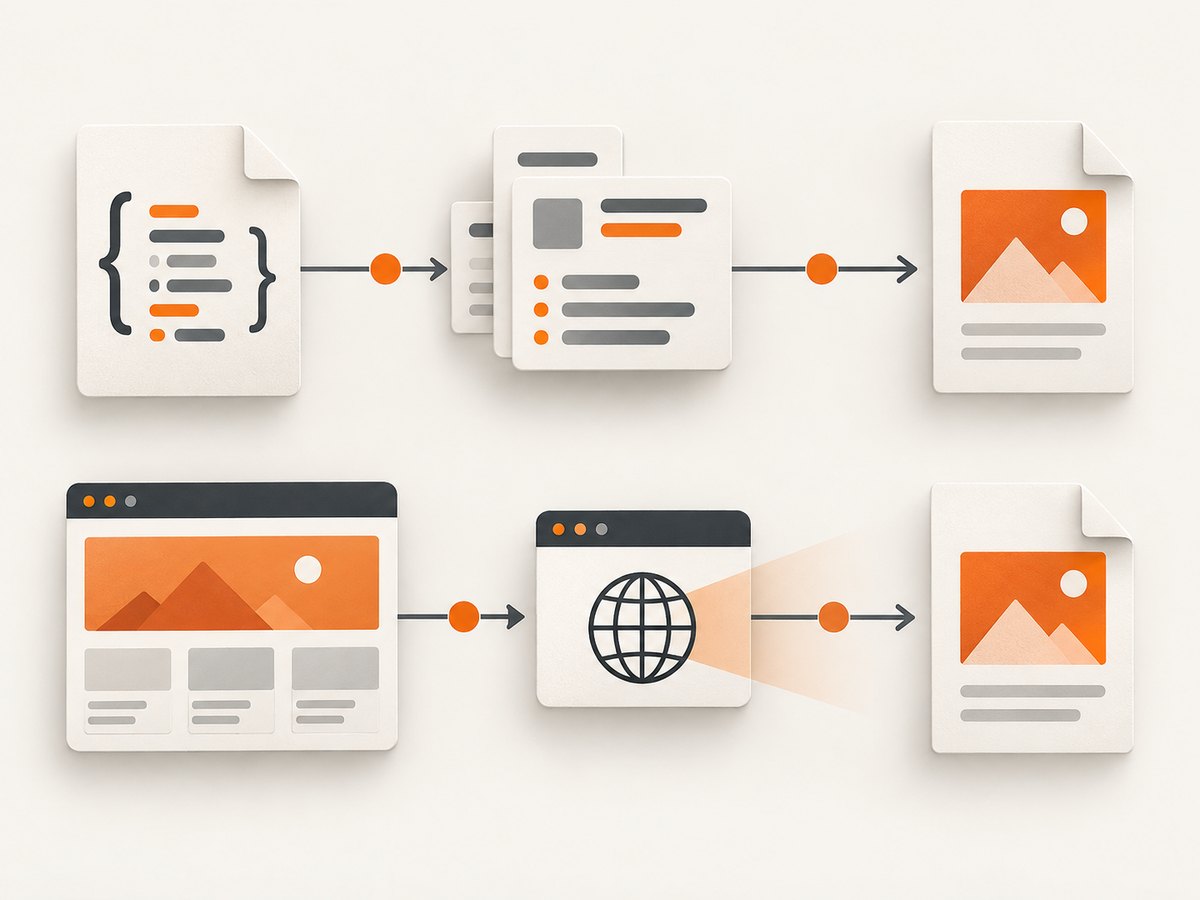
- Works well: generated reports, invoices, certificates, labels, receipts, and forms whose content is available to PHP.
- Does not provide: a browser layout engine, JavaScript execution, complete CSS support, or automatic loading of an arbitrary website.
- HTML helper limitation: the contributed
WriteHTML()script parses a limited set of markup such as bold, italic, underline, links, paragraphs, breaks, images, and font attributes. It does not establish full CSS or browser rendering.
The FPDF FAQ points readers who need real-world HTML conversion toward HTMLDOC, a separate GPL C utility. Confirm its current maintenance and deployment suitability before making it part of a production system.
Generate a PDF with FPDF in PHP
1. Include FPDF
Download FPDF from the official project and place its library files in your application. The exact include path depends on your project layout. The examples below assume fpdf.php is available in an fpdf/ directory.
2. Create a minimal PDF
<?php
require __DIR__ . '/fpdf/fpdf.php';

$pdf = new FPDF();
$pdf->AddPage();
$pdf->SetFont('Arial', '', 16);
$pdf->Cell(40, 10, 'Hello, PDF!');
$pdf->Output();
Run it through a PHP server and the PDF is sent to the browser. The same script can save a file or return the generated bytes by changing the output mode.
3. Produce a report with multiple lines
<?php
require __DIR__ . '/fpdf/fpdf.php';

$pdf = new FPDF('P', 'mm', 'A4');
$pdf->SetTitle('Monthly report');
$pdf->AddPage();
$pdf->SetFont('Arial', 'B', 18);
$pdf->Cell(0, 12, 'Monthly report', 0, 1, 'C');

$pdf->SetFont('Arial', '', 11);
$pdf->MultiCell(
    0,
    7,
    "This PDF was assembled by PHP with FPDF.\\n\\n"
    . "Replace this text with values from your application."
);

$pdf->Output('I', 'monthly-report.pdf');
MultiCell() is useful for flowing paragraphs. For long reports, add pages as your content reaches the bottom margin and keep the content model separate from presentation so the same data can be exported in another format.
Choose page orientation and size
The FPDF constructor accepts orientation, unit, and page size. AddPage() can also set page orientation and size for a particular page. Common choices are:
| Argument | Values | Use |
|---|---|---|
| Orientation | P, L |
Portrait or landscape |
| Unit | mm, pt, cm, in |
Measurement unit for coordinates and dimensions |
| Size | For example, A4 or Letter |
Paper dimensions |
<?php
require __DIR__ . '/fpdf/fpdf.php';

$pdf = new FPDF('L', 'mm', 'A4');
$pdf->AddPage();
$pdf->SetFont('Arial', '', 12);
$pdf->Cell(0, 10, 'Landscape A4 page');
$pdf->Output('F', __DIR__ . '/landscape-report.pdf');
Use landscape for wide tables and portrait for letters or conventional reports. If your document mixes layouts, call AddPage() with the settings needed for each new page.
Control where the PDF goes with Output()
The official Output() documentation defines four useful destinations:
| Mode | Behavior | Typical use |
|---|---|---|
I |
Send inline to the browser | Open a PDF viewer in the browser |
D |
Force a browser download | Download a user-requested report |
F |
Save to a local file | Batch jobs, archives, or queued processing |
S |
Return the PDF as a string | Store bytes, attach them to email, or send them through another API |
// Inline response
$pdf->Output('I', 'report.pdf');

// Force download
$pdf->Output('D', 'report.pdf');

// Save on the server
$pdf->Output('F', __DIR__ . '/exports/report.pdf');

// Keep the bytes in memory
$pdfBytes = $pdf->Output('S');
When sending a response from a PHP endpoint, do not print debug output before an inline, download, or file response. Extra bytes can corrupt the PDF stream or trigger header errors.
Adding HTML with WriteHTML()
The contributed WriteHTML() helper can translate a small, documented subset of HTML into FPDF calls. It is useful when your source is already simple markup, but it is not a general HTML-to-PDF converter.
<?php
require __DIR__ . '/fpdf/fpdf.php';
require __DIR__ . '/fpdf/html_table.php'; // Use the helper file from the script package.

$pdf = new PDF();
$pdf->AddPage();
$pdf->SetFont('Arial', '', 12);

$html = '<h1>Report</h1>'
      . '<p>A <b>short</b> paragraph with a '
      . '<a href="https://example.com">link</a>.</p>';

$pdf->WriteHTML($html);
$pdf->Output('I', 'html-report.pdf');
Check the helper’s own installation and supported-tag instructions before using this pattern. Do not expect external stylesheets, flexbox, grid, JavaScript, web fonts, complex tables, or responsive breakpoints to behave as they do in a browser.
When you actually need to export an existing web page
There are two different inputs:
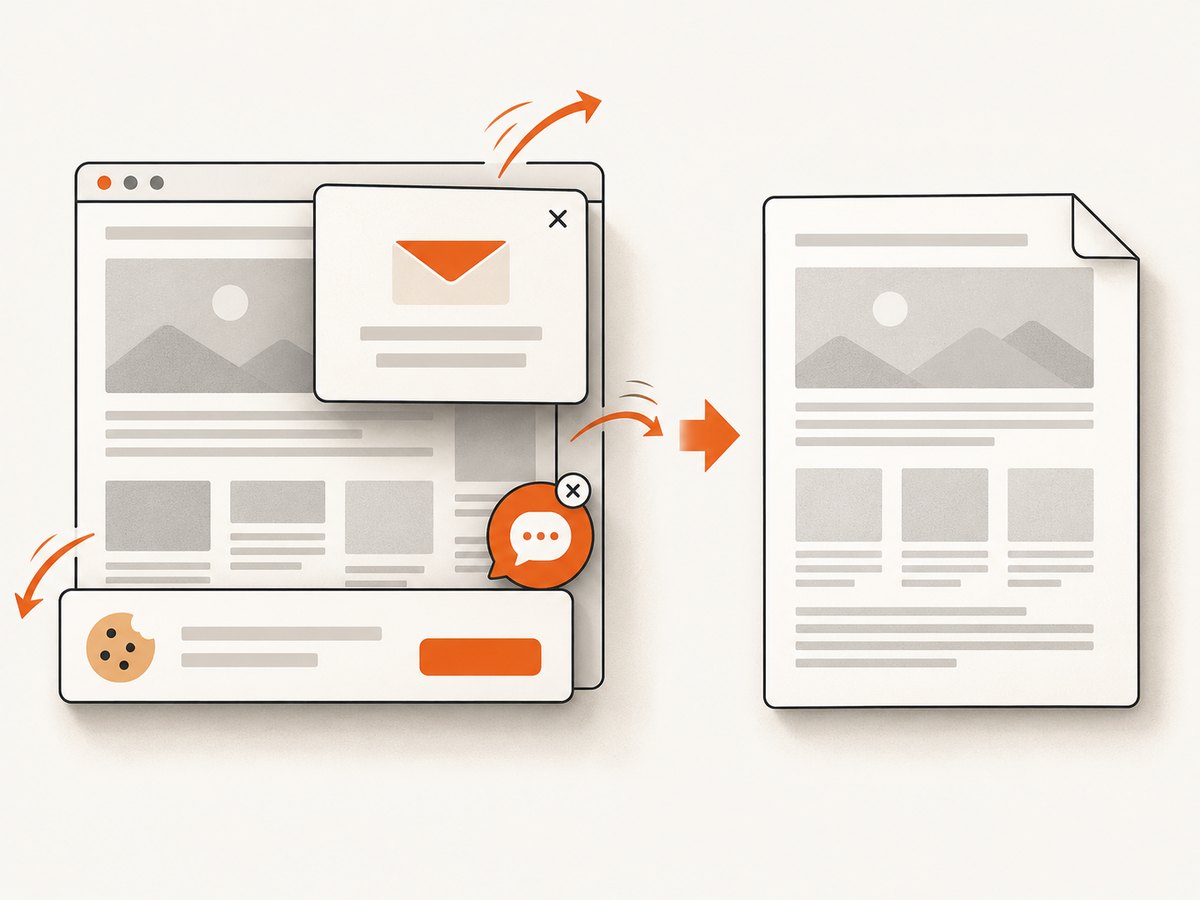
- Structured data you own: map that data to FPDF calls and control every line of the resulting document.
- An existing URL: load the page in a browser, wait for its resources and JavaScript, then print or capture the rendered page.
FPDF solves the first problem. It does not solve the second. Rebuilding a site by scraping its HTML and passing fragments through WriteHTML() usually loses the page’s CSS, dynamic content, layout rules, and state.
Or skip the browser setup
For a rendered URL, ScreenshotNeo provides a one-request PDF endpoint. See the ScreenshotNeo API documentation for the available PDF options.
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -d format=pdf \
  -o page.pdf
import requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={
"access_key": "YOUR_API_KEY",
"url": "https://stripe.com",
"format": "pdf",
},
timeout=90,
)
r.raise_for_status()
open("page.pdf", "wb").write(r.content)
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com',
  format: 'pdf',
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const pdf = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('page.pdf', pdf);
ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. Its MCP server exposes take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. You can use PDF paper size, margins, landscape mode, and page ranges, along with waits, custom headers and cookies, authentication, timezone, geolocation, request blocking, and caching with a chosen TTL.
The free plan includes 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 shots, and every feature is available on every plan. Create a free ScreenshotNeo account.
Troubleshooting FPDF exports
“FPDF error: Some data has already been output”
Cause: whitespace, warnings, notices, or debug text was sent before Output() set the PDF headers.
Fix: remove output before the PDF response, disable display of notices for the endpoint, and inspect included files for a closing PHP tag followed by whitespace.
The PDF downloads but is blank or corrupt
Cause: the script may have failed before writing content, or non-PDF bytes were mixed into the response.
Fix: check the PHP error log, save with Output('F', ...) while debugging, and verify that the saved file opens before switching back to an HTTP response.
HTML or CSS looks wrong
Cause: FPDF’s HTML helper supports only a limited tag and attribute set.
Fix: reduce the markup to supported elements and style it through FPDF calls. If the requirement is faithful rendering of a live page, use a browser-based PDF capture instead.
Images do not appear
Cause: the image path is wrong, the format is unsupported by the installed FPDF setup, or the process cannot read the file.
Fix: use an absolute or verified filesystem path, check file permissions, and confirm the image can be opened independently before adding it to the PDF.
Text has missing characters
Cause: the selected built-in font does not contain the required glyphs or encoding.
Fix: choose a font and encoding appropriate for the text, and verify the font licensing and embedding requirements for your deployment.
The output is the wrong size or orientation
Cause: the constructor and AddPage() settings differ from the page you are inspecting.
Fix: set orientation, unit, and paper size explicitly and apply the correct values whenever a new page starts.
Performance, reliability, and cost
- FPDF performance: generated documents are usually predictable because PHP writes only the content you provide. Large images, many pages, and keeping a complete PDF string in memory increase resource usage.
- Reliability: validate user data before writing it, handle file permissions for
Foutput, and keep generated files outside publicly served directories unless they are intentionally public. - HTTP delivery: use
IorDonly after the document has been generated successfully. For long jobs, generate to a file or queue the work rather than holding a request open. - Browser rendering: exporting a live page adds network, JavaScript, asset, and timeout variables. Use explicit waits and authentication settings where needed, and cache stable pages when appropriate.
- ScreenshotNeo billing: only clean shots are billed. Bot checks, blank pages, timeouts, failed loads, and cache hits cost nothing; inspect
X-Page-VerdictandX-Billedin your integration.
FAQ
Can FPDF convert any HTML page to PDF?
No. The official FAQ says FPDF does not convert real-world HTML pages. Its optional HTML helper handles a limited subset of markup.
Can I show the PDF in the browser instead of downloading it?
Yes. Pass I to Output() for inline display. Use D to force a download.
How do I save a PDF without sending it to the browser?
Pass F and a filesystem path to Output().
How do I email an FPDF document?
Generate it with Output('S'), then provide the returned string to the mail library’s attachment API.
What should I use for a pixel-accurate website PDF?
Use a browser renderer that loads the URL and prints the rendered page. ScreenshotNeo is an option when you want the page cleaned before capture and a PDF returned from one API request.
Is FPDF free to embed?
The official FPDF FAQ states that it is released under a permissive license with no usage restriction for commercial or noncommercial embedding.


