Using External Resources in Generated PDFs
Learn how to load images, CSS, JavaScript, fonts, and data reliably into generated PDFs while keeping builds reproducible and license-compliant.
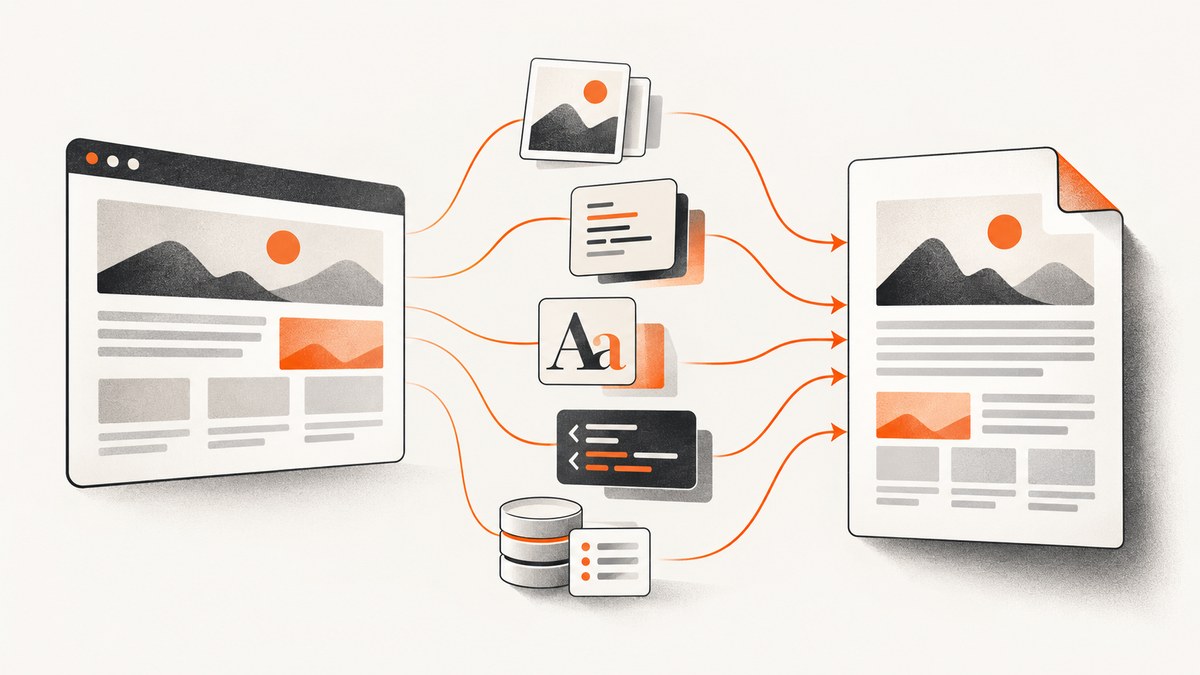
Generated PDFs often fail for a simple reason: the renderer cannot reach, trust, or reproduce an external resource. Images may be blank, web fonts may be substituted, CSS may arrive too late, and JavaScript data may never load. The reliable approach is to decide which assets should be embedded, which should be packaged with the job, and which may be fetched at render time under an explicit network policy.
Use this rule of thumb: embed small, critical assets; package the complete HTML bundle for deterministic builds; fetch remote resources only through HTTPS, allowlists, bounded timeouts, retries, and a cache. Then inspect the output for missing glyphs, broken images, layout shifts, and licensing problems.
What counts as an external resource?
An external resource is anything the renderer loads by URL or resolves outside the HTML document. Common examples include:
- Images referenced by
<img src>, CSS backgrounds, or SVG links. - Stylesheets loaded with
<link rel='stylesheet'>. - JavaScript files, modules, and data fetched with
fetch()or XHR. - Web fonts loaded through
@font-face. - Fonts selected by a document builder or template system.
- JSON, CSV, XML, or API responses used to populate a page.
Inline CSS and JavaScript, data-URI images, inline SVG, and system fonts can remove a network dependency where the renderer supports them. PDFMonkey documents these alternatives and their trade-offs.
Choose an asset strategy
| Strategy | Best for | Main risk |
|---|---|---|
| Inline | Small icons, critical CSS, tiny images, short scripts | Large HTML and difficult reuse |
| Versioned bundle | Invoices, reports, archival documents, regulated output | More packaging work |
| Remote fetch | Frequently changing data or shared assets | Outages, authentication, nondeterministic output |
| Cached remote fetch | Shared fonts, images, and stylesheets | Stale content unless TTL is controlled |
For production documents, keep index.html, CSS, JavaScript, images, and fonts in a versioned build bundle. Resolve relative paths locally, record hashes or versions, and render from that bundle. Adobe’s static HTML workflow uses the same model: an archive contains index.html at the top level and dependencies such as images and CSS. See the Adobe PDF Services documentation.
Package a deterministic HTML bundle
A bundle prevents a CDN change, authentication requirement, or temporary outage from changing a document after approval. A practical layout is:
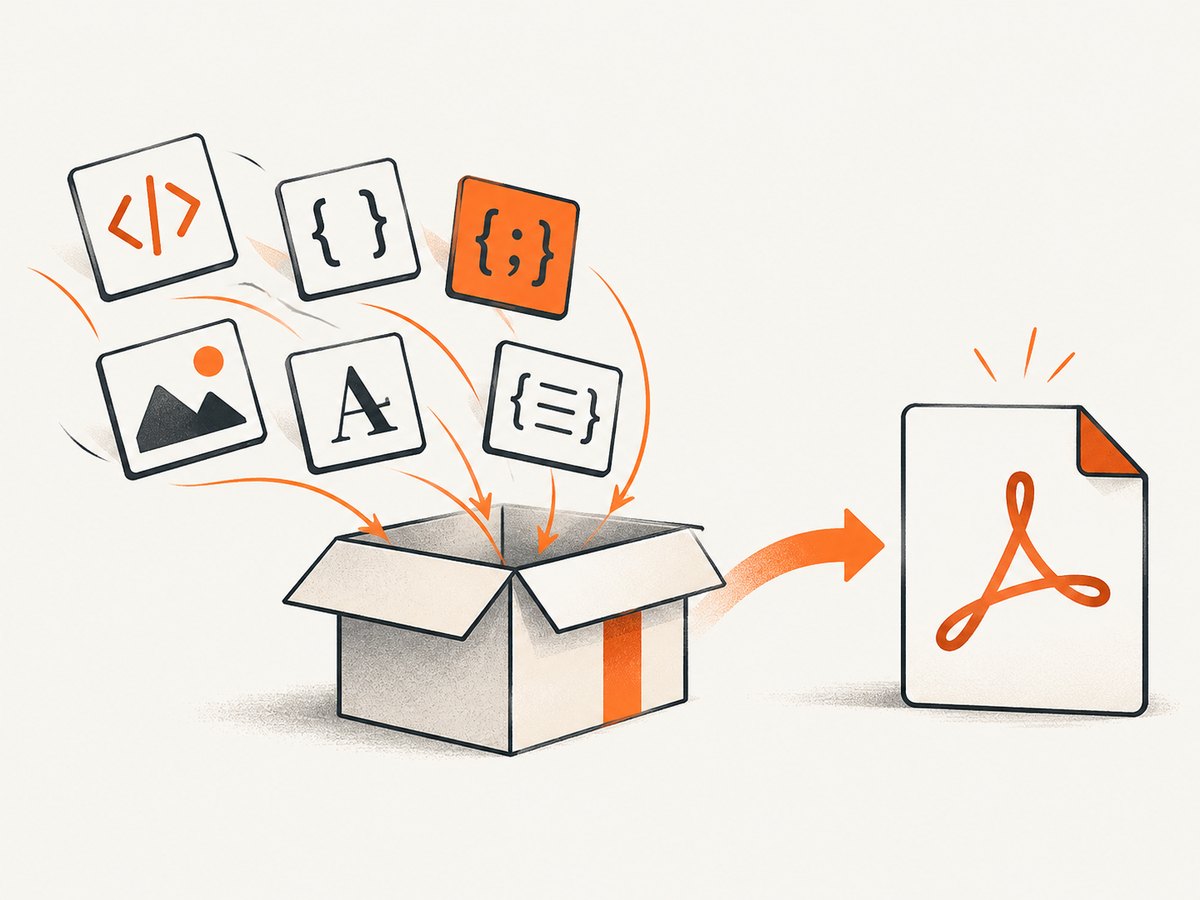
report-bundle/
  index.html
  css/
    report.css
  js/
    report.js
  images/
    logo.png
    chart.svg
  fonts/
    Inter-Regular.woff2
    Inter-Bold.woff2
  data/
    report.json
Use relative URLs in the HTML:
<link rel='stylesheet' href='./css/report.css'>
<script type='module' src='./js/report.js'></script>
<img src='./images/chart.svg' alt='Quarterly revenue chart'>
<style>
@font-face {
  font-family: 'Report Sans';
  src: url('./fonts/Inter-Regular.woff2') format('woff2');
  font-weight: 400;
  font-display: block;
}
body { font-family: 'Report Sans', sans-serif; }
</style>
The following Python program creates a reproducible ZIP archive, rejects missing files, and writes a manifest with SHA-256 hashes. It is runnable with Python 3 and uses only the standard library.
from pathlib import Path
import hashlib, json, zipfile

ROOT = Path('report-bundle')
REQUIRED = ['index.html', 'css/report.css', 'js/report.js']

missing = [p for p in REQUIRED if not (ROOT / p).is_file()]
if missing:
    raise SystemExit(f'Missing required files: {missing}')

manifest = {}
for path in sorted(p for p in ROOT.rglob('*') if p.is_file()):
    digest = hashlib.sha256(path.read_bytes()).hexdigest()
    manifest[str(path.relative_to(ROOT))] = digest
(ROOT / 'manifest.json').write_text(
    json.dumps(manifest, indent=2, sort_keys=True), encoding='utf-8'
)

with zipfile.ZipFile('report-bundle.zip', 'w', zipfile.ZIP_DEFLATED) as archive:
    for path in sorted(p for p in ROOT.rglob('*') if p.is_file()):
        archive.write(path, path.relative_to(ROOT))
print('Wrote report-bundle.zip with', len(manifest), 'files')
Fetch remote resources under an explicit policy
Sometimes a URL is unavoidable: a customer image, a live data endpoint, or a centrally managed stylesheet. Treat every URL as an input that needs policy. Require HTTPS, allow only known hosts and paths, set connect and total timeouts, retry transient failures, and report the failed asset clearly.
Do not let arbitrary user input reach private network ranges. Adobe documents restrictions on non-HTTPS and non-routable URL targets for HTML conversion. TCPDF’s remote-resource guidance also describes host and path allowlists and optional caches.
from urllib.parse import urlparse
import ipaddress, socket

ALLOWED_HOSTS = {'static.example.com', 'cdn.example.com'}

def validate_url(raw):
    parsed = urlparse(raw)
    if parsed.scheme != 'https' or parsed.hostname not in ALLOWED_HOSTS:
        raise ValueError('URL must use HTTPS and an allowed host')
    addresses = socket.getaddrinfo(parsed.hostname, 443, type=socket.SOCK_STREAM)
    for item in addresses:
        address = ipaddress.ip_address(item[4][0])
        if address.is_private or address.is_loopback or address.is_link_local:
            raise ValueError('Private and local addresses are not allowed')
    return raw

for asset in ['https://static.example.com/report.css']:
    print(validate_url(asset))
In a real renderer, apply the same checks to redirects, not only the initial URL. Record response status, content type, byte size, and a content hash. Fail the job when a required asset is unavailable instead of silently producing a damaged PDF.
Fonts, glyphs, and layout stability
Fonts affect line wrapping, pagination, and language coverage. Embed fonts or package them with the job when the license permits. If a requested font is unavailable, a service may substitute another font, changing widths and glyph selection. Apache PDFBox supports creating PDFs with embedded fonts and images; its project documentation describes it as an open source Java tool for working with PDF documents.
Test every script your audience needs, including Arabic, CJK, Cyrillic, and Hebrew. Check combining marks, right-to-left ordering, emoji behavior, and fallback when a font lacks a glyph. Subsetting can reduce file size where supported, but retain the full license and source information required by the font vendor.
Images, SVG, and data
For small, immutable images, a data URI or inline SVG avoids a fetch. For large photos or repeated graphics, package files or use a controlled cache. Confirm that the renderer supports the image format, color profile, transparency, and SVG features you use.
Data-driven documents should snapshot their input. Store the JSON or CSV used for a render alongside the template and record its version or hash. If JavaScript fetches data during rendering, wait for the data request and make failures visible. A successful HTTP response is not enough: validate that the body is the expected JSON shape and that required fields are present.
Wait for resources before PDF conversion
Asynchronous rendering creates race conditions. A page can finish loading while fonts, images, or data requests are still pending. Use a renderer’s network-idle or explicit selector wait when available, plus a bounded maximum delay. Waiting forever is as harmful as waiting too little.
- Start the document with a loading state.
- Load CSS, fonts, images, and data.
- Replace the loading state with the final content.
- Set a dedicated marker such as
window.renderReady = trueordata-render-ready='yes'. - Have the PDF job wait for that marker, then capture.
<div id='status'>Loading…</div>
<main id='report' hidden></main>
<script>
(async () => {
  try {
    const data = await fetch('./data/report.json').then(r => {
      if (!r.ok) throw new Error(`HTTP ${r.status}`);
      return r.json();
    });
    document.querySelector('#report').textContent = data.title;
    document.querySelector('#report').hidden = false;
    document.querySelector('#status').remove();
    window.renderReady = true;
  } catch (error) {
    document.querySelector('#status').textContent = `Render failed: ${error.message}`;
  }
})();
</script>
Licensing follows the asset into the PDF
Embedding an image, font, stylesheet, script, or dataset can create redistribution obligations. Check whether the license permits embedding, modification, subsetting, and distribution of the resulting PDF. Keep license records with the build artifact. TCPDF’s official guides include custom-font import information and material about third-party font licenses.
Also review service terms when a hosted converter fetches or stores your assets. For confidential documents, understand retention, access controls, and whether remote URLs expose sensitive identifiers.
Hosted API or self-hosted library?
| Decision area | Hosted API | Self-hosted PDFBox or TCPDF |
|---|---|---|
| Packaging | URL, ZIP, and supported input assets | Your files, streams, or URLs |
| Network policy | Service-defined restrictions | Your allowlists, proxy, timeout, and cache |
| Fonts | Embed or package where supported; unavailable fonts may substitute | Explicit import and embedding APIs |
| Operations | Less renderer infrastructure | More control and upgrade responsibility |
| Archival output | Confirm required profile support | TCPDF documents PDF/A modes; validate output |
PDFBox is a Java library; TCPDF is a PHP-oriented option. Choose based on runtime ownership, network controls, font workflow, language coverage, and whether you need PDF/A or another conformance profile.
Or skip the browser setup
If your input is a web page and you need a screenshot or PDF without maintaining browser infrastructure, ScreenshotNeo provides a GET-based capture API. See the API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
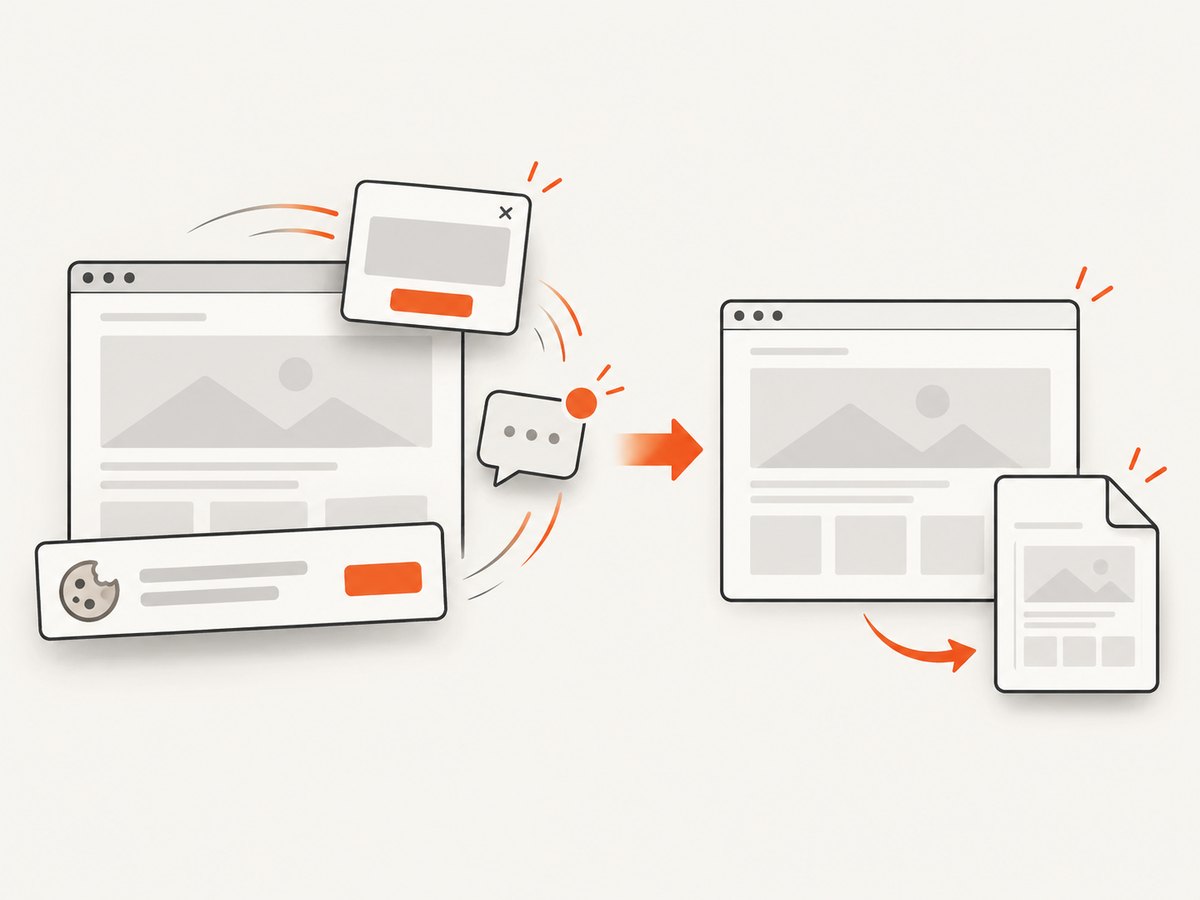
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing status. Its MCP server exposes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
Troubleshooting checklist
Images are blank or broken
Check the final URL after redirects, HTTPS certificate validity, response status, content type, and whether the image requires authentication. Package the image or use a permitted allowlist. Inspect the renderer log for blocked mixed-content requests.
Web fonts are missing
Verify the font URL, CORS policy, supported format, and license. Wait for document.fonts.ready where supported. Embed or package the font and confirm the selected weight exists; otherwise a fallback font can change pagination.
CSS appears ignored
Confirm that the stylesheet loaded before capture, that relative paths resolve from the expected directory, and that print media rules do not override screen rules. Inline a small critical stylesheet when network timing is unreliable.
JavaScript data is absent
Wait for an explicit ready marker, check API status codes and response shape, and capture console or network errors. Give the job a finite timeout and return a clear failure instead of an incomplete PDF.
Requests are rejected
Use HTTPS, an allowed host, and a routable address. Check redirects against the same policy. Do not permit private IP ranges or arbitrary user-controlled destinations.
Pagination changed between runs
Pin asset versions, embed fonts, snapshot data, and record hashes. A changed font, image dimension, stylesheet, or API response can move page breaks.
Performance, reliability, and cost
- Performance: Inline only small assets. Cache shared fonts and stylesheets with a controlled TTL. Avoid repeatedly downloading the same large image.
- Reliability: Retry transient network failures with backoff, but fail quickly on policy violations, authentication errors, and invalid content.
- Reproducibility: Keep a manifest of asset hashes, template version, renderer version, and input data.
- Security: Restrict hosts and paths, validate redirects, limit response size, and protect credentials in headers and cookies.
- Cost: Measure bandwidth, render time, storage, and hosted conversion charges. Caching and bundling reduce repeated downloads; embedding can increase PDF size.
Validate every generated PDF
- Open the PDF with a text extractor and verify expected text and glyphs.
- Render pages to images and inspect images, transparency, clipping, and page breaks.
- Compare file size and page count against a known-good fixture.
- Check metadata and embedded fonts when archival or compliance rules require them.
- If PDF/A is required, select the target profile and validate the final file. Treat validation as a QA step, not an assumption about renderer output.
FAQ
Should every asset be embedded?
No. Embed small, critical assets; package larger assets for deterministic builds; fetch remote content only under policy.
Why does a browser preview work while the PDF fails?
The preview may have cached credentials, fonts, or assets. The renderer may run in a different network, with stricter URL rules or a shorter timeout.
Can a PDF contain licensed web fonts?
Only when the font license permits embedding and redistribution. Verify the license and retain its records.
Is a cache always safe?
No. A cache improves reliability but can serve stale assets. Use a documented TTL or content-hash key and invalidate it when versions change.
How do I handle confidential remote data?
Prefer a packaged snapshot or a controlled proxy, minimize credentials, restrict destinations, and review the hosted service’s retention and access terms.


