How to Extract Structured Data with Schema.org Microdata
Learn to parse Schema.org Microdata, including nested items and itemref, with runnable Python, JavaScript, validation, and production troubleshooting.
Schema.org Microdata is HTML markup that describes entities such as articles, products, events, people, and offers. To extract it, locate elements with itemscope, read the vocabulary URL in itemtype, collect descendant elements marked itemprop, and recursively parse nested items. If properties live outside the item subtree, follow IDs listed in itemref. Preserve repeated properties as arrays, resolve URLs, and validate the extracted graph with a structured-data validator.
Microdata has three pieces: itemscope creates an item boundary, itemtype identifies its Schema.org type, and itemprop names a property. The HTML syntax is defined by the HTML standard, while Schema.org defines what types and properties mean. MDN’s Microdata guide and Schema.org Getting Started documentation are the primary references.
What Microdata looks like
Here is a complete item containing text, a URL, a date, and a nested ImageObject:
<div itemscope itemtype="https://schema.org/Article">
  <h1 itemprop="headline">How to Extract Structured Data</h1>
  <a itemprop="author" href="/authors/lee">Lee Chen</a>
  <time itemprop="datePublished" datetime="2026-09-29">September 29, 2026</time>
  <div itemprop="image" itemscope itemtype="https://schema.org/ImageObject">
    <img itemprop="contentUrl" src="/images/article.png" alt="">
  </div>
</div>
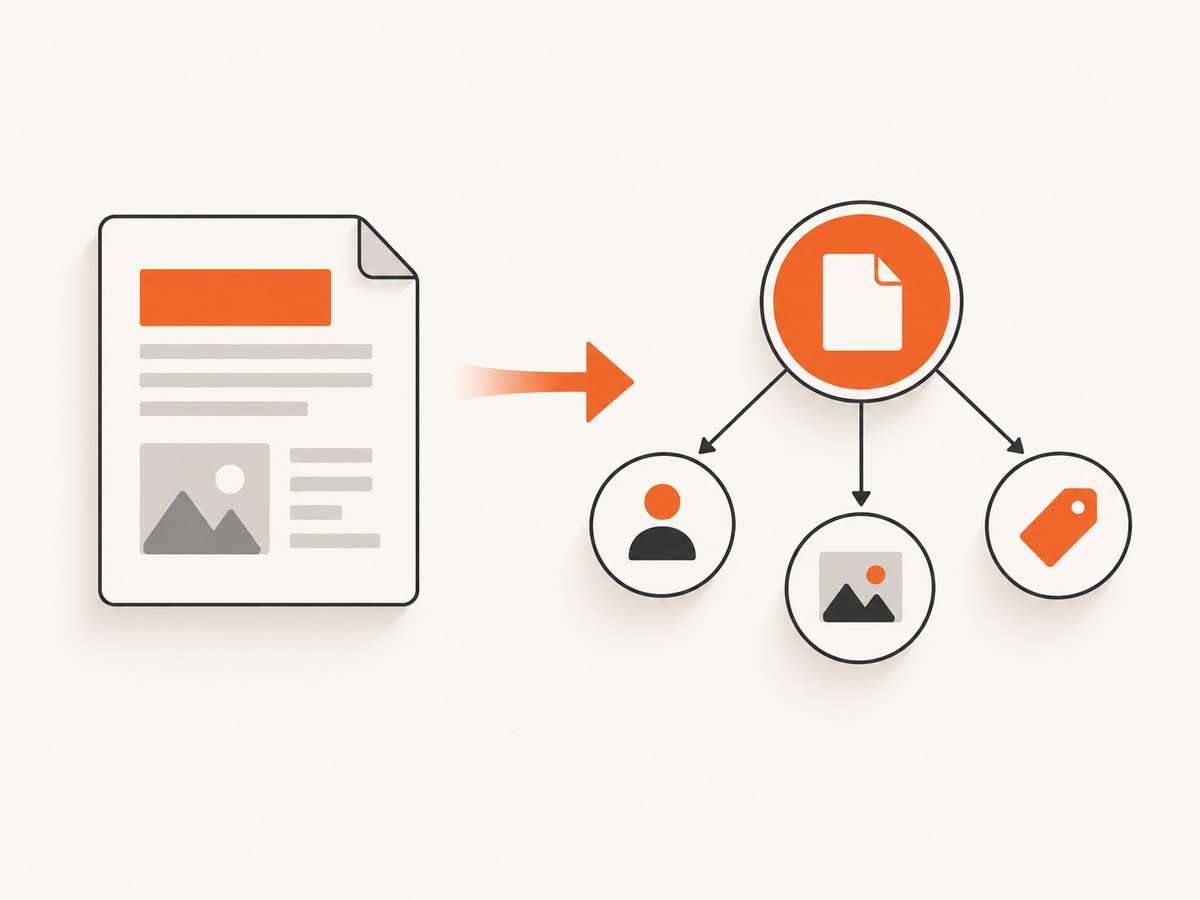
The outer element is an Article item. Its properties are headline, author, datePublished, and image. The image value is another item, so the extractor should retain it as a child object instead of flattening it.
Extraction rules you must implement
1. Find item scopes
An element with itemscope starts an item. Its descendant properties belong to that item until another nested itemscope starts a child item. An item can have no itemtype; in that case retain a null type and still collect properties.
2. Read the type and identifier
itemtype is a space-separated set of unique absolute vocabulary URLs. Schema.org markup normally uses one URL such as https://schema.org/Product. If present, itemid identifies the item. Resolve relative identifiers against the page URL.
3. Extract values according to the element
The value is not always visible text:
meta: use itscontentattribute.audio,embed,iframe,img,source,track, andvideo: use the relevant URL attribute, normallysrc.a,area, andlink: usehref.object: usedata.dataandmeter: usevalue.time: usedatetimewhen present; otherwise use its text.- Other elements: use their text content.
Resolve URL values with the document’s base URL. An element may contain multiple space-separated property names, for example itemprop="name alternateName"; add the same value to both properties.
4. Parse nested items recursively
If an element has both itemprop and itemscope, its value is a child item. Parse that child using the same rules. Do not also use the child’s rendered text as the parent property value.
5. Follow itemref
itemref contains space-separated element IDs. After collecting descendants, locate each referenced element and collect its properties as if they were descendants of the item. Follow nested references carefully and keep a visited set to avoid cycles.
6. Preserve cardinality
Microdata permits repeated properties. Always represent properties as arrays, even when there is one value. This prevents later data from silently overwriting earlier values.
A runnable Python extractor
The following script uses BeautifulSoup and implements scopes, nested items, URL resolution, repeated properties, and itemref. Install the dependencies with python -m pip install requests beautifulsoup4.
from urllib.parse import urljoin
import requests
from bs4 import BeautifulSoup, Tag

URL = "https://example.com/page"
html = requests.get(URL, timeout=30, headers={"User-Agent": "microdata-extractor/1.0"}).text
soup = BeautifulSoup(html, "html.parser")

def value_for(el, base_url):
    if el.name == "meta":
        return el.get("content", "")
    if el.name in {"audio", "embed", "iframe", "img", "source", "track", "video"}:
        attr = "src"
        raw = el.get(attr, "")
        return urljoin(base_url, raw) if raw else ""
    if el.name in {"a", "area", "link"}:
        raw = el.get("href", "")
        return urljoin(base_url, raw) if raw else ""
    if el.name == "object":
        raw = el.get("data", "")
        return urljoin(base_url, raw) if raw else ""
    if el.name in {"data", "meter"}:
        return el.get("value", "")
    if el.name == "time":
        return el.get("datetime") or el.get_text(" ", strip=True)
    return el.get_text(" ", strip=True)

def add_property(props, names, value):
    for name in names:
        props.setdefault(name, []).append(value)

def parse_item(el, base_url, seen_refs=None):
    seen_refs = set() if seen_refs is None else seen_refs
    result = {
        "type": (el.get("itemtype") or "").split() or None,
        "id": urljoin(base_url, el["itemid"]) if el.get("itemid") else None,
        "properties": {}
    }

    def visit(node):
        if not isinstance(node, Tag):
            return
        if node is not el and node.has_attr("itemscope"):
            if node.has_attr("itemprop"):
                child = parse_item(node, base_url, seen_refs)
                add_property(result["properties"], node["itemprop"].split(), child)
            return
        if node.has_attr("itemprop"):
            add_property(result["properties"], node["itemprop"].split(), value_for(node, base_url))
        for child in node.children:
            visit(child)

    for child in el.children:
        visit(child)

    for ref_id in el.get("itemref", '').split():
        if ref_id in seen_refs:
            continue
        seen_refs.add(ref_id)
        ref = soup.find(id=ref_id)
        if ref:
            visit(ref)
    return result

items = []
for el in soup.find_all(itemscope=True):
    # Only emit top-level items; nested items are included by their parent.
    parent = el.find_parent(itemscope=True)
    if parent is None:
        items.append(parse_item(el, URL))

import json
print(json.dumps(items, indent=2, ensure_ascii=False))
Replace URL with the page you are allowed to fetch. For production use, check HTTP status codes, content types, robots policies, response size, and an explicit request rate limit.
Equivalent browser JavaScript
When extraction runs in a browser or crawler that already has a DOM, this compact version returns the same object shape:
function extractMicrodata(document, baseUrl = document.baseURI) {
  const urlAttrs = new Map([
    ['A', 'href'], ['AREA', 'href'], ['LINK', 'href'], ['IMG', 'src'],
    ['AUDIO', 'src'], ['VIDEO', 'src'], ['SOURCE', 'src'], ['IFRAME', 'src'],
    ['OBJECT', 'data']
  ]);
  const seenRefs = new Set();
  const value = el => {
    if (el.tagName === 'META') return el.getAttribute('content') || '';
    if (el.tagName === 'TIME') return el.getAttribute('datetime') || el.textContent.trim();
    if (el.tagName === 'DATA' || el.tagName === 'METER') return el.getAttribute('value') || '';
    const attr = urlAttrs.get(el.tagName);
    if (attr) return new URL(el.getAttribute(attr) || '', baseUrl).href;
    return el.textContent.replace(/\\s+/g, ' ').trim();
  };
  function parse(el) {
    const out = { type: el.getAttribute('itemtype')?.split(/\\s+/) || null,
      id: el.hasAttribute('itemid') ? new URL(el.getAttribute('itemid'), baseUrl).href : null,
      properties: {} };
    const add = (node) => {
      if (!(node instanceof Element)) return;
      if (node !== el && node.hasAttribute('itemscope')) {
        if (node.hasAttribute('itemprop')) for (const p of node.getAttribute('itemprop').split(/\\s+/))
          (out.properties[p] ??= []).push(parse(node));
        return;
      }
      if (node.hasAttribute('itemprop')) for (const p of node.getAttribute('itemprop').split(/\\s+/))
        (out.properties[p] ??= []).push(value(node));
      node.childNodes.forEach(add);
    };
    el.childNodes.forEach(add);
    for (const id of (el.getAttribute('itemref') || '').split(/\\s+/)) {
      if (!id || seenRefs.has(id)) continue;
      seenRefs.add(id); document.getElementById(id)?.childNodes.forEach(add);
    }
    return out;
  }
  return [...document.querySelectorAll('[itemscope]')].filter(e => !e.parentElement?.closest('[itemscope]')).map(parse);
}
Fetching dynamic pages and screenshots
Server-side HTTP clients see only the initial HTML. If JavaScript adds Microdata after load, use a real browser, wait for the relevant selector or network idle, then read the rendered DOM. A screenshot can help you inspect what a user sees, but it is not a substitute for extracting the DOM and attributes. For pages behind consent dialogs, popups, or chat widgets, ScreenshotNeo can produce a clean visual reference before you compare the rendered page with extracted markup.

Or skip the browser setup
For a visual check of a page while you build an extractor, call ScreenshotNeo’s API. See the ScreenshotNeo documentation for all options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://schema.org/docs/gs.html -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://schema.org/docs/gs.html"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://schema.org/docs/gs.html' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing status. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
Validation and schema semantics
Extraction tells you what the HTML says; validation tells you whether that graph uses Schema.org correctly. Check each type’s page for allowed properties and expected value meanings. Run the page through the Schema Markup Validator and inspect detected items, types, properties, and warnings. A syntactically valid itemprop can still be inappropriate for the selected type.
Keep the vocabulary URL intact in your output. Do not reduce https://schema.org/Article to just Article, because downstream systems may need the absolute identifier. Store unknown properties rather than dropping them; Schema.org evolves and consumers may recognize extensions later.
Common errors and fixes
| Symptom | Cause | Fix |
|---|---|---|
| No items found | Markup is injected by JavaScript or the request received a bot page. | Use a browser, wait for the item selector, and log the final HTML and status. |
| Nested properties attached to the parent | The walker does not stop at a nested itemscope. |
When a child scope is encountered, parse it as a child and do not descend into it for the parent. |
| Images or links are blank | Extractor reads text instead of URL attributes. | Use src, href, data, or the documented value attribute, then resolve with the base URL. |
| Detached properties missing | itemref was ignored or IDs were looked up in the wrong document. |
Split the attribute on whitespace, resolve each ID in the same DOM, and track visited references. |
| Repeated values disappear | A dictionary assignment overwrites earlier values. | Represent every property as an array. |
| Wrong date or price | Visible formatting was parsed instead of machine-readable attributes. | Prefer datetime, content, or value; preserve the original string before normalization. |
| Validator warnings | Type and property do not match Schema.org definitions. | Open the current type page, correct the vocabulary or property, and validate again. |
Reliability, performance, and cost
Reliability checklist
- Set connection and read timeouts separately.
- Retry transient 429 and 5xx responses with exponential backoff and a cap.
- Cache by canonical URL plus relevant request headers.
- Record the final URL, status, content type, parser version, and extraction timestamp.
- Limit maximum response bytes and reject non-HTML content.
- Keep raw HTML for debugging where your data policy permits.
Performance
DOM parsing is generally linear in document size. Avoid repeatedly calling global selectors inside each item; build an ID map if processing large documents with many itemref links. Browser rendering costs substantially more than parsing static HTML, so classify pages first and render only when the initial response lacks expected scopes.
Cost
Direct HTTP fetching has infrastructure, bandwidth, and proxy costs. Browser pools add CPU and memory consumption. ScreenshotNeo charges only for clean shots; failed loads, bot checks, blank pages, timeouts, and cache hits are free, with billing and verdict reported in response headers. Choose caching TTLs and browser waits that match your freshness requirement.
Microdata, RDFa, or JSON-LD?
Schema.org supports Microdata, RDFa, and JSON-LD. Compare them against your constraints: whether markup must remain next to visible content, how easily your server can parse it, which syntax your consumer accepts, how nested entities are represented, and how your team validates changes. There is no universal winner in the official guidance. If a page publishes more than one syntax, deduplicate entities using stable itemid, canonical URLs, or a carefully defined identity key.
FAQ
Can an item have multiple types?
Yes. itemtype can contain multiple unique absolute URLs. Preserve all of them rather than selecting the first.
Should I parse hidden elements?
Microdata is markup in the document, so an extractor normally reads it regardless of visual visibility. Your application should decide whether hidden content is acceptable for its use case.
What happens when an item has no itemtype?
Return the item with a null or empty type and retain its properties. Validation or downstream classification can handle the missing vocabulary later.
How do I avoid duplicate items?
Emit only top-level scopes and include nested scopes inside their parent. If separate top-level items describe the same entity, deduplicate with itemid or canonical identifiers.
Does Microdata extraction prove search eligibility?
No. It proves that markup can be parsed. Search features have additional rules, required properties, content policies, and validation requirements that can change over time.
Production checklist
- Fetch the final rendered HTML when markup is dynamic.
- Collect top-level
itemscopeelements. - Preserve absolute type URLs and optional IDs.
- Apply element-specific value rules.
- Recursively parse nested scopes.
- Follow
itemrefsafely. - Keep repeated properties as arrays.
- Resolve relative URLs against the document base.
- Validate types and properties with Schema.org tools.
- Log failures, parser versions, and representative raw markup.


