How to Extract Data from Web Pages with Browser Automation
Use Playwright to wait for rendered content, extract text and links into structured data, and validate results with runnable examples.
To extract data from a JavaScript-heavy web page, load it in a real browser, wait for the specific content you need, select its elements with Playwright, and map their text or attributes into structured records. Then validate the records against the page. The examples below extract titles and links from a list, but the same approach works for prices, labels, dates, and other rendered fields.
Start by checking whether the site offers an API, export, or structured feed that fits your use. When browser automation is appropriate, use accessible locators or a deliberate test ID where possible. Keep selectors short, wait for meaningful page state, and treat missing or ambiguous matches as errors to investigate.
1. Set up a Playwright extraction
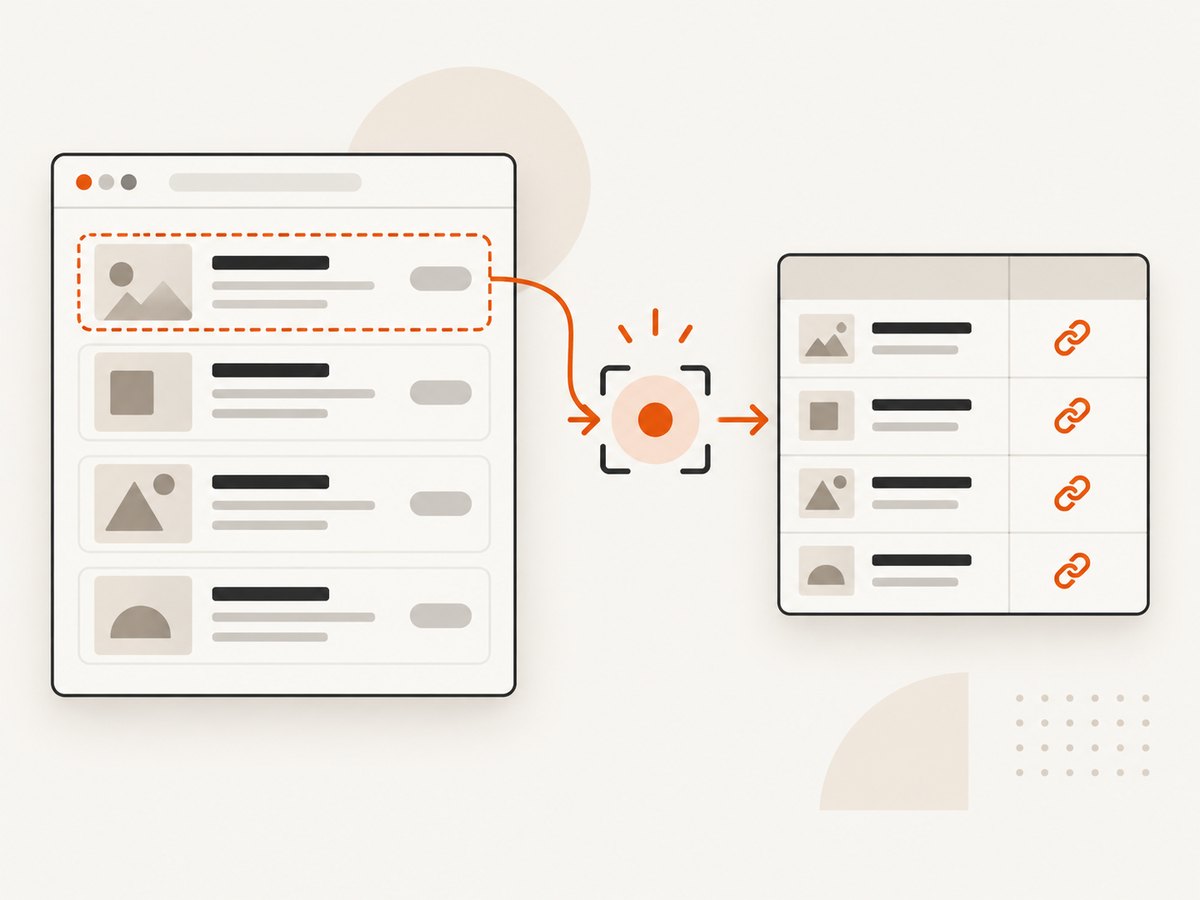
The following Node.js script opens a page, waits for article links, extracts their text and URLs, checks that results exist, and writes JSON. Replace the URL and selectors with ones you inspect on the target page.
import { chromium } from 'playwright';
import { writeFile } from 'node:fs/promises';

const url = 'https://example.com/articles';
const browser = await chromium.launch({ headless: true });

try {
  const page = await browser.newPage();
  const response = await page.goto(url, { waitUntil: 'domcontentloaded', timeout: 30_000 });

  if (!response || !response.ok()) {
    throw new Error(`Navigation failed: ${response?.status() ?? 'no response'}`);
  }

  // Wait for the content your extraction depends on, not an arbitrary delay.
  const articles = page.getByRole('article');
  await articles.first().waitFor({ state: 'visible', timeout: 15_000 });

  const rows = await articles.evaluateAll(nodes => nodes.map(article => {
    const link = article.querySelector('a[href]');
    return {
      title: link?.textContent?.trim() ?? '',
      href: link ? new URL(link.getAttribute('href'), document.baseURI).href : ''
    };
  }));

  if (rows.length === 0) throw new Error('No article records matched');
  if (rows.some(row => !row.title || !row.href)) {
    throw new Error('At least one record is missing a title or link');
  }

  await writeFile('results.json', JSON.stringify(rows, null, 2));
  console.log(`Saved ${rows.length} records to results.json`);
} finally {
  await browser.close();
}
Save it as extract.mjs, then install and run it:
npm install playwright
npx playwright install chromium
node extract.mjs
Use a representative page and record to inspect the structure before choosing the locator. If the page has no semantic article roles, replace getByRole('article') with a locator suited to the site, such as a short CSS selector: page.locator('.article-card'). The code intentionally checks navigation status, waits for a visible record, rejects empty output, and checks required fields. These checks make selector or rendering failures visible rather than producing a plausible empty file.
2. Choose selectors that survive page changes
Playwright describes locators as its central mechanism for auto-waiting and retryability. Prefer locators that express what a user or assistive technology can identify, when those names are clear. A selector can still become stale after a redesign, so check that it matches the intended records.
| Selection method | Use it when | Watch for |
|---|---|---|
| Role, label, or text | The target has a meaningful accessible role or name. | Names can change with content or redesign; verify uniqueness. |
| Test ID | The page deliberately exposes a stable automation contract. | Many public sites do not provide test IDs. |
| CSS selector | A concise structural selection or batch extraction is needed. | Selectors coupled to class names or nesting can break; invalid syntax throws. |
| XPath | A relationship is awkward to express another way. | Long paths tied to document structure are difficult to maintain. |
| Locator evaluation | You need to transform several matched DOM nodes into records. | Keep the function focused and return serializable values. |
For example, a page with named links can use a user-facing locator:
const link = page.getByRole('link', { name: 'Release notes', exact: true });
await link.waitFor({ state: 'visible' });
const href = await link.getAttribute('href');
For a repeated card list, scope a link locator inside each card instead of relying on a page-wide selector that may also match navigation. Locators are strict for single-target operations: if an action finds multiple matches, Playwright can raise an error. Resolve ambiguity by narrowing the region or improving the accessible name. Using first() or nth() just to suppress ambiguity can silently pick the wrong item.
3. Wait for the right content
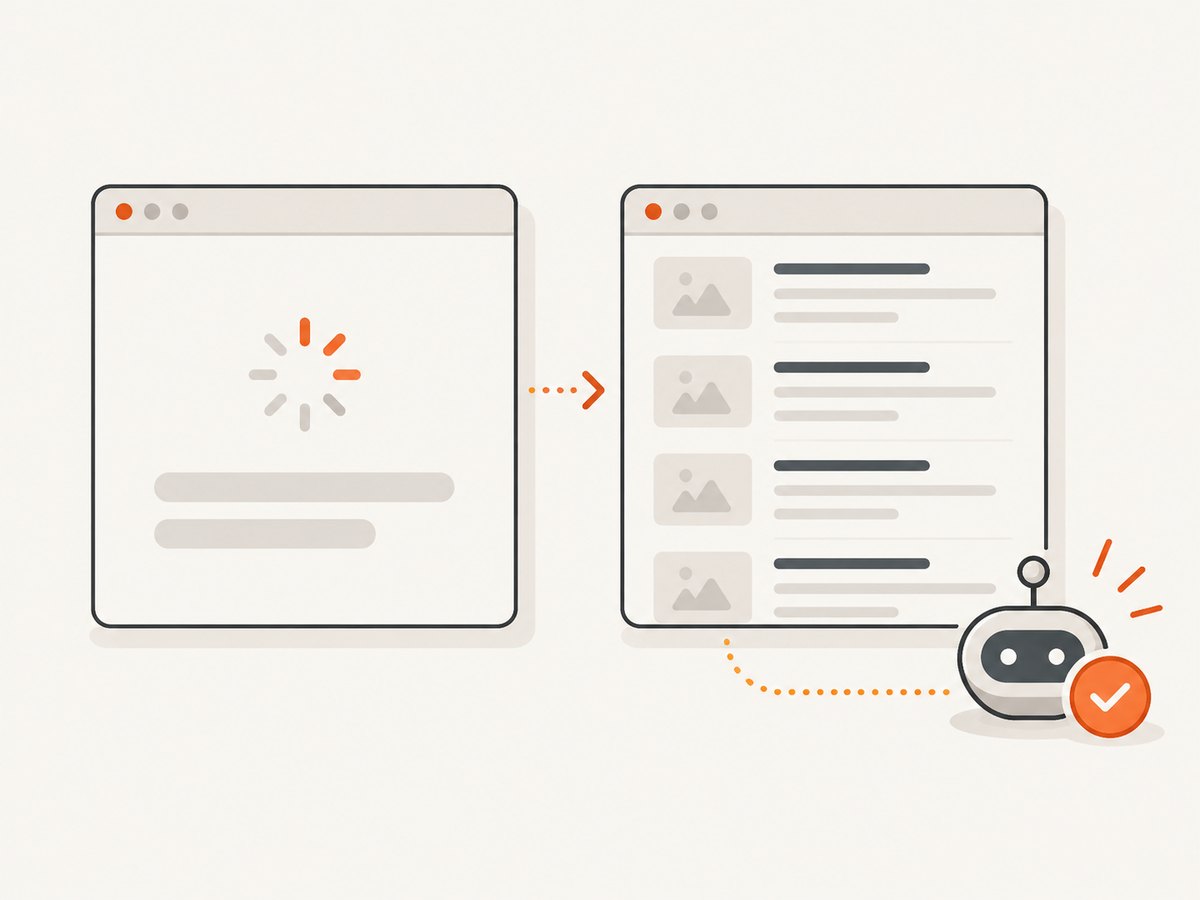
A navigation event does not necessarily mean a client-rendered list has appeared. Wait for the record, heading, or state that the extraction requires. In the example, waitFor({ state: 'visible' }) waits for a first record before collecting the list. For a page that shows a loading indicator, you can instead wait for the indicator to disappear and the list to appear:
await page.locator('[data-loading="true"]').waitFor({ state: 'hidden' });
await page.locator('[data-testid="results-list"]').waitFor({ state: 'visible' });
Use selectors that actually match the page; these attributes are examples, not assumptions about a particular site. A fixed delay can help when a site has a known delayed behavior, but it is usually less reliable than waiting for a meaningful element. A multiple-element query such as locator.all() does not itself wait for a dynamically loaded list to finish. Wait for a list marker or expected record first, then collect.
Pagination and lazy loading need page-specific handling. If the target exposes a “Next” control, extract the current page, advance deliberately, wait for the next page’s records, and stop when the control is disabled or absent. For infinite scrolling, scroll in bounded increments and detect whether the record count changes; include a maximum page or item limit so a run cannot continue indefinitely.
4. Extract text, links, and attributes
When you need a single field, locator methods are direct. When you need a record per repeated element, evaluate the matched nodes in the page context:
const cards = page.locator('.product-card');
await cards.first().waitFor({ state: 'visible' });
const products = await cards.evaluateAll(nodes => nodes.map(card => ({
  name: card.querySelector('.product-name')?.textContent?.trim() ?? '',
  priceText: card.querySelector('.price')?.textContent?.trim() ?? '',
  href: card.querySelector('a[href]')?.getAttribute('href') ?? ''
})));
Normalize relative URLs against the document base if you need absolute links, as the first example does with new URL(..., document.baseURI). Decide explicitly how to handle missing fields: reject the record, keep a null value, or record a validation issue. Avoid silently converting missing values into strings that look valid.
DOM querySelectorAll() returns a static NodeList in document order. It will not update if the page changes after the query, so run the selection again after pagination, filtering, or another interaction. An empty NodeList means no elements matched; it can indicate a wrong selector, content not yet rendered, or a page state that requires interaction.
5. Extract with Python or cURL when appropriate
Playwright has official clients for multiple languages. For rendered pages, Python can use the same browser workflow. Install the package and browser first with pip install playwright and playwright install chromium:
import asyncio
import json
from playwright.async_api import async_playwright

async def main():
    async with async_playwright() as p:
        browser = await p.chromium.launch(headless=True)
        try:
            page = await browser.new_page()
            response = await page.goto(
                "https://example.com/articles",
                wait_until="domcontentloaded",
                timeout=30_000,
            )
            if response is None or not response.ok:
                status = response.status if response else "no response"
                raise RuntimeError(f"Navigation failed: {status}")

            articles = page.get_by_role("article")
            await articles.first.wait_for(state="visible", timeout=15_000)
            rows = await articles.evaluate_all("""nodes => nodes.map(article => {
              const link = article.querySelector('a[href]');
              return {
                title: link?.textContent?.trim() ?? '',
                href: link ? new URL(link.getAttribute('href'), document.baseURI).href : ''
              };
            })""")
            if not rows or any(not row["title"] or not row["href"] for row in rows):
                raise RuntimeError("No records or required fields are missing")
            with open("results.json", "w", encoding="utf-8") as output:
                json.dump(rows, output, ensure_ascii=False, indent=2)
        finally:
            await browser.close()

asyncio.run(main())
cURL alone retrieves an HTTP response; it does not run page JavaScript. It is suitable if the desired data is already present in server-returned HTML or an accessible data endpoint. For example, save the HTML for inspection:
curl --fail --location --max-time 30 \
  --output page.html \
  'https://example.com/articles'
If the resulting HTML lacks the records because JavaScript adds them later, use browser automation rather than treating missing markup as an extraction success. Check whether an official API or feed is available before automating a visible browser.
6. Validate the result before using it
Extraction code can run without producing useful data. Validate each run before storing or acting on its output:
- Check the record count against what the page visibly shows or what the expected page state implies.
- Check required fields for empty or malformed values.
- Look for duplicate URLs or records when duplicates are not expected.
- Inspect representative values and URL normalization.
- Record the page URL and run time alongside output when traceability matters.
- Re-query after an interaction that changes the page; prior DOM collections may be stale.
For recurring jobs, log the selector used, record count, and a concise failure reason. Keep a small set of known pages for manual review after the target site changes. A zero-match result should raise a visible error or alert rather than being accepted as a successful empty dataset.
7. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Timeout waiting for a locator | The selector is wrong, the content is delayed, or the target is not visible in the current state. | Inspect the rendered page, wait for the actual content marker, and verify the page or interaction state. |
| Navigation response is missing or not successful | Network failure, redirect behavior, or an unsuccessful HTTP response. | Log the final URL and status; retry only transient failures with a bounded policy and inspect the destination. |
| Strict mode violation or multiple matches | A single-target locator matches several elements. | Scope it to the intended section and add a meaningful role, label, or text condition. |
| Zero records | Wrong selector, list not rendered, pagination, lazy loading, or a required interaction. | Wait for a real list marker, inspect a sample record, and handle the page’s loading or pagination behavior. |
| Partial or stale results | Collection happened before the list settled, or an earlier static DOM query was reused after page changes. | Wait for the updated state and collect again after each interaction. |
| CSS selector syntax error | The selector is invalid or contains special characters that need escaping. | Validate the selector in the page context and escape unusual IDs or class values. |
| Empty fields in otherwise valid rows | The markup differs across records or the selected child is not the value-bearing element. | Inspect variants, define required fields, and report missing values explicitly. |
8. Performance, reliability, and responsible operation
Browser automation uses more resources than a direct request because it runs a browser and page scripts. Keep the browser open across a batch of pages when appropriate, close each page when finished, and avoid launching a new browser for every record. Extract only required fields and avoid waiting for unrelated resources when a meaningful content marker is enough. Do not increase concurrency without considering the target’s capacity and your own memory and CPU limits.
Reliability comes from bounded timeouts, explicit checks, clear logs, and selective retries. A retry can help with a transient network error; it cannot repair a broken selector, changed page structure, or a blocked flow. Set limits on pagination, scrolling, and total records. If a site changes often, expect to review selectors and validation rules.
Keep request volume proportionate and check the site’s terms and applicable rules for your specific use. Robots directives have a limited crawler scope: robots.txt concerns crawling, while robots meta directives guide indexing behavior for cooperative crawlers. Neither alone settles broader permission or legal questions.
9. Or skip the browser setup
If your goal is a screenshot rather than extracting structured fields, ScreenshotNeo can return a capture with one GET request. Its website screenshot API also has an MCP server for AI agents. It accepts cookie and consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each cleanup step can be turned off. Bot checks and CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers report the page verdict and billing status. This is a screenshot workflow, not a replacement for DOM extraction when you need structured records.
See the ScreenshotNeo API documentation for request options.
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
import requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
await Bun.write('shot.webp', res);ScreenshotNeo offers 1,000 screenshots per month free with no card; paid plans start at $5 for 3,000. Every feature is on every plan. Learn more at ScreenshotNeo, then sign up free for 1,000 screenshots a month, with no card.
10. FAQ
Can browser automation extract data that is not visible on screen?
It can read DOM content in the loaded page, including content that may not be visually prominent. Whether the page loads that data at all depends on the site and its state. Inspect the rendered DOM and validate the fields you need.
Should I use CSS selectors or accessible locators?
Prefer roles, labels, and meaningful text when they identify the target clearly. Use concise CSS for structural batch selection when necessary, and keep it easy to review after page changes.
Can I use cURL for a JavaScript-rendered page?
cURL does not execute browser JavaScript. Use it when the response already contains the data or when an appropriate endpoint is available; otherwise use browser automation.
What should happen when a selector matches nothing?
Fail visibly, inspect the page state and selector, and correct the cause. An empty result should not be treated as a successful extraction unless an empty list is expected.


