How to Extract Web Data Using Natural Language
Extract webpage data with plain-language instructions, then make results dependable with schemas, validation, and provenance. Includes runnable code and workflow guidance.
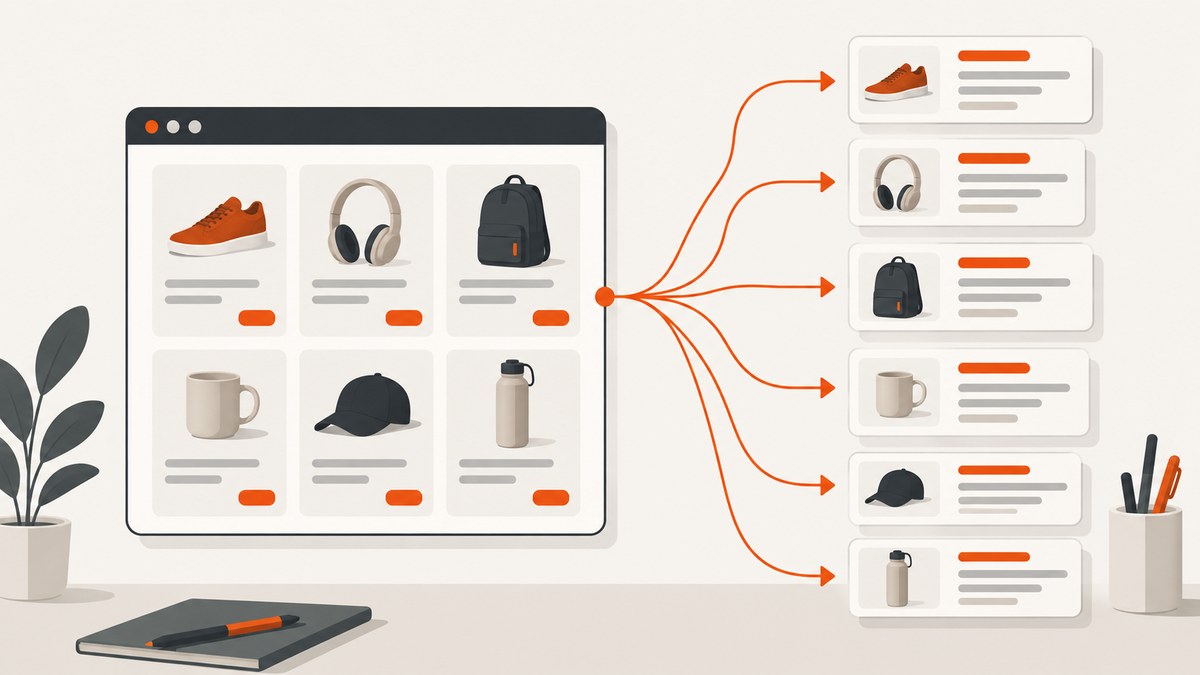
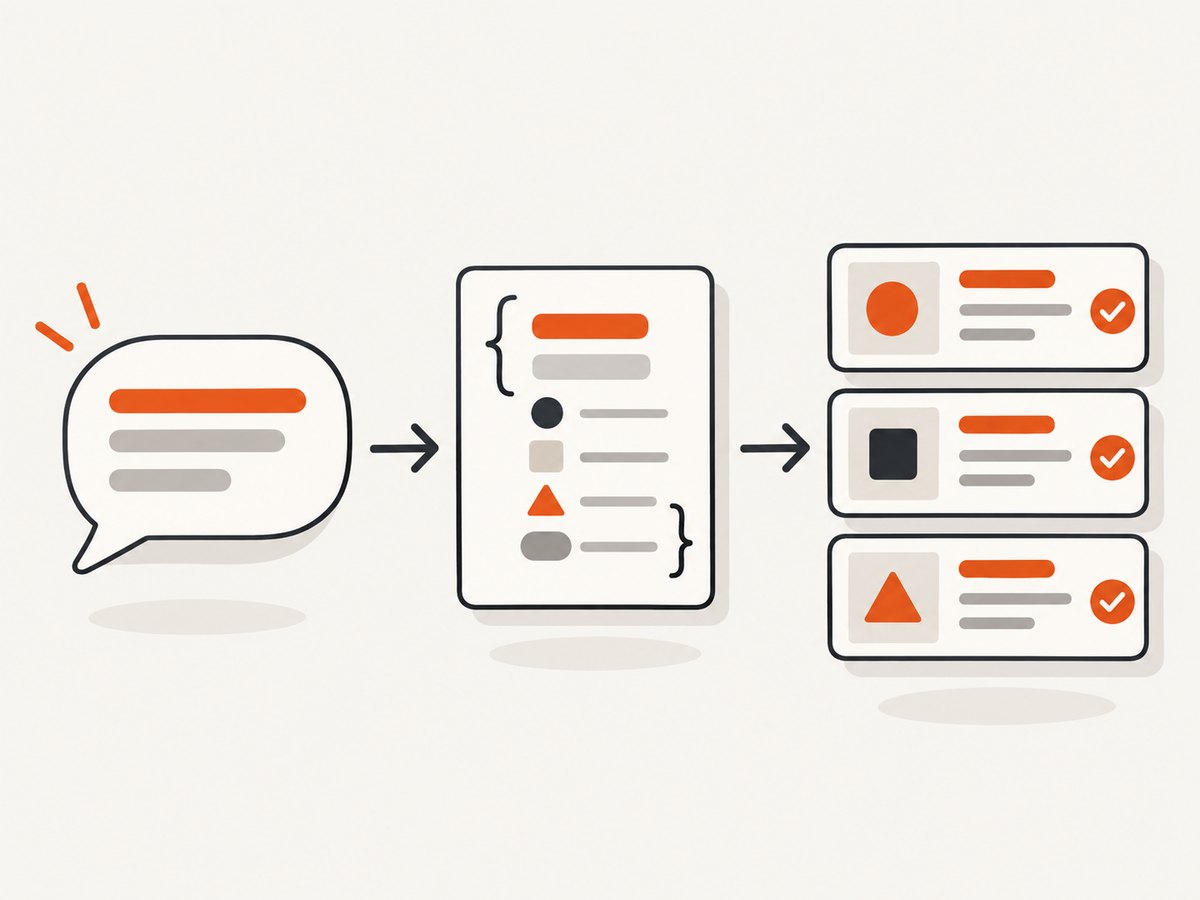
To extract web data using natural language, describe the records and fields you want, then constrain the result with a JSON Schema. Use a browser-capable extractor when content appears only after JavaScript runs or requires interaction. Validate the returned records and save the source URL and extraction time with them.
Natural language communicates intent; it does not guarantee complete or correctly typed data. Treat extracted values as candidates to check, especially before loading them into a database or using them to make decisions.
1. Define exactly what counts as a record
Start by choosing the unit you want returned: one record per product, job, article, property listing, or another repeated item. Then name each field and define its meaning. “Price” might mean the current displayed price, excluding a crossed-out list price. “Rating” might be a number from zero to five, while “review count” is an integer.
Be explicit about edge cases before you write the prompt. Decide whether absent fields should be null, whether prices should preserve the displayed currency, whether sponsored results count, and whether the target is the first page or every page. Tell the extractor to report only what is visible rather than infer missing facts.
| Decision | Example rule |
|---|---|
| Record boundary | One record for each product card in the results list. |
| Missing value | Use null; do not guess. |
| Currency and units | Preserve the page’s currency and measurement units. |
| Included items | Include visible organic listings; ignore sponsored blocks. |
| Pagination | Continue until the next-page control is absent or disabled. |
A narrowly defined task is easier to validate than “get all useful information from this site.” If a field has multiple plausible interpretations, explain which one you need.
2. Load the page the way a visitor sees it
For a static page with content in the initial HTML, a prompt-and-schema extraction endpoint may be enough. For a client-rendered page, a page with lazy-loaded cards, or a flow that needs a click or navigation, choose a browser-capable extractor that reads the rendered page. Cloudflare documents its /json endpoint for structured extraction using a prompt or JSON Schema. Browser-agent approaches can combine natural-language instructions with a typed schema. [Cloudflare Browser Run documentation; Magnitude BrowserAgent documentation]
There are four common approaches:
| Approach | Use it when | Trade-off |
|---|---|---|
| Prompt plus JSON Schema API | You need structured fields from one or a few pages quickly. | Provider access and downstream validation are still required. |
| Browser agent plus schema | The page needs interaction, navigation, or JavaScript rendering. | More runtime steps can mean more complexity and cost. |
| Deterministic selectors | The layout is stable and you know the row and field selectors. | Markup changes can break selectors; monitoring is important. |
| Multi-page crawler | You need a catalog, directory, or paginated result set. | You must define crawl boundaries, deduplicate, and respect rate limits. |
Some tools also support selector-based extraction. It can be more predictable for a stable repeated layout, and a selector path may avoid model inference when the selectors are already known. For example, Twin Browser documents extraction using field lists, maps, or JSON Schema against a rendered page. [Twin Browser documentation]
Check that you are permitted to access and process the target content. Authentication, access controls, robots guidance, and provider terms can affect what a workflow may retrieve. Do not treat a successful browser load as permission to collect or republish data.
3. Write a prompt that removes ambiguity
Use the prompt to describe the record boundary, fields, inclusion rules, and what to do when the page does not supply a value. Avoid asking the model to research or fill in facts from elsewhere unless that is explicitly part of the task.
Open the supplied page and extract one record for each product card.
Fields:
- name: string
- brand: string or null
- price: number or null; use the currently displayed price
- currency: string or null; preserve the page's currency
- availability: string or null; use the displayed wording
- rating: number or null
- review_count: integer or null
- product_url: absolute URL or null
Rules:
- Include only items visibly listed on the page.
- Ignore sponsored blocks.
- Use null when a field is absent; do not infer it.
- Return the source URL for each record.
- Return an array matching the supplied JSON Schema.
For interactive pages, include navigation and a stopping rule. For example: “Dismiss the consent dialog if shown, open the results page, select Next until the control is absent or disabled, and stop after 10 pages.” A page limit protects against loops and unexpectedly large jobs. If a dialog cannot be dismissed, make the extractor report that obstacle instead of silently returning an empty list.
4. Constrain the response with JSON Schema
When the output will feed code, a spreadsheet, or a database, provide a schema. Specify the top-level array, object properties, types, required fields, and whether extra keys are permitted. Chrome Developers guidance recommends using JSON Schema for predictable results and cautions against relying on natural-language instructions like “output only JSON” by themselves. [Chrome Developers: Built-in AI APIs guidance]
{
  "type": "array",
  "items": {
    "type": "object",
    "additionalProperties": false,
    "properties": {
      "name": { "type": "string" },
      "brand": { "type": ["string", "null"] },
      "price": { "type": ["number", "null"] },
      "currency": { "type": ["string", "null"] },
      "availability": { "type": ["string", "null"] },
      "rating": { "type": ["number", "null"], "minimum": 0, "maximum": 5 },
      "review_count": { "type": ["integer", "null"], "minimum": 0 },
      "product_url": { "type": ["string", "null"] },
      "source_url": { "type": "string" }
    },
    "required": ["name", "brand", "price", "currency", "availability", "rating", "review_count", "product_url", "source_url"]
  }
}
A schema validates shape, not truth. A response can have the right keys and still omit a card, misread a price, or attach a value to the wrong item. Use null in the type when missing values are legitimate. Keep fields required when every object must contain the key, even if its value can be null.
5. Validate before storing or scaling
Run structural validation first, then checks that reflect the page and your data rules. At minimum, check required keys and types, numeric ranges, URL shape, duplicates, and whether the number of records is plausible for the visible list. Keep a small sample for human review before expanding to many URLs.
- Coverage: compare returned records with the visible cards and confirm pagination reached its stopping condition.
- Association: verify each price, rating, and URL belongs to the same item as the name.
- Normalization: parse numbers consistently, while preserving the displayed currency or units separately.
- Duplicates: choose a stable key such as a canonical product URL or source-specific identifier.
- Provenance: store source URL, retrieval timestamp, schema version, and prompt with each batch.
Do not silently coerce malformed output into valid-looking records. Keep invalid rows in a review queue or retry them with a narrower instruction. If a value is missing on the page, preserve that fact as null; a guess may look tidy but makes the data less trustworthy.
6. Build a repeatable extraction pipeline
- Run one representative page and inspect the raw result.
- Validate the JSON against the schema and your business rules.
- Review a sample manually and refine ambiguous field definitions.
- Add pagination, bounded retries, rate limits, and duplicate detection.
- Record prompt and schema versions alongside each output batch.
- Monitor empty results, unexpected record counts, and validation failures.
For a multi-page job, set a maximum page count and a maximum runtime. Retry transient network errors with a small number of attempts and backoff; do not retry a deterministic schema failure unchanged. Store partial progress so a failed later page does not force a full restart. If the provider offers JSONL or another streaming format, it may be useful for large result sets, but still validate each record.
7. Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| Empty array | The page has not rendered, a consent dialog blocks it, or the prompt describes the wrong record boundary. | Use a browser-capable extractor, wait for a visible selector, handle the dialog, and confirm the page URL and content. |
| Some cards are missing | Lazy loading, pagination, infinite scroll, or a page limit stopped collection early. | Scroll or navigate explicitly, set a stopping condition, and compare results with the displayed count. |
| Fields have the wrong type | The instruction is vague or schema constraints are missing. | Define types and null behavior in the schema; validate and reject malformed records. |
| Prices or ratings belong to the wrong item | Repeated layout made the association ambiguous or the model grouped nearby text incorrectly. | Ask for one record per card, include the card’s product URL, and inspect a sample. Use stable selectors if available. |
| JSON parse or schema error | Provider returned an error envelope, partial output, or a result that does not match the schema. | Check HTTP status and provider error fields before parsing; capture the raw response for diagnosis. |
| Repeated rows | Pagination overlaps, retries reprocessed a page, or canonical URLs vary by tracking parameters. | Deduplicate by a stable identifier and normalize URLs before comparison. |
| Intermittent timeout or access denial | Slow page resources, provider limits, network issues, or target access controls. | Use bounded retries for transient failures, reduce concurrency, and investigate the access response rather than retrying indefinitely. |
8. Performance, reliability, and cost
Rendered browsing and interaction add time compared with reading static HTML. Keep prompts and schemas focused, avoid loading pages or fields you do not need, and begin with a small sample. For larger jobs, limit concurrent requests to a level allowed by the provider and the target site; record latency and failure rates so you can spot changes after a page redesign.
No universal accuracy percentage or success rate applies across sites. Outcomes depend on rendering, layout consistency, prompt specificity, schema design, access restrictions, and validation. Treat model output as data to check, not evidence that every record was captured correctly.
Estimate cost using the provider’s current pricing and the shape of the workflow: number of pages, browser runtime, retries, and any model or crawling charges. A multi-step browser agent may cost more to run than a single-page extraction. Track cost per valid record, not only cost per request, because retries and rejected output affect the useful result.
9. Or skip the browser setup
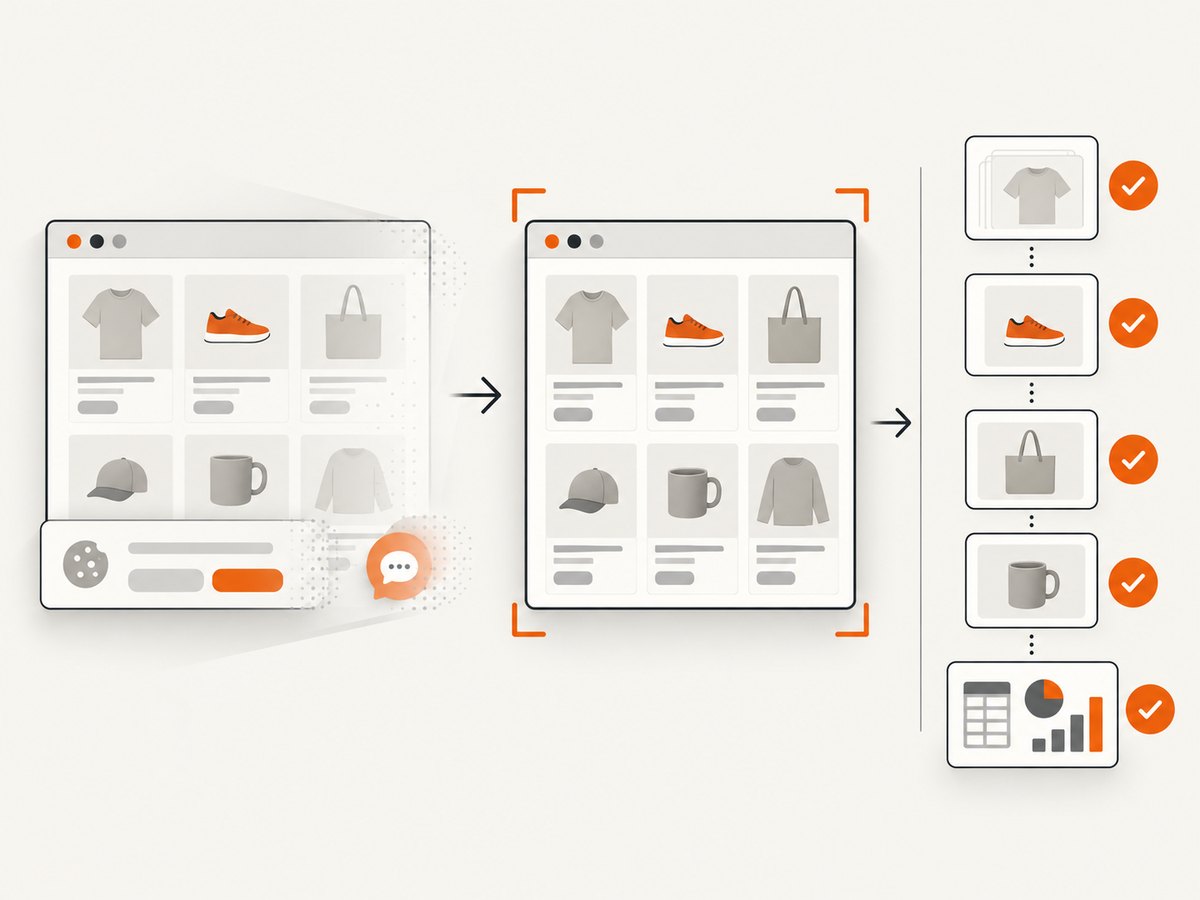
If you need screenshots as part of an extraction workflow, ScreenshotNeo is a website screenshot API and MCP server. Its screenshot can provide a visual artifact for review or an input to a separate extraction step; a screenshot by itself is not structured web data and does not replace schema validation. See the ScreenshotNeo API documentation for request options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
const fs = await import('node:fs/promises');
await fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer()));Replace the example URL with the page you need. ScreenshotNeo accepts cookie or consent banners like a visitor and removes 60+ known consent platforms, newsletter popups, and chat widgets before capture; each step can be turned off. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers report the page verdict and billing status. Its MCP server offers take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. The free plan includes 1,000 shots per month with no card; paid plans start at $5 for 3,000 shots. The same features are available on every plan. For a screenshot and browser workflow, sign up for 1,000 free screenshots a month, no card required.
10. Frequently asked questions
Can natural language extract data without selectors?
Yes, when the extraction tool can access the page and interpret the request. For stable layouts and known fields, selectors can make extraction more deterministic; choose based on how often the page changes and how much control you need.
Should I ask for JSON in the prompt?
You can describe the desired output, but use a JSON Schema when your downstream workflow depends on exact fields and types. Validate the result either way.
Can I extract data from every page on a site?
A single-page extraction tool does not automatically define a safe or complete crawl. Specify allowed starting pages, pagination rules, a stopping condition, deduplication, and request limits.
How do I know whether the data is accurate?
Compare records with a human-reviewed sample of the rendered page and validate coverage, field associations, and types. There is no universal accuracy figure that applies to all sites and prompts.
What should I keep so the result can be audited later?
At least the source URL, retrieval time, prompt, schema version, and validation outcome. Keep the raw response when your retention rules allow it.


