How to Extract Metadata from a Website
Learn to extract title, canonical, robots, Open Graph, Twitter Card, and JSON-LD metadata from raw or JavaScript-rendered pages.
How do you extract metadata from a website? Fetch the page, preserve the response, parse the valid <head>, and handle each metadata layer separately. Read the title and standard meta tags, canonical and alternate links, robots directives, Open Graph and Twitter Card properties, and JSON-LD scripts. If the values appear only after JavaScript runs, compare the raw response with a rendered DOM.
This guide shows a repeatable workflow, complete Python, cURL, and Node.js examples, validation rules, rendering options, bulk-processing considerations, and fixes for common failures.
1. Understand the metadata layers
Metadata is not one field. Different consumers read different parts of a page:
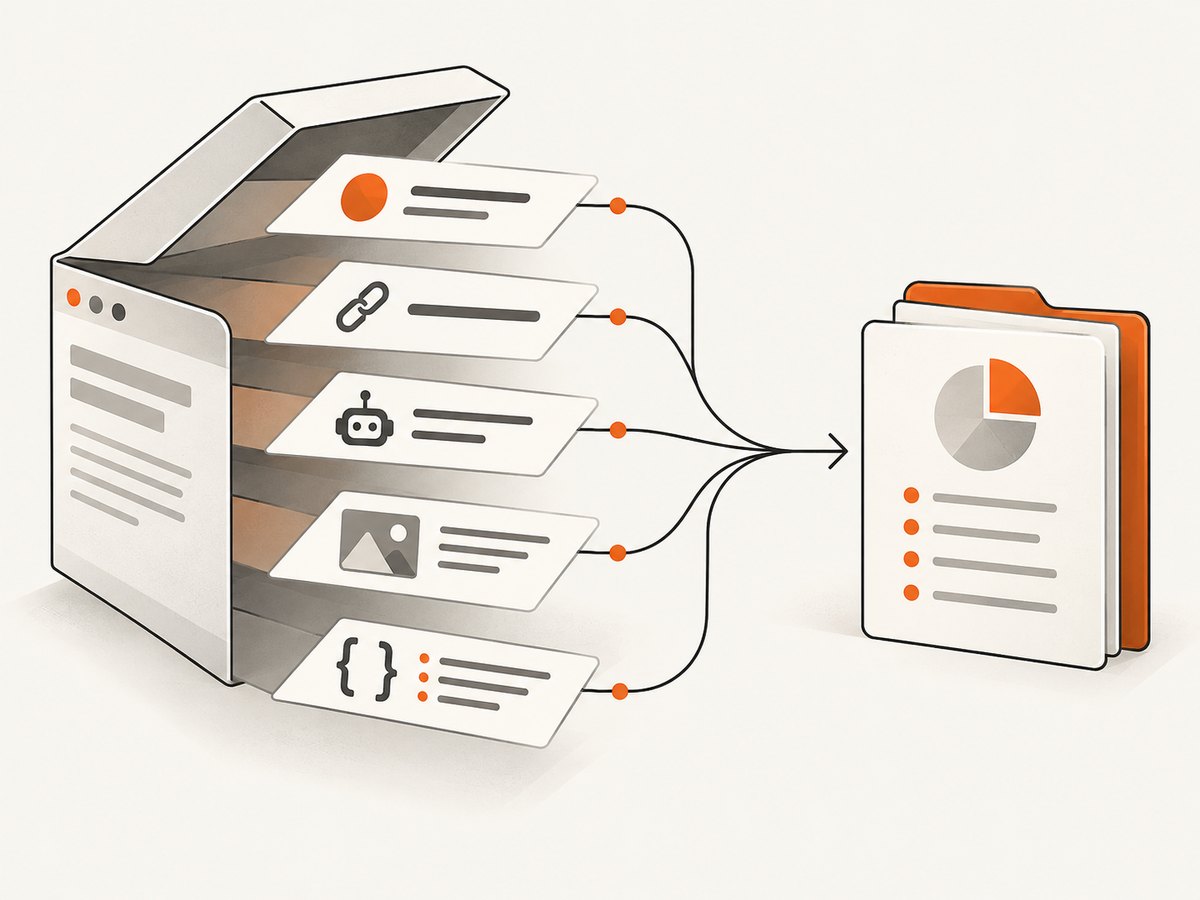
| Layer | Typical elements | Primary consumers |
|---|---|---|
| Document identity | <title>, description, language, charset, viewport |
Browsers, search engines, accessibility tools |
| Discovery and indexing | rel="canonical", rel="alternate", meta name="robots" |
Crawlers and search systems |
| Social previews | og:title, og:image, Twitter Card tags |
Social networks and link unfurlers |
| Structured data | script type="application/ld+json" |
Search features and data consumers |
| HTTP metadata | Status, redirects, content type, X-Robots-Tag |
Clients and crawlers before HTML parsing |
Extracting one layer does not prove that the others exist. Robots directives are controls for crawling, indexing, or presentation; they are not a replacement for descriptive JSON-LD or social tags.
2. Preserve the HTTP response before parsing
Start with evidence that can be audited. Record the requested URL, final URL after redirects, status code, content type, retrieval time, and raw HTML. A raw response is sufficient for server-rendered pages and is faster and cheaper than launching a browser.
curl -L --compressed -D response-headers.txt \
  -o page.html \
  "https://example.com/article"
Inspect response-headers.txt for redirect locations, a non-HTML content type, authentication challenges, or an X-Robots-Tag header. Do not assume a successful TCP request means you received the target page: bot checks and error templates often return status 200.
3. Parse core tags, links, and robots directives in Python
The following script fetches one URL and emits a JSON document. It keeps duplicate values, resolves relative URLs against the final response URL, and separates HTTP robots headers from HTML directives.
import json
import sys
from datetime import datetime, timezone
from urllib.parse import urljoin

import requests
from bs4 import BeautifulSoup

url = sys.argv[1]
r = requests.get(
    url,
    headers={"User-Agent": "metadata-audit/1.0"},
    timeout=30,
    allow_redirects=True,
)
r.raise_for_status()
retrieved_at = datetime.now(timezone.utc).isoformat()
soup = BeautifulSoup(r.text, "html.parser")


def content_values(selector, attr="content"):
    values = []
    for tag in soup.select(selector):
        value = tag.get(attr)
        if value is not None:
            values.append(value.strip())
    return values


def absolute_links(rel):
    return [urljoin(r.url, tag.get("href")) for tag in soup.find_all("link", rel=lambda x: x and rel in x)]

json_ld = []
for script in soup.select('script[type="application/ld+json"]'):
    raw = script.string or script.get_text()
    try:
        json_ld.append(json.loads(raw))
    except json.JSONDecodeError as exc:
        json_ld.append({"_parse_error": str(exc), "_raw": raw})

result = {
    "requested_url": url,
    "final_url": r.url,
    "status": r.status_code,
    "content_type": r.headers.get("content-type"),
    "retrieved_at": retrieved_at,
    "title": soup.title.get_text(" ", strip=True) if soup.title else None,
    "description": content_values('meta[name="description"]'),
    "language": soup.html.get("lang") if soup.html else None,
    "canonical": [urljoin(r.url, t.get("href")) for t in soup.select('link[rel~="canonical"]') if t.get("href")],
    "alternates": [{"hreflang": t.get("hreflang"), "href": urljoin(r.url, t.get("href"))} for t in soup.select('link[rel~="alternate"][href]')],
    "robots_meta": content_values('meta[name="robots"], meta[name="googlebot"]'),
    "x_robots_tag": r.headers.get("x-robots-tag"),
    "open_graph": {t.get("property"): t.get("content") for t in soup.select('meta[property^="og:"][content]")},
    "twitter": {t.get("name"): t.get("content") for t in soup.select('meta[name^="twitter:"][content]")},
    "json_ld": json_ld,
}
print(json.dumps(result, indent=2, ensure_ascii=False))
Install dependencies with pip install requests beautifulsoup4, then run python extract.py https://example.com/article. For production, retain arrays for fields such as descriptions and Open Graph tags because duplicate tags can signal a template defect.
4. The same extraction with Node.js
Node 18 or later includes fetch. This example uses Cheerio for CSS selectors and follows redirects through the fetch implementation.
import * as cheerio from 'cheerio';

const target = process.argv[2];
const response = await fetch(target, {
  headers: { 'user-agent': 'metadata-audit/1.0' },
  redirect: 'follow'
});
const html = await response.text();
const $ = cheerio.load(html);
const absolute = (value) => new URL(value, response.url).href;
const values = (selector, attr = 'content') => $(selector).map((_, el) => $(el).attr(attr)?.trim()).get().filter(Boolean);
const jsonLd = $('script[type="application/ld+json"]').map((_, el) => {
  const raw = $(el).text();
  try { return JSON.parse(raw); } catch (error) { return { _parse_error: error.message, _raw: raw }; }
}).get();
const pairs = (selector, key) => Object.fromEntries($(selector).map((_, el) => [$(el).attr(key), $(el).attr('content')]).get());

console.log(JSON.stringify({
  requested_url: target,
  final_url: response.url,
  status: response.status,
  content_type: response.headers.get('content-type'),
  title: $('title').first().text().trim() || null,
  description: values('meta[name="description"]'),
  canonical: $('link[rel~="canonical"]').map((_, el) => absolute($(el).attr('href'))).get(),
  robots_meta: values('meta[name="robots"], meta[name="googlebot"]'),
  x_robots_tag: response.headers.get('x-robots-tag'),
  open_graph: pairs('meta[property^="og:"]', 'property'),
  twitter: pairs('meta[name^="twitter:"]', 'name'),
  json_ld: jsonLd
}, null, 2));
Install Cheerio with npm install cheerio. Guard against malformed JSON-LD and missing attributes; real pages frequently contain both.
5. Extract Open Graph and Twitter Card fields
At minimum, collect og:title, og:description, og:type, og:url, and og:image. For Twitter Cards, collect twitter:card, twitter:title, twitter:description, twitter:image, and any creator or site fields. Resolve image and URL values to absolute URLs and preserve duplicates because galleries may use repeated image tags.
OpenGraph.io documents an endpoint that returns Open Graph, Twitter Card, and HTML metadata, with rendering and proxy options for pages that require JavaScript. A hosted metadata API is useful when you process URL inventories or cannot operate browsers yourself.
6. Parse and validate JSON-LD structured data
JSON-LD can be one object, an array, or a graph containing nested entities. Keep @context, @type, @id, URLs, and nested properties instead of flattening everything into strings. Parsing JSON proves syntax only. Validate that types and properties match Schema.org definitions and that claims correspond to visible page content. Schema.org publishes the vocabulary and machine-readable JSON-LD context.
for (const block of jsonLd) {
  const nodes = Array.isArray(block) ? block : (block['@graph'] || [block]);
  for (const node of nodes) {
    console.log(node['@type'], node['@id'] || '(no id)');
  }
}
7. Raw HTML versus a rendered DOM
Single-page applications may inject title, descriptions, canonical links, or JSON-LD after load. Compare the raw response with a browser DOM before concluding that metadata is missing. A rendered extraction should wait for a meaningful condition, such as a selector, network idle, or a short delay, and should record the final URL after client-side navigation.
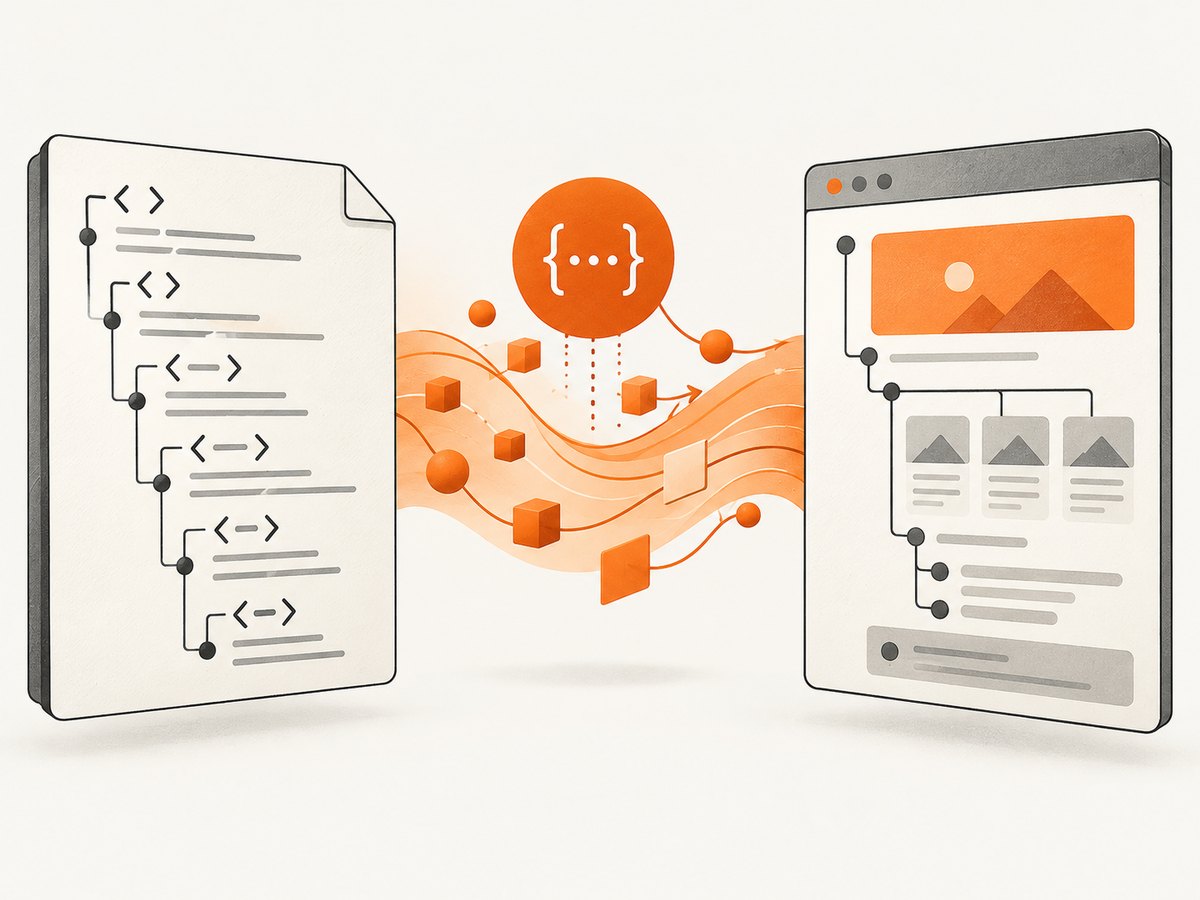
Rendering introduces edge cases: consent banners can obscure content, lazy images may not load until scrolled, scripts can hang, and bot protection may return a challenge. Use a bounded timeout, capture console and network errors, and retry only transient failures. Never treat a challenge page as the site’s metadata.
8. Or skip the browser setup
ScreenshotNeo can render a page before you inspect its screenshot or use its page-capture workflow. It accepts a URL with one GET request and supports PNG, JPEG, WebP, and PDF output. Cookie and consent banners, newsletter popups, and chat widgets are removed before the shot; bot checks, blank pages, timeouts, failed loads, and cache hits are not billed. Responses identify the page verdict and billing state with X-Page-Verdict and X-Billed headers. Its MCP server gives Claude, Cursor, and other MCP clients take_screenshot, get_page_info, and capture_pdf tools.
See the ScreenshotNeo API documentation for all options. The basic request is:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);For capture pipelines, options include full-page shots with lazy images loaded, CSS selector element capture, dark mode, device presets or custom viewports, retina scale, custom CSS and JavaScript, clicks, selector waits, delays, network idle, request and resource blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, configurable TTL caching, signed links, asynchronous jobs with signed webhooks, bulk capture of 100 URLs per call, and a usage API. Every feature is available on every plan. The free plan includes 1,000 shots each month without a card; paid plans start at $5 for 3,000.
Create a free ScreenshotNeo account and use the included 1,000 monthly screenshots to add rendered evidence to your metadata audits.
9. Validation checklist
- Confirm the final URL, status, content type, and retrieval time.
- Check that
<head>contains permitted metadata elements. Google liststitle,meta,link,script,style,base,noscript, andtemplateas valid head elements. Invalid markup can cause later metadata to be ignored. - Resolve relative canonical, alternate, image, and JSON-LD URLs.
- Flag duplicate or conflicting titles, canonicals, descriptions, and social values.
- Compare
og:urlwith the canonical and final URL, allowing for intentional differences. - Check that JSON-LD syntax parses, types and properties are valid, and claims match visible content.
- Read both HTML robots tags and the HTTP
X-Robots-Tag. - Run a rendered pass when raw HTML lacks values visible in the browser.
10. Bulk extraction, performance, and reliability
For URL inventories, use a queue with bounded concurrency, connection reuse, and per-request timeouts. Cache responses using a hash of the URL plus relevant request headers; retain the raw HTML and parser version so results can be reproduced. Separate permanent failures such as 404 and unsupported content from transient timeouts and retry the latter with exponential backoff.
Raw HTTP parsing is usually the fastest path and consumes fewer resources. Browser rendering is slower and more failure-prone, so reserve it for pages whose metadata is injected or altered by JavaScript. At scale, a hosted API can reduce browser maintenance, but account for request pricing, rate limits, privacy requirements, and storage of returned HTML. ScreenshotNeo’s cache TTL is configurable, and its bulk endpoint accepts up to 100 URLs per call; inspect usage through its usage API.
11. Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| Empty title or description | JavaScript injects it, or the response is a challenge page | Inspect status and body, then run a bounded rendered pass. |
| JSON decode error | Trailing commas, HTML comments, or multiple scripts | Parse each script independently, preserve the raw value, and flag it for review. |
| Wrong canonical URL | Relative URL or duplicate template tags | Resolve against the final URL and report every canonical. |
| Robots rule appears inconsistent | HTML and HTTP directives differ | Store both; do not overwrite one with the other. |
| Missing social image | Image is lazy-loaded or blocked by a proxy | Use the absolute declared URL, then verify it with an image request or rendered capture. |
| Timeouts in browser mode | Long scripts, third-party resources, or bot protection | Block unnecessary resources, wait for a selector, set a hard timeout, and retry transient errors only. |
| Non-HTML response | PDF, image, redirect target, or access denial | Branch on content type and retain the response metadata instead of parsing it as HTML. |
12. FAQ
Is metadata extraction the same as scraping a page?
No. Metadata extraction targets declared document fields, while scraping may collect body content. Keep the scope narrow and respect access controls.
Should I trust the meta description for search snippets?
Treat it as a supplied hint. Search systems can choose another snippet, so report the value without claiming it will always be displayed.
Can I extract metadata from a URL without downloading HTML?
You need at least the HTTP response headers and usually the HTML head. A service may perform that retrieval for you, but the data still comes from the response or rendered DOM.
Why keep duplicate tags?
Duplicates can reveal conflicting templates, localization mistakes, or intentional galleries. Discarding them hides useful audit evidence.
When should I use JSON-LD instead of Open Graph?
Use JSON-LD for typed entities and relationships; use Open Graph and Twitter fields for social previews. Many pages need both.


