How to Make Playwright Web Scraping Scripts Faster
Speed up Playwright scrapers by waiting for the right content, trimming safe-to-skip requests, managing browser resources, and measuring results.
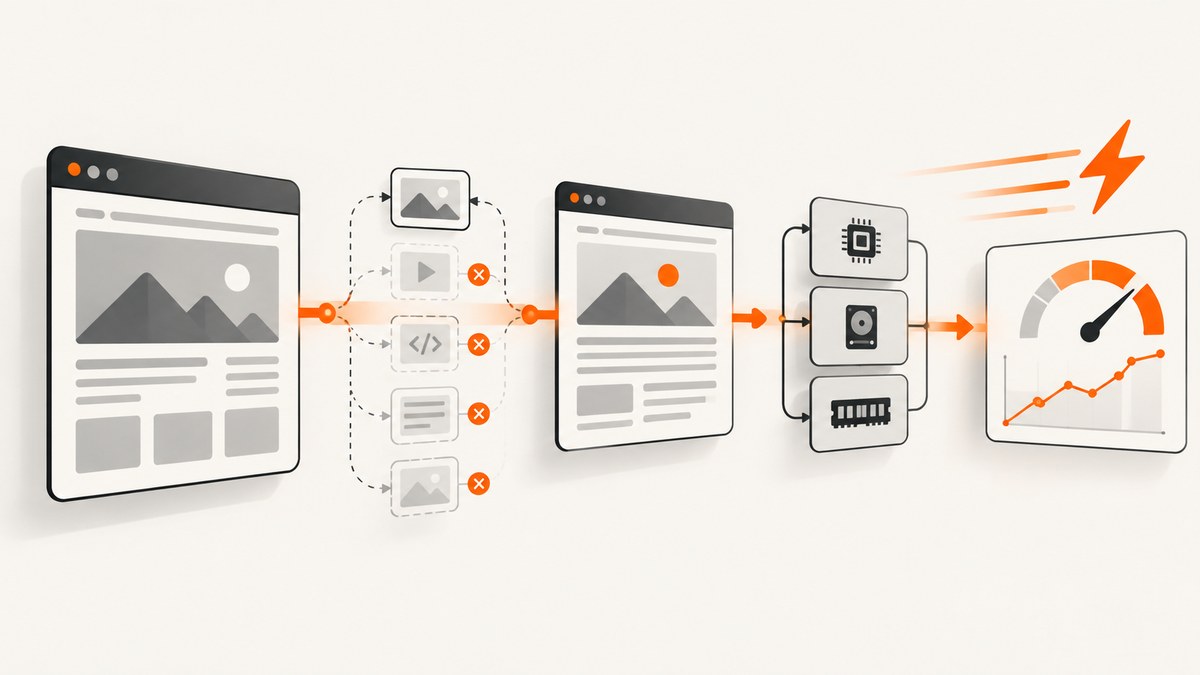
To make a Playwright web-scraping script faster, first stop waiting longer than the data requires. Choose a navigation or content-ready condition that matches what you extract, avoid redundant fixed delays, and measure where each run spends time. Then consider skipping requests the scraper does not need, reusing a browser process with deliberate context and page lifecycles, and increasing concurrency gradually. These changes have tradeoffs: early waits can capture incomplete data, request routing disables the HTTP cache, and no concurrency level is safe for every site.
There is no universal Playwright scraper speedup or safe concurrency number. The right change depends on the target pages, the extraction requirement, and the machine running the scraper. Compare changes against the same pages and verify that the same records are still collected.
1. Measure a baseline before changing the scraper
Record elapsed time and extraction correctness for a representative set of URLs before optimizing. Keep the Playwright and browser versions, machine conditions, pages, and required fields consistent between runs. A faster run that silently misses dynamically rendered content is not an improvement.
Separate the work into observable stages: navigation, waiting for the content, extracting and parsing data, and any local output or storage. Add timestamps around these stages. Playwright’s network guide explains how to monitor requests; its best-practices guidance also calls out third-party dependencies as a source of slow tests. For scraping, use that as a diagnostic prompt: determine whether time is spent waiting on the target or in your own orchestration. Do not mock the real data source when the goal is to scrape it. [Network guide] [Best practices]
const started = Date.now();
const response = await page.goto(url, { waitUntil: 'domcontentloaded' });
const navigatedAt = Date.now();
await page.locator('article h1').waitFor({ state: 'visible' });
const readyAt = Date.now();
const title = await page.locator('article h1').textContent();
const finishedAt = Date.now();

console.log({
  status: response?.status(),
  navigationMs: navigatedAt - started,
  contentWaitMs: readyAt - navigatedAt,
  extractionMs: finishedAt - readyAt,
  totalMs: finishedAt - started,
  title
});
Run the baseline more than once if repeat visits matter, because cache behavior can change the result. Keep both timing and a simple correctness check, such as the expected number of extracted records or required fields present.
2. Wait for the data you need
page.goto() supports commit, domcontentloaded, load, and networkidle. Its default is load. The Playwright Page API says networkidle waits for there to be no network connections for at least 500 ms and discourages using it as a general readiness test. A page can keep analytics, polling, or other background traffic active after the content you need is already available. Conversely, an early navigation event does not guarantee that a client-rendered listing has appeared. [Playwright Page API]
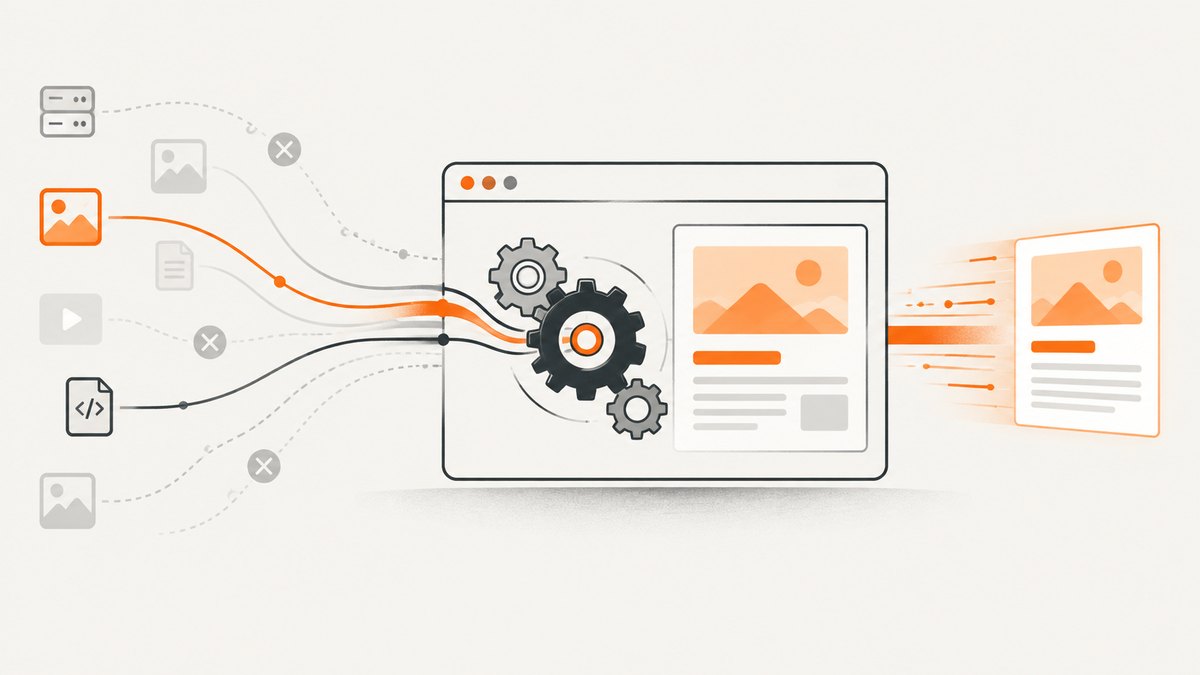
Pick the earliest signal that still makes the required data available:
commit: the response has arrived and document loading has started. Use only when you have another reliable readiness check.domcontentloaded: the initial document has been parsed. This may suit pages whose target data is in the initial markup.load: waits for the page load event; this is the default and may wait for resources your extraction does not use.networkidle: waits for a quiet network interval. Avoid using it as a blanket proxy for “scrape-ready.”
For dynamically rendered content, wait for a locator tied to the actual data, or for a specific response if the data arrives through a known request. Do not add a fixed sleep on top of a condition that already means the content is ready. If the target has a real delay or an asynchronous transition with no better signal, use a bounded delay deliberately and check the result after it.
Runnable JavaScript example
This example reuses one browser process for a small batch, creates an isolated context, checks the response, waits for the selector being scraped, and closes resources even if a URL fails. Install Playwright with npm install playwright; install its browser with npx playwright install chromium. Save as scrape.mjs and run node scrape.mjs.
import { chromium } from 'playwright';

const urls = ['https://example.com'];
const browser = await chromium.launch();
const context = await browser.newContext();

try {
  for (const url of urls) {
    const page = await context.newPage();
    try {
      const response = await page.goto(url, {
        waitUntil: 'domcontentloaded',
        timeout: 30_000
      });
      if (!response || !response.ok()) {
        throw new Error(`Navigation failed: ${response?.status() ?? 'no response'}`);
      }
      const heading = page.locator('h1').first();
      await heading.waitFor({ state: 'visible', timeout: 10_000 });
      const title = (await heading.textContent())?.trim();
      console.log({ url, title });
    } finally {
      await page.close();
    }
  }
} finally {
  await context.close();
  await browser.close();
}
Replace h1 with a selector that identifies the content you need, and validate its fields before treating the scrape as successful. If the page needs a user session, create the context with the relevant storage state or configure its cookies and headers as appropriate for that target.
3. Skip only requests the extraction does not need
Playwright routing can continue, abort, or fulfill requests. Selectively aborting assets can reduce transfers and page work when the scraper truly does not need them. But avoid blanket blocking: CSS may affect visibility or layout, images may carry lazy-loaded content, and scripts may render the data. Start with one known request class and compare both runtime and extracted results. [Playwright network guide]
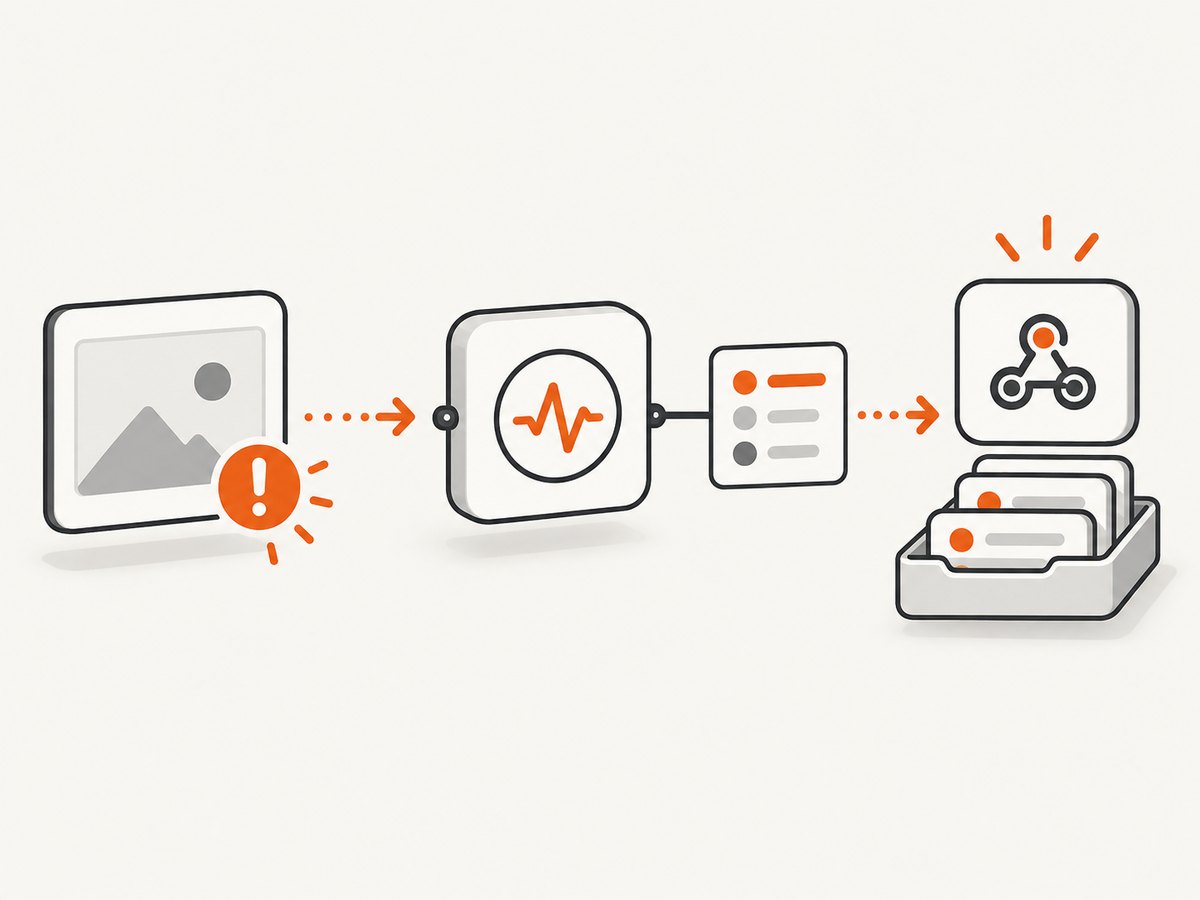
await page.route('**/*', async route => {
  const type = route.request().resourceType();
  if (type === 'image' || type === 'font') {
    await route.abort();
  } else {
    await route.continue();
  }
});
Use that policy only after confirming those resources do not affect the target’s data or behavior. A narrower URL pattern can be safer than dropping every image or font across every domain.
Two routing caveats can reverse the expected result:
- HTTP cache: enabling routing disables the HTTP cache. This can make repeated visits slower even if some requests are removed. Measure cold and repeat visits separately if cache performance matters.
- Service workers: browser-context routing does not intercept requests intercepted by a service worker. Playwright documents blocking service workers when interception is required; do so only if changing service-worker behavior is acceptable for the page you are scraping. [BrowserContext API] [Service workers]
When diagnosing routing, log request URLs and resource types first. This helps establish what the page actually fetches before you abort anything. Keep a route rule easy to disable so you can compare the routed and unrouted runs.
4. Reuse the browser and close pages deliberately
Launching a browser is a separate lifecycle decision from creating pages. Playwright recommends explicit browser contexts and pages when you need production lifecycle control; browser.newPage() is a convenience for short, single-page scenarios. Contexts isolate session state and are documented as fast and cheap to create within one browser. Reuse a browser process for a batch when appropriate, while giving independent sessions their own contexts and closing pages and contexts when finished. No universal speed gain is specified, so measure your workload. [Browser API] [Browser contexts]
Use one context for pages that should share cookies and session state. Use separate contexts when pages need isolated state. Reusing a context indiscriminately can leak cookies, local storage, or other state between unrelated jobs. Conversely, creating a new browser process for each URL adds lifecycle work and can use more local resources than a shared process. Choose lifecycle boundaries based on session requirements and observed resource use.
5. Test concurrency as a workload-specific experiment
Independent contexts can run within one browser, but Playwright’s documentation does not set a universal safe number of pages or contexts for scraping. Start with low concurrency and increase it in measured steps. Compare completed records per unit of time alongside timeouts, failed navigations, memory use, and target behavior. If throughput stops improving or failures increase, reduce parallelism.
Concurrency is not only a machine setting. A target site may respond differently as requests overlap, and the work per page varies. Keep site policies and access requirements in mind. Do not infer a safe request rate from a local benchmark on a different domain.
For production runs, define a bounded timeout, record failed URLs, and decide whether retries are appropriate for each error. Retrying every failure immediately can add load without fixing a deterministic selector or access issue. A retry should be limited and observable; retain enough information to distinguish an intermittent navigation failure from missing content.
6. Troubleshooting faster scrapers
| Symptom | Likely cause | What to change |
|---|---|---|
| Fast run returns empty or partial records | Navigation wait ended before client-rendered data was ready, or a required script/request was blocked. | Wait for a content-specific locator or response. Re-enable blocked resources one group at a time and verify fields. |
networkidle times out or takes too long |
Background requests keep the connection count active, or the page never reaches a quiet interval. | Wait for the required selector or response instead of treating global network quiet as readiness. |
| Routing makes repeat visits slower | Enabling route handlers disables HTTP cache. | Compare cold and warm runs without routing and with routing; remove interception if it costs more than it saves. |
| A blocked request still reaches the page | A service worker intercepted it before context routing. | Check service-worker behavior. If interception is essential and compatible with the target, consider blocking service workers. |
| Selector wait times out | Selector is wrong, content is absent, page changed, or the relevant frame differs. | Inspect the page and response, confirm the selector in the current markup, and report missing content clearly. |
| More parallel pages produce more failures | Workload, site response, or local resources cannot support the current concurrency. | Reduce concurrency, observe completed records and errors, then increase gradually only if stable. |
| Later jobs see unexpected page state | Pages share a context whose session state changes between jobs. | Use separate contexts for independent sessions and close them at the job boundary. |
7. Performance, reliability, and cost notes
Optimize for correct records per unit of time, not the shortest navigation timer in isolation. Keep timing for navigation, readiness, and extraction so a change can be traced to a specific stage. Repeat comparisons under the same conditions, and include both first visits and repeat visits when cache behavior matters. If you change wait conditions, request routing, or concurrency at once, you will not know which change caused a regression.
Reliability comes from explicit timeouts, meaningful readiness conditions, clear cleanup, and checks on extracted data. A scraper should distinguish an unavailable page from a successful page with zero matching records. Capture response status and error context so failures can be diagnosed rather than silently discarded.
Cost depends on where the scraper runs and what it consumes; the reviewed Playwright documentation does not provide a universal per-page cost or speed benchmark. Measure browser and machine resource use under the batch size you expect. Routing may save transfers but disable cache, while higher concurrency may improve throughput or raise memory use and failure rates. Keep an optimization only when the measured tradeoff fits the workload.
Or skip the browser setup
If you need screenshots of pages rather than structured scraping, ScreenshotNeo provides a website screenshot API. One GET request returns a PNG, JPEG, WebP, or PDF. The API accepts common screenshot API parameter names, which can make switching easier. See the ScreenshotNeo API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
await Bun.write('shot.webp', res);ScreenshotNeo removes cookie banners, popups, and chat widgets before the shot. Bot checks, blank pages, and failed loads are never billed; response headers say which page verdict applied and whether it was billed. Its MCP server lets AI agents use take_screenshot, get_page_info, and capture_pdf. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Sign up for 1,000 free screenshots a month, with no card.
Frequently asked questions
Should I always use domcontentloaded for scraping?
No. Use it when the required data is available then. For client-rendered content, add a locator or response wait tied to the data. The right condition depends on the page.
Does blocking images always speed up a scrape?
No. It can reduce work if images are irrelevant, but routing disables HTTP cache, and some pages depend on resources for behavior or lazy loading. Compare results and repeat-visit timing.
How many Playwright pages can run at once?
The cited documentation does not define a universal safe limit. Find a stable level for your target and machine by gradually increasing concurrency while tracking throughput, failures, and resource use.
Can ScreenshotNeo replace a Playwright scraper?
It returns screenshots or PDFs, not arbitrary structured extraction results. Use it when the required output is a visual capture; use browser automation when you need to interact with a page or extract its data.


