How to Find All Pages on a Website
Learn how to inventory every discoverable URL, compare sitemaps and crawls, and verify which pages Google knows, crawls, and indexes.
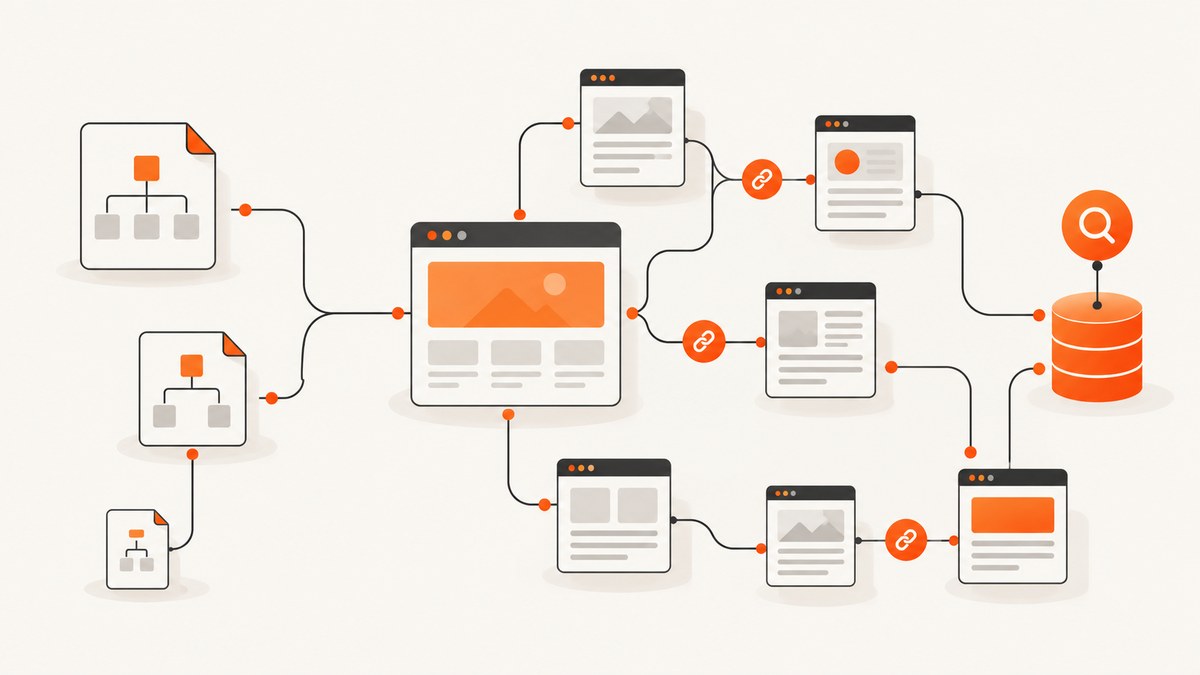
There are three different answers to “How do I find all pages on my website?”
- Every URL that exists: a site inventory assembled from sitemaps, internal links, CMS exports, logs, and application data.
- Every URL Google knows about: the set reported in Search Console and sampled by search operators.
- Every URL Google indexes: the smaller set Google considers eligible to show in search results.
No public tool can reveal every URL that exists on a site it does not control. A URL may be unlinked, blocked, generated only after a form submission, or stored in a database that crawlers cannot access. Google also separates discovery, crawling, indexing, and serving. Google states that it does not guarantee it will crawl, index, or serve a page, even when the page follows its Search Essentials (How Google Search Works).
Choose the result you need
| Method | What it shows | What it cannot prove |
|---|---|---|
site:example.com |
A sample of URLs Google knows | A complete inventory or exact count |
| XML sitemap | URLs the site owner submits for discovery | That every URL exists, is crawlable, or is indexed |
| Internal-link crawl | URLs reachable from selected starting pages | Pages with no discoverable links |
| Search Console Page indexing | Google’s reported known, submitted, crawled, and indexed statuses | Every URL on your server |
| URL Inspection | Detailed status and live test for one URL | Whether the URL will appear for every query |
For a reliable audit, use all four site-side sources: sitemap files, an internal-link crawl, Search Console, and your CMS or application database. Compare the sets instead of treating one number as “the number of pages.”
Step 1: Run a quick Google sample
Search for site:example.com, replacing the domain with yours. This is useful for spotting obvious indexed pages, old URL patterns, staging leaks, and unexpected subdomains. Google documents this as a sample check, not a complete list. Do not use the approximate result count shown on a results page as an authoritative total.

site:example.com
site:example.com/blog/
site:example.com inurl:product
site:example.com -www
Record a few result URLs and compare them with your canonical URLs. A result can be indexed under a canonical URL different from the URL you searched, and a page can be known to Google without being returned for this query.
Step 2: Find and validate the XML sitemap
Check https://example.com/robots.txt for one or more Sitemap: lines. Also inspect your CMS settings and common locations such as /sitemap.xml. A sitemap index can point to many child sitemaps.
curl -L https://example.com/robots.txt
curl -L https://example.com/sitemap.xml -o sitemap.xml
Parse each <loc> value and normalize URLs before counting them. Remove fragments, normalize host and scheme according to your canonical policy, and retain query strings because some applications use them to represent distinct resources. Do not silently discard parameterized URLs until you decide whether they are useful pages or duplicate variants.
Sitemaps are discovery hints. They can be incomplete, stale, or generated automatically by a hosting platform. Listing a URL does not guarantee crawling or indexing. Google recommends sitemaps especially for large, new, or complex sites. A sitemap file supports up to 50,000 URLs or 50 MB uncompressed; larger inventories should use multiple files and a sitemap index (Build and submit a sitemap).
Python: extract URLs from a sitemap or sitemap index
from urllib.parse import urlparse
import gzip
import io
import requests
import xml.etree.ElementTree as ET

NS = {"sm": "http://www.sitemaps.org/schemas/sitemap/0.9"}

def fetch_xml(url):
    response = requests.get(url, timeout=30)
    response.raise_for_status()
    data = response.content
    if url.endswith(".gz"):
        data = gzip.decompress(data)
    return ET.fromstring(data)

def urls_from_sitemap(url):
    root = fetch_xml(url)
    if root.tag.endswith("sitemapindex"):
        found = []
        for node in root.findall("sm:sitemap/sm:loc", NS):
            found.extend(urls_from_sitemap(node.text.strip()))
        return found
    return [node.text.strip() for node in root.findall("sm:url/sm:loc", NS)]

urls = urls_from_sitemap("https://example.com/sitemap.xml")
for url in sorted(set(urls)):
    print(url)
print(f"Total unique sitemap URLs: {len(set(urls))}")
Replace the example URL with your sitemap. Keep the raw list as an audit artifact so you can identify additions and removals over time.
Step 3: Crawl internal links
An internal-link crawl answers a different question: which pages can a visitor reach by following links from your chosen starting points? Start with the homepage, main navigation, HTML sitemap, category pages, and feeds. For each response, record the requested URL, final URL after redirects, status code, content type, canonical link, robots directives, and the source page that linked to it.
Respect the site’s robots.txt, rate-limit requests, avoid login areas, and set a clear user agent. A simple crawler is useful for small sites, but JavaScript applications may require a browser-based crawler because links are rendered after load.
Python: a small, same-origin HTML crawler
from collections import deque
from urllib.parse import urljoin, urldefrag, urlparse
import requests
from bs4 import BeautifulSoup

START = "https://example.com/"
HOST = urlparse(START).netloc
seen, queue = {START}, deque([START])
session = requests.Session()
session.headers["User-Agent"] = "SiteInventoryBot/1.0"

while queue:
    url = queue.popleft()
    try:
        r = session.get(url, timeout=20, allow_redirects=True)
    except requests.RequestException as exc:
        print("ERROR", url, exc)
        continue
    print(r.status_code, r.url, r.headers.get("content-type", ""), url)
    if "text/html" not in r.headers.get("content-type", ""):
        continue
    soup = BeautifulSoup(r.text, "html.parser")
    for tag in soup.select("a[href]"):
        absolute = urljoin(r.url, tag["href"])
        absolute = urldefrag(absolute).url
        parsed = urlparse(absolute)
        if parsed.scheme in {"http", "https"} and parsed.netloc == HOST and absolute not in seen:
            seen.add(absolute)
            queue.append(absolute)

print(f"Discovered {len(seen)} internal URLs")
This script is intentionally conservative. Production audits should add robots.txt handling, retry and backoff logic, concurrency limits, URL canonicalization, content hashing, redirect chains, and persistence. Do not treat a failed request as proof that a page does not exist.
Node.js: crawl links with built-in fetch
import { JSDOM } from "jsdom";

const start = "https://example.com/";
const host = new URL(start).host;
const queue = [start];
const seen = new Set([start]);

while (queue.length) {
  const url = queue.shift();
  try {
    const res = await fetch(url, {
      headers: { "user-agent": "SiteInventoryBot/1.0" },
      redirect: "follow",
      signal: AbortSignal.timeout(20000)
    });
    console.log(res.status, res.url, res.headers.get("content-type"));
    if (!(res.headers.get("content-type") || "").includes("text/html")) continue;
    const html = await res.text();
    const dom = new JSDOM(html, { url: res.url });
    for (const link of dom.window.document.querySelectorAll("a[href]")) {
      const next = new URL(link.href, res.url);
      next.hash = "";
      if (["http:", "https:"].includes(next.protocol) && next.host === host) {
        const normalized = next.href;
        if (!seen.has(normalized)) {
          seen.add(normalized);
          queue.push(normalized);
        }
      }
    }
  } catch (error) {
    console.error("ERROR", url, error.message);
  }
}
console.log(`Discovered ${seen.size} internal URLs`);
Install the parser with npm install jsdom. For client-rendered sites, use a browser crawler and wait for the application to finish rendering before collecting links.
Step 4: Compare sitemap, crawl, and application data
Put each source into a table keyed by normalized URL. Add columns for:
- Found in sitemap
- Found in crawl
- Found in CMS or database
- HTTP status and final URL
- Canonical URL
noindexor robots.txt restriction- Last modified time
Investigate the differences:
- Sitemap only: the page may be orphaned, blocked, redirected, deleted, or simply missed by your crawl.
- Crawl only: update the sitemap if the page should be discoverable, or remove the link if it is an accidental parameter variant.
- Database only: the application may require authentication, pagination, a form submission, or a JavaScript action to reveal the URL.
- Google only: Google may have learned an old URL, an external link target, a redirect, or a URL variant that your current site no longer exposes.
Do not automatically add every discovered URL to the sitemap. Duplicates, faceted navigation, tracking parameters, search results, and thin utility pages may not represent useful standalone content.
Step 5: Use Search Console for Google’s view
In Search Console, open the Page indexing report. It can separate known URLs, submitted sitemap URLs, crawled URLs, and indexed URLs, and it reports exclusion reasons. Filter by sitemap to check whether submitted pages are indexed.
For one missing page, use URL Inspection. Compare:
- Whether Google can crawl the URL
- Whether fetching succeeded
- Indexing permission, including
noindex - The selected canonical URL
- The live test result versus the indexed result
URL Inspection is a per-URL diagnostic, not a bulk inventory. An “URL is on Google” result also does not guarantee that the page will appear for every query. Read Google’s missing-page troubleshooting guide when a known URL is absent from results.
Dynamic sites, JavaScript, and hidden URLs
Traditional HTTP crawling misses URLs created only in JavaScript, behind filters, in infinite scroll, or after a POST request. Export routes from your framework, CMS, product catalog, or database when you control the application. For a single-page app, render pages in a real browser and collect links after hydration. For authenticated content, use a test account and keep credentials out of logs.
Also inspect:
- RSS and Atom feeds
- hreflang annotations
- Redirect logs and 404 logs
- Web server access logs
- Internal search queries
- API responses that contain canonical URLs
Or skip the browser setup
If you need visual evidence for many discovered URLs, ScreenshotNeo can capture each page through one GET request. It accepts full-page captures with lazy images loaded, CSS selector element captures, custom JavaScript and CSS, waits for selectors, delays or network idle, custom headers and cookies, blocking rules, device presets, PDFs, bulk capture of up to 100 URLs per call, caching, and signed webhooks for asynchronous jobs. See the ScreenshotNeo API documentation for parameters.
Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing status. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://example.com/page \
  -o page.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://example.com/page"},
    timeout=90,
)
r.raise_for_status()
open("page.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com/page' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`${res.status} ${await res.text()}`);
const file = await res.arrayBuffer();
await import('node:fs/promises').then(fs => fs.writeFile('page.webp', Buffer.from(file)));
Free accounts include 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 shots; every feature is available on every plan. Create a free ScreenshotNeo account.
Troubleshooting
“My sitemap has fewer URLs than my crawl”
Check whether the extra URLs are parameter variants, paginated pages, redirects, login pages, or newly published pages. Add only canonical, indexable pages that should appear in search.
“Google knows the URL but does not index it”
Inspect the URL for duplication, a canonical pointing elsewhere, noindex, blocked resources, weak internal linking, or content that Google considers unsuitable for indexing. Fix the relevant cause, then request recrawl; submission is not a guarantee.
“The crawler gets 403 or 429 responses”
Reduce concurrency, obey robots.txt, identify your user agent, and use backoff. A WAF may require an approved crawler or a browser session. Never bypass access controls without authorization.
“JavaScript pages are missing links”
Use a rendering crawler, wait for hydration or network idle, and collect links from the rendered DOM. Also export routes from the application because some valid URLs are not linked anywhere.
“The screenshot is blank or shows a consent wall”
Wait for a selector or network idle, provide required headers or cookies, and inspect the page verdict. ScreenshotNeo removes more than 60 known consent platforms plus newsletter and chat widgets before capture; failed or blank captures are not billed.
Performance, reliability, and cost
For large inventories, crawl in batches, persist results, and use conditional requests where your server supports them. Keep a stable URL normalization policy so changes in trailing slashes, hostnames, or tracking parameters do not create false differences. Separate discovery from rendering: first collect URLs cheaply with sitemaps and HTML, then render only pages that need visual validation.
Cache immutable or infrequently changing pages and assign a short retry budget for transient failures. Track status codes, redirect chains, and timestamps so a later audit can distinguish a deleted page from a temporary outage. With ScreenshotNeo, chosen cache TTLs and bulk capture can reduce repeated work; only clean shots are billed, while failed loads and cache hits cost nothing.
Checklist
- Run several
site:searches for a fast sample. - Locate every sitemap and sitemap index from robots.txt and your CMS.
- Parse and deduplicate sitemap URLs.
- Crawl internal links from the homepage and key navigation pages.
- Export URLs from your CMS, database, feeds, and logs.
- Compare the sets and investigate every difference.
- Review Page indexing in Search Console.
- Use URL Inspection for individual missing or unexpected URLs.
- Decide which duplicates, parameters, and utility pages should remain out of the index.
- Repeat the comparison on a schedule and keep historical results.
FAQ
Can I get an exact number from Google?
No. site: results are sampled, and Search Console describes Google’s systems rather than every URL that exists on your site.
Does every sitemap URL get indexed?
No. A sitemap helps discovery but does not guarantee crawling, indexing, or search visibility.
Should every URL in my database be crawlable?
No. Keep duplicates, private resources, temporary states, and low-value parameter combinations out of public navigation and indexing according to their purpose.
How often should I run an inventory?
Run it after major releases and on a schedule that matches publishing volume. Store snapshots so you can detect orphaned, redirected, and unexpectedly removed pages.


