How to Find the Index of an Element in a Python List
Use list.index() for the first match, enumerate() for custom searches, and safe patterns for missing values, duplicates, ranges, and all matches.
To find the index of a known value in a Python list, call my_list.index(value). Python returns the zero-based index of the first equal element. If the value is absent, Python raises ValueError.
items = ["red", "blue", "green"]
position = items.index("blue")
print(position)  # 1
List indexes start at 0, so the first item is at position 0, the second at position 1, and so on. This guide covers the basic method, missing values, duplicate values, bounded searches, custom matching, every matching index, performance, and production troubleshooting.
1. Use list.index() for the first matching value
The list method has this form:
list.index(value, start, stop)value is required. start and stop are optional bounds. The method compares each item with the target using normal equality and returns as soon as it finds the first match.
languages = ["Python", "Go", "Rust", "Python"]

first_python = languages.index("Python")
print(first_python)  # 0
The returned number refers to the original list, not to a newly created slice. The list is not changed by index().
Values are compared with equality
Any value that can be compared with == can be searched, including numbers, strings, tuples, and many custom objects.
records = [("ada", 36), ("grace", 41), ("linus", 55)]
position = records.index(("grace", 41))
print(position)  # 1
For custom classes, the result depends on that class's equality implementation. Two separate objects can be considered equal if their __eq__() methods say so.
2. Handle a value that is not present
If no item equals the target, index() raises ValueError. It does not return -1 or None.
items = ["red", "blue", "green"]

try:
    position = items.index("purple")
except ValueError:
    position = None

print(position)  # None
Use this pattern when absence is an expected input condition. Keep the try block small so that unrelated errors are not accidentally treated as “not found.”
Return a default with a helper function
If your application repeatedly needs a default value, wrap the operation:
def find_index(values, target, default=None):
    try:
        return values.index(target)
    except ValueError:
        return default

colors = ["red", "blue", "green"]
print(find_index(colors, "blue"))       # 1
print(find_index(colors, "purple"))     # None
print(find_index(colors, "purple", -1)) # -1
Choose a default that cannot be confused with a valid position. For most application code, None makes the missing case explicit.
Check membership first only when it improves readability
if target in items:
    position = items.index(target)
else:
    position = None
This performs two scans in the successful case, so exception handling is usually more efficient for a one-off lookup. A membership check can still be clear when the branch needs to do different work before calculating the index.
3. Find a later occurrence in a list with duplicates
index() always returns the first match in the searched range. To find the second or later occurrence, start the next search after the previous position.
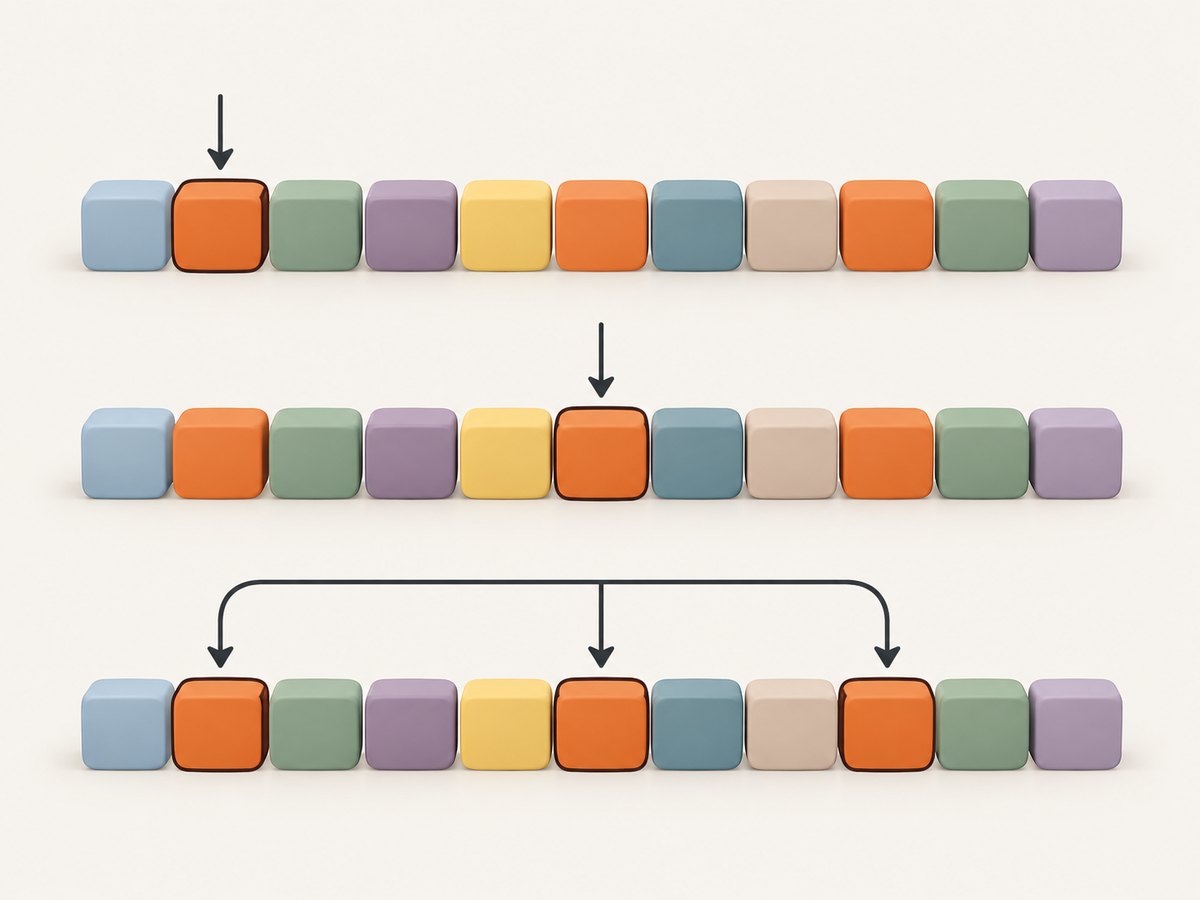
events = ["open", "close", "open", "open"]

first = events.index("open")
second = events.index("open", first + 1)
third = events.index("open", second + 1)

print(first, second, third)  # 0 2 3
If a later occurrence might not exist, each call can raise ValueError. A loop is safer when the number of matches is unknown:
def find_nth(values, target, occurrence):
    if occurrence < 1:
        raise ValueError("occurrence must be at least 1")

    start = 0
    for _ in range(occurrence):
        try:
            position = values.index(target, start)
        except ValueError:
            return None
        start = position + 1
    return position

values = ["a", "b", "a", "c", "a"]
print(find_nth(values, "a", 2))  # 2
print(find_nth(values, "a", 4))  # None
4. Restrict the search with start and stop
The optional bounds follow slice-style rules:
items.index(value, start, stop)startis the first position considered.stopis the exclusive end position.- Negative bounds are interpreted relative to the end, like slicing.
- The returned index is still an index in the original list.
items = ["zero", "one", "two", "three", "two"]

position = items.index("two", 3)
print(position)  # 4

position = items.index("two", 0, 3)
print(position)  # 2
In the second call, positions 0, 1, and 2 are searched; position 3 is excluded. If the target is outside the range, ValueError is raised.
Negative bounds
items = ["a", "b", "c", "b"]
position = items.index("b", -2)
print(position)  # 3
Here -2 starts at the third item. Bounds that extend beyond the list are clipped in the same general way as slice bounds. An empty or invalid range produces ValueError.
5. Use enumerate() for custom conditions
list.index() searches for a value using equality. Use enumerate() when the condition is more complex, such as a field comparison, a prefix check, or a numeric threshold.
users = [
    {"name": "Ada", "active": False},
    {"name": "Linus", "active": True},
    {"name": "Grace", "active": True},
]

for position, user in enumerate(users):
    if user["active"]:
        print(position)  # 1
        break
enumerate() starts at zero by default. You can choose another counter when displaying or processing a one-based position:
for display_number, value in enumerate(["a", "b", "c"], start=1):
    print(display_number, value)
# 1 a
# 2 b
# 3 c
The start argument changes the number produced by enumerate(); it does not change the list's actual indexes. Use start=1 for human-facing numbering, and keep the default for indexes used to access the list.
6. Find every matching index
For all equal values, combine enumerate() with a list comprehension:
items = ["red", "blue", "green", "blue", "blue"]
positions = [i for i, value in enumerate(items) if value == "blue"]
print(positions)  # [1, 3, 4]
This returns an empty list when nothing matches, which is often easier to consume than an exception.
For a custom predicate, put the condition in the comprehension:
temperatures = [17, 21, 29, 12, 30]
hot_positions = [
    i for i, temperature in enumerate(temperatures)
    if temperature >= 25
]
print(hot_positions)  # [2, 4]
If the list is large and you only need to process matches once, use a generator expression to avoid building a second list:
positions = (i for i, value in enumerate(items) if value == "blue")
for position in positions:
    print(position)
7. Choose the right approach
| Need | Recommended code | Missing result |
|---|---|---|
| First equal value | items.index(target) |
ValueError |
| First match in a range | items.index(target, start, stop) |
ValueError |
| Custom condition | next((i for i, x in enumerate(items) if condition), None) |
None |
| Every matching index | [i for i, x in enumerate(items) if condition] |
Empty list |
| Repeated key lookups | Build a dictionary or index structure | Depends on your lookup design |
items = ["red", "blue", "green"]
target = "blue"
position = next(
    (i for i, value in enumerate(items) if value == target),
    None,
)
print(position)  # 1
The next() pattern is useful when you want a custom condition and only the first match. It avoids a separate list allocation.
8. Performance and data-structure choices
list.index() scans from the beginning of the selected range until it finds a match. In the worst case it examines every item, so a single lookup is O(n). enumerate() with a stopping condition has the same linear worst-case behavior.
If you repeatedly need to find positions by a stable key, scanning the list each time can become expensive. Build a dictionary once:
names = ["Ada", "Linus", "Grace"]
position_by_name = {name: i for i, name in enumerate(names)}

print(position_by_name["Grace"])  # 2
Dictionary lookups are average O(1), but you must update the dictionary whenever the list changes. Duplicate keys also require a policy: keep the first position, keep the last, or store a list of positions.
For a one-time search, index() is simpler and avoids extra memory. Do not convert a list to a set when you need an index: sets provide membership, not stable positional lookup.
9. Common errors and fixes
ValueError: list.index(x): x not in list
Cause: no element equals the target, or the target is outside the specified range.
Fix: catch ValueError, use next(..., None), or verify the input and bounds.
Unexpected index from duplicate data
Cause: index() intentionally returns the first match.
Fix: pass a later start position, or collect all positions with enumerate().
Confusing one-based display numbers with indexes
Cause: using enumerate(items, start=1) and then using that number to index the list.
Fix: keep zero-based values for list access. Convert to one-based numbering only when presenting results.
Searching for a similar but unequal value
Cause: equality is exact for the types involved. For example, extra whitespace or different capitalization can prevent a match.
Fix: normalize before comparing, or use a custom predicate:
words = [" Alpha ", "beta", "GAMMA"]
target = "alpha"
position = next(
    (i for i, word in enumerate(words) if word.strip().lower() == target),
    None,
)
print(position)  # 0
Mutating the list during iteration
Cause: inserting or removing elements while scanning changes later positions and can skip items.
Fix: search a stable snapshot, collect changes first, or construct a new list. Apply mutations after the search has completed.
10. Practical patterns
Find the first object matching a field
products = [
    {"sku": "A10", "price": 12},
    {"sku": "B20", "price": 18},
]

position = next(
    (i for i, product in enumerate(products) if product["sku"] == "B20"),
    None,
)
print(position)  # 1
Find the first non-empty value
values = [None, "", "ready", "done"]
position = next(
    (i for i, value in enumerate(values) if value),
    None,
)
print(position)  # 2
Find an index while validating input
def index_of_status(statuses, wanted):
    if not isinstance(statuses, list):
        raise TypeError("statuses must be a list")
    try:
        return statuses.index(wanted)
    except ValueError:
        return None
11. Or skip the browser setup
If you are collecting indexes as part of a workflow that also needs page screenshots, ScreenshotNeo provides a single HTTP request instead of maintaining browser automation. The API can capture a clean PNG, JPEG, WebP, or PDF. Before capture it accepts cookie and consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets. Each cleanup step can be turned off.
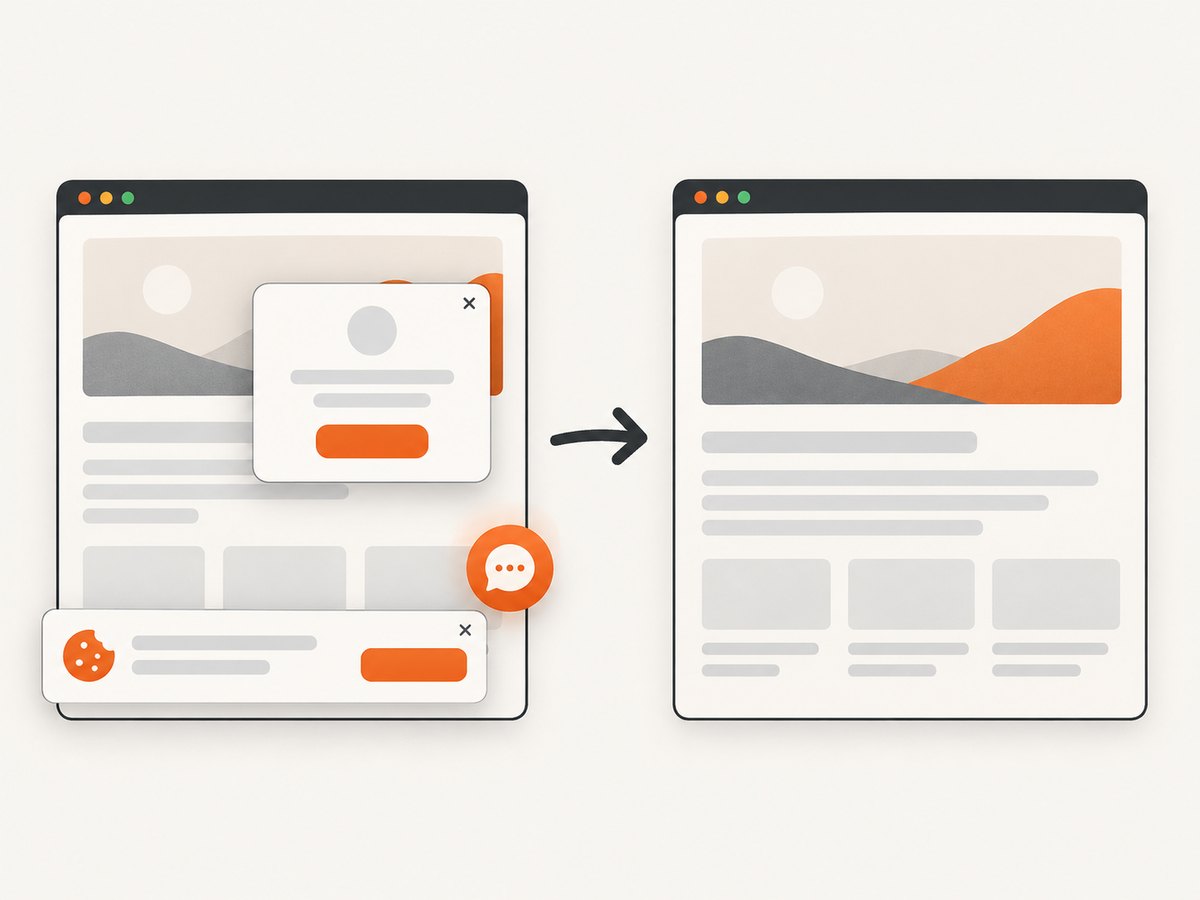
Only clean shots are billed. Bot checks and CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and the response reports the result through X-Page-Verdict and X-Billed headers.
See the ScreenshotNeo API documentation for the complete parameter list.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const image = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('shot.webp', image);
You can also use full-page capture with lazy images loaded, CSS element capture, dark mode, device presets, custom viewports, retina scale, PDF paper sizes and ranges, custom CSS and JavaScript, clicks, selector waits, delays, network-idle waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, chosen cache TTLs, signed links, asynchronous jobs with signed webhooks, bulk capture for up to 100 URLs per call, and the usage API. An MCP server exposes take_screenshot, get_page_info, and capture_pdf to Claude, Cursor, and other MCP clients.
The Free plan includes 1,000 screenshots each month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is available on every plan. Create a free ScreenshotNeo account.
12. Frequently asked questions
Does index() work with nested lists?
Yes. It compares each nested list as a value. To find an item inside nested lists, use nested loops or a custom predicate.
Can I find an index without raising an exception?
Yes. Use next((i for i, x in enumerate(items) if x == target), None), or catch ValueError around index().
What is the difference between find() and index()?
Strings provide find(), which returns -1 when a substring is absent. Lists provide index(), which raises ValueError when a value is absent.
Can I search from the end?
Use a reversed enumeration when you need the last matching position:
items = ["a", "b", "a"]
last = next(
    (i for i in range(len(items) - 1, -1, -1) if items[i] == "a"),
    None,
)
print(last)  # 2
Should I use a dictionary instead of a list?
Use a dictionary when repeated key lookups matter more than positional order. Keep a list when order and duplicate values are central to the data.
13. Quick checklist
- Use
items.index(target)for the first equal value. - Remember that indexes are zero-based.
- Handle
ValueErrorwhen a target may be absent. - Pass
startandstopto search a bounded region. - Use
enumerate()for custom conditions or every match. - Build a dictionary for frequent lookups by a stable key.
- Do not mutate the list while relying on its current positions.


