How to Fix jsPDF addHTML() Only Capturing document.body
Fix jsPDF addHTML() body-only PDFs by migrating to html(), verifying selectors, isolating canvas capture, and handling browser limits.
Direct answer: addHTML() is deprecated. Replace it with the maintained jsPDF html() method, pass the exact element you want to render, and verify that element before creating the PDF. If the output still contains only document.body, test the DOM-to-canvas step separately, then check package versions, cross-origin resources, cloning behavior, and canvas limits.
The body-only symptom does not have one universal cause. It can come from selecting the wrong node, using a legacy invocation with a newer dependency, or rendering content that the browser cannot draw into a canvas. This guide gives a repeatable diagnostic path and complete browser examples.
Why addHTML() captures the wrong content
Older jsPDF integrations commonly used doc.addHTML(...) or doc.fromHTML(...). The jsPDF maintainers documented those paths as deprecated and described html() as the maintained HTML-rendering route. The release discussion explains that the newer method is based on html2canvas and the jsPDF context2d module (jsPDF 1.4.2 release discussion).
A body-only PDF usually means the rendering call received document.body, a wrapper that contains more than the intended panel, or an argument shape that the installed version does not interpret as the target element. A callback mismatch between old jsPDF integrations and Promise-based html2canvas versions was also reported historically; treat that report as version-specific evidence, not as a diagnosis for every current project.
Step 1: verify the target element
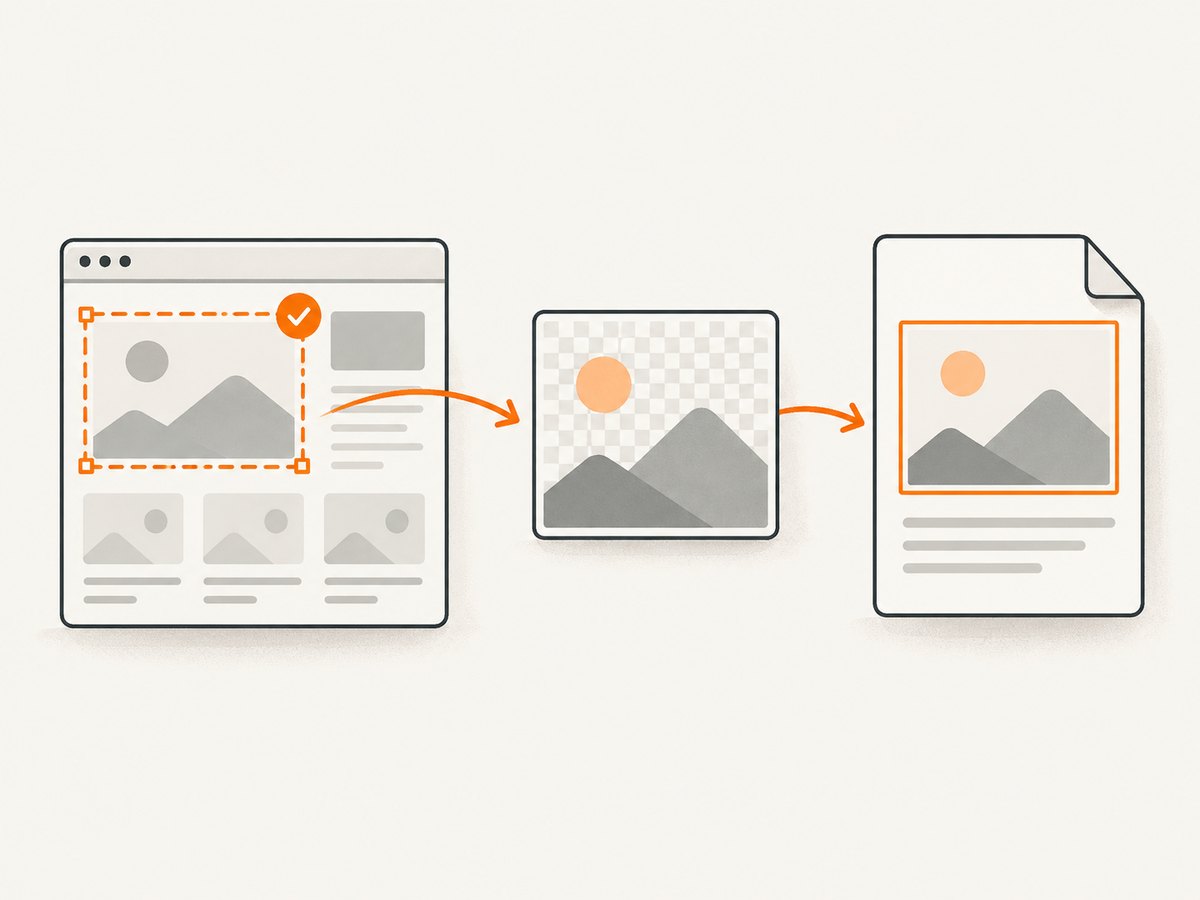
Start by proving that the selector returns the node you intend to export. Do this immediately before the PDF call, after your application has mounted the content.
const target = document.querySelector('#pdf-content');

if (!target) {
  throw new Error('PDF target not found');
}

console.log({
  tag: target.tagName,
  id: target.id,
  className: target.className,
  width: target.scrollWidth,
  height: target.scrollHeight
});
Use a unique ID or a narrowly scoped class. Avoid a selector that matches a hidden template, a modal copy, or several cards. If the content is rendered by React, Vue, or another framework, run the export after the component and its data have finished rendering.
Step 2: migrate to jsPDF html()
Install and import the versions selected by your project, then confirm the html() signature in that version’s API documentation. The migration direction is stable, but callback and option details vary across jsPDF releases.
import { jsPDF } from 'jspdf';

export function exportPdf() {
  const target = document.querySelector('#pdf-content');
  if (!target) throw new Error('PDF target not found');

  const doc = new jsPDF({
    orientation: 'portrait',
    unit: 'mm',
    format: 'a4'
  });

  doc.html(target, {
    margin: [12, 12, 12, 12],
    autoPaging: 'text',
    callback: (pdf) => {
      pdf.save('document.pdf');
    }
  });
}
Do not copy this option set blindly between major versions. Check whether your installed release expects a callback, a Promise, or both. The key fix is that target, not document.body, is passed to html().
Plain browser script example
<button id="download">Download PDF</button>

<script type="module">
  import { jsPDF } from 'https://cdn.jsdelivr.net/npm/jspdf/+esm';

  document.querySelector('#download').addEventListener('click', () => {
    const target = document.querySelector('#pdf-content');
    if (!target) throw new Error('PDF target not found');

    const pdf = new jsPDF();
    pdf.html(target, {
      callback: (doc) => doc.save('document.pdf')
    });
  });
</script>
Step 3: isolate canvas capture before PDF generation
When the PDF is wrong, separate browser rendering from PDF placement. html2canvas documents calling html2canvas(element, options?) with any DOM element and returning a Promise that resolves to a canvas (html2canvas documentation).
import html2canvas from 'html2canvas';

async function inspectCapture() {
  const target = document.querySelector('#pdf-content');
  if (!target) throw new Error('PDF target not found');

  const canvas = await html2canvas(target, {
    backgroundColor: '#ffffff',
    useCORS: true,
    scale: window.devicePixelRatio
  });

  document.body.appendChild(canvas); // temporary diagnostic output
  console.log(canvas.width, canvas.height);
}

inspectCapture().catch(console.error);
If this diagnostic canvas already shows the body or the wrong panel, fix selection, visibility, layout, or resource loading before investigating jsPDF. If the canvas is correct but the PDF is wrong, focus on page size, scaling, pagination, and the jsPDF version.
Alternative browser workflow: html2pdf.js
html2pdf.js provides a separate browser-only pipeline. Its README demonstrates selecting a node and calling html2pdf(element) (html2pdf.js documentation).
import html2pdf from 'html2pdf.js';

const target = document.querySelector('#pdf-content');
if (!target) throw new Error('PDF target not found');

html2pdf(target)
  .set({
    margin: 10,
    filename: 'document.pdf',
    image: { type: 'jpeg', quality: 0.95 },
    html2canvas: { scale: 2, useCORS: true },
    jsPDF: { unit: 'mm', format: 'a4', orientation: 'portrait' },
    pagebreak: { mode: ['css', 'legacy'] }
  })
  .save();
Use the bundled package when possible. If you load unbundled scripts, load jsPDF first, html2canvas second, and html2pdf.js third. html2pdf.js rasterizes the rendered content, so text may not remain selectable or searchable and large pages can produce large files.
Options that affect what gets captured
| Concern | What to check |
|---|---|
| Selector | Use one visible element and log it before rendering. |
| Timing | Wait for fonts, images, API data, and framework rendering to finish. |
| Page size | Set jsPDF unit, format, orientation, and margins deliberately. |
| Pagination | Use CSS page-break rules or the library’s page-break options for long content. |
| Images | Use same-origin URLs or correctly configured CORS headers. |
| Fonts | Wait for document.fonts.ready when web fonts affect layout. |
| Background | Set an explicit background color if transparent sections render unexpectedly. |
| Scale | Increase scale for sharper output, but watch memory and canvas dimensions. |
await document.fonts.ready;

await Promise.all(
  [...document.images]
    .filter((img) => !img.complete)
    .map((img) => new Promise((resolve) => {
      img.addEventListener('load', resolve, { once: true });
      img.addEventListener('error', resolve, { once: true });
    }))
);
Common errors and fixes
“The PDF contains the whole page”
Cause: the call receives document.body, a broad wrapper, or a selector that matches the wrong node.
Fix: log document.querySelector('#pdf-content'), verify its identity and dimensions, and pass that reference directly to html(), html2canvas(), or html2pdf().
“The callback never runs”
Cause: a legacy callback assumption is being mixed with a newer Promise-based dependency or an incompatible jsPDF release.
Fix: inspect installed versions with your package manager, read the API documentation for that exact release, and use its documented completion mechanism. Historical html2canvas 1.0.0-alpha.10 discussions mention this type of integration problem, but they do not establish a current universal fix.
“The canvas is blank”
Cause: the node is hidden, not laid out, still loading, or contains resources blocked by browser security rules.
Fix: capture after layout completes, avoid display: none, wait for images and fonts, and inspect cross-origin image headers. html2canvas cannot bypass browser same-origin restrictions.
“Images or charts are missing”
Cause: cross-origin assets taint the canvas, or a chart library has not finished drawing.
Fix: serve assets with appropriate CORS headers, set useCORS where supported, wait for the chart’s completion event, and test the canvas independently.
“Long pages crash or produce clipped output”
Cause: browser canvas dimensions and memory are finite. html2pdf.js also documents cloning and canvas-size limitations.
Fix: split very long documents into sections, reduce scale, paginate before rasterization, or generate the PDF on a server with a browser automation tool.
“The PDF is blurry or text cannot be selected”
Cause: the workflow renders HTML into an image before placing it in the PDF.
Fix: decide whether image-based output is acceptable. If selectable text is required, use a PDF renderer designed to preserve text and verify its CSS support.
Performance and reliability checklist
- Capture only the required subtree instead of the entire body.
- Set a practical
scale; higher values increase memory, render time, and file size. - Lazy-load or omit images that are outside the requested pages.
- Wait for fonts and images once, then reuse the settled DOM.
- Remove animations during capture with a print/export CSS class.
- Use deterministic widths so responsive breakpoints do not change between runs.
- Test on the browsers your users actually run, including mobile Safari if relevant.
- Log selector, viewport, library versions, canvas dimensions, and elapsed time when diagnosing failures.
Or skip the browser setup
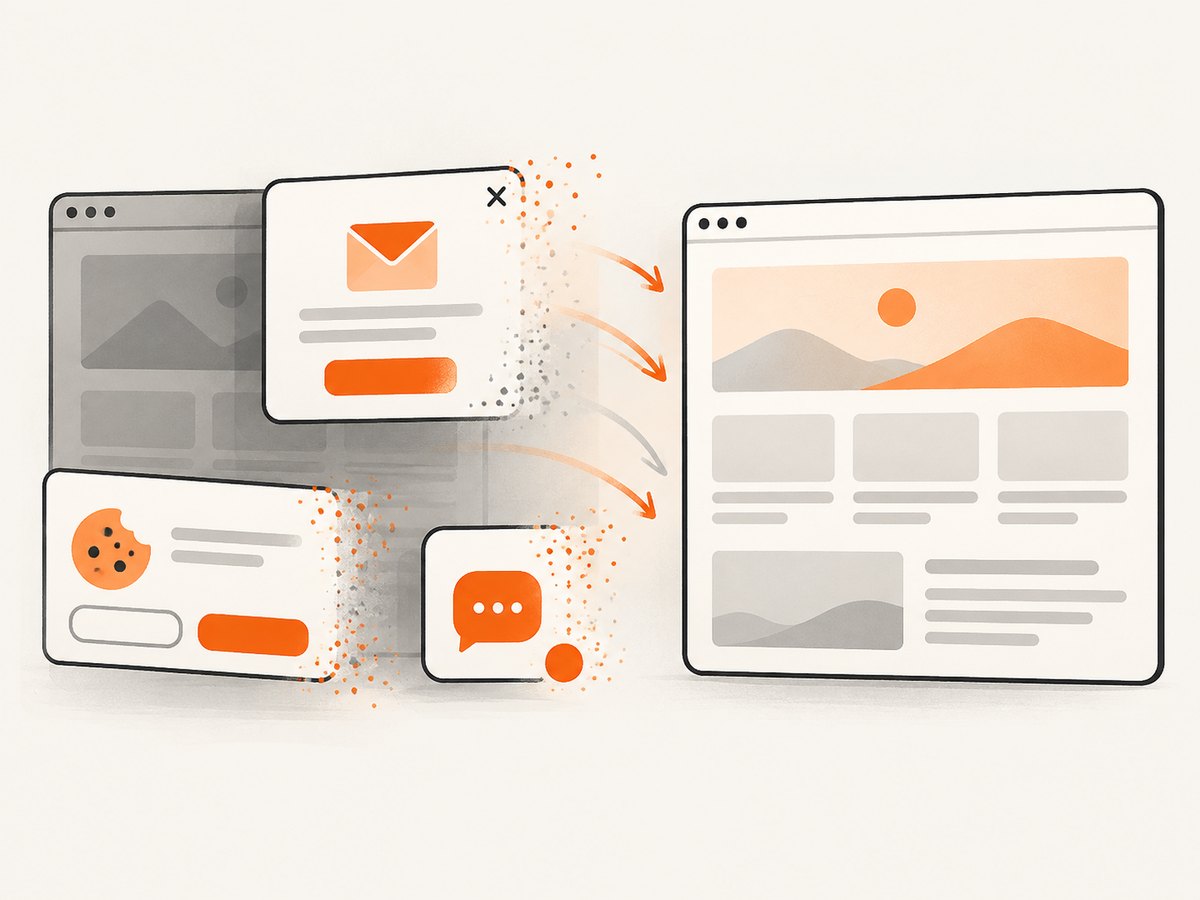
For a screenshot or PDF endpoint, ScreenshotNeo handles the browser capture for you. It accepts consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and each response reports the page verdict and billing status in headers. Its MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
See the ScreenshotNeo API documentation for all options. A direct call looks like this:
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
await import('node:fs/promises').then(fs => fs.writeFile('shot.webp', buffer));
You can request full-page captures, one CSS-selected element, dark mode, device presets or custom viewports, retina scale, PDF paper settings and page ranges, custom CSS and JavaScript, clicks, waits, blocked resources, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, caching with a chosen TTL, signed links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs, and usage data.
The Free plan includes 1,000 screenshots each month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free. Create a free ScreenshotNeo account.
Cost and architecture choices
A client-side jsPDF workflow has no screenshot API charge, but it consumes the user’s CPU and depends on browser rendering, CORS, memory, and installed dependencies. A server-side browser gives you a controlled runtime but adds infrastructure and queue management. ScreenshotNeo charges only for clean shots; failed loads, bot checks, blank pages, timeouts, and cache hits are free, which can make retry-heavy jobs easier to budget.
FAQ
Can I keep using addHTML()?
You can keep legacy code temporarily, but new code should use the maintained html() path and a verified element reference.
Should I pass an HTML string or a DOM node?
For this bug, pass the DOM node you inspected. Element-based capture makes it clear which subtree is being rendered.
Does html2canvas create a real PDF?
No. It creates a canvas. jsPDF or html2pdf.js then places that rendered result into a PDF.
Why does the result differ between browsers?
Font availability, layout engines, image security rules, viewport dimensions, and canvas limits vary by browser.
When should I use a hosted screenshot API?
Use one when you need repeatable server-side captures, queueing, bulk URLs, signed delivery, or an MCP interface without maintaining browser automation.


