How to Fix a MissingSchema Error in Python Requests
Fix Requests’ MissingSchema error by finding the URL or proxy value without a scheme, validating it, and resolving relative links correctly.
requests.exceptions.MissingSchema usually means Requests is preparing an HTTP URL that has no scheme, such as https:// or http://. Pass a complete absolute URL, inspect the exact value immediately before the request, and check proxy configuration if you use one. Requests 2.x also requires a scheme on proxy URLs.
For example, example.com/products is missing a scheme; https://example.com/products is an absolute URL. A proxy setting such as 10.10.1.10:3128 has the same problem as a destination URL without a scheme. Add the correct protocol to the value that is actually incomplete.
1. What MissingSchema means
Requests prepares a URL before sending the HTTP request. If parsing finds no scheme, Requests raises MissingSchema, often with a message like Invalid URL ...: No scheme supplied. Perhaps you meant https://...?. That message is a clue about URL structure; it does not establish which scheme or host you intend to use.
A URL has several parts. In https://example.com/products?id=7, https is the scheme, example.com is the host, /products is the path, and id=7 is a query parameter. Requests can encode query parameters for you, but parameters cannot supply a missing scheme.
Do not confuse a missing scheme with a missing host. Requests reports a URL that has a scheme but no host as a different invalid URL condition, typically InvalidURL with a “No host supplied” message. Fix the component the error identifies; adding https:// to a string that already has a scheme but no host will not create a valid destination.
2. Diagnose the value reaching Requests
Start by checking the runtime value directly before the failing call. The value may not be the one you expected: it could be None, an empty string, a relative path, or a different variable.
import requests

url = "example.com/products"
print("url:", repr(url))
print("type:", type(url).__name__)

response = requests.get(url)
This example prints the value and then fails because it has no scheme. Inspect the log without printing secrets embedded in URLs, such as access tokens in query strings. In production, log a sanitized URL or just the parsed scheme and host.
Check these items in order:
- Is the value a non-empty string?
- Does it contain the intended scheme, normally
https://for a public website? - Does it contain a host after the scheme?
- Was it built from the expected configuration key, scraped link, or function argument?
- If you use a proxy, does its URL also include a scheme?
3. Fix the destination URL
Use a complete absolute URL
For a normal web request, supply the full address. Choose http:// only when that is the correct protocol for the service; use https:// when the target supports HTTPS.
import requests

url = "https://example.com/products"
response = requests.get(url, timeout=20)
response.raise_for_status()

print(response.status_code)
print(response.url)
print(response.text[:200])
raise_for_status() raises an HTTP error for unsuccessful HTTP status codes. It is separate from URL construction: a missing scheme fails before a response exists, while a 404 or 500 is a server response that you can inspect.
Resolve a relative link against its base
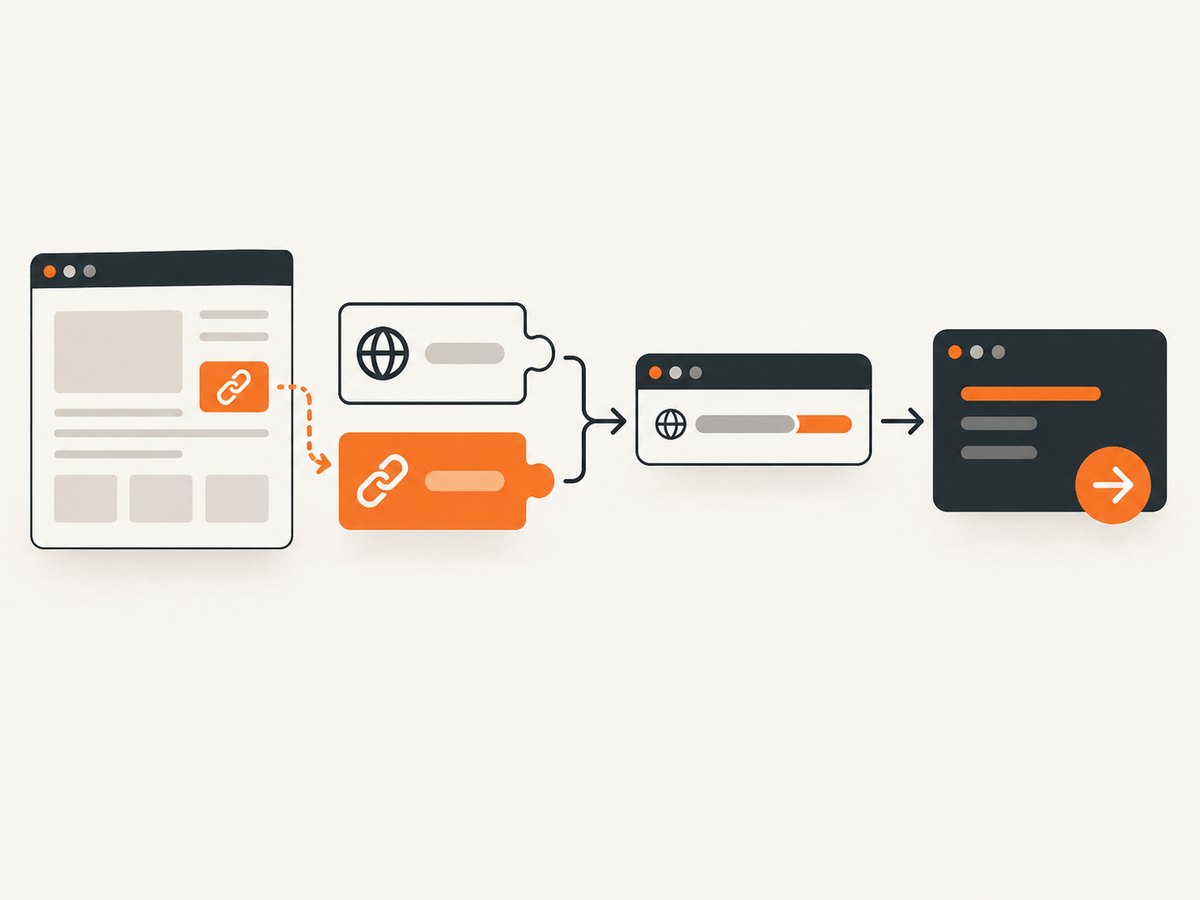
A scraped link such as /products/1 or ../help is a path, not a complete URL. Resolve it against the absolute page URL from which it came before requesting it. Python’s standard library urllib.parse.urljoin handles relative paths and absolute links:
from urllib.parse import urljoin
import requests

page_url = "https://example.com/catalog/"
href = "../products/1"
absolute_url = urljoin(page_url, href)

print(absolute_url)  # https://example.com/products/1
response = requests.get(absolute_url, timeout=20)
response.raise_for_status()
Use the real page URL as the base. A relative path cannot be resolved reliably without knowing which site and path it belongs to. Also remember that a link can itself be absolute; urljoin will use that destination, so validate links if your application must restrict requests to specific hosts.
Validate inputs before making the request
Fail near the source of bad data with a useful message. A small guard catches empty values and relative inputs without trying to guess a scheme:
from urllib.parse import urlsplit
import requests


def get_page(url: str) -> requests.Response:
    if not isinstance(url, str) or not url.strip():
        raise ValueError("url must be a non-empty string")

    url = url.strip()
    parsed = urlsplit(url)
    if parsed.scheme not in {"http", "https"} or not parsed.netloc:
        raise ValueError(f"expected an absolute HTTP(S) URL, got {url!r}")

    response = requests.get(url, timeout=(5, 20))
    response.raise_for_status()
    return response


response = get_page("https://example.com")
print(response.status_code)
This check is for common web URLs, not every URI scheme. If your application supports other schemes or unusual host formats, define its accepted inputs explicitly. Do not silently prefix https:// to arbitrary strings: that can disguise a bad value, produce a different destination than intended, and make debugging harder.
4. Check proxy configuration separately
Requests can use proxy values supplied in the request, a session, or environment configuration. In Requests 2.x, a proxy address needs a scheme too. For example, change 10.10.1.10:3128 to http://10.10.1.10:3128 when that is the appropriate proxy protocol.
import requests

proxies = {
    "http": "http://10.10.1.10:3128",
    "https": "http://10.10.1.10:3128",
}

response = requests.get(
    "https://example.com",
    proxies=proxies,
    timeout=20,
)
response.raise_for_status()
The proxy URL’s scheme describes how to connect to the proxy; the dictionary keys describe which destination traffic uses it. A proxy may accept HTTP connections while forwarding HTTPS destinations, which is why the example has http:// values for both keys. Use the protocol and address provided by your proxy operator.
If the destination is complete but the exception persists, inspect proxy environment variables such as HTTP_PROXY and HTTPS_PROXY, along with any session-level proxy configuration. Avoid logging proxy credentials. A malformed proxy value can be the source even when the URL passed to requests.get is valid.
5. Use query parameters without changing the base URL
Pass query data with params instead of building a query string by concatenating text. This takes care of encoding values, but the base URL still must be absolute:
import requests

response = requests.get(
    "https://api.example.com/search",
    params={"q": "red shoes", "page": 2},
    timeout=20,
)
response.raise_for_status()
print(response.url)
Passing "api.example.com/search" as the first argument and adding params does not fix MissingSchema. Correct the base URL first, then supply parameters.
6. Troubleshooting common cases
| Symptom | Likely cause | Fix |
|---|---|---|
Invalid URL 'example.com': No scheme supplied |
The destination is a bare domain or relative value. | Use the intended absolute URL, such as https://example.com, or resolve the relative link against its page URL. |
The error includes None |
The URL variable was not populated, or a lookup/extraction returned no value. | Trace its assignment and validate it before the request. Handle the missing input explicitly instead of converting it to text. |
The value prints as '' |
An empty configuration value or extraction result reached Requests. | Check configuration loading and parsing; reject empty URLs with a clear application error. |
A scraped href starts with / or ../ |
It is a relative path with no host and scheme. | Join it to the absolute URL of the page containing the link, then inspect the result. |
| Destination looks valid but MissingSchema remains | A proxy URL may lack its scheme, or a different variable is passed than the one inspected. | Inspect the actual call arguments and proxy configuration separately. Redact any credentials while logging. |
InvalidURL: No host supplied |
A scheme exists, but the host is absent, such as a malformed https:// value. |
Correct the host or input construction. This is not the same condition as a missing scheme. |
| A valid URL now produces a 4xx or 5xx response | URL preparation succeeded; the server returned an HTTP error. | Inspect the status, response body, authentication, path, and query parameters. Use raise_for_status() if exceptions are preferable. |
When errors appear only in one environment, compare the sanitized runtime URL, configuration source, Requests version, and proxy settings between environments. A local hard-coded URL can hide a production configuration value that is empty or incomplete.
7. Reliability, performance, and cost
Fixing the scheme addresses URL preparation; it does not guarantee the host is reachable or that the server will respond. Set a timeout on network requests so an unavailable destination does not wait indefinitely. A tuple such as timeout=(5, 20) gives separate connect and read timeouts. Handle connection failures and timeouts according to your application’s retry policy; do not retry a malformed URL, because the same input will fail again.
Validate and normalize URLs once at the boundary where untrusted or external values enter your program. For batches, reject invalid entries individually and report which input failed instead of losing the entire batch without context. If URLs come from a crawler or user input, enforce allowed schemes and, where needed, allowed hosts before fetching. This also prevents a relative or unexpected absolute link from silently sending requests somewhere unintended.
Adding a scheme has negligible computational cost. Network latency, remote server behavior, response size, and retries dominate request time and resource use. Reuse a requests.Session when making many requests to the same service so connections can be reused, and avoid retrying permanent input errors. No purchase is required to resolve MissingSchema; it is a URL or proxy configuration correction.
8. Or skip the browser setup
If the task is to produce a screenshot rather than fetch page content for your own Python logic, ScreenshotNeo provides a screenshot API: one GET request returns an image or PDF. See the API documentation for options and response details. The URL sent to the API should still be a complete URL.
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
open("shot.webp", "wb").write(r.content)
Equivalent cURL and Node.js calls:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpconst q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo removes cookie banners, newsletter popups, and chat widgets before the shot. Bot checks, blank pages, and failed loads are never billed; response headers say which verdict applied and whether the request was billed. Its MCP server gives AI agents tools for screenshots, page information, and PDF capture. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Sign up free for 1,000 screenshots a month, no card required.
9. Frequently asked questions
Does adding https:// always fix it?
It fixes a missing scheme only when HTTPS is the correct scheme and the rest of the URL is valid. It will not fix an absent host, a bad proxy setting, or a value that was supposed to come from another variable.
Can Requests fetch a relative path by itself?
No. An HTTP request needs a destination URL. Resolve a relative link against the absolute URL of the page that supplied it before calling Requests.
Why does the error mention a suggested HTTPS URL?
Requests can include a suggested scheme in its diagnostic message when parsing finds none. Treat it as a hint to inspect the input, not proof that the target supports HTTPS.
Is MissingSchema a server error?
No. It occurs while Requests prepares the URL, before a normal HTTP response can be received. A 4xx or 5xx status means a response was received and needs separate diagnosis.


