How to Fix Playwright Test Results Not Publishing in Azure Pipelines
Publish Playwright JUnit XML to Azure Pipelines by matching the reporter path, task inputs, failure conditions, and shard settings.
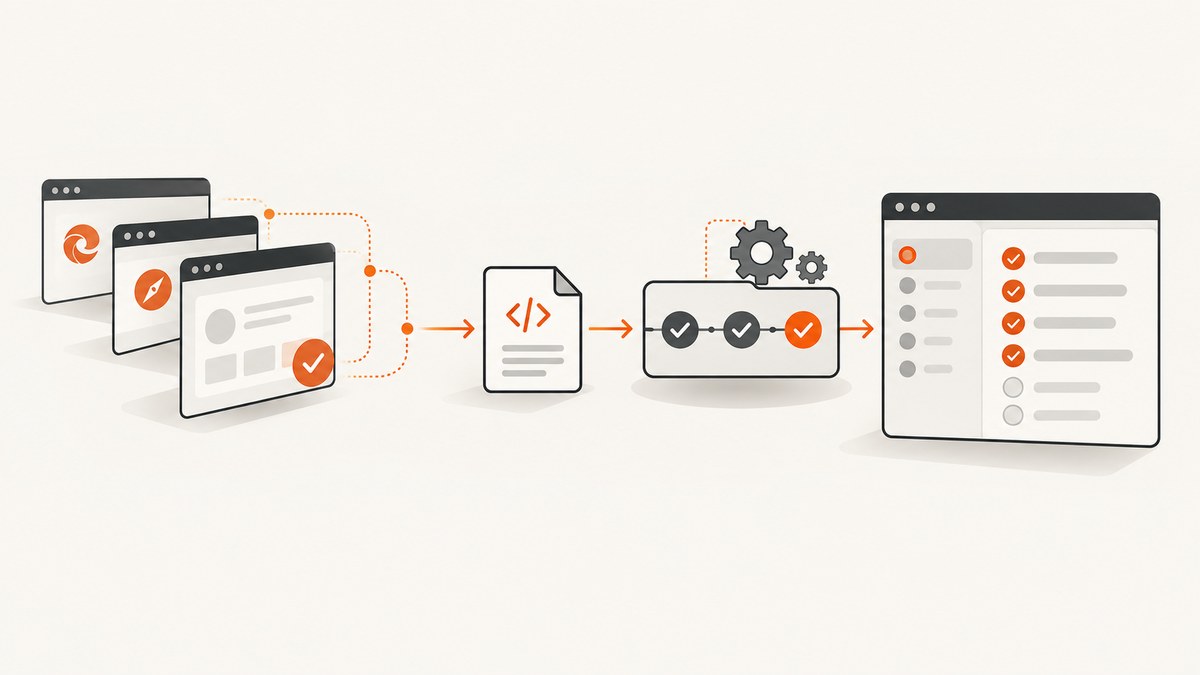
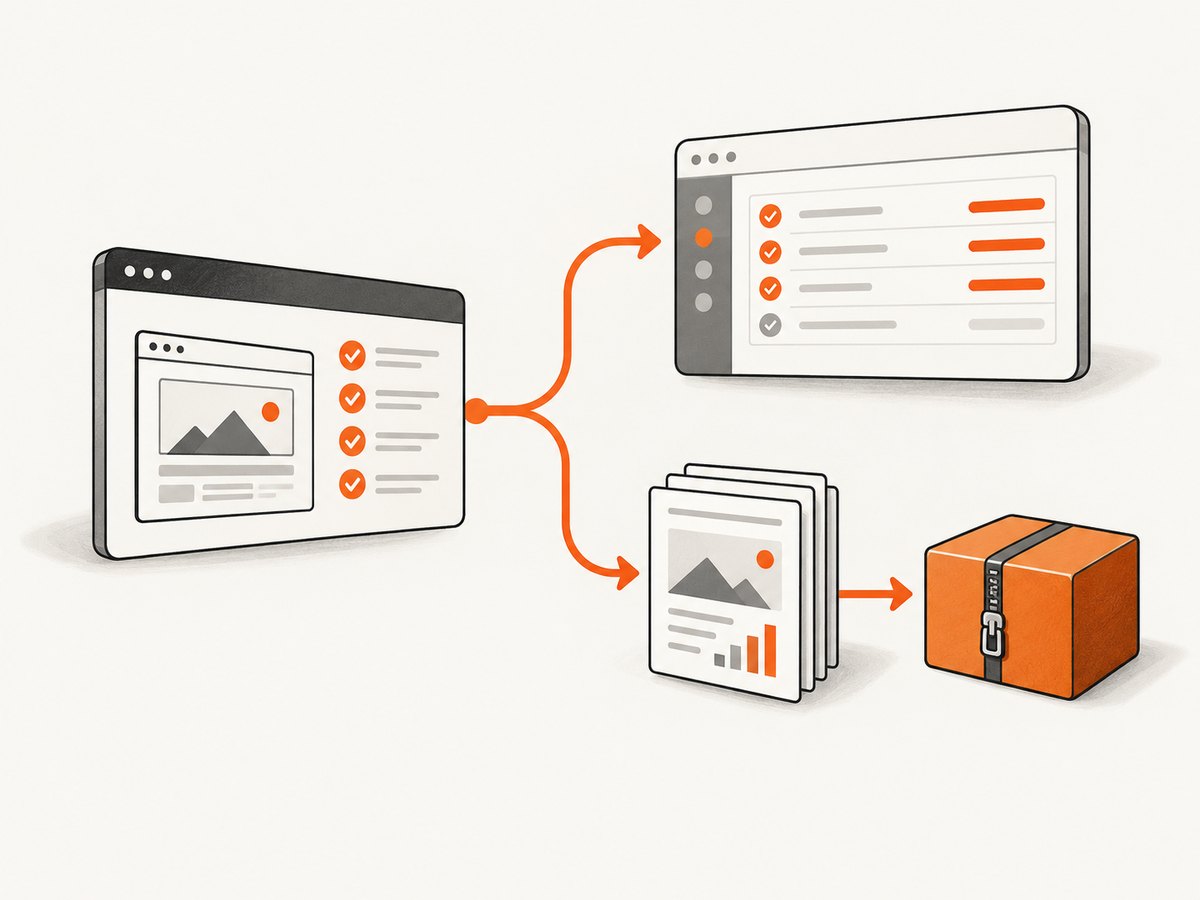
Short answer: Azure Pipelines does not read Playwright’s terminal output or HTML report as test results. Configure Playwright’s JUnit reporter to write an XML file, then point PublishTestResults@2 at the same directory and filename. Publish the HTML report separately as a pipeline artifact. Add condition: succeededOrFailed() so failed test runs still publish their results.
The most common working setup is:
reporter: [['junit', { outputFile: 'test-results/e2e-junit-results.xml' }]]

searchFolder: 'test-results'
testResultsFormat: 'JUnit'
testResultsFiles: 'e2e-junit-results.xml'
Why Playwright results are missing from the Tests tab
Playwright produces several different outputs. The line and list reporters write human-readable terminal output. The HTML reporter writes an interactive report, usually under playwright-report. Neither output automatically becomes an Azure DevOps test run.
Azure Pipelines’ Tests tab consumes supported result files, such as JUnit XML. You must explicitly enable Playwright’s JUnit reporter and then run PublishTestResults@2 against the generated XML. Playwright documents this split in its CI guidance: JUnit XML is used for Azure test reporting, while the HTML report is uploaded as a pipeline artifact (Playwright CI documentation).
Known-good Azure Pipelines configuration
Start with this complete Linux-based pipeline. It installs dependencies, installs browser binaries, runs the tests, publishes JUnit results even when tests fail, and stores the HTML report for interactive debugging.
- script: npm ci
  displayName: Install dependencies

- script: npx playwright install --with-deps
  displayName: Install Playwright browsers

- script: npx playwright test
  displayName: Run Playwright tests
  env:
    CI: 'true'

- task: PublishTestResults@2
  displayName: Publish test results
  inputs:
    searchFolder: 'test-results'
    testResultsFormat: 'JUnit'
    testResultsFiles: 'e2e-junit-results.xml'
    mergeTestResults: true
    failTaskOnFailedTests: true
    testRunTitle: 'Playwright end-to-end tests'
  condition: succeededOrFailed()

- task: PublishPipelineArtifact@1
  displayName: Publish Playwright HTML report
  inputs:
    targetPath: playwright-report
    artifact: playwright-report
    publishLocation: pipeline
  condition: succeededOrFailed()
The corresponding playwright.config.ts is:
import { defineConfig } from '@playwright/test';

export default defineConfig({
  reporter: [
    ['junit', { outputFile: 'test-results/e2e-junit-results.xml' }],
    ['html', { outputFolder: 'playwright-report', open: 'never' }]
  ],
  use: {
    screenshot: 'only-on-failure',
    trace: 'retain-on-failure'
  }
});
The JUnit and HTML reporters serve different purposes. JUnit creates test entries in Azure DevOps. The HTML report preserves Playwright’s step details, traces, screenshots, videos, and network information for investigation.
Match every path and filename exactly
Most “no files were found” errors are path mismatches. The reporter’s outputFile is resolved from the agent’s working directory. The publisher’s searchFolder and testResultsFiles must resolve to that same file.
| Playwright setting | Azure task input | Required relationship |
|---|---|---|
outputFile: 'test-results/e2e-junit-results.xml' |
searchFolder: 'test-results' |
Publisher searches the directory containing the XML |
Filename e2e-junit-results.xml |
testResultsFiles: 'e2e-junit-results.xml' |
Names must match exactly |
| JUnit reporter | testResultsFormat: 'JUnit' |
Format declarations must agree |
Do not point searchFolder at playwright-report. That directory contains HTML and supporting assets, not the JUnit XML consumed by the Tests tab.
Step-by-step diagnosis
1. Confirm the JUnit reporter is active
Inspect playwright.config.ts and check whether a command-line override changes it. A configuration containing only list, line, or html reporters will not create the XML file.
You can also set the reporter for one run:
npx playwright test --reporter=junitIf this creates a JUnit file, the problem is your normal configuration or an environment-specific override.
2. List the agent’s files immediately after the test command
Add a diagnostic step before publishing:
- script: |
    pwd
    find . -maxdepth 3 -type f | sort
    ls -la test-results || true
  displayName: Inspect test output
On a Windows agent, use PowerShell:
- powershell: |
    Get-Location
    Get-ChildItem -Recurse -File test-results
  displayName: Inspect test output
Compare the actual path with the task inputs. This catches differences such as test-results/results.xml versus test-results/e2e-junit-results.xml, capitalization differences, and a test command running from a subdirectory.
3. Publish after failures
By default, a failed Playwright command can prevent later tasks from running. Put condition: succeededOrFailed() on both the test publisher and artifact publisher. This lets Azure record failed tests and preserve the report needed to debug them.
4. Make missing files fail loudly while debugging
Temporarily add the diagnostic inputs supported by PublishTestResults@2:
- task: PublishTestResults@2
  inputs:
    searchFolder: 'test-results'
    testResultsFormat: 'JUnit'
    testResultsFiles: 'e2e-junit-results.xml'
    failTaskOnMissingResultsFile: true
    failTaskOnFailureToPublishResults: true
  condition: succeededOrFailed()
Once the path is correct, you can decide whether these strict failure settings fit your pipeline policy. During diagnosis, they prevent a silent green publishing step when no file exists.
Sharding, retries, and multiple XML files
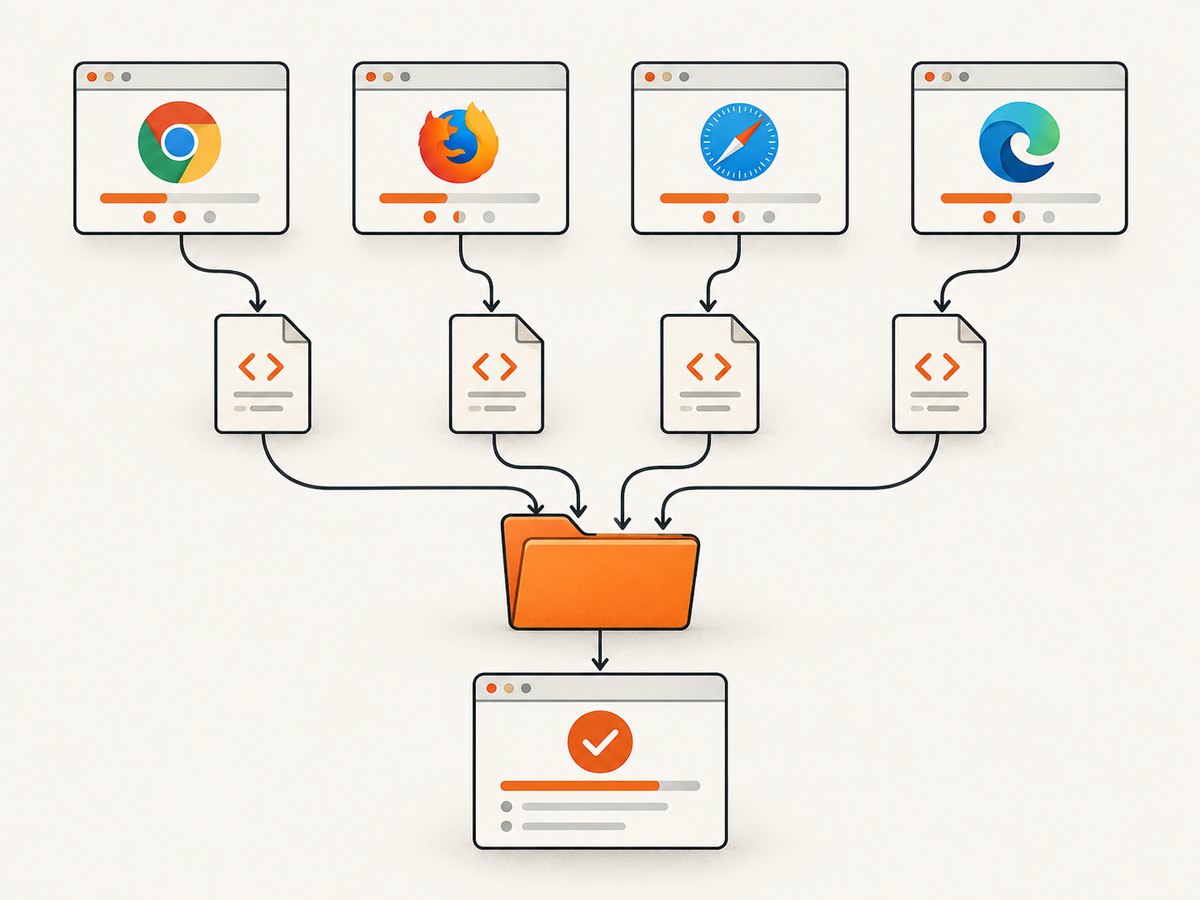
Parallel jobs and shards often produce one result file per worker. Give each shard a unique filename, then publish them with a glob and enable merging.
import { defineConfig } from '@playwright/test';

export default defineConfig({
  reporter: [['junit', {
    outputFile: `test-results/junit-${process.env.SHARD_INDEX || 'local'}.xml`
  }]]
});
- task: PublishTestResults@2
inputs:
searchFolder: 'test-results'
testResultsFormat: 'JUnit'
testResultsFiles: 'junit-*.xml'
mergeTestResults: true
failTaskOnFailedTests: true
condition: succeededOrFailed()Use a unique path per shard if all shards write to a shared workspace. Otherwise, files can overwrite one another or be incomplete when the publisher starts. If each shard runs on a separate agent, publish its results in that job and use the task’s merge behavior for the resulting test runs.
Retries do not remove the need for JUnit configuration. The XML should contain the suites and test cases produced by the run. A zero-byte or malformed XML file cannot create useful test entries, even when the task finds it.
Screenshots, traces, videos, and attachments
Configure failure diagnostics in Playwright so expensive artifacts are retained only when they help investigation:
use: {
  screenshot: 'only-on-failure',
  video: 'retain-on-failure',
  trace: 'retain-on-failure'
}
Azure DevOps can associate attachment paths recorded in the JUnit XML. Paths may be absolute or relative to the XML file. After publishing, open a failed test in the Tests tab and select Attachments to inspect or download the files. Keep the HTML report as a separate pipeline artifact because it contains the complete interactive Playwright experience.
Common errors and fixes
| Message or symptom | Likely cause | Fix |
|---|---|---|
| “No test result files were found” | Wrong folder, filename, glob, or working directory | List files after the test command and make searchFolder plus testResultsFiles match the real path |
| Publisher task is skipped | Playwright exited with failures | Add condition: succeededOrFailed() |
| Tests tab is empty but HTML report exists | Only the HTML reporter is configured | Add the JUnit reporter and publish its XML |
| One shard’s results replace another’s | All shards write the same XML filename | Include a shard identifier in each output filename and use a glob |
| Task finds XML but shows no tests | Malformed, empty, or non-JUnit XML | Open the file, validate that it contains suites and test cases, and set testResultsFormat: 'JUnit' |
| Attachments are missing | Paths in XML do not exist on the publishing agent | Retain artifacts, use valid absolute or XML-relative paths, and publish after the test step |
| Browser launch fails before XML is written | Browsers or Linux dependencies are absent | Run npx playwright install --with-deps before tests |
Reliability and performance considerations
Publishing a small JUnit XML file is normally cheap compared with running browser tests. The larger cost is retaining traces, videos, screenshots, and HTML assets. Restrict screenshots and traces to failures unless every run needs them.
Use npm ci for reproducible dependency installation and pin Playwright versions in your lockfile. Install browsers explicitly on ephemeral hosted agents. Keep result publication independent from test success so a red test run still produces evidence.
For large suites, shard the tests and write one XML file per shard. Use stable naming and a glob in the publisher. Merging results improves the Tests-tab view, but it does not eliminate the need to retain shard-specific HTML reports when investigating a failure.
Or skip the browser setup
If you need a clean screenshot of a page for a pipeline artifact, documentation step, or visual check, ScreenshotNeo provides a single HTTP request instead of maintaining browser installation and capture code. Its API accepts a URL and returns PNG, JPEG, WebP, or PDF. Cookie and consent banners, newsletter popups, and chat widgets are removed before capture; bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and the response identifies the verdict with X-Page-Verdict and X-Billed headers.
See the ScreenshotNeo API documentation for all options. A minimal cURL call is:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const fs = await import('node:fs/promises');
await fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer()));
ScreenshotNeo also offers full-page capture with lazy images loaded, CSS-selector element capture, dark mode, device presets and custom viewports, retina scale, PDF paper and margin controls, custom CSS and JavaScript, clicks, waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs with signed webhooks, bulk capture for up to 100 URLs, a usage API, and an MCP server with take_screenshot, get_page_info, and capture_pdf for AI clients.
The free plan includes 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
FAQ
Can Azure publish Playwright’s HTML report to the Tests tab?
No. Publish the JUnit XML with PublishTestResults@2. Upload playwright-report separately as a pipeline artifact.
Should I use a relative or absolute output path?
A consistent relative path is usually simplest. Ensure the test command and publisher run from the same agent workspace. Use an absolute path only when your pipeline deliberately changes working directories.
Why use succeededOrFailed() instead of always running?
It publishes results after success or test failure while still allowing cancellation and other pipeline states to stop the task.
Do retries create duplicate Azure tests?
Retries are represented in the generated result data according to the reporter’s output. If your pipeline combines separate runs or shards, use one deliberate glob and merge policy so repeated executions are not accidentally published as unrelated runs.
Where should I look first when this still fails?
Read the agent log immediately after npx playwright test, list the workspace files, open the XML, and compare its exact path and contents with the publisher inputs. This separates reporter, path, condition, and XML-format problems quickly.


