How to Fix Puppeteer When It Does Not Generate a PDF
Fix Puppeteer PDF failures by checking the output path, page readiness, Chrome launch environment, and print settings in order.

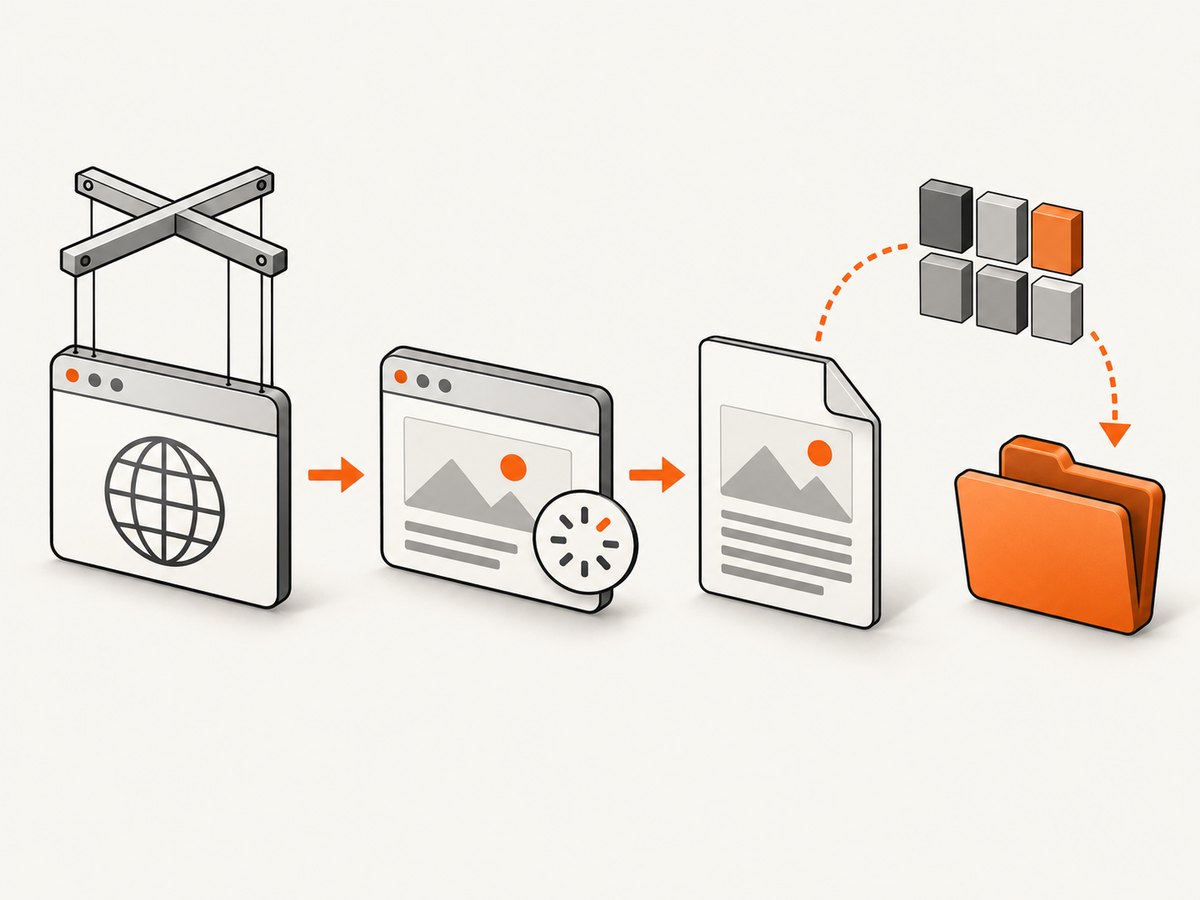
Puppeteer creates PDFs with page.pdf(). When no file appears, first set an explicit writable absolute path; then confirm Chromium launched, navigation and app data are ready, and print settings match the page. A missing file is often a path or write-permission issue rather than a PDF-rendering failure.
This guide walks through a reliable minimal implementation, diagnoses empty or stalled output, and covers the extra constraints you can hit in Linux containers, Cloud Run, and AWS Lambda. Puppeteer’s official guide points to Page.pdf() for printing PDFs. Puppeteer PDF generation guide.
1. Start with a known-good PDF flow
Run a small script with a known URL and an explicit output path. Keep browser shutdown in a finally block so a navigation or PDF error does not leave Chromium running.
const puppeteer = require('puppeteer');

async function main() {
  const browser = await puppeteer.launch();
  try {
    const page = await browser.newPage();
    const response = await page.goto('https://example.com', {
      waitUntil: 'networkidle2',
      timeout: 60000,
    });

    if (!response || !response.ok()) {
      throw new Error(`Navigation failed: ${response?.status() ?? 'no response'}`);
    }

    await page.pdf({
      path: '/tmp/output.pdf',
      format: 'A4',
      printBackground: true,
    });
    console.log('Wrote /tmp/output.pdf');
  } finally {
    await browser.close();
  }
}

main().catch((error) => {
  console.error(error);
  process.exitCode = 1;
});
Use a path you can inspect and whose parent directory is writable. In production, choose a path appropriate to your runtime and move or stream the resulting bytes to durable storage if needed; a temporary directory may be cleared after the process exits.
2. Check the output path and write permissions
The path option controls whether Puppeteer writes a file. If it is omitted or evaluates to undefined, page.pdf() returns PDF data instead of writing a file. Relative paths resolve against the process’s current working directory, which can differ between a local shell, a service manager, and a container. Puppeteer PDFOptions reference.
- Temporarily use an absolute path such as
/tmp/output.pdf. - Log
process.cwd()and the final path if you need a relative path. - Check that the parent directory exists and the process user can write there.
- After generation, check the returned value or file metadata and confirm the file is nonzero in size.
If you want the PDF in memory rather than on disk, omit path intentionally and handle the returned data:
const pdf = await page.pdf({ format: 'A4' });
await require('node:fs/promises').writeFile('/tmp/output.pdf', pdf);
In recent Puppeteer versions the result is a byte buffer-like value; consult the API reference for the version installed in your project. Avoid assuming an omitted path writes to the current directory.
3. Make sure the page is ready before printing
A successful navigation event does not always mean your application has finished rendering. Client-side routes may fetch data after the initial document load, and a page may show a shell before the report or invoice content appears. Choose a navigation condition that matches the site, then wait for an application-specific signal.
await page.goto(url, { waitUntil: 'domcontentloaded', timeout: 60000 });
await page.waitForSelector('[data-report-ready="true"]', { timeout: 30000 });
await page.evaluate(() => document.fonts.ready);
await page.pdf({ path: '/tmp/report.pdf', format: 'A4' });
Useful readiness signals include a report container, a known heading, a loading indicator disappearing, or a specific API response completing. Prefer a real page-specific signal to an arbitrary sleep. A fixed delay can be useful for a known animation or delayed widget, but it makes every capture slower and can still be too short under load.
networkidle0 and networkidle2 wait for network activity to become quiet according to different connection thresholds. They can be unsuitable for pages with polling, analytics, long-lived requests, or streaming connections. If navigation never reaches a network-idle condition, use domcontentloaded or load and wait for the element that means your content is ready.
Fonts and late page content
Puppeteer waits for fonts by default when generating a PDF. A web font that loads slowly can therefore delay output; missing font access or a late application render can also change line breaks and page count. Keep the default waitForFonts: true when correct typography matters, and wait for your own data-rendering condition before printing. You can explicitly await document.fonts.ready as shown above. The waitForFonts PDF option is documented in the PDFOptions reference.
Setting waitForFonts: false may be appropriate when a page’s fonts are known not to matter or cannot finish loading, but it can produce fallback typography. Treat it as a deliberate output tradeoff, not a general fix for a hung script.
4. Match print CSS and PDF options to the desired output
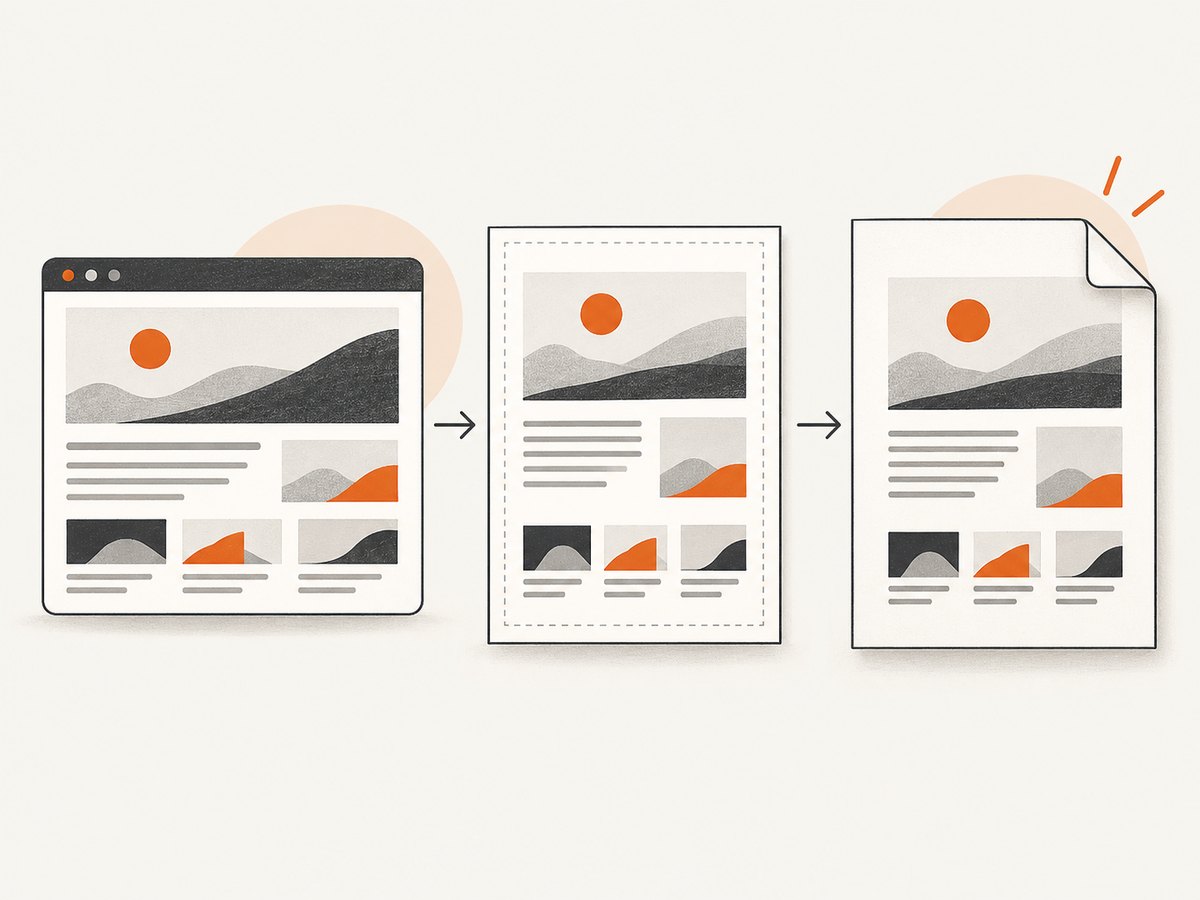
PDF output uses print media by default. A page can look correct in the browser window but differ in its PDF because print styles hide elements, change colors, or alter layout. If the PDF should preserve screen styling, emulate screen media before printing:
await page.emulateMediaType('screen');
await page.pdf({
  path: '/tmp/screen-style.pdf',
  format: 'A4',
  printBackground: true,
});
For print-oriented output, keep print media and inspect the site’s @media print and @page rules. Commonly relevant options include:
| Option | When to use it | What to check |
|---|---|---|
path |
Write a file to disk | Absolute path during diagnosis; writable parent |
format |
Use a standard paper size such as A4 or Letter | Do not combine conflicting paper-size assumptions |
printBackground |
Keep background colors and graphics | Without it, backgrounds may be omitted |
preferCSSPageSize |
Honor the page size declared in CSS @page |
Confirm the document defines the size you want |
landscape |
Use a wider page orientation | Check that tables and page breaks still fit |
margin |
Set top, right, bottom, and left margins | Check headers, footers, and clipped content |
pageRanges |
Print selected pages | Ensure the requested range exists |
displayHeaderFooter |
Add browser-generated header/footer templates | Supply header/footer templates when enabled |
Use options supported by the Puppeteer version in your lockfile; the API reference lists the current PDF options and types.
5. Separate Chromium launch errors from PDF errors
If the script fails before a page is created, investigate browser installation and operating-system dependencies before changing PDF settings. First run the smallest launch check in the same image, user account, and runtime as the failing job:
const puppeteer = require('puppeteer');
(async () => {
  const browser = await puppeteer.launch();
  console.log(await browser.version());
  await browser.close();
})().catch((error) => {
  console.error(error);
  process.exitCode = 1;
});
On Debian or Ubuntu-like systems, Chrome may need shared libraries and fonts that are not present in a minimal image. Puppeteer’s troubleshooting guide lists dependencies including libatk-bridge2.0-0, libatk1.0-0, libcairo2, libgbm1, libnss3, libpango-1.0-0, and libpangocairo-1.0-0. Use the guide for the supported package list and diagnosis. On Linux, ldd can reveal unresolved shared libraries:
ldd /path/to/chrome | grep 'not found'The actual Chrome executable location depends on how Puppeteer and the browser were installed. Find the executable in the failing environment rather than copying a path from a different machine. See Puppeteer troubleshooting.
6. Check sandboxing and writable runtime directories
A No usable sandbox! message means Chrome cannot start with the sandbox configuration available in that environment. The first choice is to make a supported sandbox available. Puppeteer strongly discourages disabling the sandbox; its documentation mentions --no-sandbox only for trusted content. Do not use that flag as a blanket production fix for arbitrary URLs. Review the official sandbox guidance, including the Ubuntu AppArmor note: profiles can prevent Chrome for Testing from using user namespaces.
Chrome also needs writable locations for its profile and cache. Read-only filesystems and locked-down home directories can cause launch failures or confusing secondary errors. Configure writable temporary directories and a user data directory:
const browser = await puppeteer.launch({
  userDataDir: '/tmp/.puppeteer-profile',
  env: {
    ...process.env,
    XDG_CONFIG_HOME: '/tmp/.chromium/config',
    XDG_CACHE_HOME: '/tmp/.chromium/cache',
  },
});
Create the directories first if your runtime does not create them automatically, and ensure the process can write to them. Do not reuse a single browser profile concurrently across independent jobs; give workers isolated writable profiles or manage browser instances deliberately.
7. Deployment notes for Cloud Run and Lambda
Cloud Run
Cloud Run’s default Node.js runtime does not include every system package needed by headless Chrome. Build an image that installs the required browser dependencies and verify the browser launches inside that image. Cloud Run also changes CPU availability after a response is sent when CPU is not configured to remain allocated. If PDF work begins after responding, it can become unexpectedly slow or stop progressing as expected. Generate the PDF before returning the response, or configure CPU always allocated when the service design requires post-response work. Refer to Puppeteer’s platform troubleshooting notes for the Cloud Run considerations.
AWS Lambda
Lambda imposes deployment package size constraints, so shipping a full browser may require a compatible Chromium packaging strategy. Verify that the browser build matches the runtime architecture and that executablePath points to the installed binary. Also check temporary storage, memory, and the function timeout against the size and complexity of the pages you render. Puppeteer’s troubleshooting guide discusses Lambda packaging constraints; browser-layer and runtime choices change, so confirm the current compatibility of the package you select.
8. Troubleshooting common symptoms
| Symptom | Likely cause | Fix |
|---|---|---|
| No file appears, but no error is thrown | path is missing/undefined, relative path points elsewhere, or directory is unwritable |
Set an absolute path, log it, check permissions, or save the returned PDF bytes explicitly |
| PDF is zero bytes or unreadable | Write was interrupted, the wrong value was handled, or the process exited before completion | Await page.pdf(), verify its return value/file size, and keep the process alive through the write |
| PDF is blank | Printed before app data rendered, print CSS hides content, or navigation landed on an error/login page | Check the response status and page URL, wait for a content selector, and inspect print media styles |
| Script hangs at navigation | Network-idle condition never occurs because of polling, analytics, or persistent connections | Use domcontentloaded or load and wait for a page-specific readiness selector |
| Script stalls at PDF generation | Fonts or page rendering are still pending, page is very large, or renderer is resource constrained | Await required app readiness, inspect font loading, increase a reasonable job timeout, and simplify/partition huge documents |
| Chrome fails to launch with missing-library errors | Container lacks system libraries or fonts | Install documented dependencies; inspect unresolved libraries with ldd |
No usable sandbox! |
Sandbox support or host policy prevents startup | Configure supported sandboxing; investigate AppArmor/user namespace policy; avoid disabling sandbox for untrusted content |
| Works locally, fails in a container | Different user, filesystem permissions, libraries, fonts, architecture, or browser build | Reproduce in the deployment image and user context; set writable profile/cache directories |
| Looks different from the browser | PDF uses print media; backgrounds or CSS page size are not being applied | Emulate screen media if needed; enable printBackground; consider preferCSSPageSize |
9. Performance, reliability, and cost
Browser startup and page readiness can dominate the time for small PDFs. Reusing a browser process can reduce repeated startup work, but isolate pages and profiles carefully, close each page, and recycle the browser when it becomes unhealthy. For workloads with many documents, put jobs behind a bounded queue so concurrent Chromium instances do not exhaust memory or CPU. Set navigation and job timeouts, record the failing stage, and preserve enough logs to distinguish launch, navigation, readiness, and PDF errors.
Large pages, full-page content, web fonts, and image-heavy layouts consume more time and memory. Keep the output scope limited, avoid loading irrelevant resources when doing so will not change the document, and split very long reports into manageable sections if the design allows it. A retry can help with transient network failures, but retry only the failed stage where practical; blindly repeating a costly navigation and render can multiply resource use.
Puppeteer itself has no per-PDF service charge in this workflow, but the browser job uses your compute, memory, storage, and engineering time. Cloud services may bill those resources according to their own current terms. No fixed render benchmark is universal: URL behavior, fonts, CPU allocation, browser build, and page size all affect latency.
10. Or skip the browser setup
If your task is taking a website screenshot or PDF through an API rather than debugging your own Chromium pipeline, ScreenshotNeo accepts one GET request and returns an image or PDF. For Puppeteer-style PDF troubleshooting specifically, note that this is a hosted capture option, not a drop-in way to run arbitrary Puppeteer code.
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -d format=pdf \
  -o page.pdf
See the ScreenshotNeo API documentation for authentication and supported PDF parameters. Cookie banners, popups, and chat widgets are removed before the shot. Bot checks, blank pages, and failed loads are never billed. Its MCP server lets AI agents use screenshot tools, and 1,000 screenshots a month are free with no card; paid plans start at $5 for 3,000. Sign up for the free plan.
FAQ
Does page.pdf() return data if I do not provide a path?
Yes. An undefined path means Puppeteer returns the PDF data rather than writing a disk file. Save that returned value yourself if you want a file.
Can Puppeteer save a PDF without opening a visible browser window?
Yes. Puppeteer’s browser launch is commonly run headless for automated capture. A visible window is not required for page.pdf().
Why does the PDF have different page breaks than the screen?
PDF rendering follows print layout and paper dimensions. Review print CSS and page-size settings, then compare with the intended screen or print media mode.
Should I always use networkidle0?
No. Persistent connections and background traffic can keep it from resolving. Select the navigation wait condition based on the target page, then wait for a meaningful content-ready signal.


