How to Fix Pyppeteer JavaScript Loading Errors with Requests
Requests fetches HTML but does not run JavaScript. Learn when to use Pyppeteer, how to wait for rendered content, and how to diagnose every failure layer.
Short answer: Python Requests downloads the server response; it does not execute JavaScript. If a page inserts its content after load, Requests will show only the initial HTML. Use a browser runtime such as Pyppeteer, wait for the page state that contains the data, then extract the DOM or call the page’s API directly when one is available.
Debug the problem in layers: (1) Chromium starts, (2) navigation succeeds, (3) the page’s API requests succeed, (4) the target content becomes ready, and (5) your JavaScript evaluation or selector is valid. A timeout or longer sleep cannot repair a missing browser binary, blocked API request, authentication failure, or incorrect selector.
Why Requests returns less content than a browser
A normal requests.get() call returns the server-delivered response body. It does not create a browser context, run scripts, execute fetch/XHR calls, or update the DOM. Compare the raw response with the page you see in a browser:
import requests

url = "https://example.com/results"
r = requests.get(url, timeout=30)
r.raise_for_status()

print("URL:", r.url)
print("status:", r.status_code)
print("target in raw HTML:", "target-text" in r.text)
print(r.text[:500])
If the target is absent from r.text but appears in a normal browser, inspect the browser’s Network panel. A documented JSON endpoint is usually simpler and more reliable than browser automation. Use a browser when the data is created in the page, depends on JavaScript state, requires interaction, or is not exposed through a stable endpoint.
Choose the right fix
| Situation | Best approach | Trade-off |
|---|---|---|
| Data is in the initial HTML | Requests and an HTML parser | Fastest and simplest |
| A stable documented JSON endpoint exists | Call that endpoint with Requests | You must handle authentication, pagination and rate limits |
| JavaScript creates the DOM | Pyppeteer or another browser automation library | Chromium, waits and deployment complexity |
| You need a maintained browser automation stack for new work | Evaluate Playwright for Python | Requires adapting APIs and packaging |
Pyppeteer’s repository currently warns that it is unmaintained and recommends considering playwright-python. Existing Pyppeteer code can still be diagnosed with the workflow below, but maintenance status should be part of a new-project decision.
Install Pyppeteer and make Chromium runnable
Install the Python package, then install Chromium explicitly when your environment does not allow the first-run download:
python -m pip install pyppeteer
pyppeteer-install
Pyppeteer can download Chromium on first use. In containers and CI, verify the executable path, file permissions and required Linux shared libraries. If your image already contains Chrome or Chromium, pass its real path:
import asyncio
from pyppeteer import launch

async def open_page(url: str):
    browser = await launch(
        headless=True,
        executablePath="/usr/bin/chromium",  # replace with a real path
        args=[],
    )
    try:
        page = await browser.newPage()
        await page.goto(url, {"waitUntil": "domcontentloaded", "timeout": 30_000})
        return browser, page
    except Exception:
        await browser.close()
        raise

async def main():
    browser, page = await open_page("https://example.com")
    try:
        print(await page.title())
    finally:
        await browser.close()

asyncio.run(main())
Do not copy --no-sandbox into production without understanding your container’s security model. A launch failure is a runtime problem; changing selectors or increasing page timeouts will not fix it. See the Pyppeteer installation notes and troubleshooting guidance.
Navigate, then wait for application readiness
goto() finishing means the chosen navigation condition occurred. It does not guarantee that a framework has fetched data or rendered the component you need. Wait for a selector, a predicate, or the specific response that supplies the data.
import asyncio
from pyppeteer import launch

async def scrape(url: str):
    browser = await launch(headless=True)
    try:
        page = await browser.newPage()
        await page.goto(url, {
            "waitUntil": "domcontentloaded",
            "timeout": 30_000,
        })

        await page.waitForSelector("#results", {"timeout": 30_000})
        html = await page.content()
        return html
    finally:
        await browser.close()

html = asyncio.run(scrape("https://example.com/results"))
print(len(html))
Wait for the API response and rendered state
await page.waitForResponse(
    lambda response: "/api/results" in response.url and response.status == 200,
    {"timeout": 30_000},
)
await page.waitForFunction(
    "() => document.querySelectorAll('#results li').length > 0",
    {"timeout": 30_000},
)
Use a condition tied to the data you need. A fixed sleep(10) can still be too short on a slow run and wastes time on a fast run.
Evaluate JavaScript without expression and function mistakes
Pyppeteer tries to infer whether a string passed to evaluate() is a function or an expression. Make the intent explicit when inference is wrong:
# Expression: force_expr removes ambiguity
txt = await page.evaluate("document.body.textContent", force_expr=True)

# Function with an element argument
heading = await page.evaluate(
    "element => element.textContent",
    await page.querySelector("h1"),
)

# Function that returns structured data
rows = await page.evaluate("""
() => Array.from(document.querySelectorAll('#results li')).map(li => ({
  text: li.textContent.trim(),
  href: li.querySelector('a')?.href || null
}))
""")
If you see an error saying an expression is not a function, check whether Pyppeteer interpreted your string as a callback. Use force_expr=True for a plain expression or provide an explicit arrow/function expression.
A complete diagnostic script
Attach listeners before navigation so you can tell browser, navigation, network and page-code failures apart:
import asyncio
from pyppeteer import launch

async def debug_page(url: str):
    browser = await launch(headless=True)
    page = await browser.newPage()

    page.on("console", lambda msg: print("CONSOLE", msg.type, msg.text))
    page.on("pageerror", lambda err: print("PAGE ERROR", err))
    page.on("requestfailed", lambda req: print(
        "REQUEST FAILED", req.url, req.failure
    ))
    page.on("response", lambda res: print(
        "RESPONSE", res.status, res.url
    ) if "/api/" in res.url else None)

    try:
        response = await page.goto(url, {
            "waitUntil": "domcontentloaded",
            "timeout": 30_000,
        })
        print("main status:", response.status if response else None)
        print("final URL:", page.url)
        print("cookies:", await page.cookies())
        await page.waitForSelector("#results", {"timeout": 30_000})
        return await page.content()
    finally:
        await browser.close()

try:
    html = asyncio.run(debug_page("https://example.com/results"))
except Exception as exc:
    print(type(exc).__name__, str(exc))
Record the final URL, status, console errors, failed requests, cookies and the exact selector or predicate. These facts identify the failing layer much faster than changing several settings at once.
Avoid navigation races after clicks
Start the navigation wait before the action that triggers navigation, then wait for the content on the destination page:
navigation = asyncio.ensure_future(
    page.waitForNavigation({"waitUntil": "networkidle2", "timeout": 30_000})
)
await page.click("a.next")
await navigation
await page.waitForSelector("#results", {"timeout": 30_000})
A History API update may change the URL without a new main-resource navigation. In that case, wait for the relevant API response or page predicate instead of relying on waitForNavigation().
Use requests-html when you want a Requests-style parser
requests-html adds a render() method backed by Pyppeteer. Its first render can download Chromium into the user home directory.
from requests_html import HTMLSession

session = HTMLSession()
r = session.get("https://example.com/results", timeout=30)
r.html.render(timeout=30, retries=2, wait=0.2)
items = r.html.find("#results li", first=False)
for item in items:
    print(item.text)
For asynchronous code:
from requests_html import AsyncHTMLSession

async def load():
    session = AsyncHTMLSession()
    r = await session.get("https://example.com/results")
    await r.html.arender(timeout=30, retries=2, wait=0.2)
    return [item.text for item in r.html.find("#results li", first=False)]
Options such as retries, wait, sleep, reload, cookies, send_cookies_session and keep_page affect known page behavior. They do not replace diagnosing a blocked request or incorrect selector.
Troubleshooting Pyppeteer JavaScript loading errors
| Symptom | Likely cause | Fix |
|---|---|---|
Browser closed unexpectedly, missing executable |
Chromium was not downloaded, path is wrong, permissions or libraries are missing | Run pyppeteer-install, set a verified executablePath, inspect container dependencies and filesystem permissions |
goto() timeout |
Slow or stalled navigation, invalid URL, TLS failure or blocked main resource | Log the exception and final URL; check the URL and failed requests before adjusting the bounded timeout |
| Selector wait timeout | Wrong selector, consent gate, failed API call or content is rendered in a frame | Inspect the DOM, console and network events; wait for the actual data condition; handle frames or consent when required |
| HTML shell but no records | API request failed, requires cookies/headers, or returned an error | Use waitForResponse, inspect status and transfer only the required cookies or headers |
page.evaluate says expression is not a function |
Expression/function auto-detection chose the wrong form | Use force_expr=True or an explicit function string |
| Click hangs while waiting for navigation | Click changes state with History API or does not navigate | Wait for a selector or API response instead; start navigation waiting before clicks that truly navigate |
| Works locally, fails in CI | Different Chromium path, sandbox, missing libraries, proxy or environment variables | Print executable and version details, capture browser logs, install dependencies and reproduce with the same image |
| Repeated downloads or slow startup | Chromium cache is ephemeral | Persist the browser cache or install a browser during image build, subject to your deployment policy |
Cookies, headers, authentication and blocked resources
Some applications render only after a session cookie, authorization header, locale or user agent is present. Set these deliberately and avoid copying credentials into logs:
await page.setCookie({
    "name": "session",
    "value": "SESSION_VALUE",
    "domain": "example.com",
    "path": "/",
})
await page.setExtraHTTPHeaders({"Accept-Language": "en-US"})
await page.setUserAgent("your-approved-user-agent")
await page.goto("https://example.com/results", {
    "waitUntil": "domcontentloaded",
    "timeout": 30_000,
})
Use request interception only when you understand the page’s dependencies. Blocking a stylesheet may be harmless; blocking a script or API call can leave a permanent loading state. Check the site’s terms, robots policy and authorization before automating protected content.
Performance, reliability and cost
- Prefer direct HTTP: when a documented endpoint supplies the data, it avoids Chromium startup and page timing.
- Reuse a browser: launch once per worker and create pages as needed; always close pages and browsers on errors.
- Bound every wait: use explicit timeouts and fail with diagnostics rather than hanging indefinitely.
- Wait on state: selectors, predicates and response filters reduce both premature extraction and unnecessary delay.
- Control concurrency: too many simultaneous pages can exhaust CPU, memory, file descriptors or site rate limits.
- Cache deliberately: cache stable API responses or rendered output only when freshness and authorization allow it.
- Measure your own workload: the sources provide behavior and configuration guidance, not comparative benchmarks or success-rate figures.
Browser automation has a real operational cost: a Chromium binary, memory, startup time, dependency maintenance and failure handling. Pyppeteer itself is unmaintained, so weigh migration to a maintained alternative before committing new production code.
Or skip the browser setup
ScreenshotNeo is a website screenshot API and MCP server. It handles browser capture behind one HTTP request, including JavaScript-rendered pages:
See the ScreenshotNeo API documentation for all options.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
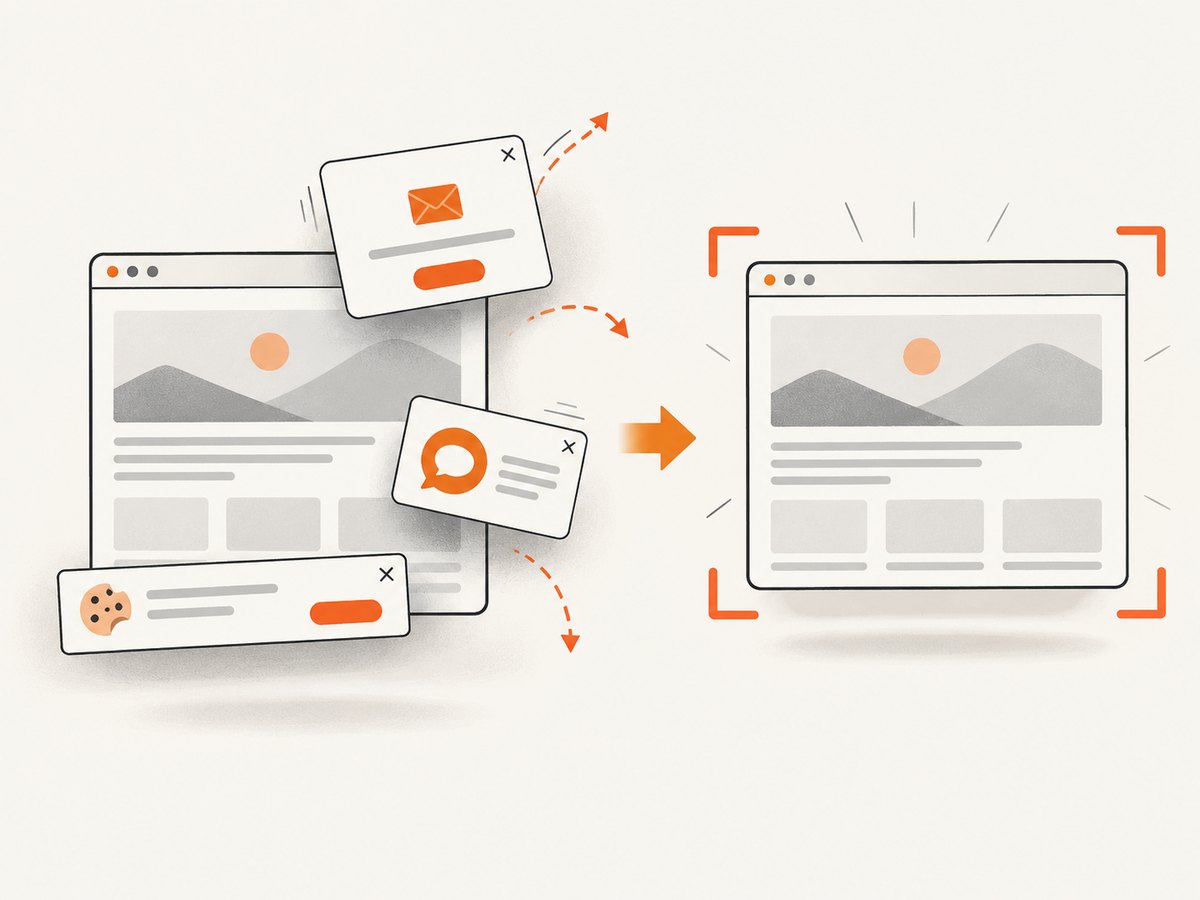
Cookie banners, newsletter popups and chat widgets are removed before the shot. Bot checks, blank pages and failed loads are never billed, and response headers report the page verdict and billing result. An MCP server lets Claude, Cursor and other MCP clients call take_screenshot, get_page_info and capture_pdf. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000.
Create a free ScreenshotNeo account and start with 1,000 screenshots a month at no charge.
FAQ
Can Requests execute JavaScript if I change its headers?
No. Headers can change the server response, but Requests still does not run scripts. Use a documented endpoint or a browser runtime.
Should I increase every timeout?
No. First identify whether the problem is launch, navigation, an API response, readiness, or evaluation. Increase a bounded timeout only when the target is valid and simply slower.
Why does networkidle2 still return too early?
Network-idle conditions describe observed network activity, not whether your application finished rendering the target component. Follow them with a selector, predicate or response wait.
Is Pyppeteer suitable for a new production scraper?
Review its current maintenance warning and compare a maintained browser automation library, deployment support and the site’s API options before choosing it.
Can I use ScreenshotNeo for PDFs as well as images?
Yes. Its API supports PNG, JPEG, WebP and PDF output, and its PDF options include paper size, margins, landscape mode and page ranges.


