How to Fix JavaScript Rendering Errors with requests-html HTMLSession
Fix requests-html JavaScript rendering errors, including active event loops, Chromium startup failures, timing issues, and reliable alternatives.
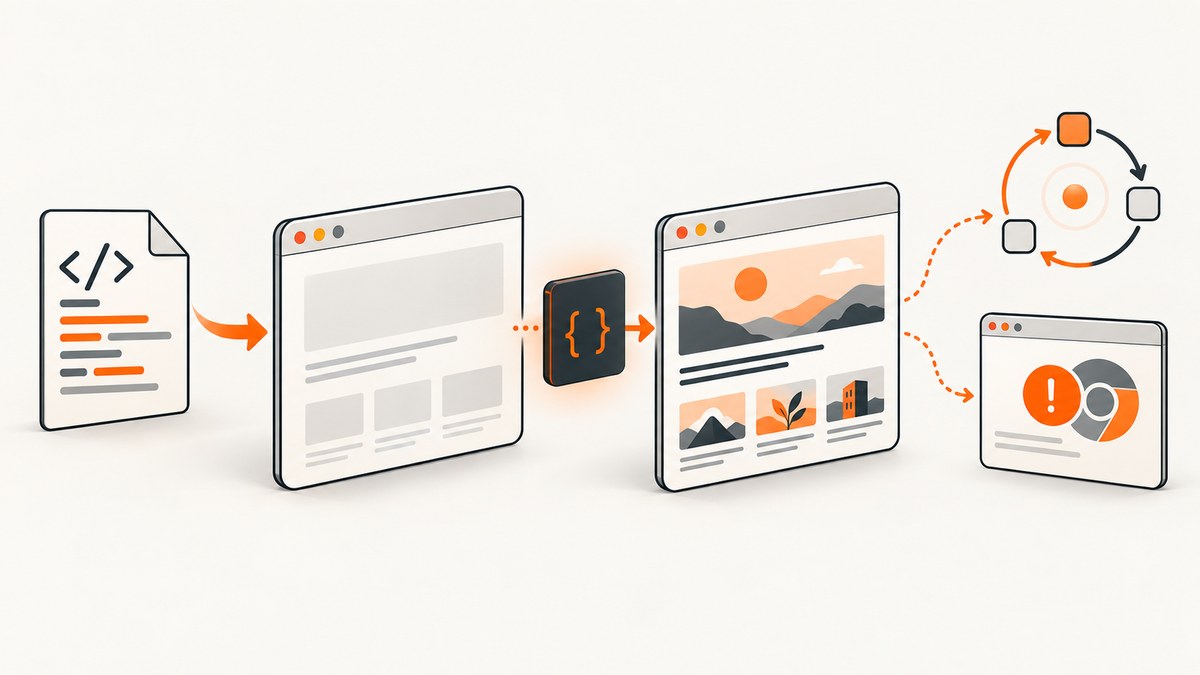
Direct answer: use HTMLSession and call response.html.render() in a normal synchronous Python script. If your code runs inside an already active asyncio event loop, switch to AsyncHTMLSession and await response.html.arender(). If rendering fails before JavaScript runs, check the first-run Chromium download, operating-system libraries, and the complete traceback. Timing options such as sleep, scrolldown, and script help content that appears later; they do not repair an event-loop mismatch or a broken browser installation.
This guide shows how the rendering path works, how to diagnose each common failure, and how to make the result dependable in scripts, notebooks, web servers, and scheduled jobs.
What requests-html does when you call render()
An ordinary requests-html fetch is an HTTP request. It downloads the server response but does not execute the page’s JavaScript. A page that fills a table, product list, or article body in the browser can therefore contain only an empty shell in response.html.
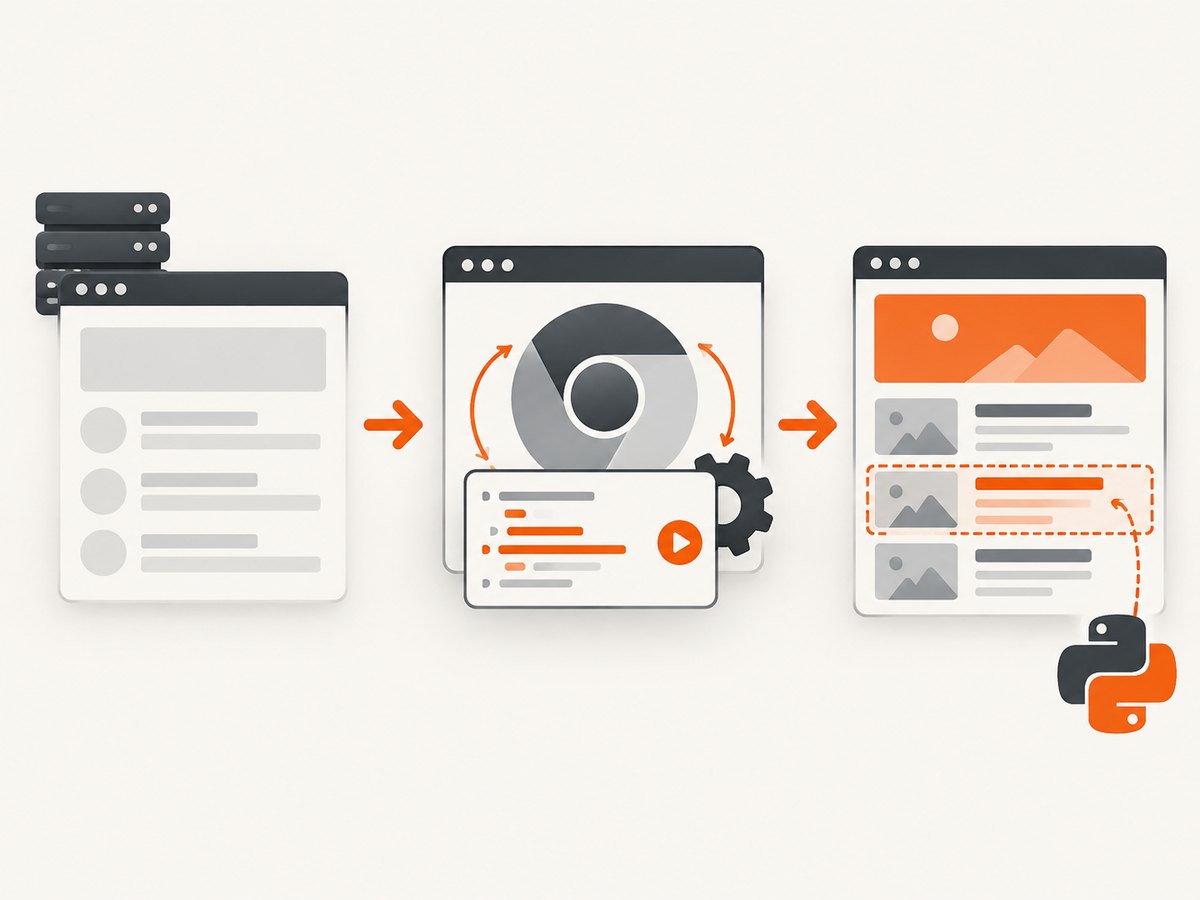
The documented rendering sequence is:
- Create an
HTMLSession. - Fetch the URL with
session.get(). - Call
response.html.render(). - Read selectors or the updated HTML.
render() reloads the response in Chromium through pyppeteer, executes JavaScript, and replaces the parsed HTML with the updated version. The first render in an environment normally downloads Chromium into pyppeteer’s home directory. That download and the browser’s native runtime dependencies are part of the setup, not part of your target site’s HTML.
Minimal synchronous example
from requests_html import HTMLSession

session = HTMLSession()
response = session.get("https://example.com")
response.raise_for_status()
response.html.render()

print(response.html.html)
print(response.html.text)
Run this as a regular Python process, for example python scrape.py. Inspect the HTML after rendering, then select the elements you need:
titles = [element.text for element in response.html.find("h2")]
for title in titles:
    print(title)
If the expected text exists in the initial server response, rendering is unnecessary. Fetch the page once and inspect response.html.html before introducing Chromium; this separates a selector problem from a JavaScript problem.
Fix the active event-loop error
The most recognizable failure is:
Cannot use HTMLSession within an existing event loop. Use AsyncHTMLSession instead.HTMLSession is synchronous. Jupyter notebooks, async web frameworks, async test runners, and applications using asyncio.run() may already have an event loop. Starting the synchronous session there causes the error before a usable render is produced.
Use AsyncHTMLSession in async code
from requests_html import AsyncHTMLSession

async def fetch_rendered(url):
    session = AsyncHTMLSession()
    response = await session.get(url)
    response.raise_for_status()
    await response.html.arender()
    return response.html.html

# In an async framework or notebook:
html = await fetch_rendered("https://example.com")
print(html)
The important changes are the session class, await session.get(), and await response.html.arender(). Do not call synchronous render() from the active loop and do not mix the two patterns in the same request path.
Choose the session from the execution context
| Where the code runs | Use | Render call |
|---|---|---|
| Plain script or synchronous job | HTMLSession |
response.html.render() |
| Notebook with an active loop | AsyncHTMLSession |
await response.html.arender() |
| Async web endpoint | AsyncHTMLSession |
await response.html.arender() |
Do not “fix” the exception by patching or nesting event loops. Align the requests-html API with the loop that owns your application.
Control when dynamic content appears
A successful browser launch does not guarantee that an asynchronous widget has finished loading. The render API provides controls for additional time, scrolling, and page-side JavaScript.
Wait for delayed application code
response.html.render(sleep=2)
sleep adds a delay after the page loads. Use a small value based on the page’s behavior, then inspect the resulting HTML. There is no universal delay that works for every site: a fixed wait can be too short for a slow application and wasteful for a fast one.
Trigger lazy loading by scrolling
response.html.render(scrolldown=5, sleep=1)
scrolldown repeats scrolling so pages that load images or rows near the viewport can request them. It is useful for lazy content but does not repair a browser that never started.
Run a page-side script
response.html.render(script="document.querySelector('button.load-more')?.click()")
The optional script runs JavaScript in the rendered page. Keep it focused on an interaction the page itself supports, and verify that the selector exists before relying on it. A script that throws, clicks the wrong element, or runs before a component exists can leave the page unchanged.
Diagnose failures in the right order
- Confirm the target URL and status. Print
response.status_code, callraise_for_status(), and save the initial HTML. - Prove that JavaScript is required. Search the initial HTML for the text or element you expect. If it is present, fix the selector instead of rendering.
- Check the execution context. An active loop requires
AsyncHTMLSession; a plain script can useHTMLSession. - Check Chromium setup. On the first render, allow pyppeteer to download Chromium. Confirm the download completed and that the process can launch the downloaded browser.
- Read the complete traceback. Separate installation, operating-system library, protocol, timeout, and target-page errors. Do not assume every browser error has the same fix.
- Add timing or interaction only after startup works. Use
sleep,scrolldown, orscriptfor late content, not as a remedy for missing dependencies.
Common errors, causes, and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| “Cannot use HTMLSession within an existing event loop” | Synchronous session used inside asyncio | Use AsyncHTMLSession, await get(), then await arender(). |
| Chromium download hangs or is incomplete | First-run download was blocked or interrupted | Check network access and the pyppeteer home directory; remove the incomplete browser only when you understand the effect, then retry. |
| Browser fails to launch on Linux | Required system packages or libraries are unavailable | Review the requests-html and pyppeteer environment requirements for your distribution. There is no single package list valid for every platform. |
| Connection or protocol closes unexpectedly | Browser startup, platform compatibility, runtime mismatch, or target-page behavior | Read the full traceback, verify the browser executable and environment, and reproduce with a small URL before changing page options. |
| Rendered HTML still lacks the data | Content appears after the initial render or requires interaction | Try a measured sleep, scrolldown, or page-side script; verify selectors and save the output. |
| Selector returns no elements | Wrong selector, content in a frame, or render not completed | Inspect response.html.html, confirm the selector in browser markup, and render before selecting. |
Make a small diagnostic script
from pathlib import Path
from requests_html import HTMLSession

url = "https://example.com"
session = HTMLSession()
response = session.get(url, timeout=30)
print("status:", response.status_code)
print("initial length:", len(response.html.html))

Path("before-render.html").write_text(response.html.html, encoding="utf-8")
response.html.render(sleep=1)
Path("after-render.html").write_text(response.html.html, encoding="utf-8")
print("rendered length:", len(response.html.html))
print(response.html.text[:500])
Comparing the two saved files reveals whether JavaScript added the expected markup. Keep the URL, status, lengths, and traceback in logs for scheduled jobs so a later failure can be classified without guessing.
Reliability and performance considerations
Browser startup is expensive
Rendering starts a Chromium-based workflow, so it is slower and heavier than an ordinary HTTP fetch. Reuse a session where your application lifecycle allows it, avoid rendering pages that already contain the data, and limit scrolling and delays to what the page needs.
Control concurrency
Launching many browser pages at once increases CPU and memory pressure. In an async service, use a bounded worker pool or semaphore around render operations. Keep request timeouts explicit and record failures separately from empty results.
Expect compatibility work
The package documentation is old: the PyPI page states support for Python 3.6, and the stable documentation identifies version 0.3.4. Treat compatibility with newer Python versions, Chromium releases, and operating systems as an environment question to verify. Pin and reproduce the versions used by your deployment rather than assuming current compatibility.
Cache only when the page permits it
If the target changes slowly, cache the rendered result and reduce repeated browser work. For frequently changing or personalized pages, stale HTML can be worse than a slower fresh render. Respect the target site’s access rules and avoid unnecessary request volume.
Or skip the browser setup
If your goal is a clean screenshot or PDF rather than extracting data inside Python, ScreenshotNeo provides a hosted website screenshot API. It handles the browser environment for you. Before capture it accepts cookie or consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks and CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers report the page verdict and billing result.
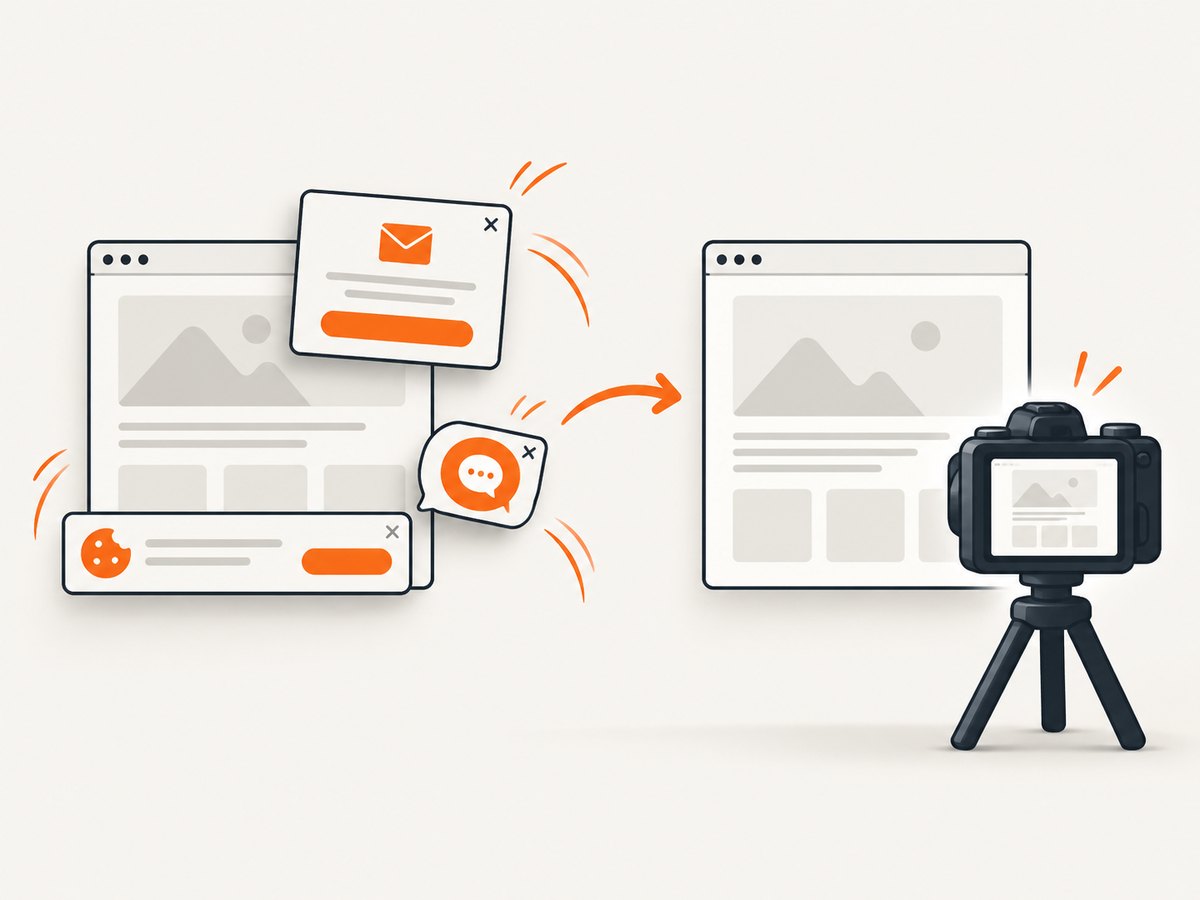
See the ScreenshotNeo API documentation for all options. A one-call capture looks like this:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);You can request PNG, JPEG, WebP, or PDF and configure full-page capture, an element selector, dark mode, device presets, custom viewports, retina scale, waits, custom CSS and JavaScript, headers, cookies, user agents, geolocation, resource blocking, resizing, caching, signed links, asynchronous jobs, webhooks, bulk capture, and usage reporting. Its MCP server includes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients.
The Free plan includes 1,000 screenshots each month with no card. Paid plans start at $5 for 3,000 shots, and every feature is available on every plan. Create a free ScreenshotNeo account.
FAQ
Does render() modify the original response?
Yes. The documented behavior replaces the parsed HTML with the version produced after Chromium executes JavaScript. Save the initial HTML first if you need both versions.
Can sleep fix an event-loop error?
No. An event-loop error requires the asynchronous session and arender(). Sleep only gives already-running page code more time.
Why does the first render take longer?
Pyppeteer may download Chromium on the first render. Later runs can reuse that browser if the environment preserves its home directory.
Should every scraper use JavaScript rendering?
No. Render only when the required content is created or changed by client-side JavaScript. A normal HTTP fetch is simpler and faster for server-rendered pages.
Is requests-html guaranteed to work with current Python and Chromium?
No guarantee follows from its old documentation. Verify the exact versions and operating system in your deployment, and keep the complete traceback when compatibility fails.


